lansespirit/
image-gen-mcp

lansespirit/image-gen-mcpConnectors
An MCP server that integrates with gpt-image-1 & Gemini imagen4 model for text-to-image generation services
69
An MCP server that integrates with gpt-image-1 & Gemini imagen4 model for text-to-image generation services

An MCP server providing tools for image processing operations

GPT Image 2/2.5 prompt gallery, image prompt library, agentic skill, and CLI for OpenAI image generation/editing

Generate GPT images from Codex or Claude Code using a ChatGPT subscription, without the Images API.

A Cli, a webUI, and a MCP server for the Z-Image-Turbo text-to-image generation model (Tongyi-MAI/Z-Image-Turbo base model as well as quantized models)

Local MCP server for ChatGPT image generation.

Production-grade, agent-portable image prompting skill for Nano Banana Pro and Nano Banana 2 in the Gemini image family

MCP server for AI image generation and editing with automatic prompt optimization and quality presets. Supports Nano Banana (Gemini), OpenAI GPT Image, and BytePlus Seedream.

Turn slide screenshots and generated images into editable PowerPoint decks with visual-layer splitting, OCR evidence, and QA.

Standalone Skill and Codex Plugin for OpenAI-compatible image generation, editing, batch workflows, QA, and focused canvas editing.
Use your ChatGPT subscription to generate images from the command line — no OPENAI_API_KEY, no gateway, no daemon. Zero-dep Python CLI + AI-agent skill.

AI agent skill(e.g., Claude Code, Codex): Upload local images to a GitHub PR and embed them in the description or comments

A powerful OCR extension with area selection tool and more

Connect Claude to image generation with Agent Skills. Three levels: a zero-cost code-based design engine, a Three.js 3D renderer, and a real diffusion model on Cloudflare. Plus an AI Storybook pipeline that turns a plain-English story into an illustrated, narrated HTML book.
An advanced in-memory image visualization plugin for GDB and LLDB on Linux, with experimental support for MacOS and Windows. Previously known as gdb-imagewatch. Also available as an extension for VSCode and forks

Rebuild the object in a reference image as a code-only, procedural, quality-gated, animation-ready Three.js model. Token-efficient image-to-3D.

AI agent that turns your rough ideas into perfect image generation prompts. 7-component formula, 70+ creative techniques, 9 domain modes.

Official MiniMax Model Context Protocol (MCP) server that enables interaction with powerful Text to Speech, image generation and video generation APIs.
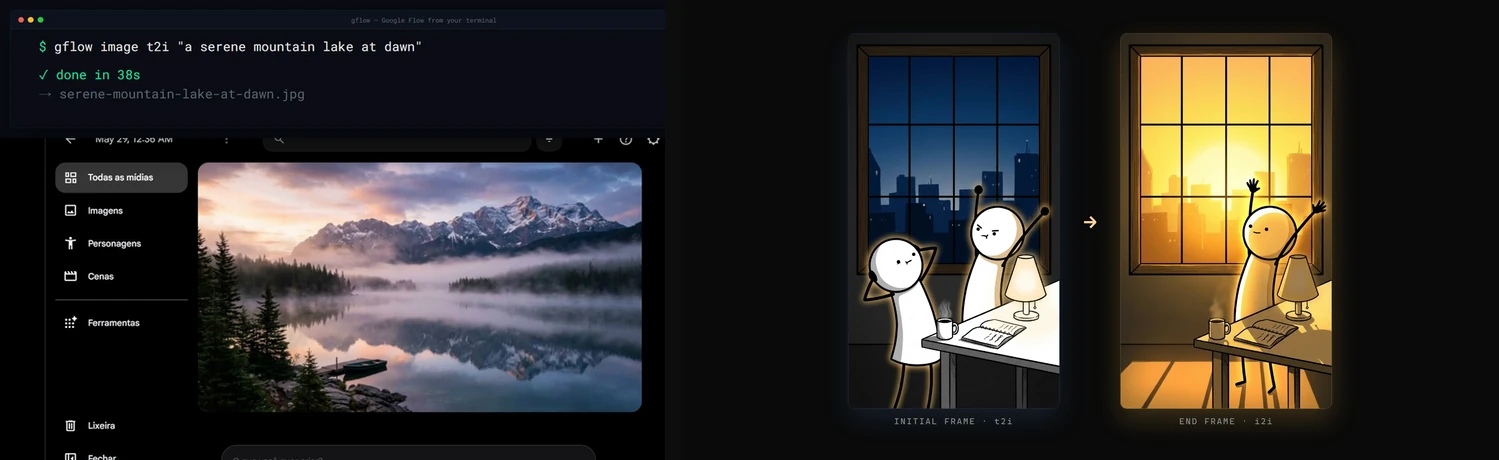
Drive Google Flow from the command line: Veo video and Imagen images, scripted, batched and pipeline-ready. Ships an MCP server so coding agents can drive it too, giving you and your agents full programmatic control over generation. Unofficial, alpha, not affiliated with Google.

Agentic, long-horizon visual generation: a fuzzy story → a cross-model-audited image-based movie. Brings ARIS's research-wiki + multi-agent debate to multimodal generation (intelligence lives in the agent; the diffusion model just renders). Image-based today, video next.

Subject-aware minimal-zine image production for Agent Skills: art direction, generation, series, evidence, and real-bitmap QA.

Blender plugin for TRELLIS and TRELLIS.2 (3D AIGC Model, Text-to-3D, Image-to-3D)

Claude Code skills for Bria AI - generate, edit, and transform images with Fibo, RMBG-2.0, and VGL structured prompts
MCP server for OpenRouter — chat with 300+ LLMs (Claude, Gemini, GPT), analyze images / audio / video, generate images / speech / music / video (Veo 3.1, Sora, Seedance, Wan) from Claude Desktop, Cursor, Kiro, VS Code.