lookfree/
cc-harness

lookfree/cc-harnessTools
Desktop workbench for Claude Code — live subagent topology, token cost breakdown with drill-down, hook sandbox, config audit. Reads your session files locally. Electron, MIT.
48
Desktop workbench for Claude Code — live subagent topology, token cost breakdown with drill-down, hook sandbox, config audit. Reads your session files locally. Electron, MIT.

Free Kagi Search MCP server — access search and summarizer via session tokens, no API key needed. Works with Claude Desktop, Cursor, Windsurf, Hermes and any MCP client.

Up to 71.5x fewer tokens per session on Claude Code with Obsidian + Graphify. Persistent memory, codebase knowledge graphs, and chat import pipeline. 🇧🇷 PT-BR included.

CLI output compressor for Claude Code. Reduces token consumption by 50–90% by compressing verbose command output before it enters the context window. Supports 52+ commands — git, docker, kubectl, npm, terraform, and more.

Local-first control plane for AI coding agents — launch browser terminals, run and remotely control sessions, and track files, tokens & cost across Claude Code, Codex, Cursor, Gemini CLI and 20+ more. 100% local, no telemetry.

MCP for semantic code search & navigation that reduces token waste
An agentic memory database that cuts session tokens by 82–99%. One portable SQLite file — your agent's memory, anywhere.
A Claude skill that writes the accurate prompts for any AI tool. Zero tokens or credits wasted. Full context and memory retention

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Local-first telemetry collector for AI coding agents — unified OpenTelemetry events for Claude Code, Codex, Cursor and more. Token usage, cost, traces and security audit, exported anywhere.
Fast and Accurate Code Search for Agents. Uses 99% fewer tokens than grep+read

Recursive Language Model patterns for Claude Code — handle massive contexts (10M+ tokens) by treating them as external variables
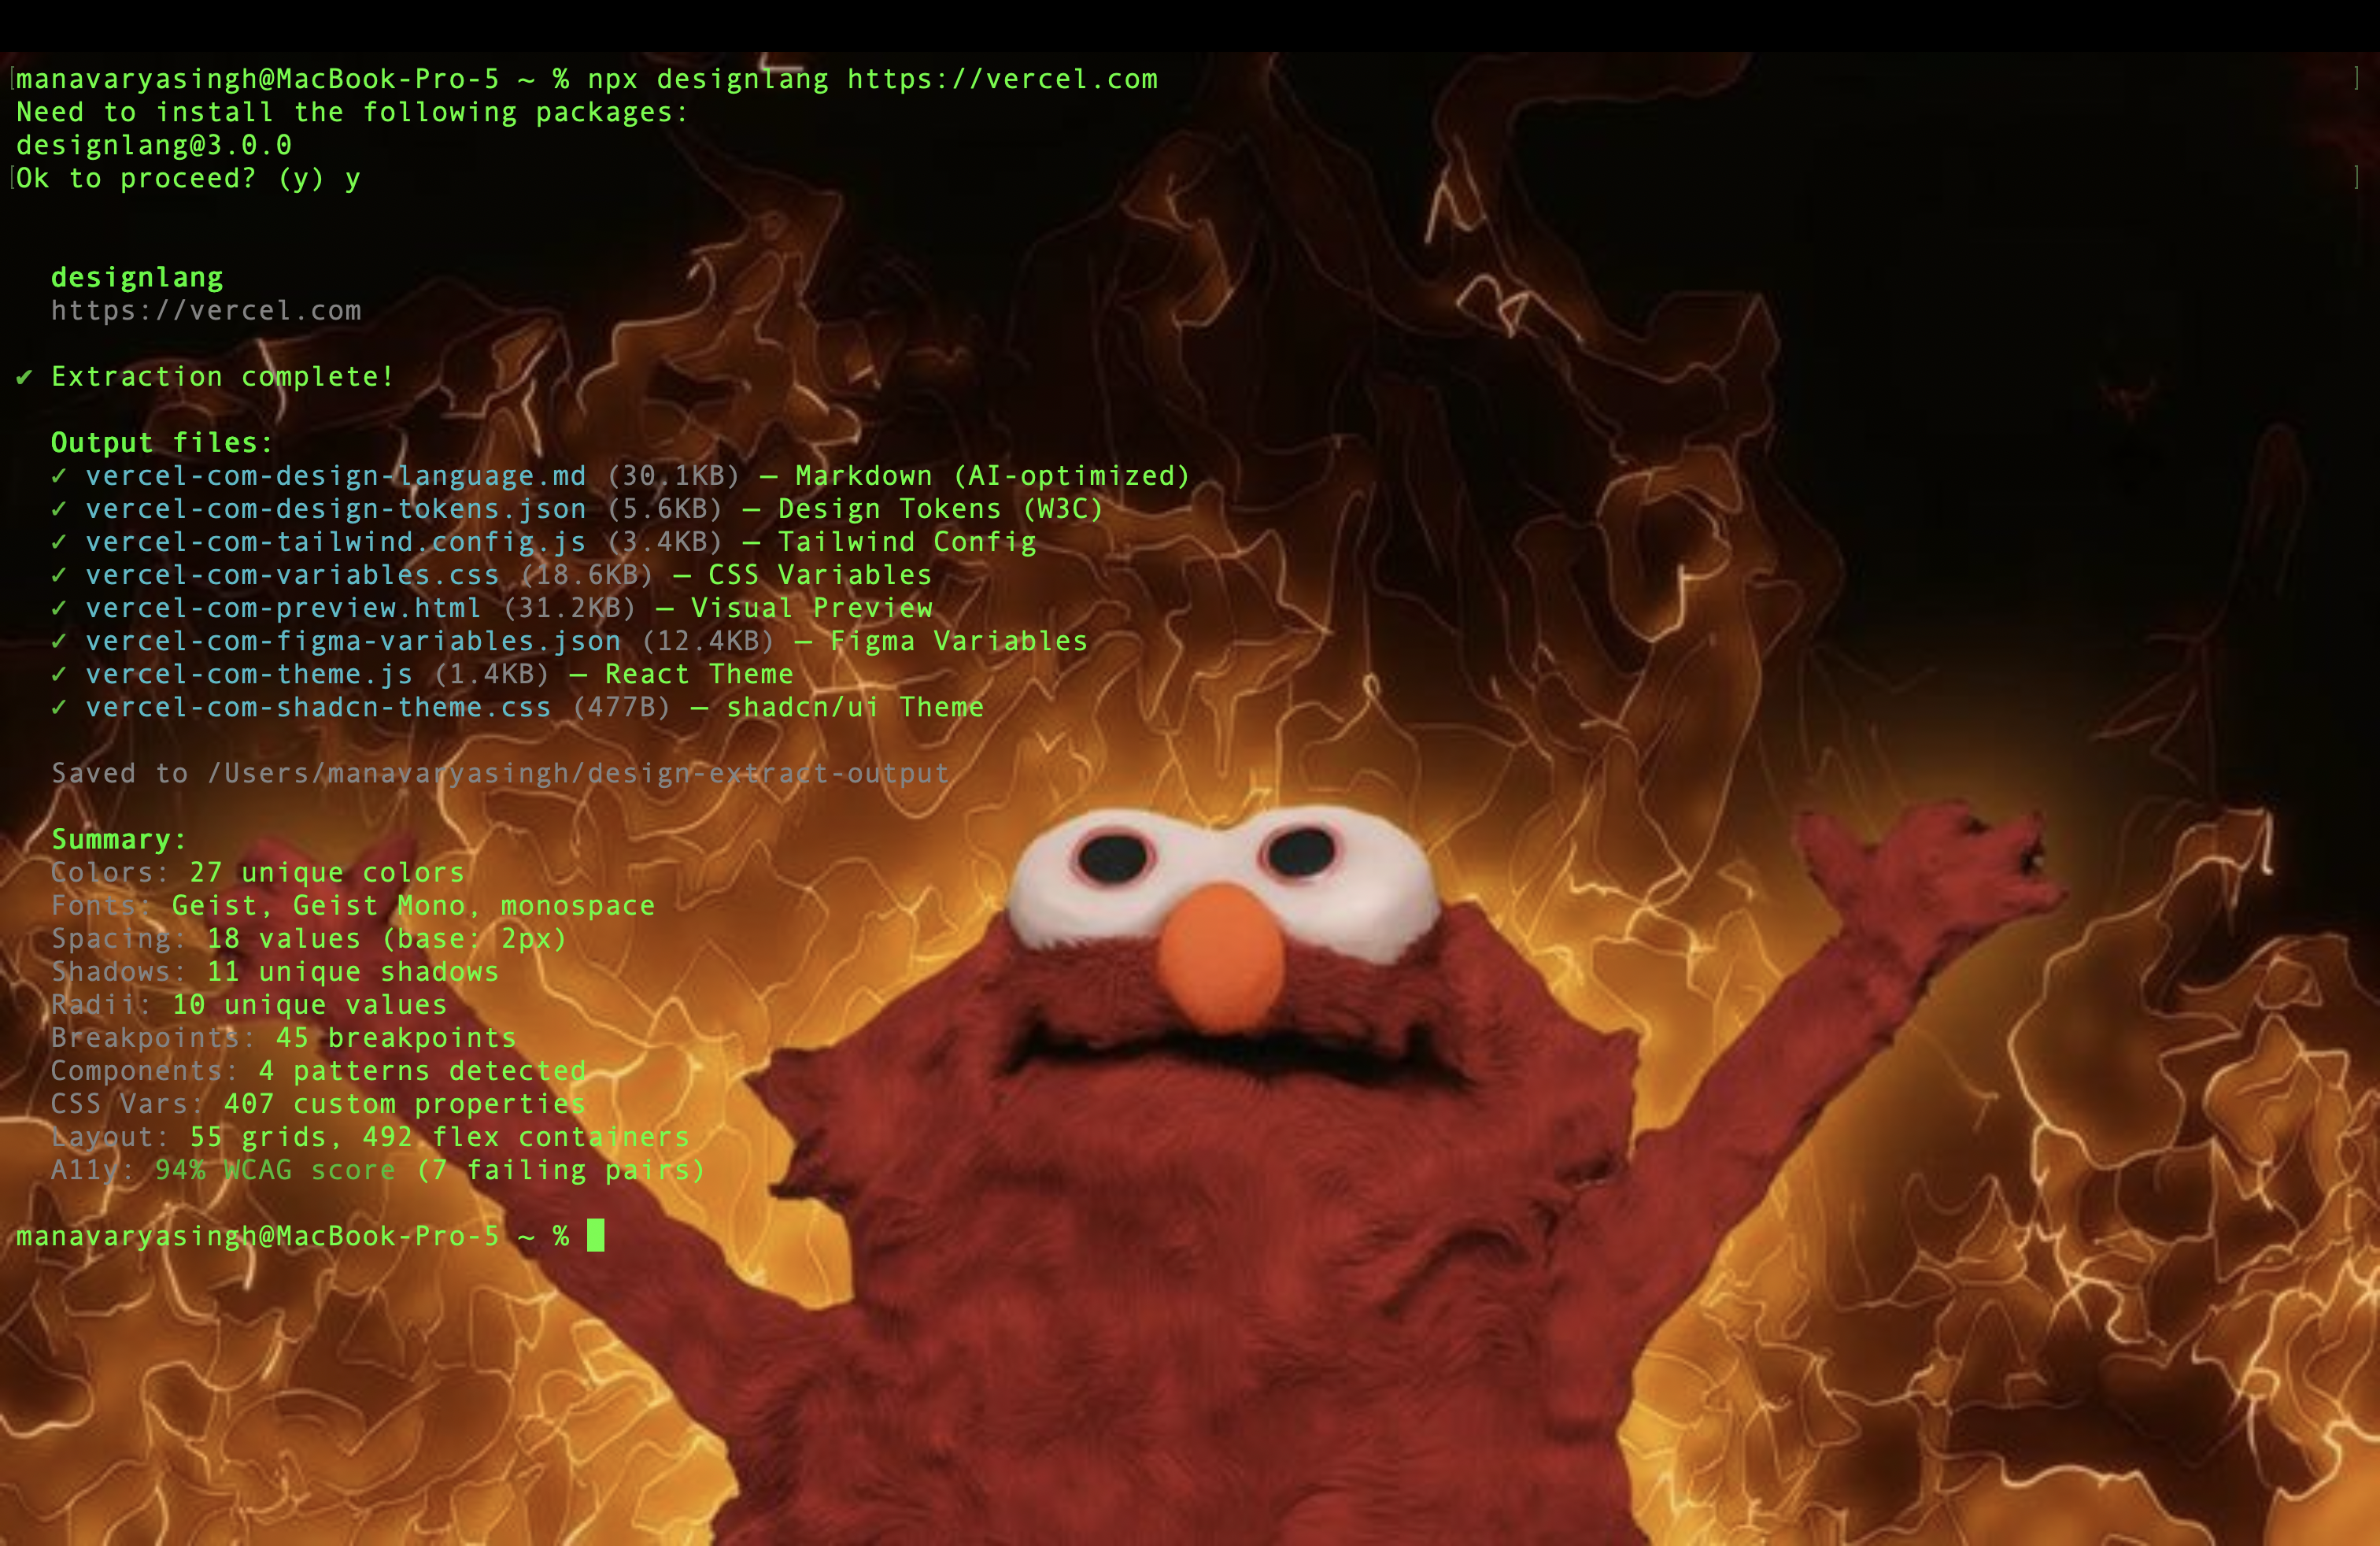
Extract any website's complete design system with one command. DTCG tokens, semantic+primitive+composite, MCP server for Claude Code/Cursor/Windsurf, multi-platform emitters (iOS SwiftUI, Android Compose, Flutter, WordPress), Tailwind v4, Figma variables, shadcn/ui, CSS health audit, WCAG remediation, Chrome extension. MIT, Playwright, Node 20+.

Quickly reads webpages and converts to markdown for fast, token efficient web scraping

🎨 Open-source design MCP server + shadcn/ui registry — AI design systems for Claude Code, Cursor, Codex, GitHub Copilot & any MCP client. 31 brand-grade themes (Linear, Stripe, Vercel, Notion, Apple, Supabase, Figma…) + design tokens, UI principles & WCAG rules. Install any component with one command.

Open-source control plane for your AI agents. Connect tools, hire agents, track every token and dollar

Hooks that force Claude Code to use LSP instead of Grep for code navigation. Saves ~80% tokens

Structured skill framework for Claude Code. 130 skills, persistent memory, TokenStack compression, localhost dashboard with 3-agent runner, real-time streaming, MCP tools.
(HAM) Memory system for AI coding agents. Cut token usage by 80% by scoping context to directories.
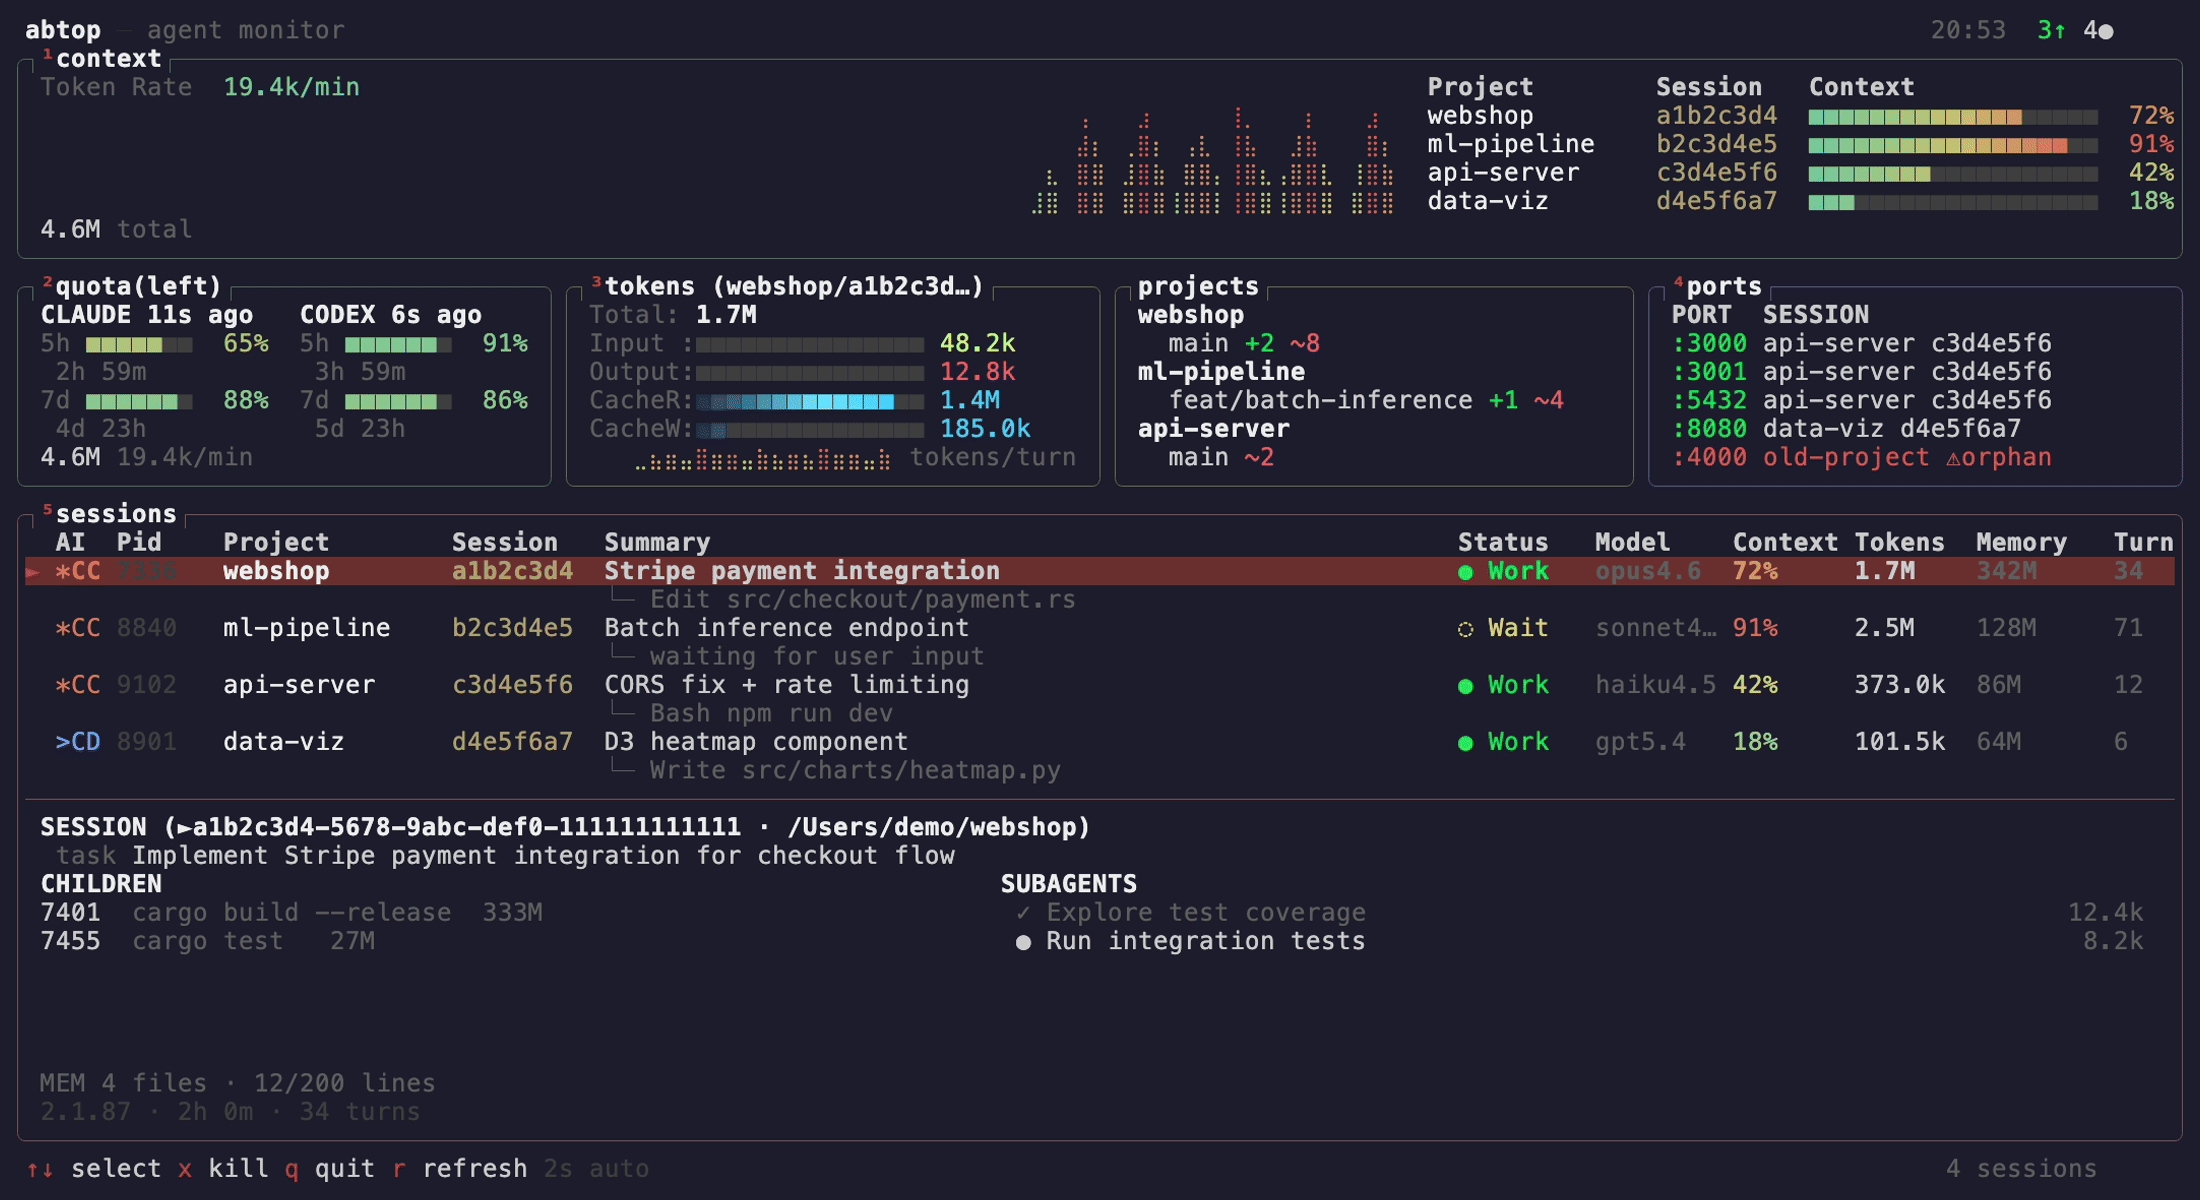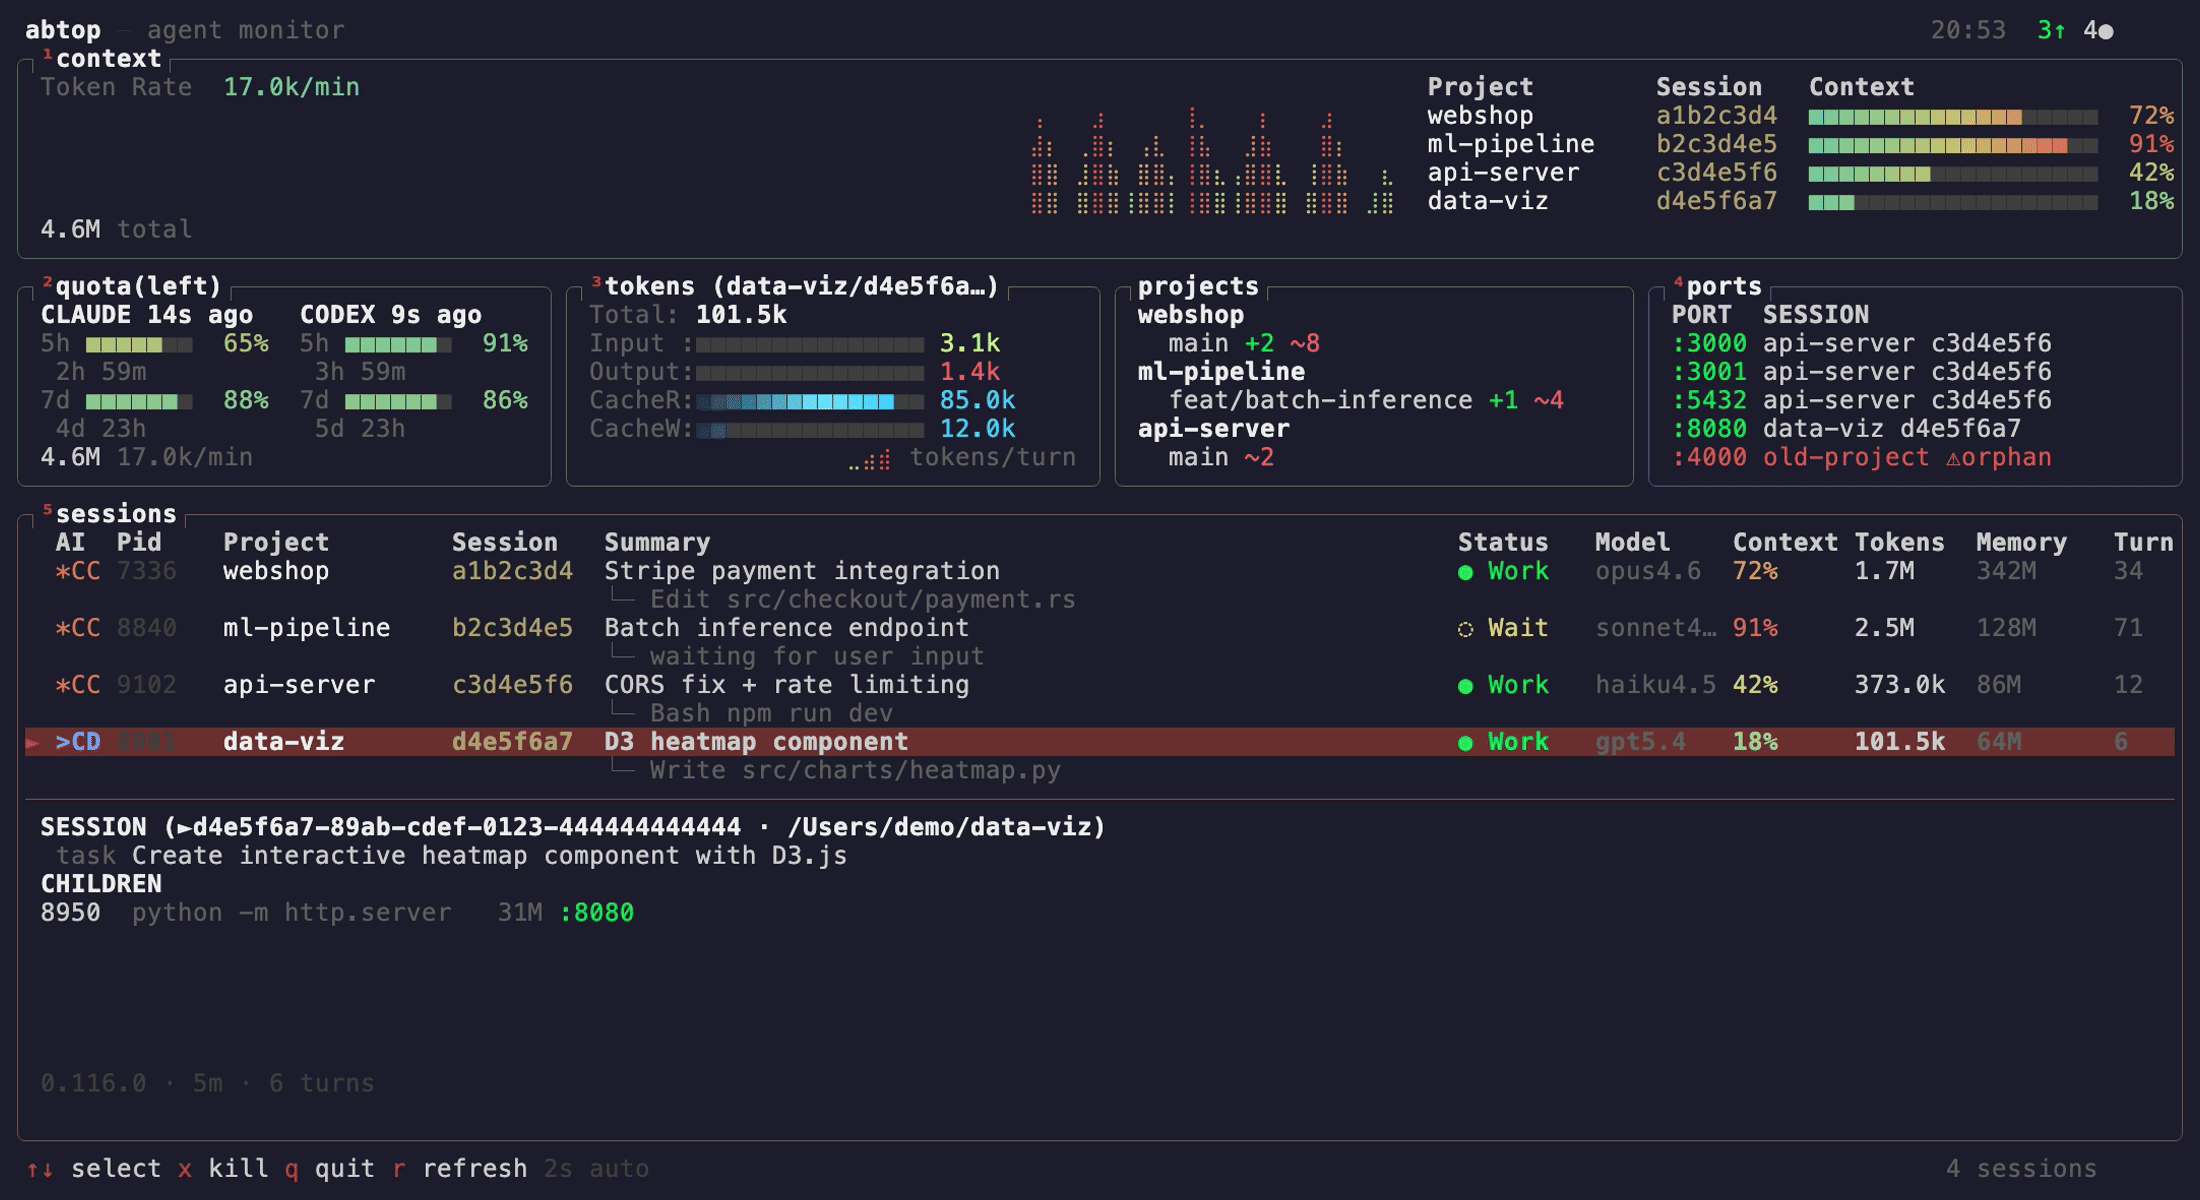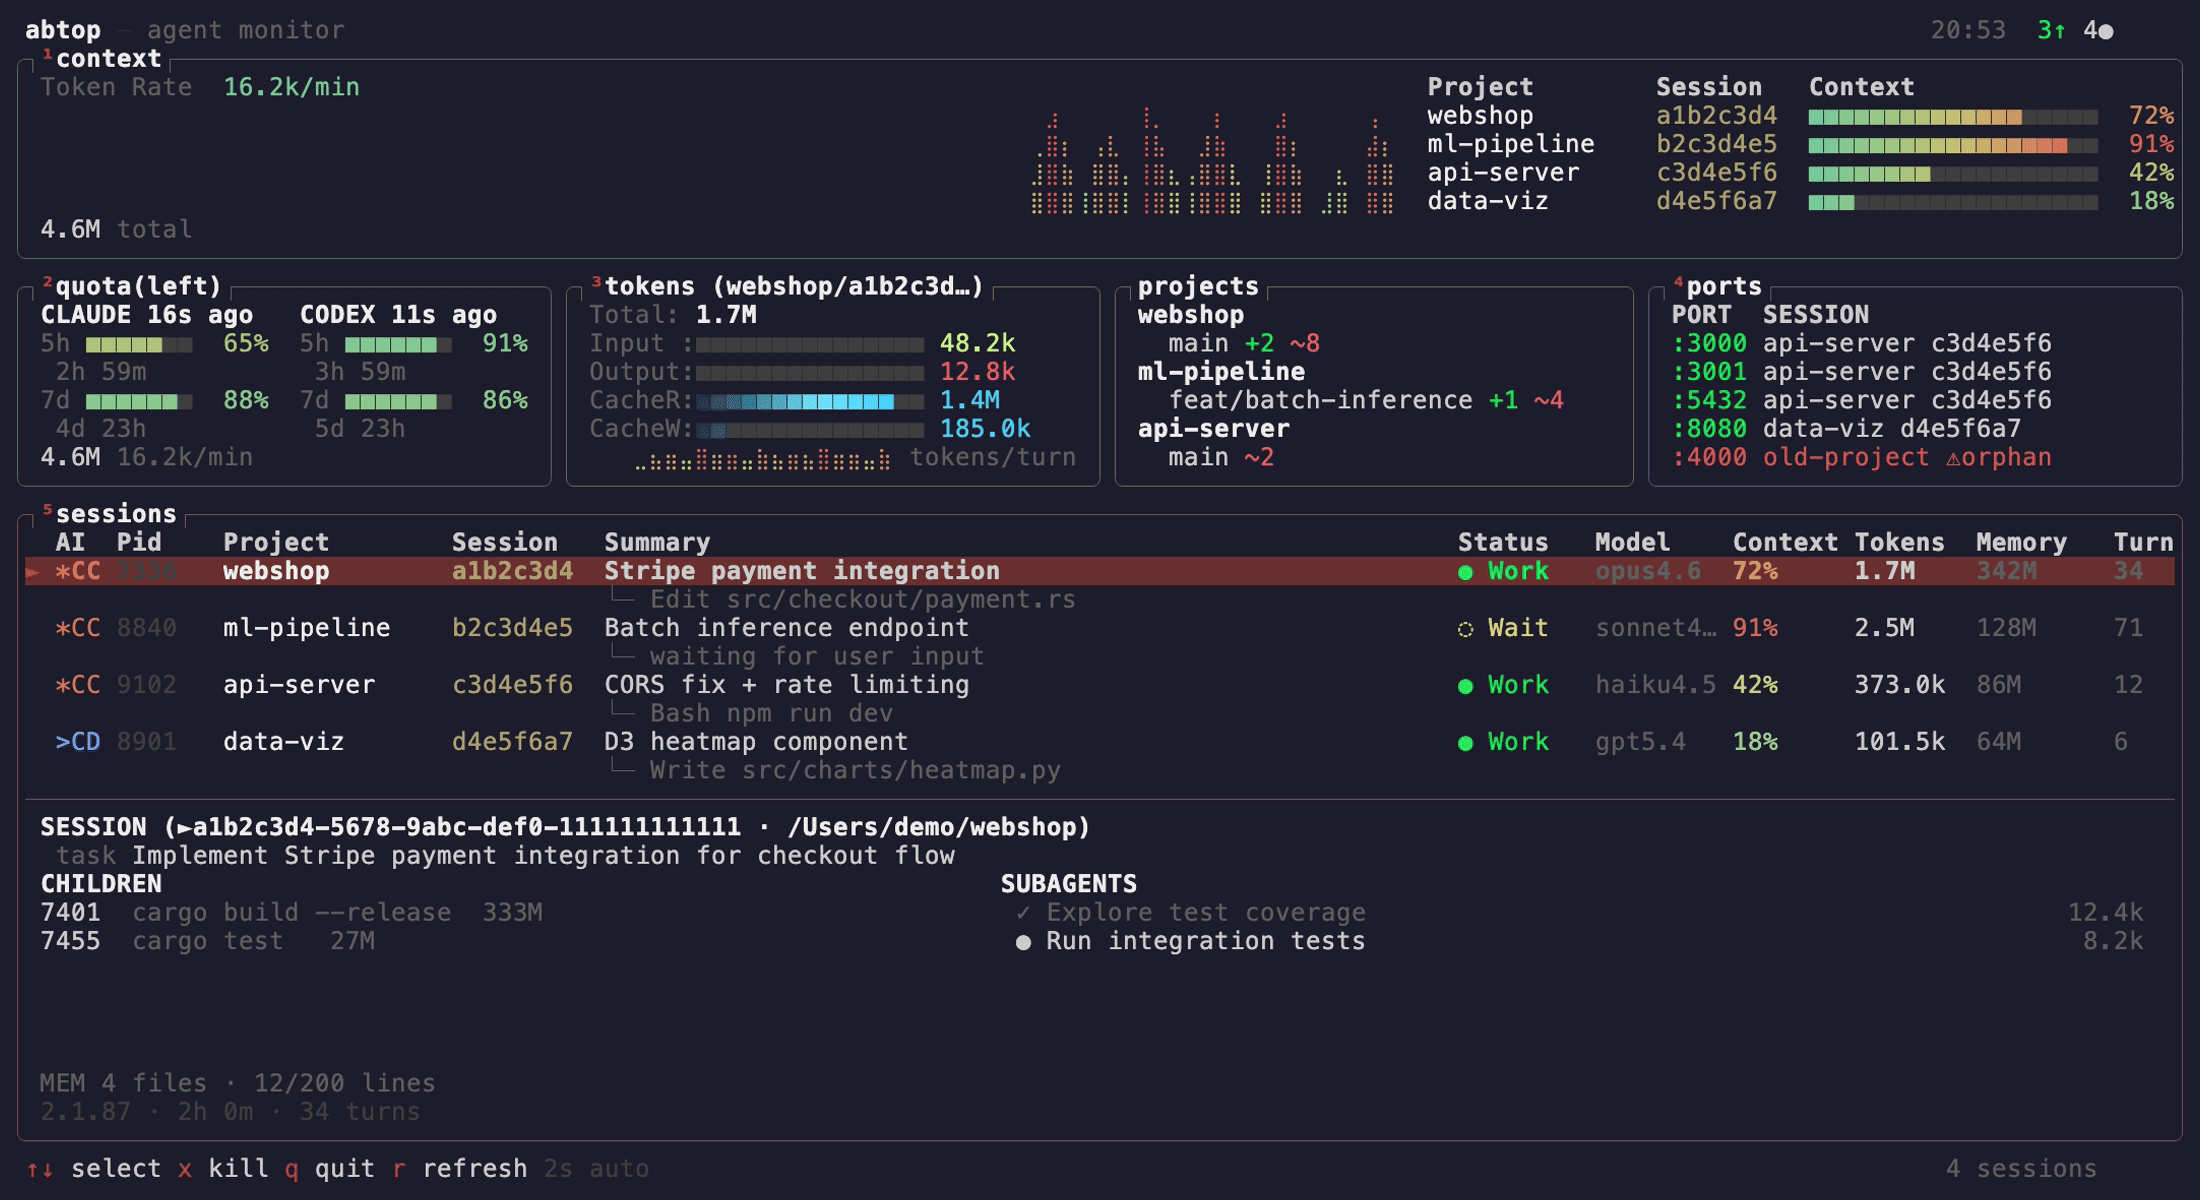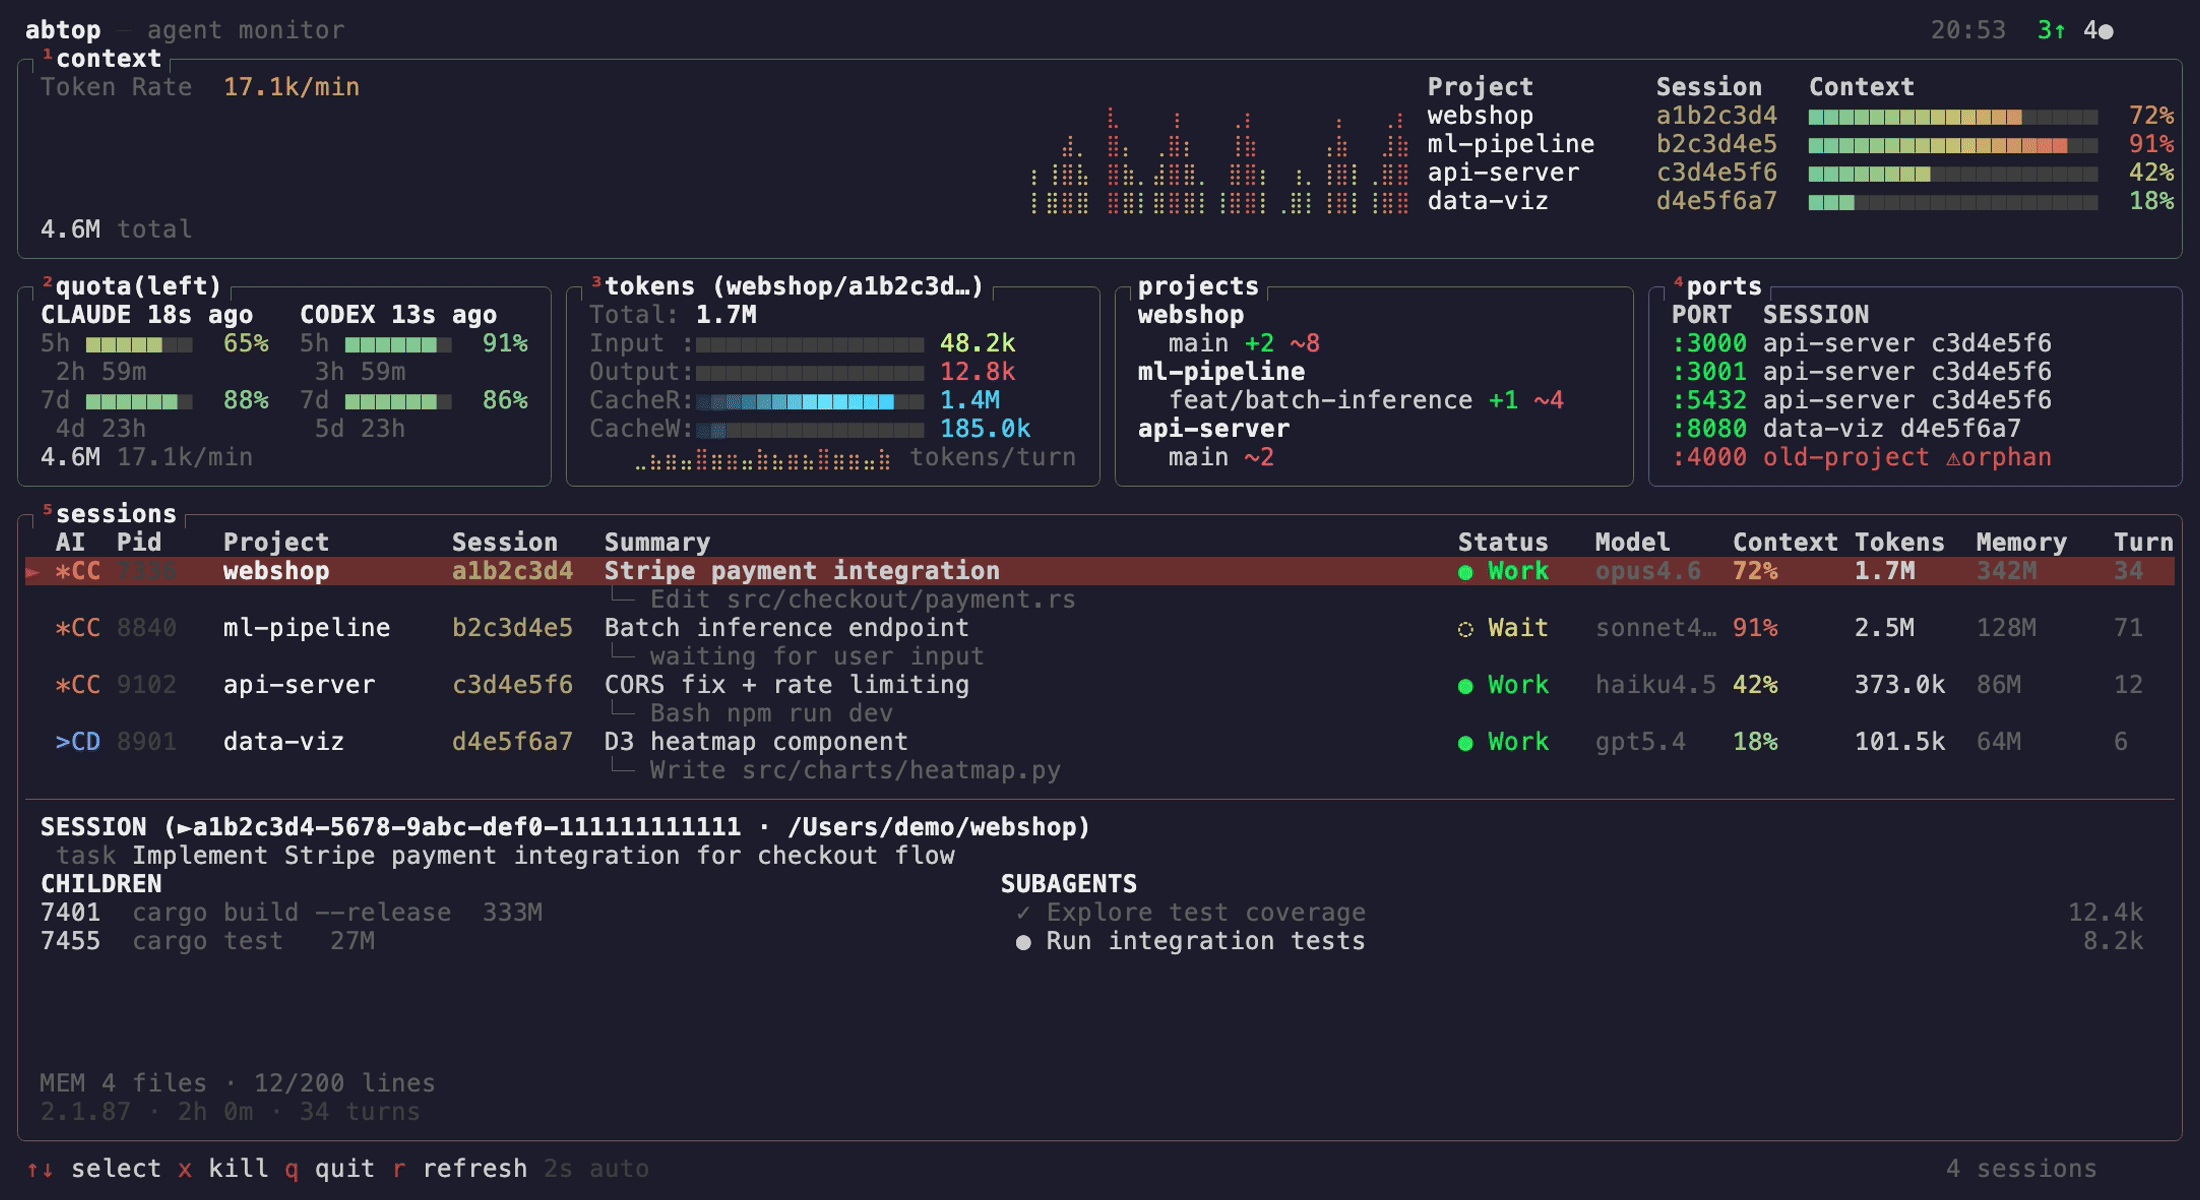
Like htop, but for AI coding agents. Monitor Claude Code & Codex CLI sessions, tokens, context window, rate limits, and ports in real-time.
A headless browser for AI agents that fetches modern web pages, runs JavaScript, manages sessions, and returns token-efficient Markdown.
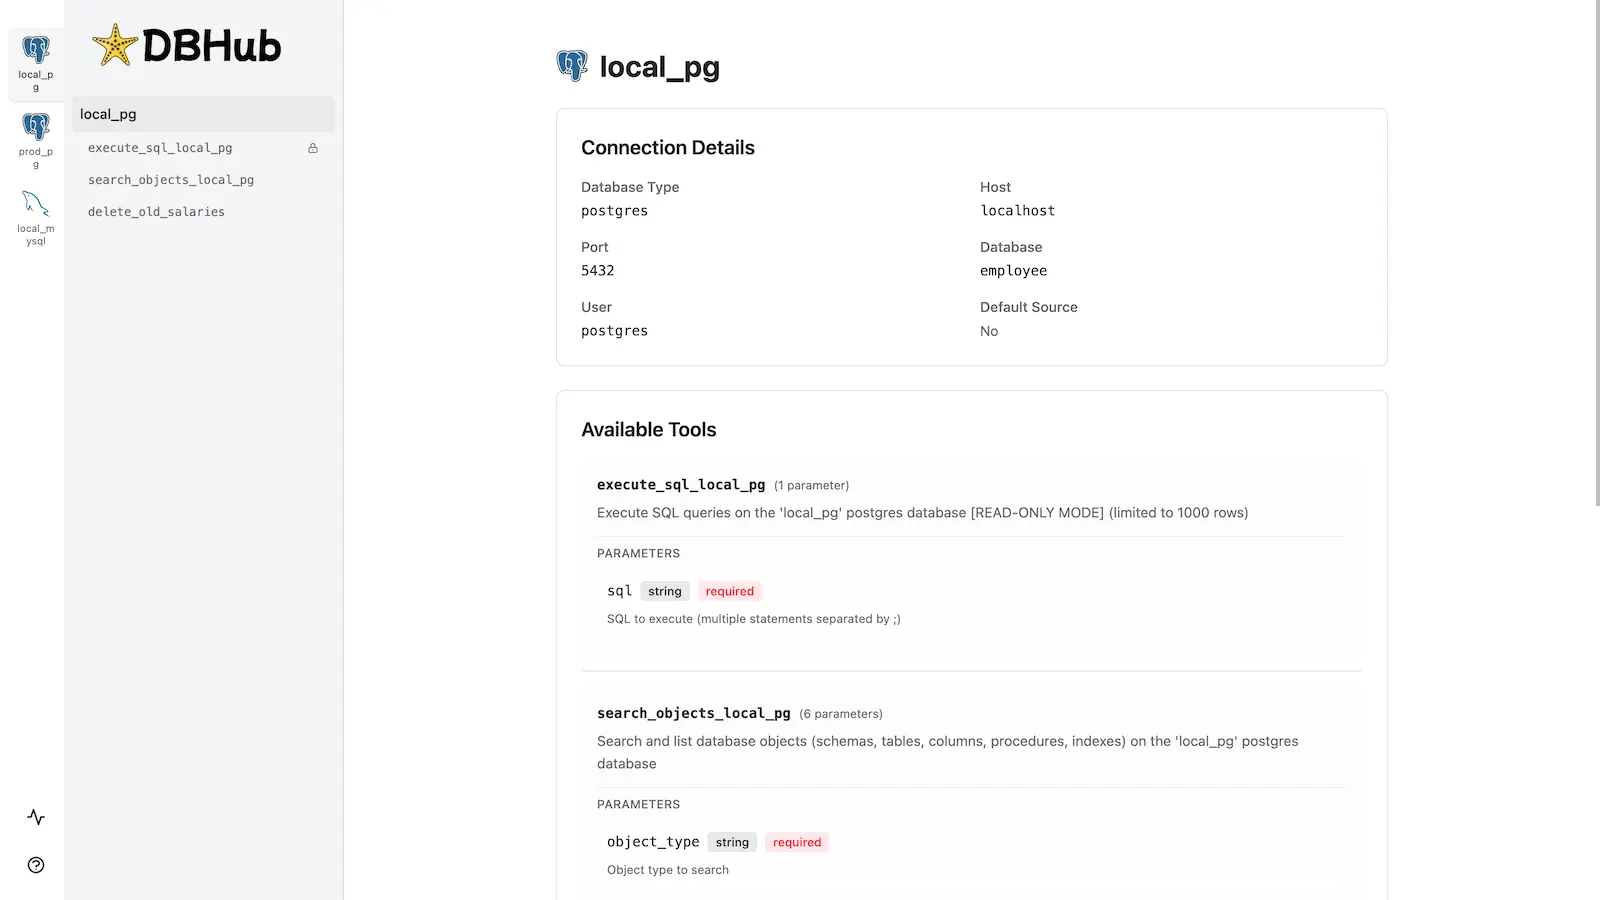
Token conscious database MCP server for Postgres, MySQL, SQL Server, MariaDB, SQLite.

Turn any website into a compact CLI tailored for AI agents. Browse the web in hundreds of tokens, not tens of thousands.
30 sec to give your AI agents persistent memory. Reduce 90% token consumption while also maintaining quality.