ddalcu/
mlx-serve

ddalcu/mlx-serveTools
Native LLM inference server for Apple Silicon. OpenAI + Anthropic API compatible. No Python. Includes MLX Core macOS app with chat, agent mode, and tool calling.
1.2k
Native LLM inference server for Apple Silicon. OpenAI + Anthropic API compatible. No Python. Includes MLX Core macOS app with chat, agent mode, and tool calling.
An ML engineering plugin for your coding agents.

Model Context Protocol (MCP) server for Opik, the open-source LLM observability and evaluation platform, built by Comet. Read traces, log scores, and manage prompts from Claude Code, Cursor, or VS Code.
Adaptive Python web scraping toolkit + MCP server for AI agents. Self-healing selectors that survive site changes, TLS-fingerprint stealth to bypass anti-bot filters, CSS/XPath parsing, and 24 built-in scrapers, clean, structured, LLM-ready data from any URL.
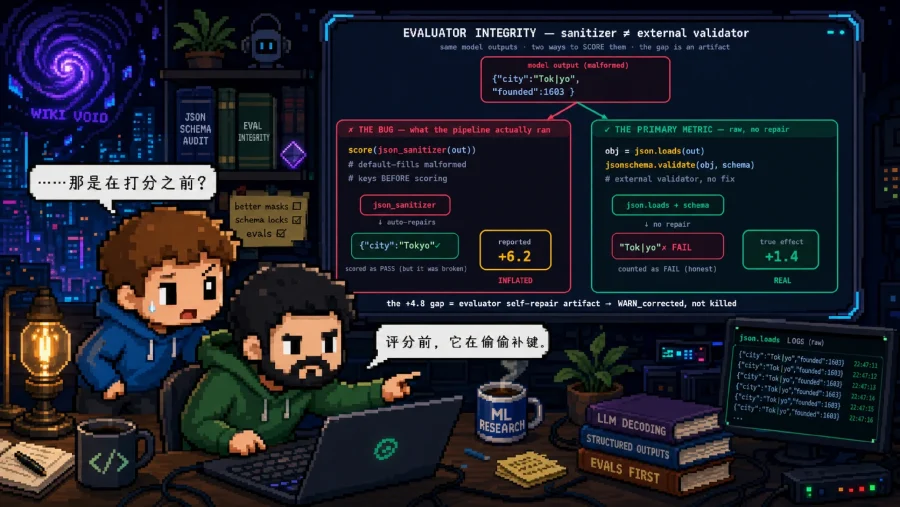
ARIS ⚔️ (Auto-Research-In-Sleep) — Lightweight Markdown-only skills for autonomous ML research: cross-model review loops, idea discovery, and experiment automation. No framework, no lock-in — works with Claude Code, Codex, OpenClaw, or any LLM agent.
The python library for research and development in NLP, multimodal LLMs, Agents, ML, Knowledge Graphs, and more.

A highly customizable agentic harness for arXiv-ready ML/AI review papers (and beyond). It drives agentic AI like Codex CLI and Claude Code through a gated LaTeX workflow with verified BibTeX citations.
The Context Layer for unstructured data: typed, versioned datasets over S3, GCS, Azure

a recursive self-improving harness designed to help your agents (and future iterations of those agents) succeed on any task

🔥 An autonomous AI agent that runs your deep learning experiments 24/7 while you sleep. Zero-cost monitoring, Leader-Worker architecture, constant-size memory.

An Agent Skill for the DL experiment lifecycle: RUN (a GPU you own or rent) → VERIFY the number is real → DELIVER reproducible, single-source figures and tables.

Loop until it's better — drop-in agentic loops (autoresearch, scientific writing, data analysis, code/SQL/prompt optimization, red-teaming) as open-standard Agent Skills. Verification-gated; native on Claude Code, portable across Codex, Cursor & other Skills hosts.

Don't trust an autoresearch paper at face value. Reviewer-side integrity forensics (self-consistency + fabrication), deterministic verdict. 61 signals: 46 integrity hack-patterns (families A–H, verdict-bearing) + 13 zero-weight AI writing-style impressions (AIS) + 2 advisory. Not an opaque AI-text classifier. The dual of ARIS.

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.

Offline context handoff between coding agents. Read local histories into fresh sessions; source stores stay unchanged. Stdlib-only Python, not live session restore.