

obra/
superpowers

obra/superpowersSkills
An agentic skills framework & software development methodology that works.
285k
1 add
ARIS packages research workflows as Markdown skills that agents can follow for review loops, experiment automation, novelty checks, and paper writing. It is built to work with Claude Code, Codex, Cursor, and other agents, with extra MCP servers and docs for integrations and setup.
Builders who want their agent to plan, review, and write research work in a repeatable workflow.
You can turn agent-led research into a reusable loop instead of re-explaining the process every session.
`skills/` contains many reusable skills such as `idea-discovery`, `auto-review-loop`, `experiment-plan`, `novelty-check`, and `paper-write`.
The repo includes review flows and MCP servers for Claude, Codex, and Gemini-style review passes so one model can check another.
Skills like `experiment-queue`, `monitor-experiment`, `experiment-audit`, and `analyze-results` shape how experiments are planned and reviewed.
Skills for `paper-compile`, `paper-figure`, `paper-slides`, `paper-talk`, and `paper-poster` support research output assembly.
`AGENT_GUIDE.md`, `SETUP_GUIDE.md`, and the `docs/*ADAPTATION.md` files explain how to adapt ARIS to different agents and editors.
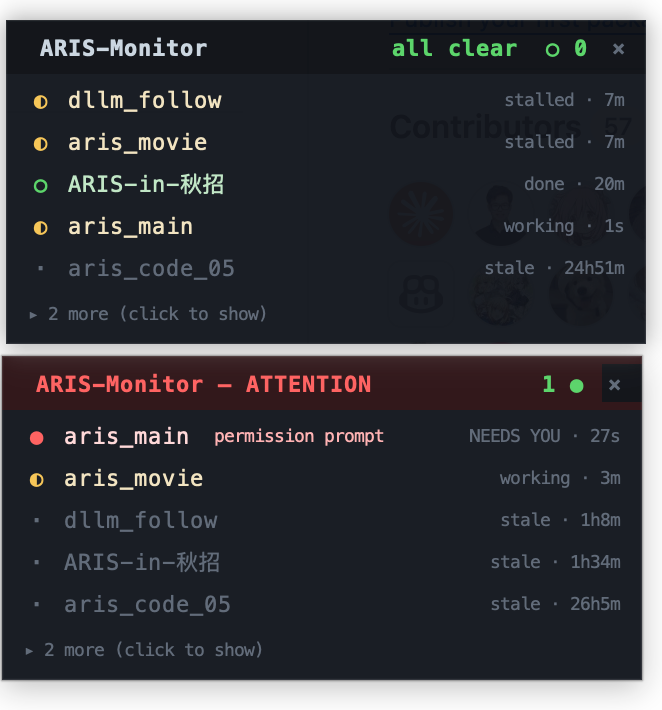
`aris-monitor/` provides a small always-on-top widget that shows when a session needs approval and lets you jump to it.
# In Claude Code:
> /research-wiki init                         # creates research-wiki/ in your project
# That's it. From now on, /research-lit auto-ingests papers, /idea-creator reads
# the wiki before brainstorming (and writes ideas back), /result-to-claim updates
# claim status. Failed ideas become anti-repetition memory for future ideation.
# One-time setup in your project directory
mkdir -p .claude .aris/meta tools/meta_opt
cp Auto-claude-code-research-in-sleep/templates/claude-hooks/meta_logging.json .claude/settings.json
cp Auto-claude-code-research-in-sleep/tools/meta_opt/*.sh tools/meta_opt/
chmod +x tools/meta_opt/*.sh
# Then start Claude Code — hooks are active immediately
claude
pip install deepxiv-sdk
pip install exa-py
export EXA_API_KEY=your-key-here
cd Auto-claude-code-research-in-sleep && ls skills/ | xargs -I{} rm -rf ~/.claude/skills/{}npm install -g @openai/codex claude mcp add codex -s user -- python3 "$HOME/aris_repo/mcp-servers/codex-exec/server.py"







💡 Use ARIS as a skill-based workflow in Claude Code / Codex CLI / Cursor / Trae / Antigravity / GitHub Copilot CLI / OpenClaw / DeepSeek Harness, or get the full experience with the standalone ARIS-Code CLI — enjoy any way you like!
❗ 
codex mcp-server — the entry point every ARIS reviewer call used. No impact on ARIS: the codex MCP server is now ARIS's own bridge over codex exec (mcp-servers/codex-exec/), same tools, same results, all 82 skills unchanged, ultra and per-thread resume intact. One re-registration is all it takes — already installed? → Quick Start step 2b · new install → step 2 · what changed.
🎯 准备 2026 AI 秋招? → 🌐 ARIS-in-AI-Offer · GitHub repo · 中文 README —— 23 篇双语 ML / LLM / 多模态 / 生成式 / Agent 面试 cheat sheet,每篇 = 公式推导 + 从零 PyTorch + 25 高频面试题(L1 / L2 / L3),全部由 ARIS 的 /render-html 自动生成。希望大家秋招轻松一点 🌱
🐋 On DeepSeek Harness it installs as one plugin: dsh plugin --profile web add dsh-aris (fetches from npm by itself — no separate install step, but pnpm must be on PATH) — all 82 skills unchanged, Codex still the independent reviewer. Setup and limits on the dsh-aris branch.
🌱 ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.
🤖 AI agents: Read AGENT_GUIDE.md instead — structured for LLM consumption, not human browsing.
🧱 Two repos, one disease — agents that over-defend, papers that read like autoresearch. HERO: a ~550-token block for CLAUDE.md / AGENTS.md against Hashing, Edge cases, Rubrics, Overbuild — bounds what the agent proposes, never what it looks for. Anti-Autoresearch: 61 integrity signals into a deterministic, reviewer-ready report — fabrication forensics, not an AI-text detector.
🎬 ARIS goes multimodal → ARIS-Movie-Director — hand it a rough story and get back a movie told in still frames, checked scene by scene (the reference run has 19 scenes). Long stories usually break when the model forgets earlier details or judges its own work — so ARIS keeps a research-wiki for memory and has other models check every frame.
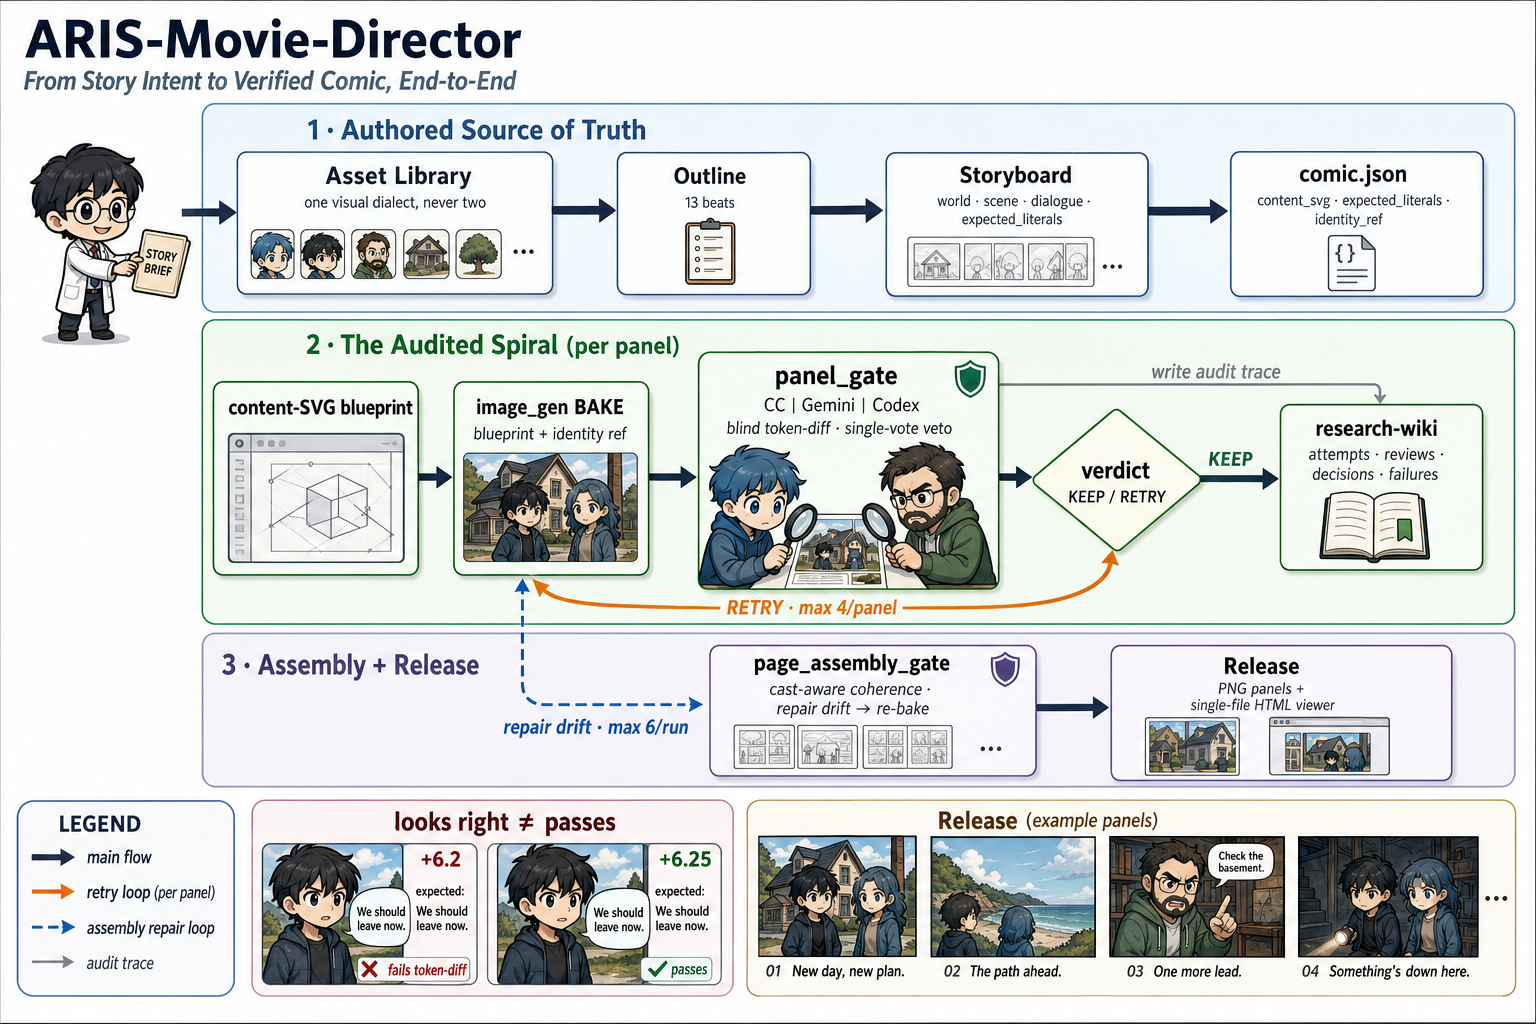
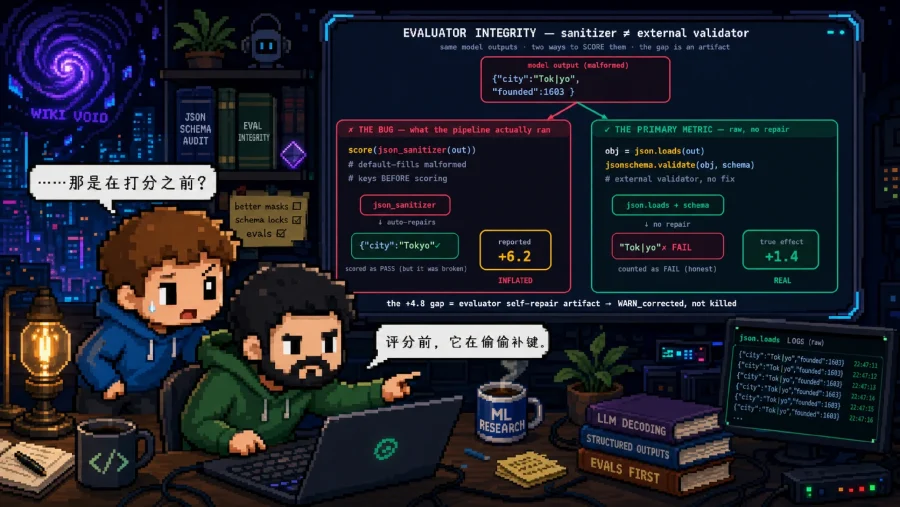
🧭 The same loop also makes clean method / flow diagrams — the figure above was made with it. Entry points in ARIS-Movie-Director:
/movie-pipelineand/method-figure, the skill that made this figure.
+6.2 but really moved +1.4. ▶ watch all 19 scenes → | 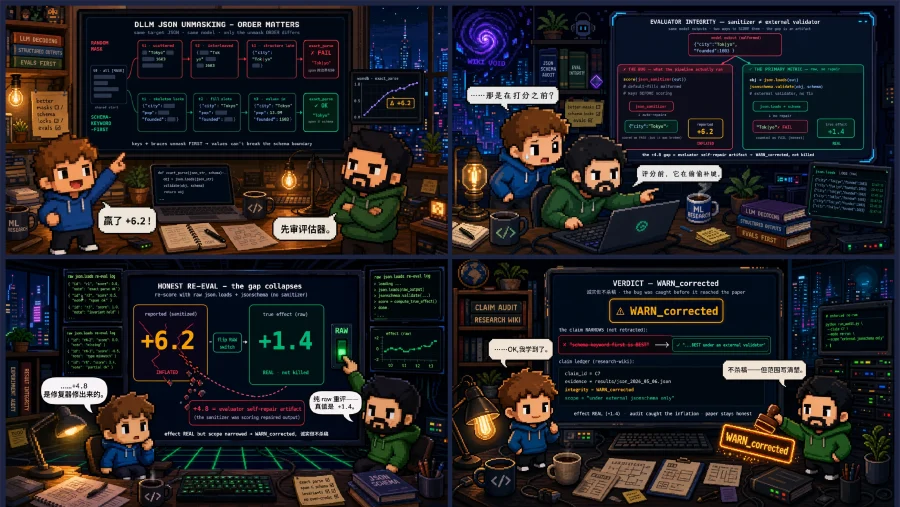 | 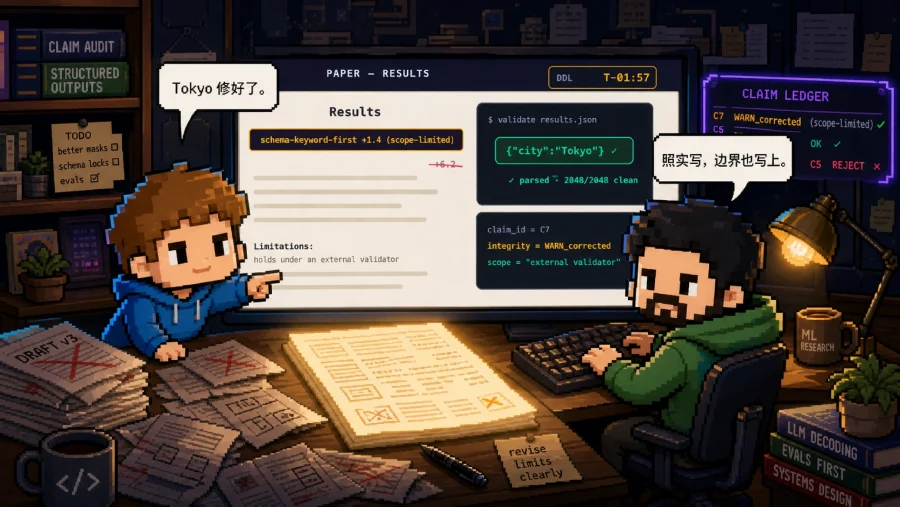 |
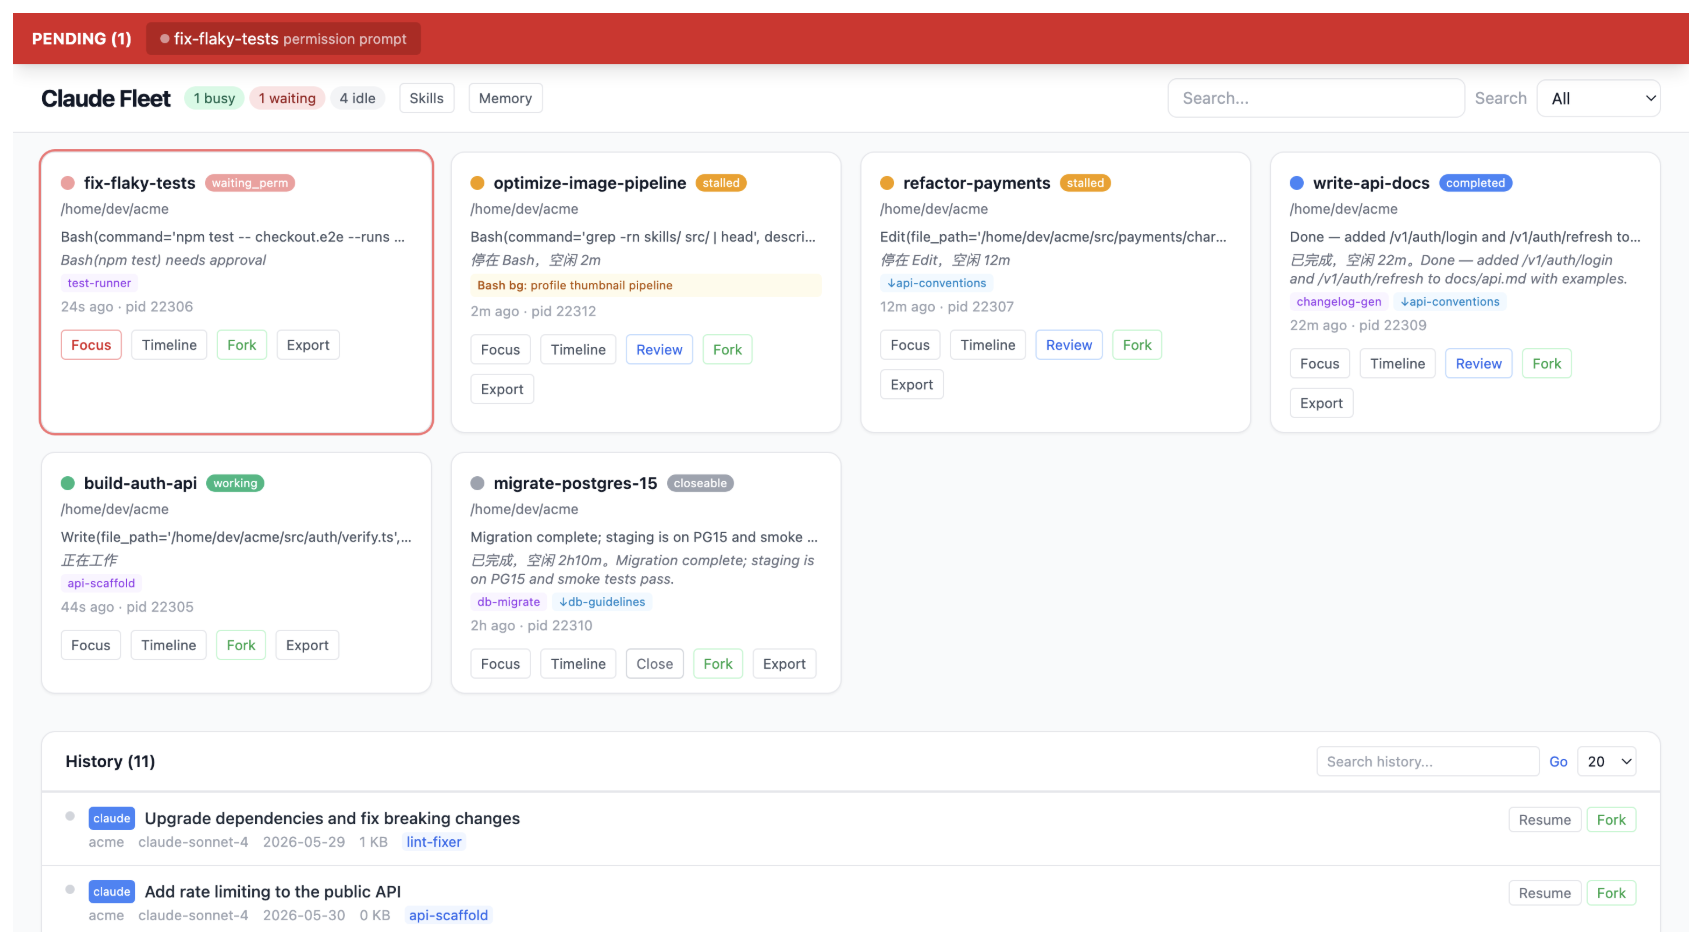
🛰 Keep an eye on your agent windows — Claude Fleet (by @tianyilt; local read-only dashboard for many parallel Claude Code / Codex windows, full-text transcript search — worth a ⭐), or the lighter built-in ARIS-Monitor (a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval; click to jump there).
|
|
| Claude Fleet · 全功能网页看板 | ARIS-Monitor · 极简悬浮小窗(自带) |
ARIS-Monitor — built-in, no clone / no pip / no browser:
cd aris-monitor && ./run.sh
# a borderless panel floats top-right; click a row to jump to that terminal
Claude Fleet — full web dashboard:
git clone https://github.com/tianyilt/claude-fleet
cd claude-fleet && bash run.sh
# open http://127.0.0.1:7878 in your browser
🚀 Beyond 科研 → 任何 "研究":ARIS-Anything 把 ARIS 的五步 loop(plan / draft / 对抗审 / 迭代 / 持久化)推广到非学术的结构化研究——投资尽调 / 法律研究 / 市场研究 / 自驱学习 / 调查新闻 / 工程复盘等。
🔥 ARIS-Code CLI — 独立安装版 · English | ⬇️ Download ·
|
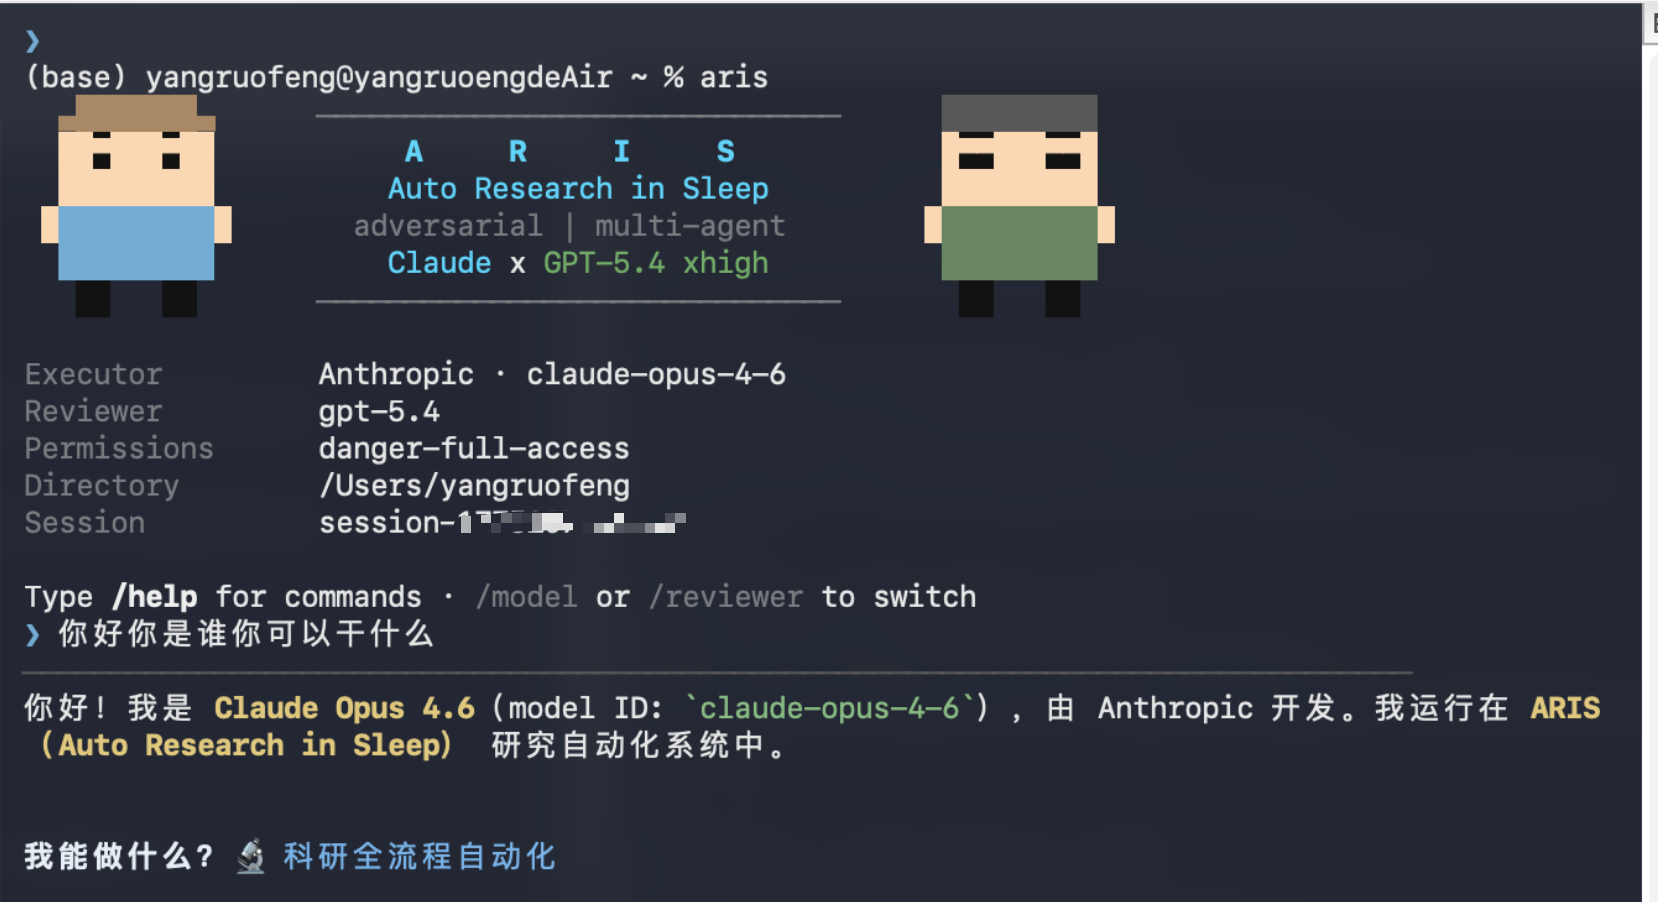
📰 ARIS-Code v0.4.24 (2026-08) — latest is the Claude 5 model refresh (#392): first-class Claude Opus 5 (new default, same $5/$25 tier) and Claude Fable 5 (Mythos-class flagship, correct $10/$50 pricing) — |
|
Per-release details (v0.4.5 → v0.4.24)
v0.4.24 (2026-08-09) — the Claude 5 model refresh (#392, requested by @YukinoshitaLove). Explicit
--model claude-opus-5/claude-fable-5already passed through on every platform — this release makes them first-class. Default →claude-opus-5(main session, subagents,aris setup; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered chain walk (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise404 not_found_error, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks./modelpicker adds Fable 5 / Opus 5 / Sonnet 5; newfablealias. New Mythos-class pricing tier (fable/mythos= $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.v0.4.23 (2026-08-02) — the output-folding release (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). 🧹 Tool-output folding, display layer ONLY: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context,
--output-format jsonand/exportare untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. 🐛 Bash timeout now kills the command: a timed-out call reportedinterrupted: truewhile the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatchARIS_BASH_KILL_ON_TIMEOUT=0; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). 📦 Bundle 79→81 (pin 7182624 → 3e49e63):/integrity-forensics— the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and/web-debug-search, +tools/forensics_gate.py (29 helpers, 104 embedded resources). 🎁 Also: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that"numMatches": nullserializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green under a live proxy; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).v0.4.22 (2026-07-12) — the skills-resync + GPT-6-Astra release. 📦 Bundle resync (pin 7e3ab67 → 7182624, 93 commits): 79 bundled skills (+
meta-apply, +paper-poster-html;paper-posterretired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening —ARIS_SYNC_EXPECT_SHAguard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. 🎛 GPT-6-Astra two-tier reviewer alignment: the CLI's system-prompt nudge now passes the skills' explicitmodel: gpt-6-astra+ per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pinsapproval-policy: "never"+ explicitsandboxon every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display//reviewerare honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). 🐛 8 verified fixes: explicit--modelwas silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices;/modeland/setupre-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution);--output-format jsonnever prompts (locked by a real end-to-end binary test against a mock SSE server); Windowsaris loginfixed (PKCE randomness read /dev/urandom → getrandom); Windows command probing fixed (the PowerShell tool probed itself throughsh; now where.exe); codex.cmdshims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. 🖥 New windows-latest CI job (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.v0.4.21 (2026-06-28) — bug-fix patch: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). 🐛 Headline: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into
�— each HTTP body chunk wasfrom_utf8_lossy'd independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. A saved OpenAI/custom executor config no longer overrides a shell-setEXECUTOR_PROVIDER— the startup "shell-provided vars win" path had one ungated write that re-pointedEXECUTOR_PROVIDER=anthropic … aris …to OpenAI (wrong executor / model-not-found). An Anthropic stream truncated after content but before a terminal signal now hard-errors (premature_eof) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI#249guard; thestop_reason-only compat path is preserved, andARIS_ALLOW_EOF_WITHOUT_STOP=1opts a terminal-signal-less proxy back into the old behavior).grep_searchwithmultiline: truenow matches across lines in content mode (was silently empty —countmode already worked). MCP tool results carried only instructuredContent(emptycontent) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends withmessage_stop) was WebFetch-verified. Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) remain deferred.v0.4.20 (2026-06-19) — bug-fix patch: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). 🐛 Headline (#299): short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, but
finishthen cleared that whole line, erasing a short single-line reply. The REPL now finishes without clearing when the turn printed visible text (Clear(UntilNewLine)wipes only the spinner tail after the reply). Streamed multi-paragraph replies rendered glued ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). Markdown tables with CJK/fullwidth content misaligned — width now counts display cells (CJK = 2), not chars.aris "prompt"/aris setup(REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. Esc now actually closes the completion dropdown (it was recomputed right back).glob_searchreports the total matched count when truncated (not the capped 100, which made the model think a 1000-match glob had 100 files)./model's custom menu reads the effective env the executor uses, not stale on-disk config. Tests (CI mode): api 32 / runtime 205 / tools 67 / aris-cli 172 / commands 5, all green; +7 new; real-machine verified (short reply renders + "✔ Done"; paragraphs keep their blank lines). Codex MCP (gpt-5.5 xhigh): hunt → 3 review rounds (NO-GO → NO-GO → GO). Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) deferred to a hardening pass.v0.4.19 (2026-06-14) — honesty / guardrails patch (theme from a Codex fresh-eyes audit; no behavior change for healthy setups). 🔴 MCP protocol-version negotiation guard — the stdio handshake requested
2025-03-26but never read the version the server negotiated back (a parsed-but-dead field), so a server agreeing on a version ARIS can't speak was silently accepted and latertools/list/tools/callran on an incompatible protocol with opaque failures. ARIS now validates the negotiated version against a supported set (2025-11-25/2025-06-18/2025-03-26/2024-11-05— stdio framing is identical
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
An agentic skills framework & software development methodology that works.

Turn any codebase, with its docs, SQL schemas, configs, and PDFs, into a queryable knowledge graph. A /graphify skill for Claude Code, Cursor, Codex, and Gemini CLI: local deterministic AST parsing, every edge explained, no vector store.

Topic in, narrated explainer video out. A Claude Code / Codex skill that turns any topic into a black-canvas motion-graphics explainer video with TTS voiceover, subtitles and a chapter progress bar. Chinese or English; every frame drawn in code with Remotion.
Public repository for Agent Skills
Open-source AI job search: scan job portals, evaluate listings into a structured A-H report with a global 1-5 score, tailor your CV, track applications — runs locally in your AI coding CLI (Claude Code, Codex, OpenCode, Antigravity…)

Production-grade engineering skills for AI coding agents.