A lightweight MCP (Model Context Protocol) server for integrating ComPDF AI with Claude Desktop, enabling AI-powered intelligent document processing and data extraction from PDFs via natural language.
LinkedIn automation skills for AI agents – sales, social selling, data extraction, and more.
Model Context Protocol server that integrates AgentQL's data extraction capabilities.

Browser automation CLI built for AI agents. Break through anti-bot walls, hand off to humans across platforms when stuck. Parallel multi-task execution, independent multi-session operation, isolated multi-account browsing.
Analysis of Claude Code spinner words and their version history.
🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl!

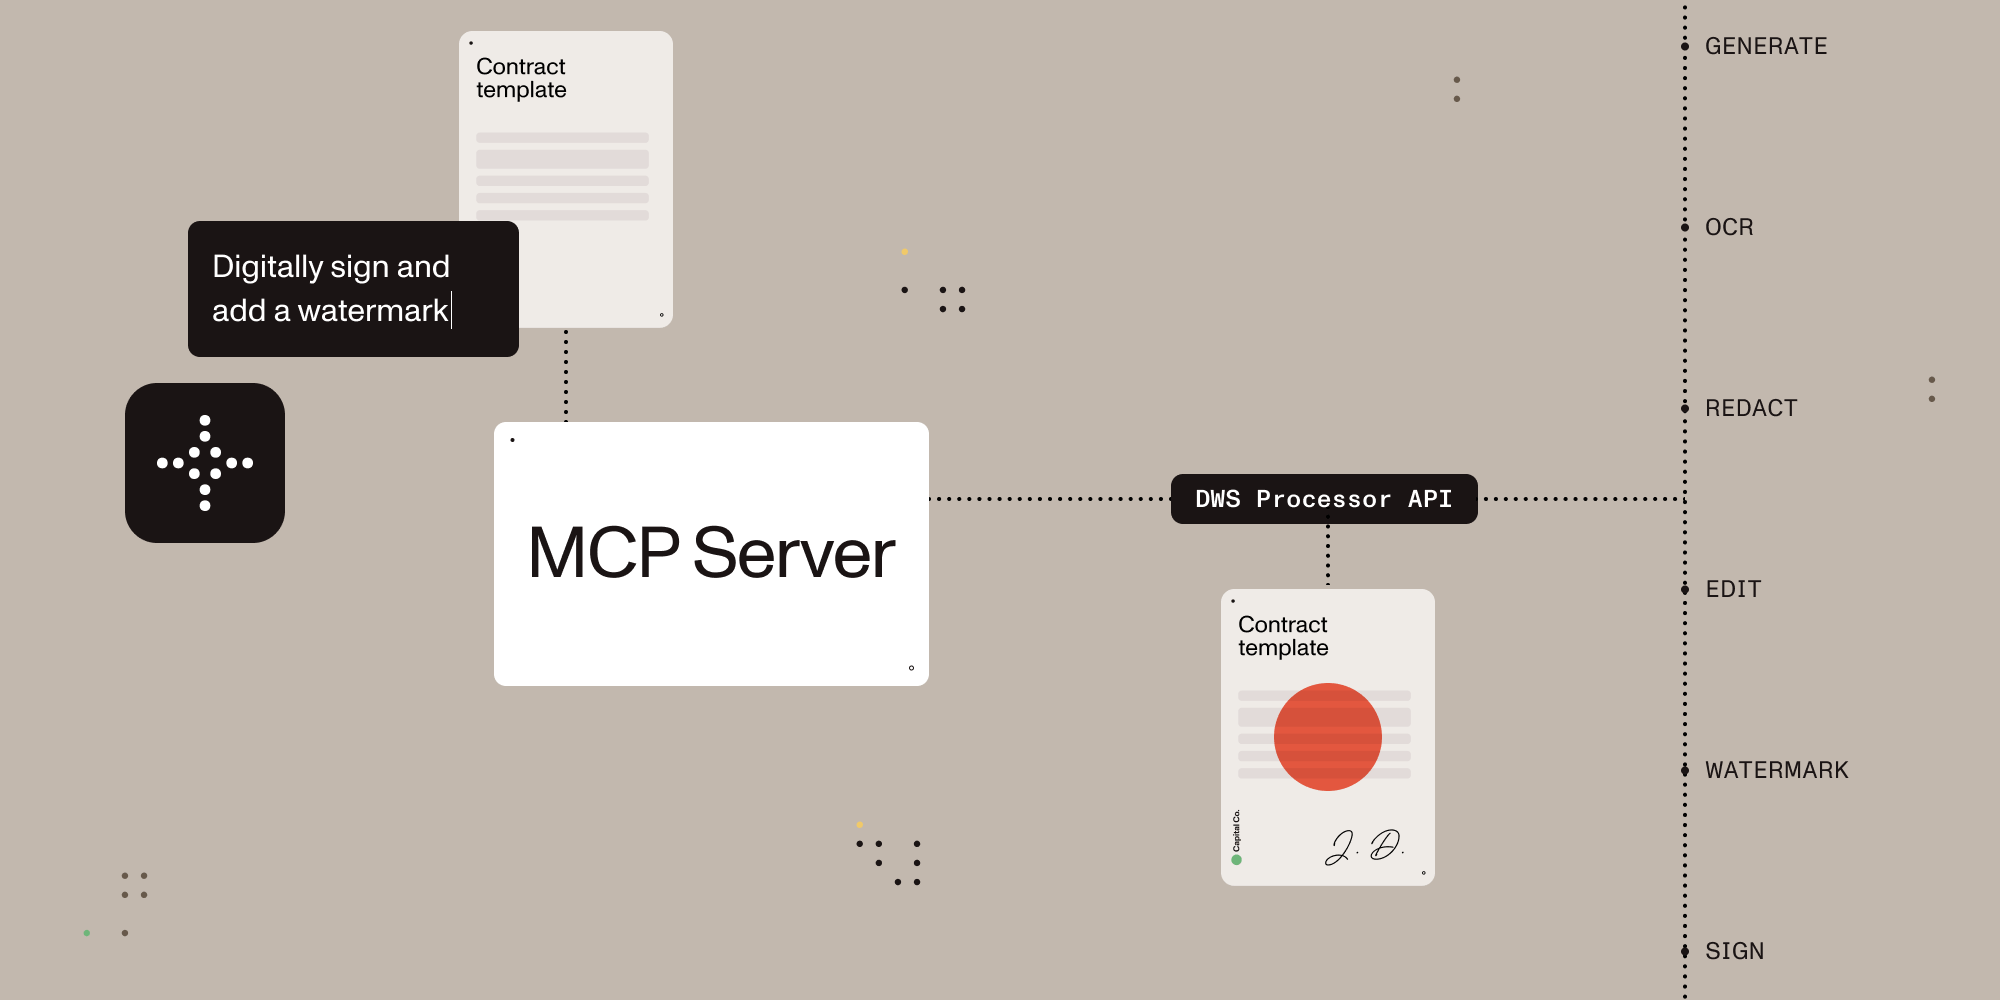
A Model Context Protocol (MCP) server implementation that integrates with the Nutrient Document Web Service (DWS) Processor API, providing powerful PDF processing capabilities for AI assistants.
A powerful Model Context Protocol (MCP) server that provides an all-in-one solution for public web access.
Scrape JavaScript-heavy sites and extract structured data via reusable CSS schemas. Portable agent skill wrapping the Crawl4AI CLI and Python SDK.
Token-efficient MCP server for tabular data retrieval. Index CSV/Excel files, query rows, aggregate — 99%+ token savings vs raw file reads.
Web tasks that compile. Other browser tools tell your AI agent the click worked. chrome-agent reads the page back after every action and answers in JSON what actually happened. One 3 MB Rust binary, no Node, no cloud.
X (Twitter) scraper API & X API alternative with REST, MCP, SDKs & webhooks. Not affiliated with X Corp.
The AI-native technical SEO crawler. Open-source MCP server for Claude / Cursor / Codex — 37 tools, 50+ checks, unlimited pages, WAF detection, ephemeral by design. Built on LibreCrawl. MIT.
Fast, lightweight Firecrawl/Tavily alternative in Rust. Web scraper, crawler & search API with MCP server for AI agents. Drop-in Firecrawl-compatible API (/scrape, /crawl, /search). 2.3x faster than Tavily, 1.5x faster than Firecrawl in 1K-URL benchmarks. 6 MB RAM, single binary. Self-host or use managed cloud.