
koala73/worldmonitorConnectors
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
86k
This server exposes Nutrient DWS as MCP tools for document conversion, OCR, redaction, signing, and data extraction. Your agent sends files through stdio MCP, authenticates with OAuth or an API key, and writes results back to a sandbox path when needed.
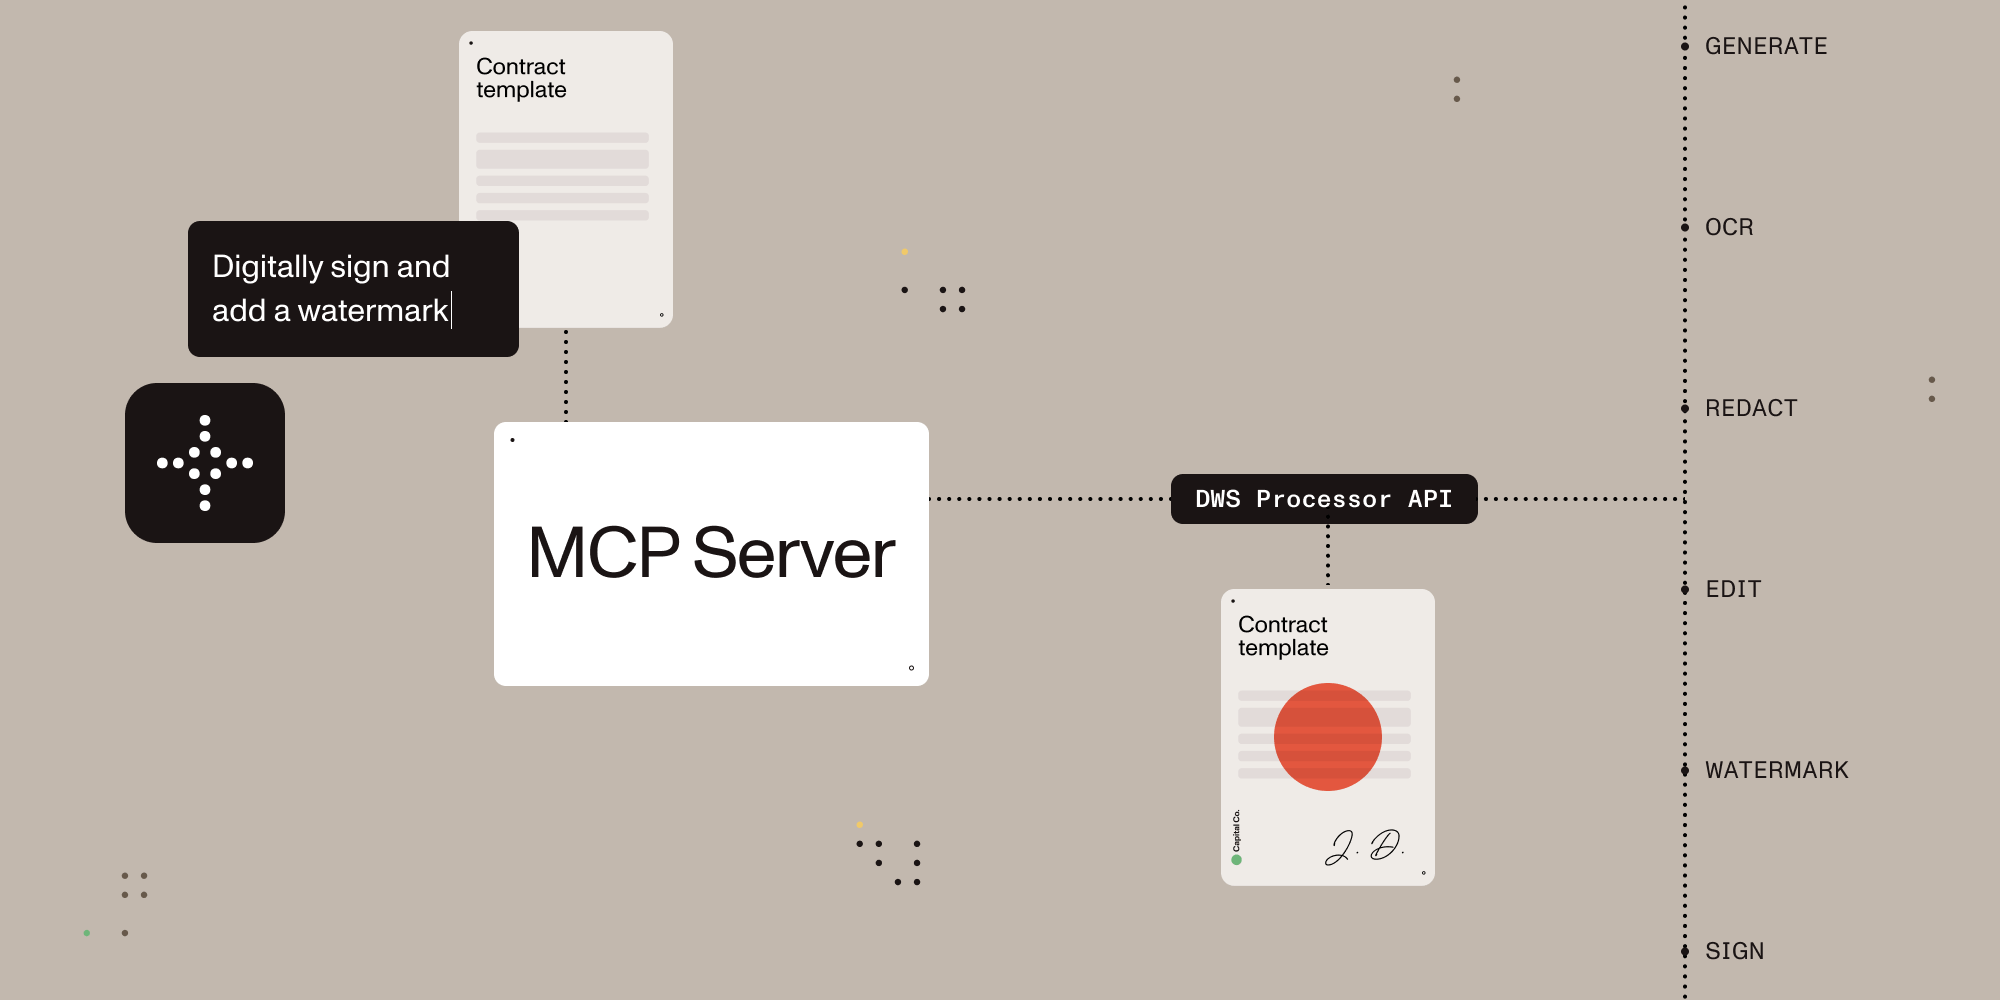
Builders who want Claude Desktop, Cursor, Windsurf, or other MCP clients to process PDFs and office files.
You can turn natural-language requests into document edits, extraction, and signing without leaving your agent.
Runs conversions, OCR, watermarking, rotation, annotation flattening, and redaction through the DWS Processor API.
Parses documents into Markdown or spatial JSON, and extracts schema-shaped fields with citations through the Data Extraction API.
Signs PDFs with CMS / PKCS#7 and CAdES signatures, with visible or invisible signature appearance options.
Uses browser-based OAuth on first use, with static API-key support for CI and headless setups.
Restricts file reads and writes to a configured sandbox directory and returns explicit output paths.
Provides a read-only tool for checking DWS credits and usage without uploading document content.
SANDBOX_PATH=/your/path npx @nutrient-sdk/dws-mcp-server

# Optional for CI or headless usage:
NUTRIENT_DWS_API_KEY=your_key SANDBOX_PATH=/your/path npx @nutrient-sdk/dws-mcp-server

Give AI agents the power to generate, read, extract, process, and sign documents.
A Model Context Protocol (MCP) server that connects AI assistants to the Nutrient Document Web Service (DWS) Processor and Data Extraction APIs — enabling document creation, editing, conversion, digital signing, OCR, and redaction, plus structured data extraction (typed JSON with bounding boxes and confidence, or schema-guided field extraction with per-field citations) through natural language.
text (1 credit/page, no OCR), structure (1.5), understand (9, the default), agentic (18, VLM)Once configured, you (or your AI agent) can process documents through natural language:
You: "Merge report-q1.pdf and report-q2.pdf into a single document" AI: "Done! I've merged both reports into combined-report.pdf (24 pages total)."
You: "Redact all social security numbers and email addresses from application.pdf" AI: "I found and redacted 5 SSNs and 3 email addresses. The redacted version is saved as application-redacted.pdf."
You: "Digitally sign this contract with a visible signature on page 3" AI: "I've applied a PAdES-compliant digital signature to contract.pdf. The signed document is saved as contract-signed.pdf."
You: "Convert this PDF to markdown" AI: "Here's the markdown content extracted from your document..."
You: "OCR this scanned document in German and extract the text" AI: "I've processed the scan with German OCR. Here's the extracted text..."
You: "Pull the vendor, invoice number, total, and due date out of invoice-0341.pdf, with citations" AI: "Here are the four fields as JSON. Each value cites the page and bounding box it came from..."
Install it from Claude Desktop Settings -> Extensions if you are using Claude Desktop. If you are developing locally, use the manual setup below.
The Claude Desktop MCPB extension defaults its sandbox directory to ~/Documents/Nutrient. You can change that directory in the extension settings. Clearing the field starts the server without sandbox restrictions, so file operations can use any path visible to your user account.
Sign up for free at nutrient.io/api.
For local desktop use, the recommended path is to omit NUTRIENT_DWS_API_KEY and complete the browser sign-in flow on the first request that uses the Nutrient API. For CI, headless environments, or scripted setups, create an API key in the dashboard and set NUTRIENT_DWS_API_KEY.
Choose your platform and add the configuration:
Open Settings → Developer → Edit Config, then add:
macOS: ~/Library/Application Support/Claude/claude_desktop_config.json
Windows: %APPDATA%\Claude\claude_desktop_config.json
{
  "mcpServers": {
    "nutrient-dws": {
      "command": "npx",
      "args": ["-y", "@nutrient-sdk/dws-mcp-server"],
      "env": {
        "SANDBOX_PATH": "/your/sandbox/directory",
        // "C:\\your\\sandbox\\directory" for Windows
        // Optional for CI or headless usage:
        // "NUTRIENT_DWS_API_KEY": "YOUR_API_KEY_HERE"
      },
    },
  },
}
Create .cursor/mcp.json in your project root:
{
  "mcpServers": {
    "nutrient-dws": {
      "command": "npx",
      "args": ["-y", "@nutrient-sdk/dws-mcp-server"],
      "env": {
        "SANDBOX_PATH": "/your/project/documents",
        // "C:\\your\\project\\documents" for Windows
        // Optional for CI or headless usage:
        // "NUTRIENT_DWS_API_KEY": "YOUR_API_KEY_HERE"
      },
    },
  },
}
Add to ~/.codeium/windsurf/mcp_config.json:
{
  "mcpServers": {
    "nutrient-dws": {
      "command": "npx",
      "args": ["-y", "@nutrient-sdk/dws-mcp-server"],
      "env": {
        "SANDBOX_PATH": "/your/sandbox/directory",
        // "C:\\your\\sandbox\\directory" for Windows
        // Optional for CI or headless usage:
        // "NUTRIENT_DWS_API_KEY": "YOUR_API_KEY_HERE"
      },
    },
  },
}
Create .vscode/mcp.json in your project, or add the same server definition to your user mcp.json profile:
{
  "servers": {
    "nutrient-dws": {
      "type": "stdio",
      "command": "npx",
      "args": ["-y", "@nutrient-sdk/dws-mcp-server"],
      "env": {
        "SANDBOX_PATH": "${workspaceFolder}",
        // Optional for CI or headless usage:
        // "NUTRIENT_DWS_API_KEY": "YOUR_API_KEY_HERE"
      },
    },
  },
}
Any MCP-compatible client can connect using stdio transport:
SANDBOX_PATH=/your/path npx @nutrient-sdk/dws-mcp-server

# Optional for CI or headless usage:
NUTRIENT_DWS_API_KEY=your_key SANDBOX_PATH=/your/path npx @nutrient-sdk/dws-mcp-server
Restart the application to pick up the new MCP server configuration.
Place documents in your sandbox directory and use explicit file names or paths in prompts. Explicit paths are safer and more reliable than vague file-browsing requests.
| Tool | Description |
|---|---|
document_processor | Document processing for conversions, OCR, watermarking, rotation, annotation flattening, and redaction workflows |
parse_document | Structured data extraction (DWS Data Extraction API): typed JSON elements with bounding boxes and confidence, or whole-document Markdown |
extract_fields | Schema-guided field extraction (DWS Data Extraction API): pulls specific named fields into a JSON shape you define, with per-field citations |
document_signer | PDF signing with CMS / PKCS#7 and CAdES signatures plus visible or invisible appearance options |
ai_redactor | AI redaction for detecting and permanently removing sensitive content such as names, addresses, SSNs, emails, and custom criteria |
check_credits | Read-only account lookup for current DWS credits and usage. No document content is uploaded |
sandbox_file_tree | Read-only view of files inside the configured sandbox directory |
directory_tree | Read-only view of local files when sandbox mode is disabled. Sandbox mode is strongly recommended |
sign_and_watermark — Add a text watermark to a document, then digitally sign the watermarked PDF.extract_document_fields — Extract named fields into a JSON object, optionally retaining citations in a file.redact_pii — Detect and permanently redact personally identifiable information from a document.parse_for_rag — Parse a document as Markdown for retrieval-augmented generation and search indexing.office_to_pdfa — Convert an Office document to an archival PDF/A file.| Feature | Description |
|---|---|
| Document Creation | Merge PDFs, Office docs (DOCX, XLSX, PPTX), and images into a single document |
| Format Conversion | PDF ↔ DOCX, images (PNG, JPEG, WebP), PDF/A, PDF/UA, HTML, Markdown |
| Editing | Watermark (text/image), rotate pages, flatten annotations |
| Security | Redact sensitive data (SSNs, credit cards, emails, etc.), password protection, permission control |
| Data Extraction | Now a dedicated tool — see Data Extraction (parse_document) for typed JSON/Markdown with coordinates and confidence |
| OCR | Multi-language optical character recognition for scanned documents |
| Optimization | Compress and linearize PDFs without quality loss |
| Annotations | Import XFDF annotations, flatten annotations |
| Digital Signing | PAdES-compliant CMS and CAdES digital signatures (via document_signer tool) |
The parse_document and extract_fields tools wrap the DWS Data Extraction API and authenticate as follows:
NUTRIENT_DWS_API_KEY set): the same browser-flow token used by every other tool also covers Data Extraction. No extra configuration is needed.NUTRIENT_DWS_API_KEY cannot be reused. Set NUTRIENT_DWS_EXTRACTION_API_KEY to a Data Extraction key from the dashboard. Without it, parse_document and extract_fields return an error instead of calling the API.parse_document runs one of four processing modes:
| Mode | Output | OCR | Cost per page |
|---|---|---|---|
text | Markdown only | No | 1 credit |
structure | Spatial or Markdown | Yes | 1.5 credits |
understand (default) | Spatial or Markdown | Yes (AI-augmented) | 9 credits |
agentic | Spatial or Markdown | Yes (VLM) | 18 credits |
outputPath and the tool returns a content-free summary (element counts, low-confidence flags, page geometry).outputPath when provided (recommended for large documents) — useful for RAG and search indexing.formats: ["spatial", "markdown"] instead of format to get output.elements and output.markdown in one call. The second format is billed at no extra cost. outputPath is required (as for spatial alone); the summary also reports the markdown byte length.The document can be supplied either as filePath (uploaded from the local file system or sandbox) or url (fetched directly by the API) — provide exactly one.
Additional options:
language — OCR language(s) for structure/understand/agentic modes; left unset, the API auto-detects. maxLanguages / maxScripts cap how many languages/scripts auto-detection considers, and only apply when language is left unset.useHtmlTables (default true), enableSemanticBlockFormatting (default true), includeHeadersAndFooters (default false), extractWordsFromPictures (default false).check_credits.Note: Extracted content returned inline (Markdown output, or
extract_fieldsresults) enters the conversation and may be logged by the host. For sensitive documents, prefer spatial output to a file plus targetedextract_fieldscalls.
extract_fields)Where parse_document parses a whole document into elements or Markdown, extract_fields pulls out only the fields you name. Pass a JSON schema (schema) whose root is type: "object" with properties — the response's output.data matches that shape, e.g. { invoiceNumber, total, lineItems: [...] }.
type, properties, required, items, description, string enum, and format: "date". $ref/$defs and composition/conditional keywords (allOf/anyOf/oneOf/if/then/else) are rejected. Schemas are closed — do not set additionalProperties yourself. Limits: 32 KB serialized, 500 fields, 50 properties per object, 5 nesting levels, enum values capped at 50.mode runs the parse feeding the extraction: structure (1.5 credits/page), understand (default, 9 credits/page), or agentic (18 credits/page) — no text mode, since schema-guided extraction needs the structural parse text mode skips. Total cost per page is that parse component plus a fixed extract component, in Data Extraction credits.output.data is always returned inline, pretty-printed — it is the answer, bounded by your own schema. Alongside it, a citation match summary reports how each field was grounded (id_match, id_match_multiblock, id_match_partial, fuzzy_match, not_found) and lists which field paths came back not_found (capped at 10, then "+N more"). Field paths come from your schema, not the document, so this leaks no document content.outputPath is set — they can be large and add little without the document open alongside them. Without outputPath, a note says they were omitted.includeCitations (server default true), strict (default false), and multimodal (default false, increases cost/latency) are only sent when you set them explicitly.instructions (free text, up to 10000 characters) adds guidance for ambiguous fields. language/maxLanguages/maxScripts tune OCR the same way as parse_document.These examples assume your files live inside the configured sandbox and that you use explicit paths.
User prompt: Convert /path/to/sandbox/invoice.html to PDF and save it as /path/to/sandbox/invoice.pdf. Then digitally sign /path/to/sandbox/invoice.pdf with a visible signature and save it as /path/to/sandbox/invoice-signed.pdf.
What happens: The server uploads the HTML file to Nutrient, saves the generated PDF in the sandbox, then signs that PDF and writes the signed result back to the requested output path.
User prompt: Run OCR on /path/to/sandbox/scanned-contract.pdf, return the extracted text, and save the OCR'd file as /path/to/sandbox/scanned-contract-ocr.pdf.
What happens: The server sends the scanned PDF to Nutrient for OCR, returns the extracted text in Claude, and writes the OCR-processed file back to the sandbox for later use.
User prompt: Check my Nutrient credits, convert /path/to/sandbox/report.docx to PDF, save it as /path/to/sandbox/report.pdf, and then tell me where the output file was written.
What happens: The server first performs a read-only account lookup, then converts the DOCX file to PDF, saves the result in the sandbox, and tells the user exactly where the output file was written.
User prompt: Extract vendor_name, invoice_number, total_amount and due_date from /path/to/sandbox/invoice-0341.pdf and save the citations next to it.
What happens: The agent calls extract_fields with a small JSON schema ({ "type": "object", "properties": { "vendor_name": {"type": "string"}, "invoice_number": {"type": "string"}, "total_amount": {"type": "string"}, "due_date": {"type": "string"} } }) and an outputPath. The server sends the PDF to the Data Extraction API, returns the four values inline as JSON with a citation match summary, and writes the full per-field citations (page, bounding box, confidence) to the output file for auditing.
This MCP server works with any platform that supports the Model Context Protocol:
AI can read and understand documents — but most tools stop there. Nutrient gives AI agents the ability to actually manipulate documents: merge, redact, sign, watermark, convert formats, extract structured data, and more.
The server supports sandbox mode that restricts file operations to a specific directory. Set the SANDBOX_PATH environment variable to enable it:
export SANDBOX_PATH=/path/to/sandbox/directory
npx @nutrient-sdk/dws-mcp-server
Supported CLI flags are --sandbox <dir> and -s <dir>. Unrecognized flags cause a startup error.
When sandbox mode is enabled:
Note: If no sandbox directory is specified, the server operates without file path restrictions. Sandbox mode is strongly recommended for security.
Processed files are saved to a location determined by the AI. To guide output placement, use explicit output paths such as save the result to /path/to/sandbox/output/result.pdf or create an output directory in your sandbox.
The server authenticates to the Nutrient DWS API (https://api.nutrient.io) using one of:
| Method | When | Config |
|---|---|---|
| API key | NUTRIENT_DWS_API_KEY is set | Static key passed as Bearer token to DWS API |
| OAuth browser flow | No API key set | Opens browser for Nutrient OAuth consent on the first request that uses the Nutrient API, caches token locally |
When no API key is configured, the server stays connected and opens a browser-based OAuth flow on the first request that uses the Nutrient API (similar to gh auth login). Tokens are cached at $XDG_CONFIG_HOME/nutrient/credentials.json or ~/.config/nutrient/credentials.json and refreshed automatically.
Data Extraction (parse_document, extract_fields) is a separate product with its own tenant. Under OAuth, one token covers both products — nothing extra to configure. Under a static API key, the Processor key in NUTRIENT_DWS_API_KEY cannot be reused for extraction; set NUTRIENT_DWS_EXTRACTION_API_KEY to a Data Extraction key from the dashboard, or omit NUTRIENT_DWS_API_KEY entirely to use OAuth instead.
Setting only NUTRIENT_DWS_EXTRACTION_API_KEY (with no NUTRIENT_DWS_API_KEY) runs the server in extraction-only mode: parse_document and extract_fields work normally, while the Processor tools (document_processor, document_signer, ai_redactor, check_credits) return an error instead of calling the API.
| Variable | Required | Description |
|---|---|---|
NUTRIENT_DWS_API_KEY | No* | Nutrient DWS API key (get one free) |
NUTRIENT_DWS_EXTRACTION_API_KEY | Only with a static key† | Data Extraction API key from the dashboard (starts with pdf_live_), needed for parse_document / extract_fields |
SANDBOX_PATH | Recommended | Directory to restrict file operations to |
AUTH_SERVER_URL | No | OAuth server base URL (default: https://api.nutrient.io) |
CLIENT_ID | No | OAuth client ID. Skips DCR and enables refresh token reuse when set |
DWS_API_BASE_URL | No | DWS A |
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface

Git-native persistent memory for AI coding agents. Implements Google OKF v0.2 with sub-300µs in-memory BM25 search, embedded MCP server, and progressive disclosure. Slashes token bloat by 80% with zero external databases or dependencies. Built in pure Go.

Stop your AI from making things up — it proposes, deterministic tools decide, every claim checked against ground truth with evidence. Grounded facts and context survive resets. Reverse engineering is the proving ground. MCP server + CLI.
20 MB lightweight cross-platform database client for 90+ databases, including MySQL, PostgreSQL, SQLite, Redis, MongoDB, DuckDB, SQL Server, and Dameng. Built-in AI, MCP Server, CLI, desktop and Docker. | 轻量级跨平台数据库管理工具,支持 MySQL、PostgreSQL、SQLite、Redis、MongoDB、达梦等 90+ 数据库,提供桌面端、Docker、CLI、内置 AI 助手和 MCP Server。
x64dbg-MCP Server is a native MCP (Model Context Protocol) plugin for x64dbg that exposes the debugger's full functionality over HTTP. Connect any MCP-compatible AI assistant and control x64dbg programmatically: set breakpoints, step through code, read memory, dump registers, and more. Built with Zig — zero dependencies, single-binary output, cros
The fastest browser for AI agents to run browser automation, built for sharing your logged-in browser state with your AI agents, like Codex or Claude Code, without disturbing you. Zero cost, zero config.