
SuperLocalMemory V4.1.14
Rent the LLM. Own the memory.
Rent an LLM — but own the memory, for your company and for your industry.
The governed memory layer for AI agents: local-first, auditable, and built for the compliance obligations teams now actually carry.
Models are interchangeable and rented by the token. What your agents remember is
yours — it is your customers' data, your retention obligations, and your audit trail. SLM
keeps that layer on infrastructure you control, with multi-workspace isolation, role-based
access, and GDPR + EU AI Act governance controls built in.
The boundary. SuperLocalMemory starts with a local runtime;
provider-backed enrichment, cloud backup, connectors, and proxy use are explicit choices.
Different products solve different boundaries. Published benchmark evidence carried into V4
comes from the published V3 research architecture; it is not a claim of a newly rerun V4 package benchmark.
How to check that, rather than believe it. Every reliability
guarantee here is stated as a falsifiable invariant, tested under an adversarial condition with a
negative control, and shipped with the harness that regenerates the evidence:
python benchmark/run_all.py --trials 200 --output-dir results/. What each experiment
does not exercise is stated too.
v4.1.14 — one control plane: SLM-Mesh peer coordination · multi-scope memory (personal / shared / global) · profiles · Cache · Compress · 7-layer retrieval · code graph · Entity Explorer · skill evolution · Modes A/B/C · GDPR retention & audit chain · bounded loops — across CLI, MCP, dashboard, the Claude plugin, the Codex add-on, and documented IDE integrations.
Proxy: slm wrap claude · MCP: add slm_compress to your config · Skill: zero-config
Four public arXiv preprints · V4: arXiv:2608.08253 · companion archive: Zenodo 21853302 (DOI 10.5281/zenodo.21853302) · prior preprints: 2603.02240 · 2603.14588 · 2604.04514.






Why SuperLocalMemory?
SuperLocalMemory is an enterprise-grade, local-first memory control plane for AI agents. Your team's agent memory lives on infrastructure you control, with per-workspace isolation, role-based access, and GDPR / EU AI Act governance controls — built for organizations, and for EU data-residency obligations where agent context must not leave your environment by default.
Agent-memory systems make different storage, model-provider, and deployment trade-offs. SuperLocalMemory starts with a local runtime and makes provider-backed enrichment, cloud backup, connectors, and proxy use explicit choices.
Different products solve different boundaries. The published LoCoMo benchmark evidence in this README is protocol-scoped evidence from the published V3 research architecture; it is carried forward for continuity and is not a claim of a newly rerun V4 package benchmark.
SuperLocalMemory V4 combines conventional dense and lexical retrieval with graph, temporal, associative, and statistical relevance scoring in a 7-layer control plane (admission → queryable core → enrichment → brain → multi-channel retrieval → context safety → operations). The default local runtime does not require Docker, a separately operated graph database, or an API key.
Memory with a sense of time. SLM does not only store what an agent learned — it records when. Every fact carries ingestion timing and provenance; recall runs a dedicated temporal candidate channel alongside semantic, lexical, and associative retrieval; scenes and entity timelines reconstruct sequence; and the lifecycle lets neglected memory decay and self-archive instead of growing without bound. Time is a first-class ranking and lifecycle signal rather than a timestamp column an agent never reads — which is what lets a long-lived agent reason about how its context changed, not only what it currently holds.
What changed in this release. See the CHANGELOG — every release is written up there, in plain language, newest first.
- SLM-Mesh — authenticated cross-session and cross-machine peer coordination (messages, locks, shared state, inbox/outbox, optional discovery). Coordination only — not automatic replicated memory.
- Multi-scope memory & profiles — workspaces (profiles) plus
personal / shared / global scopes; cross-profile recall is default-deny.
- Cache & compression (context optimization) — exact-match cache with tagged invalidation, safe compression, and opt-in reversible/aggressive paths across proxy, MCP, and skill surfaces.
- Entity Explorer & skill evolution — compiled entity summaries/timelines; opt-in skill lineage, budgets, and verification outcomes.
- Modes A / B / C — local-only (A), on-device LLM enrichment (B), provider-assisted (C). An operating mode records technical locality facts; it does not determine EU AI Act legal compliance (that is deployment-context assessment — see Privacy controls).
- GDPR posture, retention & audit chain — export, fail-closed cross-store erasure, retention policies, and a hash-chained audit trail. Engineering controls for compliance programs, not a legal certification.
- 7-layer retrieval/recall stack & code graph — multi-channel candidates (semantic, BM25, temporal, Hopfield, spreading activation) plus optional code-graph tools for blast radius and review context.
- MCP profiles —
code exposes 31 tools for installed coding agents; full 49; power 61; whole 94 (all registered). Also core (16), mesh (8), and the unrestricted default surface (49 with mesh enabled).
- Governed write path & verifiable transactions — admission + policy control, a per-owner obligation ledger, and a hash-sealed completion manifest with a reconciler that redrives unmet obligations.
- Self-healing lifecycle & admin remediation — stale locks cleared on restart; list/resolve stuck operations from CLI, MCP, or the dashboard.
SLM is one strand of Qualixar's work on AI reliability engineering: making agent behavior observable, bounded, and reproducible instead of best-effort.
The architecture evaluated in the V3 paper remains the foundation of this release. The figures below keep their original LoCoMo protocol, answer-construction, model, and sample scope.
How SLM fits beside other memory systems
Different products solve different boundaries. SLM is for developers who want
one local-first operating control plane—not only an SDK, managed context API,
or agent runtime. It combines dated evidence, graph-aware retrieval, cache and
compression controls, SLM-Mesh, and MCP/CLI/hooks/dashboard/IDE
surfaces in one install.
| If your primary need is… | Product boundary to evaluate |
|---|
| Local-first agent memory plus operations, optimization, and IDE-agent surfaces | SuperLocalMemory — Mode A local core; Modes B/C by explicit choice. |
| A memory SDK, self-hosted server, or managed platform | Mem0 |
| A temporal context-graph service or graph engine | Zep / Graphiti |
| A stateful agent runtime with memory blocks and archival memory | Letta |
| LangGraph-native memory primitives and managers | LangMem |
| A context API/app with profiles, connectors, and RAG | Supermemory |
| User profiles and event-timeline memory | Memobase |
See the source-linked market comparison
for current primary sources and protocol-scoped benchmark evidence. A LoCoMo
percentage is comparable only when the dataset scope, answer model, judge,
retrieval stack, and release artifact match.
The V4 capability architecture
SuperLocalMemory is one local control plane for persistent agent context. It is
not just a vector store: the same runtime can accept evidence, build and govern
memory, retrieve bounded evidence for an agent, and expose cache, compression,
and SLM-Mesh peer-coordination controls through a CLI, MCP, dashboard, and supported
IDE integrations.
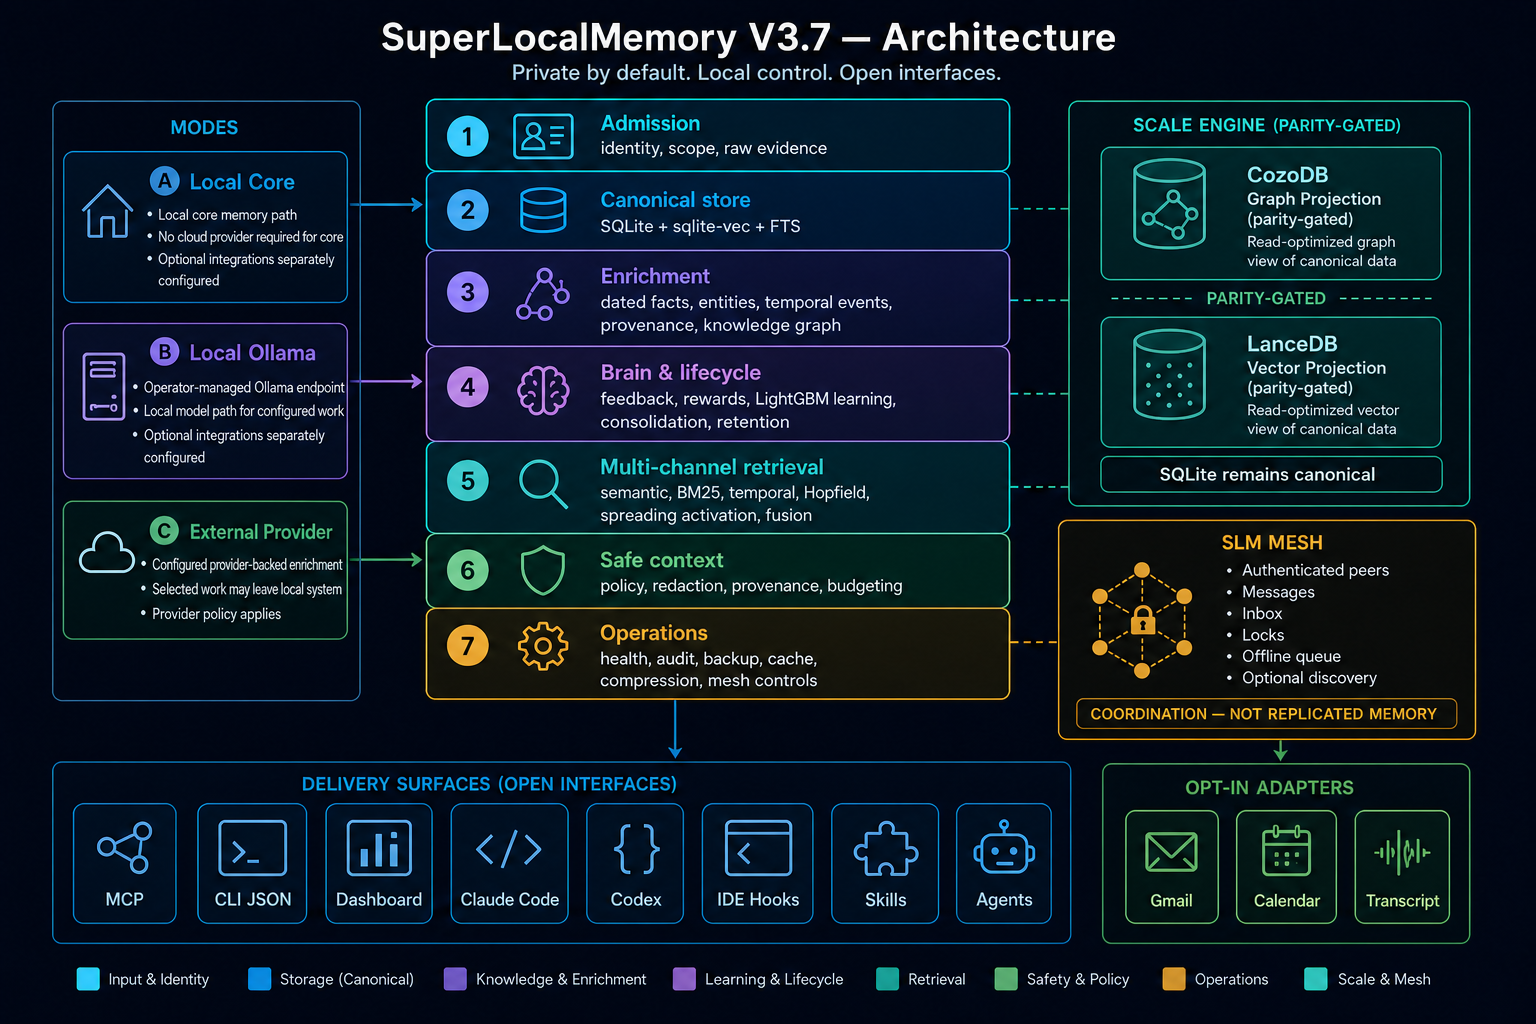
Architecture boundary: SQLite + sqlite-vec remain canonical; CozoDB and
LanceDB are parity-gated projections; SLM-Mesh coordinates trusted peers rather
than replicating a distributed memory database; connectors are opt-in.
Memory boundaries: profiles isolate workspaces by default. Every memory is
personal, shared with named profile readers, or global; cross-profile
recall is default-deny and must be explicitly enabled. This scoped sharing is
local authorization, not SLM-Mesh synchronization. See
shared-memory.md.
IDEs, agents, scripts, connectors, and humans
│ CLI · MCP (HTTP/stdio) · hooks · dashboard
▼
┌────────────────────────── SLM CONTROL PLANE ──────────────────────────┐
│ 1. Admission identity, scope, idempotency, raw evidence │
│ 2. Queryable core SQLite facts + FTS durable receipt │
│ 3. Enrichment facts, entities, scenes, time, provenance, graph │
│ 4. Memory brain feedback, patterns, rewards, consolidation │
│ 5. Retrieval semantic · BM25 · temporal · Hopfield · activation │
│ 6. Context safety policy, trust, provenance, redaction, budgets │
│ 7. Operations lifecycle, audit, cache/compress, mesh, backups │
└───────────────────────────────────────────────────────────────────────┘
│
▼
SQLite + sqlite-vec canonical store ──► optional graph/vector projections
The seven stages are an execution model, not a promise that every optional
enricher or retrieval channel runs for every request. The receipt, trace, and
health surfaces expose the stages actually completed by the installed runtime.
| Capability | What ships today | Operator boundary |
|---|
| Memory types and lifecycle | Atomic facts, episodic scenes, temporal events, canonical entities, profiles/scopes, consolidation, forgetting and retention controls | Lifecycle policies and retention decisions remain operator-configured. |
| Memory boundaries | Profile-isolated workspaces plus personal, shared, and global memory scopes | Personal is the default; shared/global recall requires explicit scope policy or per-call opt-in. |
| Ingestion | Durable raw-to-complete operation state, fact extraction, entity resolution, graph/temporal/provenance derivations, and replay-safe identity | --sync waits for declared stages; dependencies and mode determine which enrichers are available. |
| Retrieval and recall | Semantic, lexical, temporal, Hopfield and spreading-activation candidate channels; RRF fusion, optional reranking and graph score enhancement | Healthy channels participate; response provenance states the evidence used. |
| Brain and learning | Behavioral patterns, feedback/outcome records, rewards, consolidation, LightGBM-related ranking components, soft prompts, and guarded skill-evolution workflows | Learning is evidence-driven; it does not claim autonomous correctness or guaranteed improvement. |
| Knowledge graph and entities | Canonical entities, aliases, entity profiles, graph edges, scenes, timelines, explorer and graph APIs | Stored/derived graph data is evidence, not an instruction authority. |
| Scale Engine | SQLite + sqlite-vec are canonical. CozoDB graph and LanceDB vector projections are managed with prepare → verify → promote → rollback; a structurally detected pre-v3.7 projection can be explicitly adopted. | Promotion is parity-gated and crash-recoverable. Legacy adoption preserves the prior projection as a rollback backup; repeated physical edge rows normalize to one logical edge with the strongest weight. |
| Optimize | Exact cache, tagged invalidation, safe compression, opt-in aggressive prose compression, CCR originals, proxy/MCP/skill surfaces | Only proxy intercepts a primary provider turn. MCP/skill cache results explicitly routed through SLM. |
| SLM-Mesh | Authenticated peer messages, inbox/outbox, locks, offline queue, optional discovery and mesh MCP tools | SLM-Mesh is coordination, not automatic replicated memory or conflict resolution. |
| Governance and operations | Provenance, audit/retention/policy surfaces, export/erasure controls, diagnostics, health, backups and daemon lifecycle | These are engineering controls, not a legal certification. |
| Integrations | CLI, Python SDK, MCP HTTP/stdio, Claude plugin, Codex add-on, supported IDE configurations, Gmail/Calendar/transcript adapters | Hooks, IDE edits, connectors, and networked adapters require explicit operator activation. |
What the dashboard exposes
slm dashboard opens a local operational view of the same control plane:
| Workspace | Use it to inspect or control |
|---|
| Dashboard and Health | daemon identity, storage/runtime health, diagnostics and recent activity |
| Brain | consolidation, behavioral patterns, outcomes/rewards, learning state and soft prompts |
| Knowledge Graph and Memories | graph neighborhoods, entities, scenes, temporal evidence, memory inspection and mutation |
| Operations | ingestion-operation state, traces, maintenance and lifecycle work |
| Entity Explorer and Skill Evolution | compiled entity summaries/timelines; opt-in skill lineage, budgets and verification outcomes |
| Multi-Agent Memory | per-agent write activity and attribution; memories stamped by SLM_AGENT_ID, agent write counts, and trust signals |
| SLM-Mesh Peers | configured peers, inbox/outbox, pending coordination and locks |
| Settings and Optimize | mode/provider/configuration; cache, compression and savings telemetry |
Dashboard visibility is not a substitute for runtime proof: use slm doctor,
slm health, slm trace, and the relevant CLI/MCP operation to validate a
deployment.
Watch the product walkthrough
Watch the SuperLocalMemory demo on YouTube — a five-minute walkthrough of installation, setup, recall, cache, and compression. The video shows a product walkthrough; use the commands and release notes in this README as the current release contract.
Published LoCoMo evidence (V3 architecture, carried into V4)
The V3 paper evaluates the multi-channel architecture that V4 still runs. Every figure below
is protocol-scoped, so a reader can distinguish local retrieval, answer
construction, and cloud-assisted evaluation rather than treating unlike runs as
one score.
| Published configuration | LoCoMo aggregate | Protocol scope | What the result establishes |
|---|
| Mode A Raw | 60.4% | 10 conversations; 1,276 scored questions; local embeddings, local retrieval, and zero-LLM answer construction | End-to-end local answer construction under the published V3 protocol. |
| Mode A Retrieval | 74.8% | 10 conversations; 1,276 scored questions; local retrieval, then GPT-4.1-mini answer synthesis | Retrieval evidence: local retrieval contributes the evidence, while the disclosed external model constructs the final answer. |
| Mode C | 87.7% | Conv-30 only; 81 scored questions; text-embedding-3-large plus GPT-4.1-mini answer generation and judge | Cloud-assisted configuration on one fully disclosed conversation; not a full-dataset result. |
Published category results: Mode A Retrieval scored 72.0% single-hop,
70.3% multi-hop, 80.0% temporal, and 85.0% open-domain. Mode C
scored 64.0% single-hop, 100.0% multi-hop, and 86.0% open-domain
on its 81-question Conv-30 scope (no temporal category was reported for that
run). Across six LoCoMo conversations, the paper reports 71.7% with the
information-geometric layers versus 58.9% without them: +12.7pp.
See arXiv:2603.14588 and the official
LoCoMo paper for the full protocol,
ablation table, and limitations. These are published V3 architecture results
carried into V4—not a substitute for a newly rerun release-artifact benchmark.
Quick Start
# Primary path 1 — npm global CLI (Node 18+)
# Creates a package-owned virtual environment. It does not modify system Python.
npm install -g superlocalmemory
slm setup       # Choose mode (A/B/C)
slm doctor      # Verify everything is working
# Primary path 2 — Python CLI + SDK in an activated virtual environment
python3 -m venv .venv
source .venv/bin/activate  # Windows PowerShell: .venv\Scripts\Activate.ps1
python -m pip install superlocalmemory
slm setup
slm doctor
# First use
slm remember "Alice works at Google as a Staff Engineer" --json
slm recall "What does Alice do?"
slm status
The default daemon write commits raw evidence plus a relational/FTS projection
and returns a durable receipt in queryable state. Enrichment then advances the
same operation through enriching to complete, or records a retryable
failed state. Use slm remember "..." --sync when the caller must wait for
all declared derivation and projector stages. JSON output includes the opaque
operation_id, current materialization_state, and fact IDs.
# Wrap your agent — starts proxy + sets environment + launches agent
slm wrap claude
# Your first repeat prompt → CACHE HIT → $0.00
# See savings: slm optimize savings --since 1
Upgrading: use the owner of the installation: npm update -g superlocalmemory
or, while the Python virtual environment is active,
python -m pip install --upgrade superlocalmemory. Then run
slm restart && slm doctor. Repository-clone users use the matching upgrade
action in scripts/install.sh or scripts/install.ps1. Installers never move
or delete memory data.
Three Pillars
Memory
Current recall has five candidate producers—dense semantic, BM25 lexical,
temporal, Hopfield associative, and spreading activation—followed by fusion,
optional reranking, and entity-graph score enhancement. The entity graph does
not create an independent candidate in the current implementation. Core memory
is SQLite-backed. SQLite and sqlite-vec remain the canonical source of truth.
The packaged Scale Engine can maintain CozoDB graph and LanceDB vector
projections, and it remains outside active retrieval paths until a staged
parity witness proves it matches the canonical store. New installations remain
on Local Core. During upgrade, slm db scale status can identify a positive
pre-v3.7 layout candidate; the operator confirms it with slm db scale adopt.
SLM then rebuilds from canonical SQLite, verifies it, and promotes it with a
durable recovery journal while retaining the prior directories as a rollback
backup. adopt reports restart_required: true; run slm restart before
checking daemon health. If proof fails, recall remains on SQLite and status
retains the rejected manifest for inspection, retires its replaceable derived
payload, and allows a corrected retry.
Canonical ingestion is a durable state machine: raw → queryable → enriching → complete, with failed retaining raw evidence, error details, attempt count,
and retry timing. SQLite relational facts and FTS are the queryable checkpoint;
optional ANN/vector projectors are verified before complete is granted.
Recalled text is treated as untrusted evidence. Hooks, MCP session_init, CLI
session context, and chat use one bounded renderer that redacts recognized
secrets, neutralizes forged boundary markers, and attaches provenance. Trusted
IDE instruction files contain only the static SLM protocol; fresh memory is
retrieved at runtime rather than copied into those files.
Score Contract v2: relevance_score is query-relative relevance;
ranking_score is internal ranking utility; memory_confidence belongs to the
stored assertion; and trust_score is an evidence-p




