
koala73/worldmonitorConnectors
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
86k
pdf-mcp gives an agent a set of PDF tools instead of a single dump of text. The server handles hybrid search, selective page reads, OCR, tables, images, charts, and corpus-wide search across a folder of PDFs.
Builders who want their agent to search, read, and compare PDFs without stuffing whole documents into context.
You can answer questions from large or scanned PDFs by retrieving only the relevant pages and excerpts.
Searches by both semantic meaning and keyword matching, then returns excerpts with source coordinates.
Reads specific pages or ranges on demand, instead of loading an entire PDF at once.
Warms, triages, and searches a whole folder of PDFs with provenance back to each document and page.
Extracts text from scanned PDFs and handles multi-column, vertical Japanese, and other complex layouts.
Pulls out structured tables, embedded images, and chart data from plot geometry.
Keeps a SQLite cache across restarts and can serve the same tools over STDIO or HTTP.
pip install pdf-mcp
brew install tesseract        # macOS
apt install tesseract-ocr     # Ubuntu/Debian
winget install Tesseract-OCR  # Windows
claude mcp add pdf-mcp -- pdf-mcp


Agentic RAG over your PDFs, one file or a whole folder, as a single MCP tool.
The agent decides when to search; pdf-mcp does the retrieval and hands back excerpts. It is an MCP server that lets Claude Code and other AI agents search one PDF or a whole folder by meaning or keyword, read only the pages that matter, and cleanly pull out tables, images, and scanned text, even from multi-column and Japanese layouts, with optional CUDA acceleration for warming large corpora.
mcp-name: io.github.jztan/pdf-mcp
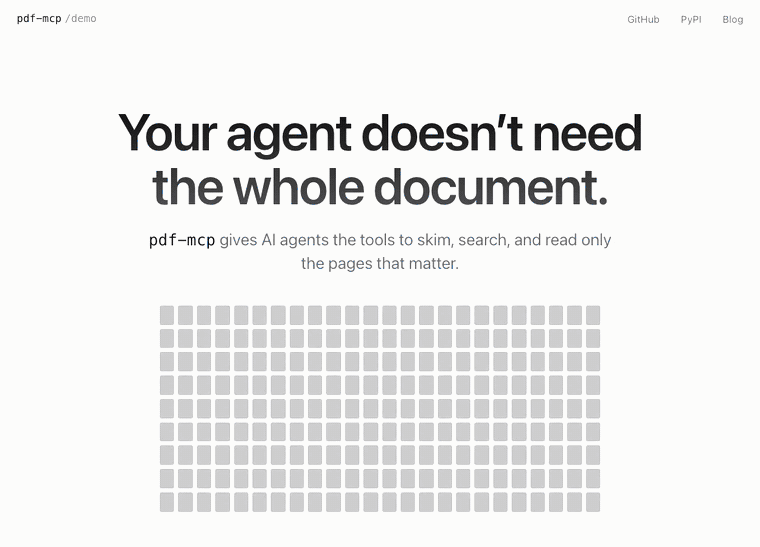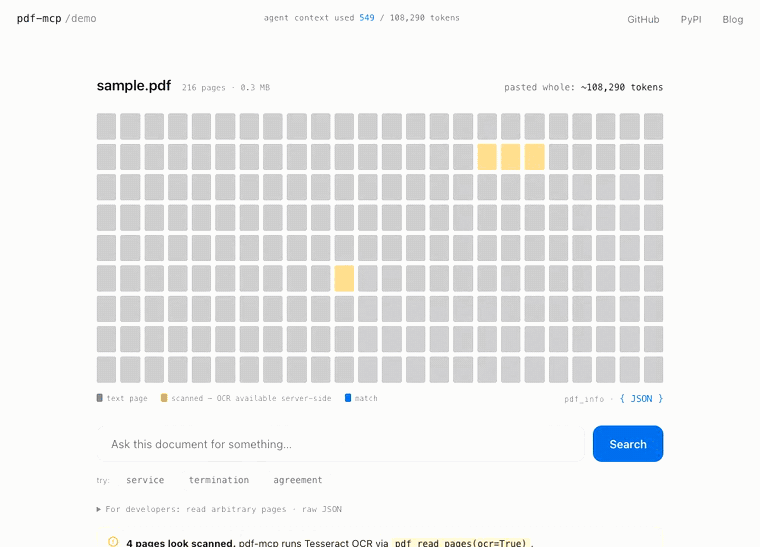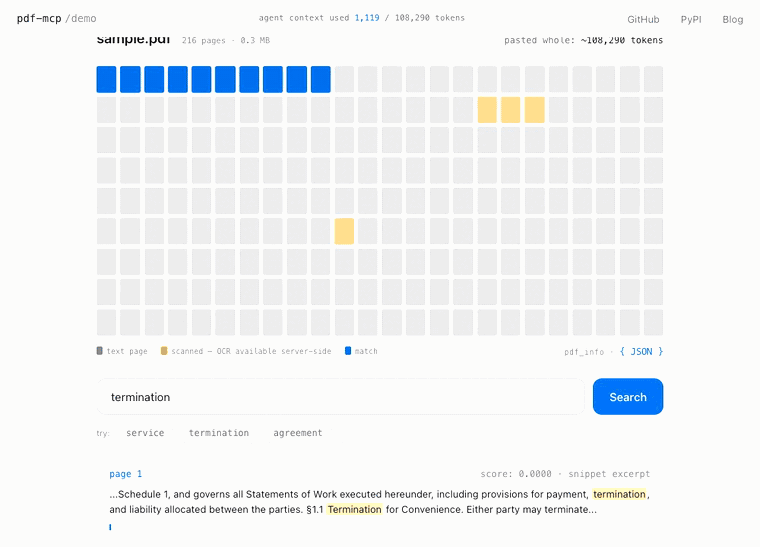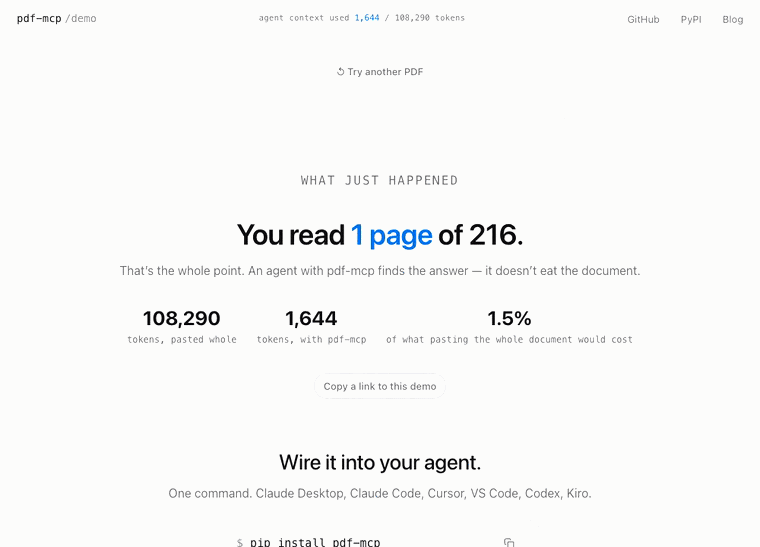
Drop in any PDF, or a whole folder of them, and watch an agent triage the corpus, search across every document at once, and read only the pages that matter, using a fraction of the tokens. 100% client-side, no install required.
| Without pdf-mcp | With pdf-mcp | |
|---|---|---|
| Large PDFs | Context overflow | Read only the pages you need |
| Finding content | Load everything | Hybrid search: BM25 keyword + semantic |
| Folders of PDFs | One document at a time | Warm, triage, and search a whole folder |
| Warming a big folder | Minutes of CPU embedding | Length-sorted small-batch CPU encode; optional CUDA embedding, one to two orders of magnitude faster on an NVIDIA card |
| Tables and charts | Lost in raw text | Structured rows, and (x, y) data from vector charts |
| Multi-column and vertical layouts | Columns interleaved | Correct reading order, including Japanese tategaki |
| Scanned PDFs | No text at all | OCR via Tesseract, parallel across pages |
| Repeated access | Re-parse every time | SQLite cache that survives restarts |
| Hidden or injected text | Silently ingested | Flagged as untrusted, nothing stripped |
pip install pdf-mcp
That is the whole install: hybrid search, corpus tools, multi-column and CJK reading order all work out of the box.
OCR on scanned PDFs additionally needs system Tesseract:
brew install tesseract        # macOS
apt install tesseract-ocr     # Ubuntu/Debian
winget install Tesseract-OCR  # Windows
GPU embedding is optional and off by default. On an NVIDIA card it makes the
embedding pass one to two orders of magnitude faster; set PDF_MCP_CUDA=1
after installing the CUDA build of onnxruntime. Setup per CUDA series is in
docs/configuration.md.
claude mcp add pdf-mcp -- pdf-mcp
Then ask Claude to read a PDF. For Claude Desktop, VS Code, Codex CLI, Kiro, or any other MCP client, see docs/clients.md.
pdf-mcp's tools are also plain Python functions, so you can import them and hand a PDF to the Anthropic SDK without running a server. Two runnable scripts, for a question and for a whole document: examples/.
Why this exists, and what broke along the way: Claude's 100-page PDF limit and how I got around it
13 specialized tools rather than one monolithic one. Typical pattern:
pdf_info to plan, pdf_search to locate (its paragraph excerpts often
answer the question outright), pdf_read_pages when you need more. For a
folder, pdf_corpus_overview to triage, then pdf_corpus_search.
| Tool | What it does |
|---|---|
pdf_info | Page count, metadata, TOC summary, scanned-page detection. Call first. |
pdf_search | Hybrid search (keyword + semantic), page or section granularity, paragraph or context-window excerpts with source coordinates |
pdf_read_pages | Read specific pages or ranges, with OCR on demand, tables, and embedded images |
pdf_read_all | Read a whole document in one call, byte-capped |
pdf_get_toc | Full table of contents for documents with many bookmarks |
pdf_render_pages | Render pages as PNG for vision models: diagrams, handwriting, scans |
pdf_extract_chart | Chart data as exact (x, y) tables, read from plot geometry |
pdf_corpus_warm | Warm a folder of PDFs into the cache within a time budget |
pdf_corpus_overview | Per-document triage cards for a folder |
pdf_corpus_search | Search across a folder, with document and page provenance; excerpt_style="auto" picks the excerpt unit per query |
pdf_cache_stats | Per-document cache breakdown and total size |
pdf_cache_clear | Clear expired or all cache entries |
server_info | Which optional features and config are active |
Text returned by any of these is untrusted content extracted from a PDF.
pdf_info(content_trust=True) reports hidden text a human reader cannot
see, and the read tools flag it per page.
Example prompts:
"Read the PDF at /path/to/document.pdf"
"Which pages discuss supply chain risks?"
"Find sections about the training process"
"Show me what page 5 looks like"
"OCR pages 3-5 of the scanned PDF"
Full reference, every parameter and response shape: docs/tool-reference.md. Embedding model selection: docs/embedding-models.md.
For a large document (e.g., a 200-page annual report):
User: "Summarize the risk factors in this annual report"

Agent workflow:
1. pdf_info("report.pdf")
   → 200 pages, TOC shows "Risk Factors" on page 89

2. pdf_search("report.pdf", "risk factors")
   → Matches with structural paragraph excerpts: each excerpt
     is the bullet, paragraph, or heading that matched, not a
     fixed-width window. Often enough to answer directly.

3. If excerpts are sufficient → synthesize answer

4. If more context needed:
   pdf_read_pages("report.pdf", "89-95")
   → Full page text for deeper reading
STDIO is the default and is what every example above uses. pdf-mcp-http
serves the same tools over HTTP, for clients that cannot spawn a process
(the Anthropic API MCP connector, claude.ai custom connectors) and for a
warm corpus shared by several clients.
export PDF_MCP_AUTH_TOKEN="$(openssl rand -hex 32)"
pdf-mcp-http
Paths resolve on the server, so an HTTP agent reads what is already there:
files under an allow-listed root, or a URL the server fetches. It cannot
hand over a file from its own machine. It is single-tenant and fails
closed: with no auth token and no [paths] allow list, the process exits
rather than serving an open endpoint.
Docker images are published to GHCR for amd64 and arm64, with everything baked in, so every tool works on the first request:
./deploy.sh              # token, image, start, health-check
cp your.pdf documents/   # this folder is the server's /data/pdfs
Read docs/remote-access.md for the trust boundary and threat model before deploying, and docs/configuration.md for setup, client config, and token rotation.
pdf-mcp works out of the box. To restrict which paths and URL hosts the server may touch, tune cache and worker settings, or add your own content-trust phrases, see docs/configuration.md.
See ROADMAP.md for planned features and release history.
Contributions are welcome. See docs/contributing.md for setup, checks, the coherence eval harness, and quality-loop guidelines.
Thank you to everyone who has helped improve this project through code, reviews, testing, and feature requests:
@Summer907 · @ebbsanchez · @VooDisss · @DerDennisOP · @deepdmk · @TheSOV
Per-release contributor credits are listed in the Changelog.
Found a vulnerability? See SECURITY.md for the threat model, reporting channel, and expected response timeline. Please do not open a public GitHub issue for unpatched security reports.
MIT. See LICENSE.
The story behind the releases. Building pdf-mcp keeps surprising me: benchmarks that go the wrong way, formats that break everything, features I had to remove. I write about that thinking in The Dispatch. Come along if that's your kind of thing.
Background, benchmarks, and design notes from building pdf-mcp:
Getting started
Corpus & multi-document search
Search & retrieval
Engineering & security
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
High-performance code intelligence MCP server. Indexes codebases into a persistent knowledge graph — average repo in milliseconds. 158 languages, sub-ms queries, 99% fewer tokens. Single static binary, zero dependencies.

Universal provider proxy for OpenAI Codex & Claude Code — use any LLM (Claude, Gemini, Grok, DeepSeek, Ollama…) with Codex CLI, App, SDK, and Claude Code

Git-native persistent memory for AI coding agents. Implements Google OKF v0.2 with sub-300µs in-memory BM25 search, embedded MCP server, and progressive disclosure. Slashes token bloat by 80% with zero external databases or dependencies. Built in pure Go.

Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters, with benchmarked context reductions on reviews and large-repo workflows.

Stop your AI from making things up — it proposes, deterministic tools decide, every claim checked against ground truth with evidence. Grounded facts and context survive resets. Reverse engineering is the proving ground. MCP server + CLI.