shinpr/
mcp-image

shinpr/mcp-imageConnectors
MCP server for AI image generation and editing with automatic prompt optimization and quality presets. Supports Nano Banana (Gemini), OpenAI GPT Image, and BytePlus Seedream.
161
MCP server for AI image generation and editing with automatic prompt optimization and quality presets. Supports Nano Banana (Gemini), OpenAI GPT Image, and BytePlus Seedream.

Self-hosted MCP server for your documentation

An MCP server that provides LLMs access to other LLMs

Shell and coding agent on mcp clients

Trello integration for Claude Desktop via Model Context Protocol (MCP) - 19 tools for comprehensive board, card, and list management
A third-party Perplexity MCP/REST API implementation that leverages Pro account Pool to provide unlimited quota for ask and deep search capabilities.

An MCP server that integrates with gpt-image-1 & Gemini imagen4 model for text-to-image generation services
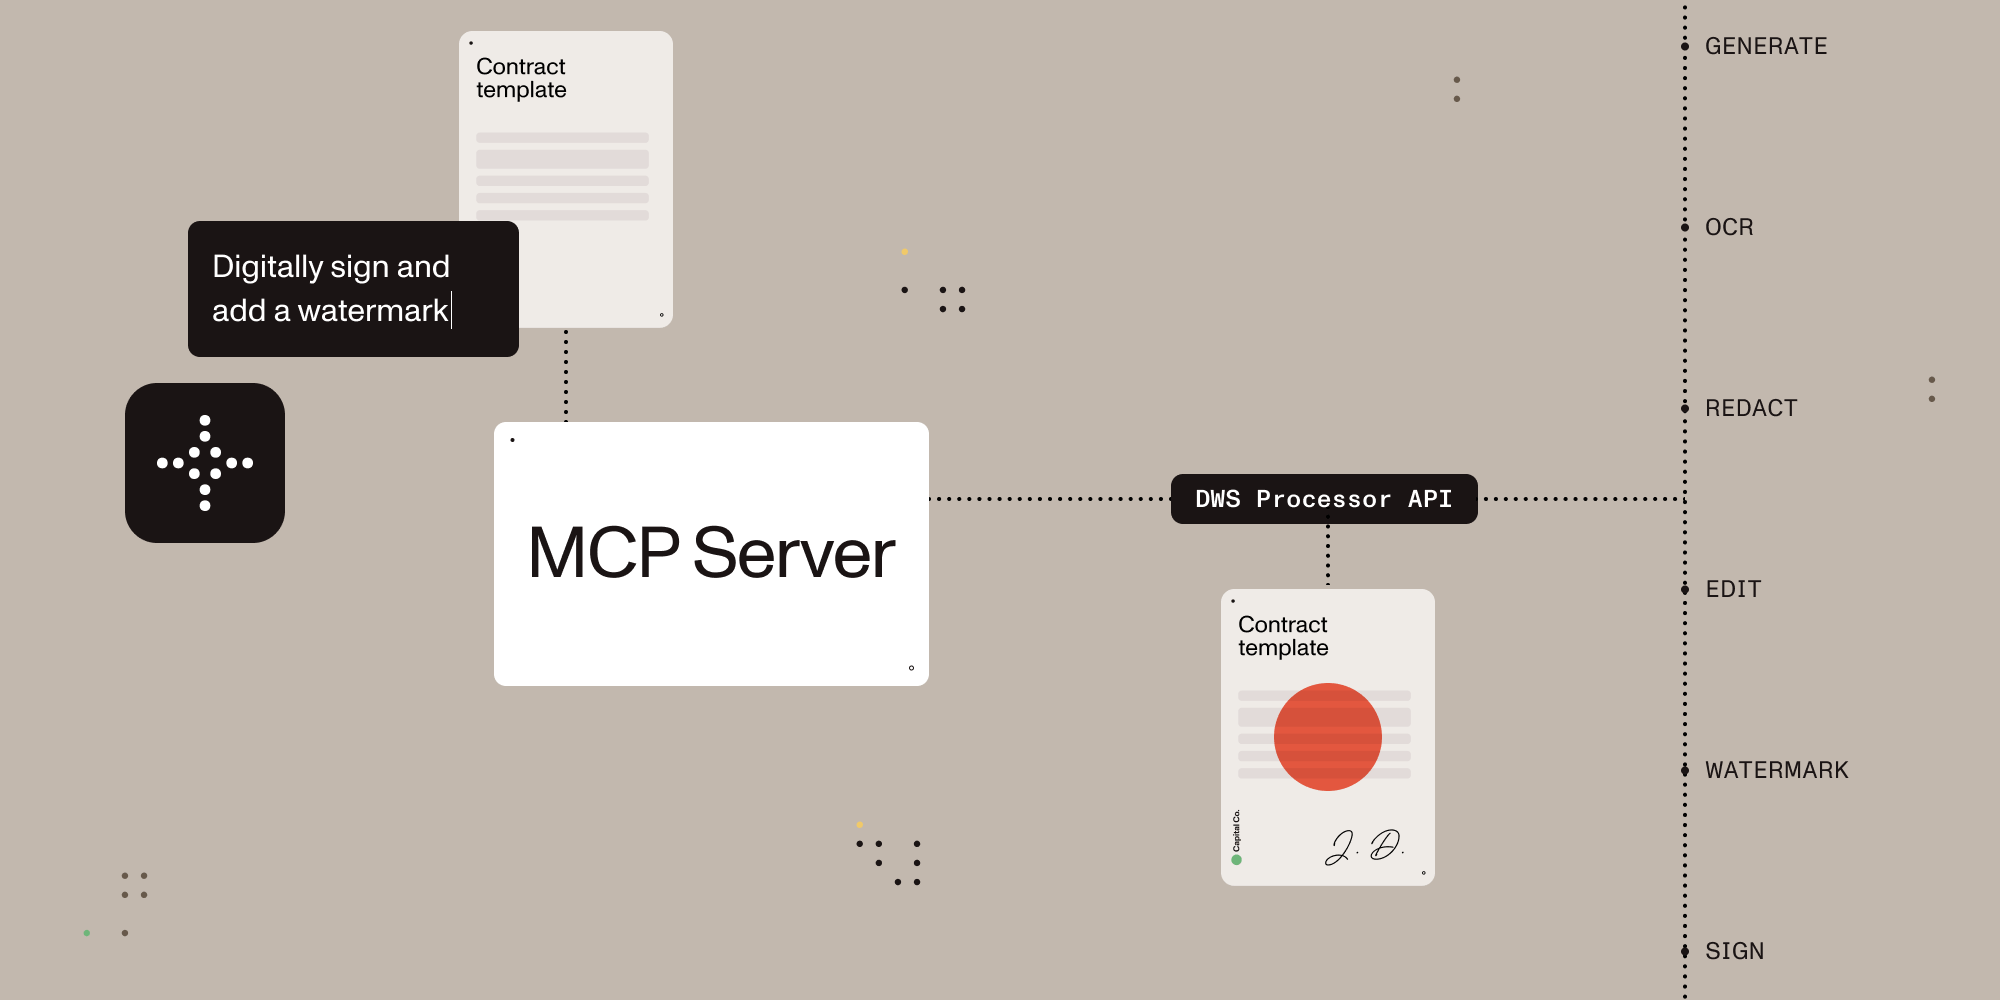
A Model Context Protocol (MCP) server implementation that integrates with the Nutrient Document Web Service (DWS) Processor API, providing powerful PDF processing capabilities for AI assistants.

Open-source memory and context for user-aware agents: scoped memory, provenance, retrieval quality, correction, boundaries, evals, and MCP/HTTP access.

Caura (formerly MemClaw) — governed shared memory for AI agent fleets. Multi-agent, multi-tenant, MCP-native. Trust tiers, keystone policies, audit trails, knowledge graph, self-improving retrieval. Apache 2.0.

CLI server for Zotero 7/8/9 — let AI manage your library. 70+ CLI commands for search, import, PDF, BibTeX, notes, and more. Works with Claude, Cursor, ChatGPT.
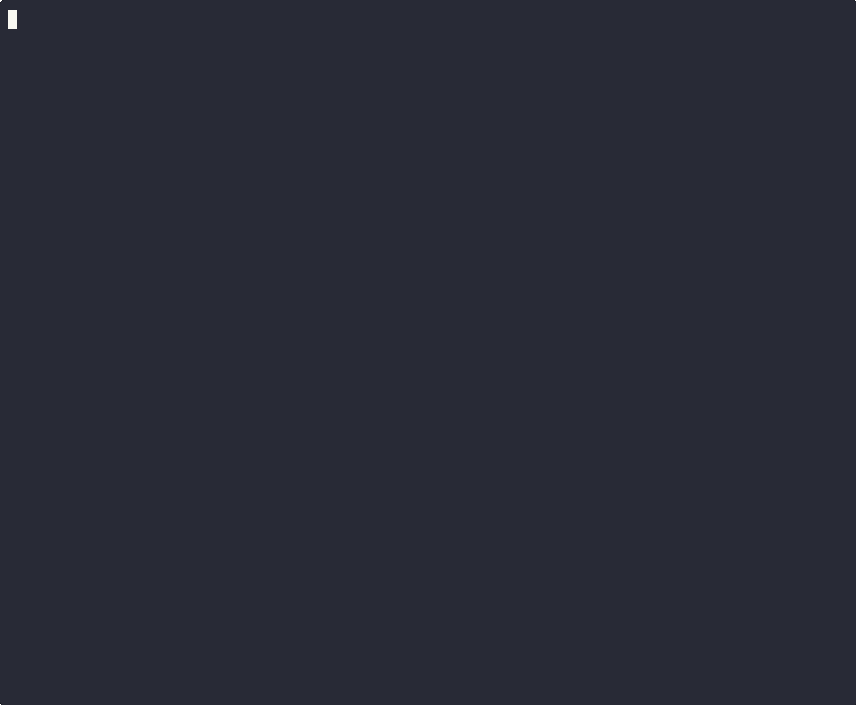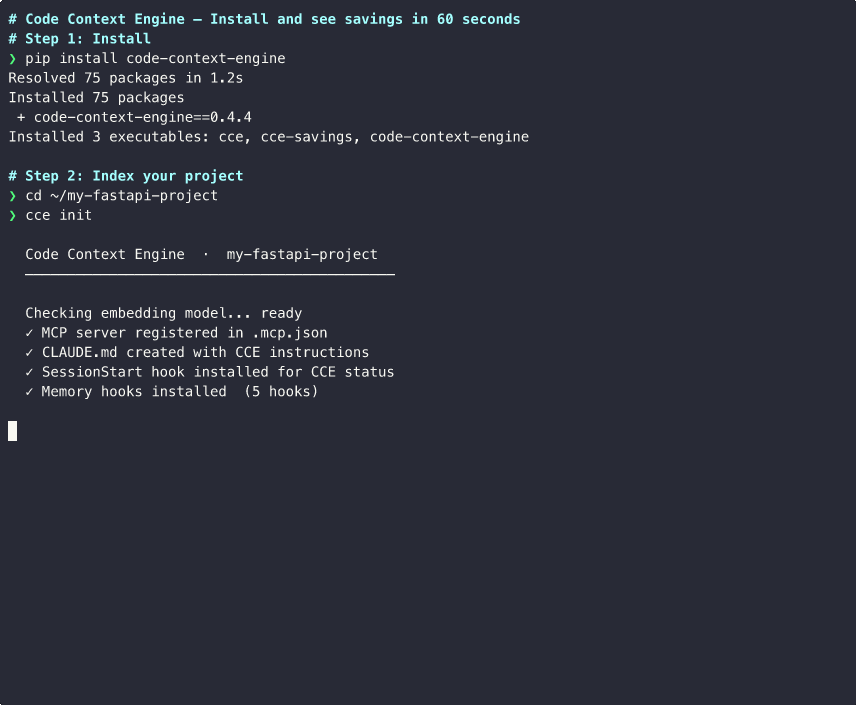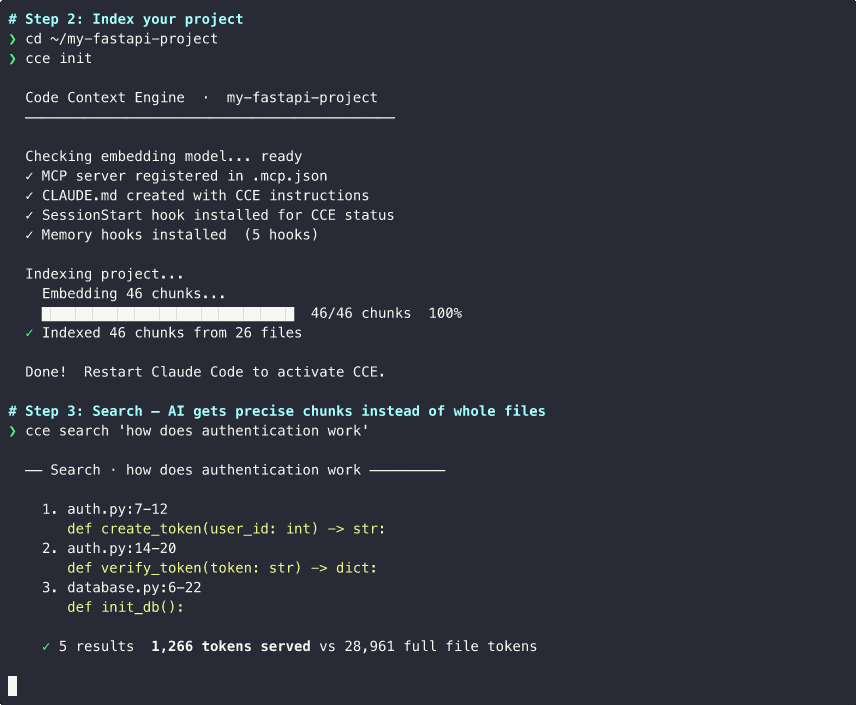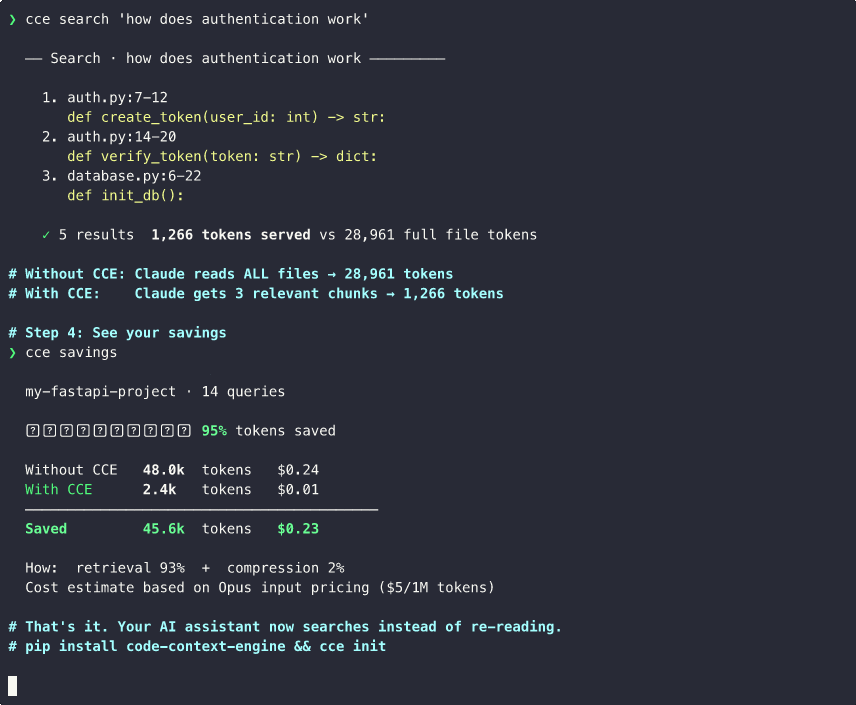
Save 94% on AI coding tokens. Index your codebase, agents search instead of reading files. Works with Claude Code, Codex, Copilot, Cursor, Gemini CLI. Local MCP server, free, open source.

Own your LLM's web search: a local search->fetch->rank pipeline that replaces hosted web-search tools. Measured: matches hosted accuracy at 66% lower cost and up to 88% fewer tokens, plus a precision-tuned semantic caching with query-dependant TTL that no API offers.