



koala73/worldmonitorConnectors
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
86k
GoldenMatch matches messy records into stable entities, then keeps the identity layer durable with field provenance, survivorship, merge/split, and audit history. The same engine is exposed through Python, TypeScript, SQL in Postgres and DuckDB, and an MCP server so agents can call it directly.
Builders who want their agent to resolve duplicate records and maintain a Customer 360 identity layer.
You can feed messy customer data into one system and get stable golden entities back with provenance and history.
Profiles incoming data and deduplicates records without manual rules or training data.
Assigns stable entity IDs and keeps merge, split, survivorship, and audit history.
Returns a unified record with per-field provenance, source records, timeline, and relationships.
Exposes the same capabilities through an MCP server and REST API for agent use.
Provides Python, TypeScript, and SQL surfaces with conformance-tested shared behavior.
Includes benchmarked Arrow-native and Rust-backed matching paths for large datasets.
pip install goldenmatch && goldenmatch dedupe customers.csv
pip install golden-suite
golden-suite doctor        # verify every package + native kernel is importable and healthy
golden-suite optimize      # repair / re-enable the perf-optimized config

pip install golden-suite[mcp]     # + aggregator MCP server (every tool, one endpoint)
pip install golden-suite[all]     # everything
Your customer data lives in a CRM, a billing system, and three spreadsheets nobody owns. Some records are duplicates. Some are the same company spelled four different ways. Nobody can answer how many customers do we actually have, and every dashboard built on top inherits the doubt.
Splink-beating entity resolution, Arrow-native and Rust-fast with zero tuning, feeding a durable identity layer so messy records from every source become stable golden entities with whole-record, Customer-360 provenance.
Zero-config matching that beats expert-tuned Splink head-to-head on messy customer records, in an Arrow-native, Rust-authoritative engine verified from a laptop CSV to a 250M-row dedupe in 11.2 minutes. The identities it produces live in a transaction-native control plane carrying stable entity_ids, per-field provenance, merge/split, and a tamper-evident audit log, all one call away as a Customer 360. It even owns its primitives: byte-identical, faster-than-rapidfuzz / jellyfish / FAISS Rust kernels, not rented dependencies.
Python · TypeScript · SQL, at 4-decimal parity · native in Postgres + DuckDB · edge WASM · 70+ MCP tools · beats hand-tuned Splink · 250M rows in 11.2 min








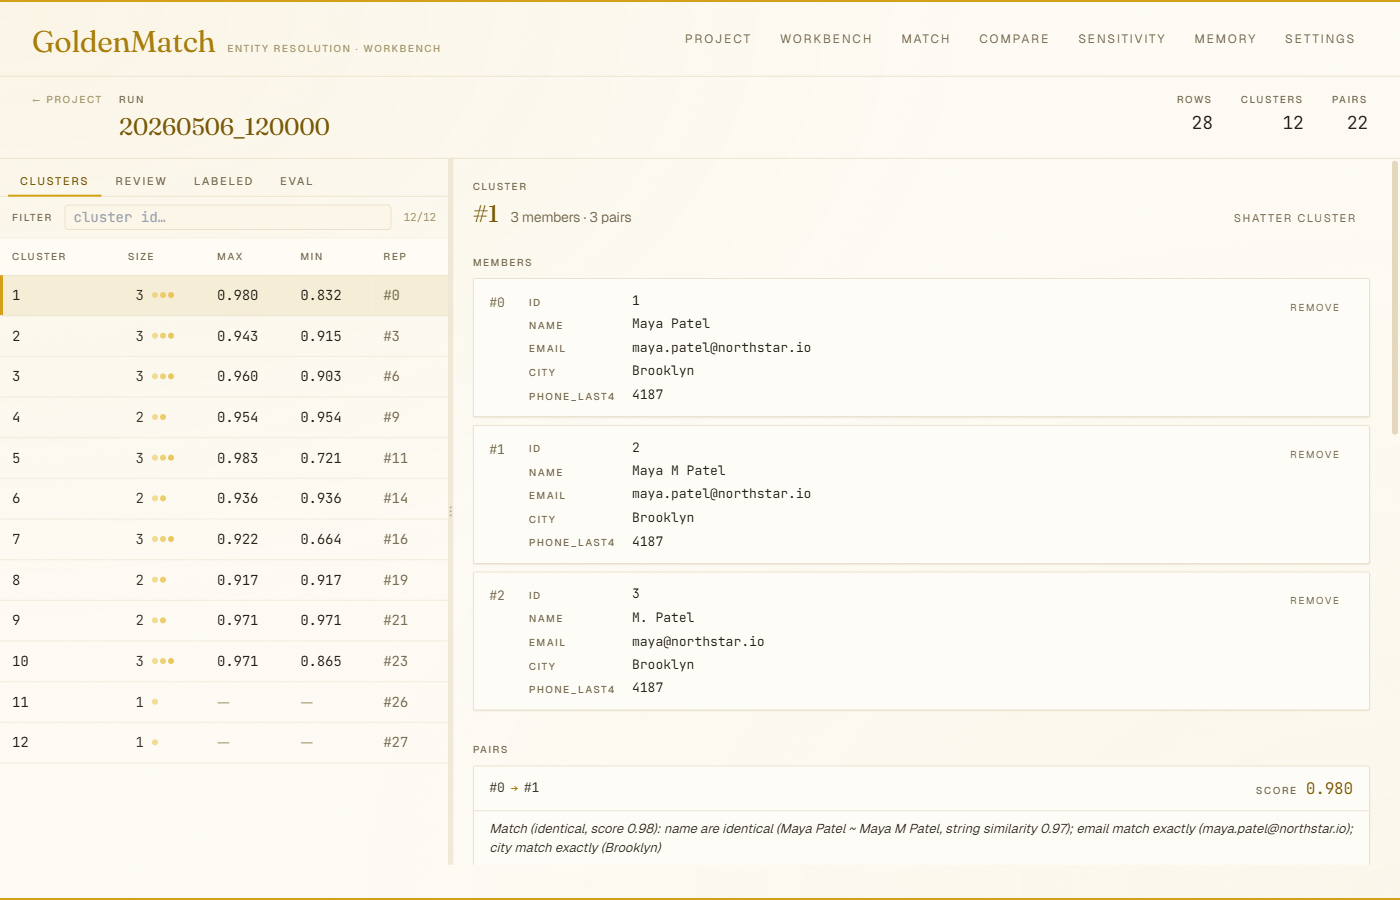
Pair drilldown in the web workbench: cluster members, field-level diff, and a one-line NL explanation per pair. pip install goldenmatch[web] then goldenmatch serve-ui <project>. More screenshots →
v3.17.1: The polars-free first run actually works now. 3.17.0 claimed this and did not deliver it: auto-config puts negative evidence on the exact matchkey by default, and that path still bridged to polars, so
goldenmatch dedupe customers.csvexited 3 on a default install. Verified the way it should have been the first time --pip installinto a clean polars-free venv, then the documented command.v3.17.0: The documented first run works on a default install.
pip install goldenmatchfollowed bygoldenmatch dedupe customers.csv-- the quickstart on every doc surface -- exited 3 on a polars-free install, which is what a plain install has produced since polars became an optional extra. Three separate polars imports on the zero-config path (auto-config ingest, the Arrow lane's preflight decline, and the csv writer) are gone, with polars' exact csv bytes reproduced and parity-pinned.v3.13.0: Fellegi-Sunter training runs distributed on Spark. The E-step reads only the comparison vector, so identical vectors collapse to one counted row and the whole step becomes a Spark
GROUP BYover agreement patterns -- the cluster counts, the driver only fits. Training cost tracks DISTINCT vectors (bounded byprod(levels + 1)), not pairs: 1M -> 5M rows grew candidate pairs 5.00x and the distributed counting stage 5.25x, while distinct patterns grew 3.0% (433 -> 446) and driver-side EM stayed at 0.01s. Runs on jar-only executors viagoldenmatch-spark, off the same Rust kernel every other surface uses.
Most entity-resolution tools hand you clusters and stop. GoldenMatch keeps going: it resolves messy records into a durable golden entity, one per real-world customer, that survives re-runs, carries provenance on every field, and answers "who is this, and where did each value come from?" in a single call.
entity_id (UUIDv7) that persists across runs as new data arrives. Records are absorbed, entities merge or split, but the id an entity earns is the id downstream systems can rely on. Run-local cluster numbers reshuffle on every run; these don't.customer_360(entity_id) composes it into one read: golden record, per-field provenance, every linked source record, the event timeline, and the entity's relationship neighborhood:
// customer_360("018f...c2a1")  (trimmed)
{
  "entity_id": "018f2b7e-...-c2a1", "confidence": 0.97, "record_count": 3,
  "sources": ["salesforce", "billing", "support"],
  "golden_record": { "name": "Ada Lovelace", "email": "ada@analytical.io", "phone": "+1-555-0100" },
  "field_provenance": [
    { "field": "email", "value": "ada@analytical.io",
      "winning_source": "billing", "winning_record_id": "billing:8821",
      "conflicting_values": [ { "value": "ada@ada.dev", "source": "salesforce" } ] },
    { "field": "phone", "value": "+1-555-0100", "winning_source": "salesforce" }
  ],
  "timeline": [ { "kind": "created", "actor": "pipeline", "recorded_at": "2026-07-30T..." },
                { "kind": "absorbed_record", "reason": "matched billing:8821" } ],
  "relationships": [ { "other_entity_id": "018f...9d0e", "kind": "shares_address" } ]
}
What ships today vs. what's emerging. The identity spine is production-grade and in
main: stableentity_ids, per-field provenance, survivorship, merge/split, the append-only log + audit chain, cross-channel stitching, the relationship overlay, and incremental resolution against a persisted index (a new record resolves without a full re-run). Thecustomer_360()serving view above and the source-registry layer that keeps it fresh from live systems are the newer, actively-landing pieces. The source connectors (Snowflake, BigQuery, Salesforce, HubSpot) ship today; the registry that wires them into the spine is emerging. See the Customer 360 design + ADR. We label the seam rather than blur it.
The golden entity lives in the control plane; the matching that builds it runs in the compute engine. That split is the next section.
The golden entity above is produced by two engines that optimize for genuinely different things, and keeping them distinct is the architecture, not an implementation detail (ADR 0047).
flowchart LR
    src([source records])
    e360([golden entities · Customer 360])
    subgraph compute ["Identity Compute Engine: Arrow-native, Rust-authoritative"]
        match[block · score · cluster]
    end
    subgraph control ["Identity Control Plane: transaction-native state machine"]
        spine[stable ids · survivorship · merge/split · provenance · audit]
    end
    src --> compute -->|resolution batch + evidence| control --> e360
    control -.->|persisted index| compute
| Identity Compute Engine | Identity Control Plane | |
|---|---|---|
| Shape | Arrow at bulk boundaries, Rust-authoritative kernels | Transaction-native state machine (SQLite default · Postgres) |
| Job | Block, score, cluster: throughput, vectorized, deterministic per run | Stable ids, survivorship, merge/split, provenance, append-only audit |
| State | Stateless per call; measurement-driven kernelization | Durable, transactional, replayable, auditable |
| Backends | DataFusion · Ray · Sail · Spark are replaceable execution backends, none synonymous with GoldenMatch | Storage backends conform to one externally-observable semantics |
Many surfaces, one answer. The same capabilities reach Python, edge-safe TypeScript (with an opt-in WASM backend running the same Rust kernels), SQL inside PostgreSQL and DuckDB, and MCP / REST / A2A, all governed by specification + conformance, not copy-paste. There is one authoritative owner per capability; pure-Python / standalone-TS paths are classified, conformance-tested fallbacks. Where a boundary can't cross byte-for-byte, we measure and label it rather than claim parity.
Why a platform engineer should care:
The identity layer is only as good as the matching underneath it, and the matching starts at zero config. dedupe_df(df) runs with no rules and no training data: it profiles the data, picks a defensible configuration, and returns golden records immediately. The config it chose comes back on result.config: inspectable, diffable, versionable. Never a black box.
historical_50k pairwise F1 0.827 vs 0.757, cluster B³ 0.862 vs 0.788, one shared evaluator, reproducible bake-off. Fuzzy, exact, probabilistic (Fellegi-Sunter), and LLM scorers, with EM-trained weights and calibrated scores.result.suggestions. Each is kept only if it doesn't worsen a health proxy, so a suggestion never makes results worse. dedupe_df(df, heal=True) applies and re-runs in one call. You close the gap to expert-tuned without being the expert.Runs on unstructured input, too: extract records from PDFs and images, then resolve them like any other source (
pip install goldenmatch[documents]).
The engine and the identity layer reach your stack through the surface you already use, with the same capabilities governed by conformance (one product, two engines) rather than re-implemented thinly per surface.
evaluate · Fellegi-Sunter scoring · GoldenFlow transforms. Resolve without moving data out of the warehouse.node:*-free (browsers, Cloudflare Workers, Vercel Edge, Deno); an opt-in WebAssembly backend (await enableWasm()) swaps in the same pyo3-free Rust kernels the Python wheels and SQL UDFs use, with pure-TS as the byte-identical default.spark.addArtifact("goldenmatch-spark.jar")) and are called over JNI, so executors need no goldenmatch virtualenv, no packed env, nothing installed. Fellegi-Sunter training runs distributed on that path -- the E-step is a Spark GROUP BY over agreement patterns, so the cluster does the counting and the driver only fits the model. Deployment story, not a throughput one: the JVM scoring path measured ~2.4x slower than the Python-worker path, and the reason to use it is that there is nothing to install.Surface parity is not the same as handing any pipeline phase from one language to the other byte-for-byte. Each verdict below is measured by a conformance harness, not assumed:
| Boundary | Verdict |
|---|---|
| Identity graph DB | ✅ byte-safe + cryptographically cross-verifiable (a seal written by one toolkit validates under the other) |
score → cluster and the end-to-end split-run | ✅ byte-safe, reproduces the single-language run |
Cluster JSON · config YAML · Learning Memory · record_fingerprint | ✅ portable |
| String scoring | 🟡 4-decimal tolerance; a pair on a threshold can flip (byte-identical only with the shared WASM scorer) |
| Standardize / dates · embeddings · auto-config controller | 🟠 divergent, not byte-portable |
| Distributed / Ray · document (VLM) ingest | ⛔ Python-only by architecture |
Rule of thumb: hand off at the cluster or identity boundary and it's seamless; don't split across standardize/dates, embeddings, or the controller and expect bit-exact reproduction. Full detail + the runnable harness that keeps these verdicts honest: Cross-language parity & phase-handoff limits.
GoldenMatch is the headline, but resolution is only as good as what feeds it. Five sibling tools clean, standardize, and map records before they reach the identity layer. Each stands alone, but they compose into one pipeline, orchestrated declaratively by GoldenPipe:
flowchart LR
    raw([raw rows])
    golden([golden entities])
    subgraph orchestration ["GoldenPipe orchestrates"]
        direction LR
        infermap[InferMap] --> goldencheck[GoldenCheck] --> goldenflow[GoldenFlow] --> goldenmatch[GoldenMatch]
    end
    raw --> infermap
    goldenmatch --> golden
| Package | Lang | Role in the pipeline | Install |
|---|---|---|---|
| InferMap | Python · TS | Schema mapping: auto-aligns columns across heterogeneous sources | pip install infermap · npm i infermap |
| GoldenCheck | Python · TS | Data-quality scanning: encoding, format validation, anomaly detection | pip install goldencheck · npm i goldencheck |
| GoldenFlow | Python · TS | Transforms & standardizers: phone, date, address, categorical | pip install goldenflow · npm i goldenflow |
| GoldenMatch | Python · TS | Zero-config entity resolution → the identity spine. Headline package. | pip install goldenmatch · npm i goldenmatch |
| GoldenAnalysis | Python · TS | Analysis & reporting: any stage's artifacts → a unified AnalysisReport + cross-run regression detection | pip install goldenanalysis · npm i goldenanalysis |
| GoldenPipe | Python · TS | Orchestrator: declarative YAML wiring the steps | pip install goldenpipe · npm i goldenpipe |
| golden-suite | Python | One-line meta-install: the whole suite + native acceleration | pip install golden-suite |
The deepest docs live in packages/python/goldenmatch/README.md (~1,300 lines: full feature list, CLI, architecture, benchmarks).
Not pipeline stages — the pieces the stages agree through, and the single front door an agent points at.
| Package | What it is | Install |
|---|---|---|
| goldencheck-types | Shared canonical field-type registry: one source of truth for what a field type means, across every package and both languages | pip install goldencheck-types · npm i goldencheck-types |
| goldensuite-mcp | One MCP server exposing every suite tool under a single endpoint (stdio or Streamable HTTP) | pip install goldensuite-mcp |
The suite owns its string-matching primitives instead of renting them: byte-identical drop-in replacements, published on their own so they're usable outside the suite too.
| Library | Replaces | What it is | Install |
|---|---|---|---|
| goldenfuzz | rapidfuzz | Fuzzy-string scorers + the full fuzz.* composite family + one-vs-many extract/cdist. Byte-identical (oracle-fuzzed), faster on short strings. | pip install goldenfuzz · cargo add goldenfuzz-core |
| goldenphonetic | jellyfish | Phonetic encoders: soundex / metaphone / nysiis / match-rating. Byte-identical (6,000-input + 2,500-pair fuzz corpus), pure-Rust zero-dep. | pip install goldenphonetic · cargo add goldenphonetic-core |
| goldenmatch-hnsw | FAISS IndexHNSWFlat | Pure-Rust HNSW approximate-nearest-neighbor index (zero C deps). Powers embedding-based blocking across Python, Rust, and TS/WASM. | pip install goldenmatch-hnsw |
Entity resolution is the stage most GraphRAG pipelines do worst: duplicate surface forms of one entity scatter across documents. Two packages put GoldenMatch's resolution there:
| Package | What it does | Status |
|---|---|---|
| goldenmatch-kg | Drop-in GoldenMatch resolution as the ER stage of existing KG frameworks (neo4j-graphrag, LlamaIndex, Graphiti). | in-repo · not published (by design) |
| goldengraph | Build-your-own-KG from text: text → LLM extraction → GoldenMatch resolution → durable bi-temporal store. Rust engine; ER is the differentiator. | in-repo · first PyPI release pending |
Measured, not asserted (ER-KG-Bench): resolution scores F1 0.602 on the labelled set, ahead of Neo4j-KGBuilder (0.456), neo4j-graphrag (0.403), and MS-GraphRAG / LightRAG / Cognee / mem0 (0.066). A resolved graph also does two things passage-window RAG structurally can't: exact aggregation (size-invariant where RAG recall collapses 0.99 → 0.64 across cluster-size buckets) and temporal as-of (1.000 vs 0.002 on past-date queries).
Every headline number maps back to a single committed runner (scripts/run_benchmarks.py); see docs/reproducing-benchmarks.md for per-number commands, dataset URLs, and expected output with tolerance.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
High-performance code intelligence MCP server. Indexes codebases into a persistent knowledge graph — average repo in milliseconds. 158 languages, sub-ms queries, 99% fewer tokens. Single static binary, zero dependencies.

Universal provider proxy for OpenAI Codex & Claude Code — use any LLM (Claude, Gemini, Grok, DeepSeek, Ollama…) with Codex CLI, App, SDK, and Claude Code

Git-native persistent memory for AI coding agents. Implements Google OKF v0.2 with sub-300µs in-memory BM25 search, embedded MCP server, and progressive disclosure. Slashes token bloat by 80% with zero external databases or dependencies. Built in pure Go.

Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters, with benchmarked context reductions on reviews and large-repo workflows.

Stop your AI from making things up — it proposes, deterministic tools decide, every claim checked against ground truth with evidence. Grounded facts and context survive resets. Reverse engineering is the proving ground. MCP server + CLI.