
koala73/worldmonitorConnectors
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
86k
Atlas is a local-first memory backend for agent runtimes. It keeps a typed knowledge graph, revises beliefs with AGM compliance, and runs Ripple to propagate the impact of changed facts through dependent beliefs. It exposes the system through CLI, FastAPI, MCP, and runtime integrations, with Obsidian used for adjudication queues.
Builders who run Claude Code or other agent runtimes and need memory that updates downstream beliefs when facts change.
You can change one fact and have the affected beliefs get re-evaluated, routed for review, and kept in a tamper-evident ledger.
Implements AGM revision on a property graph and reports 49/49 compliance scenarios.
Walks `Depends_On` edges and re-computes downstream beliefs when an upstream fact changes.
Runs on your laptop and keeps the core system open-source and self-hosted.
Connects Atlas to Claude Code and other agent runtimes through MCP and native adapters.
Routes strategic contradictions into markdown for human review in Obsidian.
Ships `atlas` commands plus FastAPI and daemon entry points for operating the memory service.
git clone https://github.com/RichSchefren/atlas && cd atlas
docker compose up -d
python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
./demo.sh
atlas --help
atlas status
atlas queue --json
atlas search "current pricing belief"
atlas ingest
PYTHONPATH=. python scripts/demo_runtime_adapters.py
PYTHONPATH=. pytest tests/integration/test_agm_compliance.py -v
PYTHONPATH=. python scripts/run_bmb.py
Open-source local-first cognitive memory — alpha. Implements AGM-compliant belief revision on a property graph. Adds a propagation engine — Ripple — that recomputes downstream beliefs when an upstream fact changes. Runs entirely on your laptop.


↑ 3× preview — watch the narrated 90-second version with sound. The story behind it is on X — reply with the stale belief that bit you.
Alpha: the propagation loop works end-to-end (
./demo.shproves it in 12 seconds). Ingestion and entity resolution on truly unstructured text are still maturing — seeatlas_core/ingestion/for the prompts we're iterating on.
git clone https://github.com/RichSchefren/atlas && cd atlas
docker compose up -d
python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
./demo.sh
The ./demo.sh command runs the entire loop end-to-end, visibly:
Depends_On edges)RippleEngine.propagate() — the real orchestratoradjudication.resolve() (real AGM revise)Every line is real Neo4j + real ledger. No mocks. ~6s on subsequent runs. This is the front door — if it doesn't impress, nothing else will.
The final stages of ./demo.sh should look like this — if they don't, file an issue:
▶ Stage 4 / 7 — RippleEngine.propagate()
  ✓ cascade complete
  impacted nodes: 2
  contradictions: 0
  routing — auto: 1, strategic: 1, core: 0

▶ Stage 5 / 7 — Reassessment proposals
  1. kref://AtlasDemo/Beliefs/origins_accessible.belief
     0.88 → 0.75  (-0.13)
  2. kref://AtlasDemo/Decisions/marketing_to_newcomers.decision
     0.80 → 0.66  (-0.14)

▶ Stage 6 / 7 — Resolve one through adjudication
  ✓ resolved with decision='accept'

▶ Stage 7 / 7 — Verify SHA-256 ledger chain
  ✓ chain intact at sequence 1

LOOP CLOSED.
last_verified_sequence = 1 looks small because the demo plants exactly one promotion-eligible fact and verifies the chain holds with one entry — every later run extends the chain and the number grows. The point is the chain intact, not the count.
The installed Python package also exposes an atlas command:
atlas --help
atlas status
atlas queue --json
atlas search "current pricing belief"
atlas ingest
atlas demo delegates to the complete repository demo.sh, so that one
command requires a source checkout. The operational commands work from an
installed package.
To save you time:
Depends_On graph. Vector-only systems can retrieve old context; Atlas reassesses what depended on it. (Worked example with stale-belief failure mode →)atlas_core/ingestion/extractors/ for the prompt set we're iterating on.The adapter cores now perform real local store, search / recall, get,
list, and forget operations against Atlas's SQLite trust store. This path
does not require Neo4j, Docker, an embedding model, or an API key:
PYTHONPATH=. python scripts/demo_runtime_adapters.py
CI runs that proof with the Neo4j endpoint deliberately pointed at a dead port.
Atlas also ships native packages for current Hermes Agent, OpenClaw, and GBrain:
integrations/hermes-atlas/ implements Hermes's
MemoryProvider lifecycle, and
integrations/openclaw-atlas/ is a TypeScript
memory-capability plugin. integrations/gbrain-atlas/
is a package-only MCP bridge that keeps GBrain pages authoritative while Atlas
adds page-linked cognition. All three are tested against pinned upstream
contracts and require no Neo4j or Docker for retrieval or the bounded
AGM/Ripple service.
Hermes, OpenClaw, and GBrain now share one proven cognitive boundary: their native packages manage a profile-scoped, authenticated localhost service that owns AGM revision, dependency traversal, and persisted Ripple proposals. Cognitive records participate in recall, search, list, get, forget, audit, and restart. The service uses SQLite for persistence but keeps cognitive semantics in one Python owner, not in host-specific adapters or SQL. Hermes manages one service per profile, OpenClaw manages one per agent/session scope, and the GBrain bridge maps brain + source + slug to a stable Atlas identity. Its black-box suite covers 49 AGM scenario IDs plus the canonical A-to-B cascade, and its 10k/20k performance contract is enforced in CI.
OpenClaw's protected host proof executes all seven tools, including dependency
declaration and a revision that must emit a nonempty Ripple proposal set.
GBrain's protected host proof installs the package-only tarball and drives the
real pinned gbrain serve MCP lifecycle. The exact capability split and installation paths are in
docs/RUNTIME_ADAPTERS.md.
The strongest early users are:
Three concrete shapes the loop solves:
After running ./demo.sh, open http://localhost:7474 (default password atlasdev) and run any of these:
// Show the dependency edges Atlas walks during Ripple
MATCH (downstream)-[r:DEPENDS_ON]->(upstream)
RETURN downstream.kref, upstream.kref, r.dependency_strength
LIMIT 25;

// Show every belief and its current confidence
MATCH (b:Belief)
RETURN b.kref, b.confidence_score, b.deprecated
ORDER BY b.confidence_score DESC;

// Show the AGM revision history of a single belief
MATCH (root:AtlasItem)-[:REVISED_TO|SUPERSEDES*0..]->(rev)
WHERE root.kref = 'kref://AtlasCoffee/Beliefs/origins_value.belief'
RETURN rev.revision_index, rev.content, rev.revision_reason
ORDER BY rev.revision_index;

// Show the contradictions detector found
MATCH (a)-[r:CONTRADICTS]->(b)
RETURN a.kref, b.kref, r.detected_at;
The video Every Claude Code Memory System Compared maps 6 levels of memory — from native CLAUDE.md to OpenBrain's cross-tool Postgres. They all answer the same question: "how do we store and retrieve?"
Atlas answers a different question: when stored knowledge changes, what happens to everything that depended on it?
That's a Level 7 problem. Atlas runs ON TOP of any of the 6 lower levels. Every memory system flags affected beliefs when a fact changes. Atlas is the only one that re-evaluates them.
You have a vault. Maybe Obsidian, maybe Notion, maybe just markdown in a folder. Plus your meetings get transcribed (Limitless, Fireflies, Otter), plus your screen gets captured (Screenpipe, Rewind), plus you talk to Claude or ChatGPT all day. Together that's hundreds of files and tens of thousands of facts about your work.
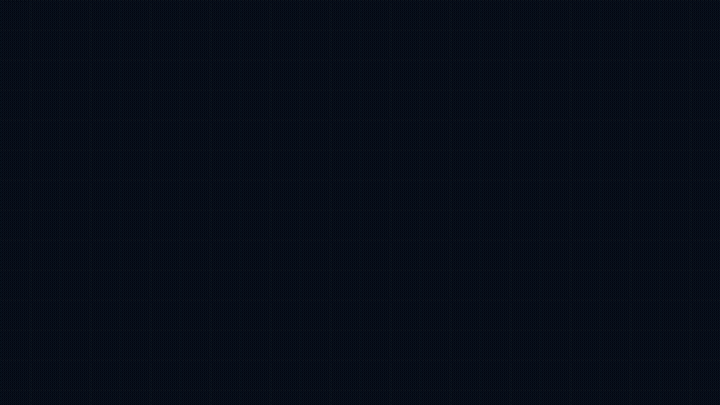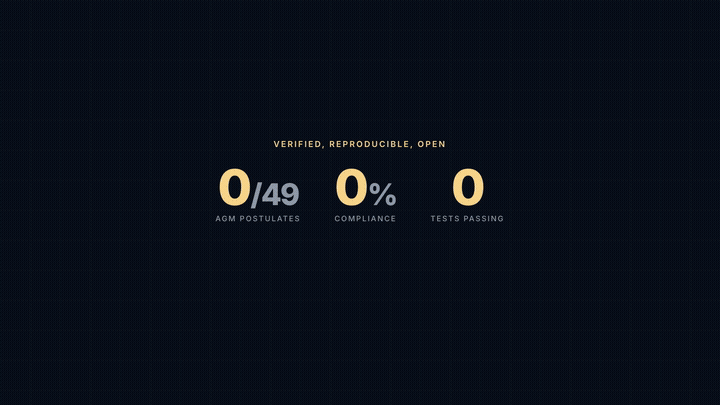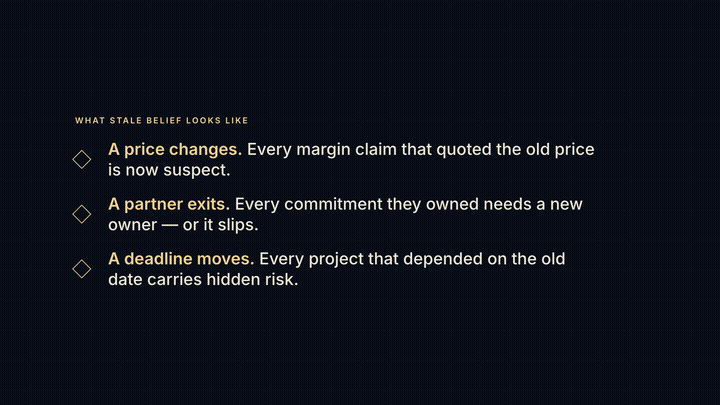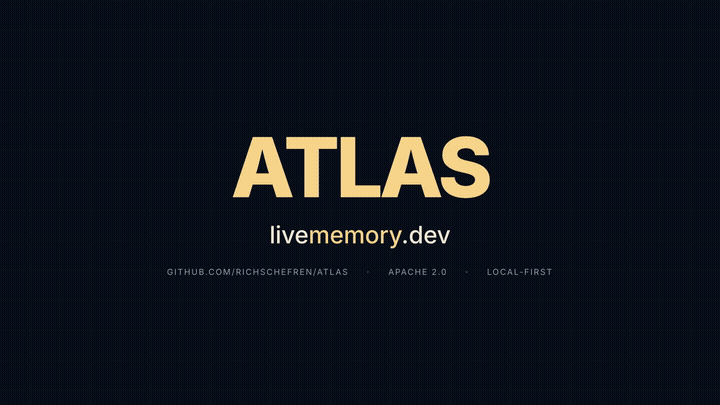
The problem we focus on: when one of those facts changes — a price changes, a partner exits, a deadline slips — every belief that depended on the old fact is now suspect. Today, you have to chase the cascade in your head. Atlas tries to do it for you.
We're not aware of another open-source system that ships propagation as a first-class primitive; if you know of one, please file an issue — we want to compare honestly.
| When a fact changes... | Typical memory systems | Atlas (alpha) |
|---|---|---|
| Detect what's affected | Vector-similarity heuristic | Depends_On graph walk via RippleEngine.analyze_impact() |
| Re-evaluate downstream beliefs | Not exposed as a primitive | RippleEngine.propagate() — additive-with-damping confidence updates |
| Surface emergent contradictions | Not exposed | Type-aware detector (atlas_core/ripple/contradiction.py) |
| Route strategic conflicts to human | Not exposed | Obsidian markdown queue + adjudication.resolve() |
| Audit what was decided and why | Limited | Hash-chained SHA-256 ledger with verify_chain() |
| Forget deprecated beliefs cleanly | Not exposed | AGM contract() removes from closure, preserves history |
Verify any row above by reading the cited module or running ./demo.sh.
Atlas implements AGM belief revision (Alchourrón-Gärdenfors-Makinson 1985) on a property graph. The seven postulates K*2-K*6 plus Hansson's Relevance and Core-Retainment all hold — verified by 49 scenarios against live Neo4j 5.26. Same compliance Kumiho's commercial paper claims, but as fully open-source local-first code anyone can audit. The full per-scenario reproducibility artifact is at docs/AGM_COMPLIANCE.md (machine-readable rows in benchmarks/agm_compliance/runs/baseline.json).
If you're shopping memory backends for an agent system, here's how Atlas stacks up against the named alternatives:
| Atlas | Kumiho | Graphiti | Mem0 | Letta | Memori | |
|---|---|---|---|---|---|---|
| Open-source | ✅ Apache 2.0 | ❌ commercial | ✅ | ✅ | ✅ | ✅ |
| Local-first (no cloud) | ✅ | ❌ requires kumiho.io | ✅ | partial | ✅ | ✅ |
| AGM-compliant revision (K*2–K*6) | ✅ 49/49 @ 100% | ✅ 49/49 @ 100% | ❌ | ❌ | ❌ | ❌ |
| Hansson Relevance + Core-Retainment | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ |
| Hash-chained tamper-detection ledger | ✅ SHA-256 | partial | ❌ | ❌ | ❌ | ❌ |
| Automatic downstream reassessment (Ripple) | ✅ | ❌ flag-only | ❌ | ❌ | ❌ | ❌ |
| Domain-typed business ontology shipped | ✅ 8 entity types | ❌ | ❌ | ❌ | ❌ | partial |
| Continuous multi-stream ingestion | ✅ 6 streams | ❌ SDK only | ❌ | ❌ | ❌ | partial |
| Runtime integration | ✅ Claude MCP + native Hermes/OpenClaw/GBrain | partial | ❌ | partial | ❌ | ❌ |
The table above lists what Atlas does that the alternatives don't. The other half of an honest comparison: here's what they currently do better, and where you should reach for them instead of Atlas.
| Concern | What we'd reach for instead | Why |
|---|---|---|
| Pure-retrieval throughput on large corpora | Mem0, a hosted vector DB | Atlas reads embeddings, but the typed graph + Ripple bookkeeping adds latency a vector-only path doesn't pay. If retrieval-quality alone is your bottleneck, a flat vector index will be faster. |
| Conversational chat memory ("remember what I said in this thread") | Letta, Memori | Atlas is built around long-lived business beliefs and dependencies. For "the user mentioned a cat in turn 3, surface that in turn 47" you want a system designed for conversation state. |
| Managed hosted service, support contract, SOC 2 | Kumiho's commercial cloud | Atlas is open-source local-first. There is no "Atlas Inc." with a sales team. If your buying process needs a vendor on the other end, Atlas isn't that yet. |
| Plug-and-play with zero-config setup | Mem0, Letta | Atlas wants you to think about your domain — it ships the AGM operators, not a "just call add_memory()" facade. The opinionated typed ontology is power for some users and friction for others. |
| Real-time multi-user concurrency at scale | A managed graph platform (Neo4j Aura, AuraDB) | Atlas's local-first stance means a single Neo4j instance per user. Multi-tenant Tier 5 work is in progress; production-grade concurrency tuning is not the alpha's focus. |
| Natural-language extraction quality on truly unstructured text | LLM-tuned extractors maintained by a larger team | The extractors in atlas_core/ingestion/extractors/ work on real Limitless / Fireflies / Claude transcripts but quality is uneven — see the alpha framing in the hero. Improving extraction is on the roadmap; if you need state-of-the-art entity extraction today, build a richer extraction layer above Atlas's quarantine API. |
If your shopping criteria match any row in the worse table, use the alternative. Atlas exists for the case where dependency-driven belief revision is load-bearing — and it's better to admit the tradeoffs than to over-claim and lose your trust the moment you hit one.
Atlas is a Python service that maintains a continuously-updated typed knowledge graph of your domain. Tell it something — directly, or via continuous capture from Screenpipe / Limitless / Fireflies / Claude Code logs / Obsidian / iMessage — and it:
Depends_On edges, re-evaluates downstream beliefs with confidence propagation, surfaces emergent contradictions. Atlas does not infer dependency edges from prose; callers declare them through the AGM/MCP surfaces.All revisions are AGM-compliant (K*2–K*6 + Hansson Relevance + Core-Retainment), formally verified against Kumiho's correspondence theorem (arxiv:2603.17244).
Honest accounting. Atlas's cost story shifts dramatically between v0.1.0a1 (today) and the post-Tier-1 system:
v0.1.0a1 (today): ≈ $0/month.
HeuristicReassessor (default) does no LLM call; it's a closed-form damped formula. The LLMReassessor exists but is opt-in and not the default.Post-Tier-1.4 (LLM-driven extraction lands): bounded by your token budget.
ATLAS_DAILY_LLM_BUDGET_USD, defaults to $5/day) hard-stops extraction when the daily budget is exceeded. Worst case is $150/month even if the corpus explodes.Post-Tier-1.3 (entity resolution lands): same dollars, clearer outcomes.
For multi-tenant deployments (one Neo4j, many trust ledgers — not yet implemented but plausible by 2027), the math scales linearly per active user. A 100-user deployment at Rich-scale per user is ≈ $5K-12K/month in inference, dominantly Haiku.
The substrate strategy bet: $50-125/month is below the line where most knowledge workers think twice. It's an order of magnitude cheaper than running Cursor or hosting Mem0's commercial cloud. Atlas's local-first design is the architectural reason this number stays small.
On a one-author corpus (Rich Schefren's actual Obsidian vault + 5,000 Limitless transcripts + 300 Screenpipe audio rows + 5,000 Claude Code session logs):
== Atlas first real run ==
Streams        : 4
Total events   : 10,604
Total claims   : 14,674
Total errors   : 0
Elapsed        : 21.3s

Quarantine status breakdown:
  requires_approval      6,761  (medium-risk default; awaits adjudication)

Quarantine lane breakdown:
  atlas_observational    5,608  (Limitless + Screenpipe)
  atlas_vault              956  (vault frontmatter + body)
  atlas_chat_history       197  (Claude session prompts)

Ledger intact: ✅  (SHA-256 chain verified)
Re-runs are idempotent: 0.9s for the next cycle, with all duplicate claims fingerprint-deduplicated against existing entries.
Three good install paths depending on why you want Atlas — researcher / dev, Obsidian power-user, or agent-runtime integration. Each one is self-contained and documented in
docs/INSTALL_MODES.md. The block below is the universal version that works for all three.
# 1. Clone
git clone https://github.com/RichSchefren/atlas && cd atlas

# 2a. Prove portable Hermes/OpenClaw storage + retrieval (no Docker)
python -m venv .venv && source .venv/bin/activate
pip install -e .
PYTHONPATH=. python scripts/demo_runtime_adapters.py

# 2b. Native Hermes: install its managed cognitive service (no Docker)
bash integrations/hermes-atlas/install.sh

# 2c. Or install the native OpenClaw / GBrain cognitive package
bash integrations/openclaw-atlas/install.sh
bash integrations/gbrain-atlas/install.sh

# 2d. Optional broader property-graph/MCP/adjudication tier
docker compose up -d                               # bolt://localhost:7687

# 3. Install — base is deterministic + $0/month; opt in to extras as you need them
pip install -e .              # core: AGM + Ripple + ledger + adapters + ingest
# pip install -e ".[llm]"        # add Anthropic SDK for LLM-driven extraction
# pip install -e ".[embeddings]" # add sentence-transformers (~2GB; rarely needed — vault-search is the default retrieval path)
# pip install -e ".[benchmarks]" # add Mem0 / Letta clients for the BMB matrix
# pip install -e ".[full]"       # everything above
# pip install -e ".[dev]"        # contributor tooling (includes anthropic for tests)

# 4. Verify with the test suite (532 tests in this snapshot)
PYTHONPATH=. pytest tests/ -v

# 5. Reproduce AGM compliance (49/49 scenarios, ~30s)
PYTHONPATH=. pytest tests/integration/test_agm_compliance.py -v

# 6. First real ingest from your own Obsidian vault
ATLAS_VAULT_ROOT=~/Documents/Obsidian PYTHONPATH=. python scripts/first_real_run.py

# 6b. Multiple vaults (colon-separated, like PATH) — e.g. a shared business
#     vault plus a personal vault feeding one belief graph
ATLAS_VAULT_ROOTS=~/Vaults/business:~/Vaults/personal PYTHONPATH=. python scripts/first_real_run.py
┌──────────────────────────────────────────────────────────────┐
│  ATLAS API LAYER                                             │
│  MCP (13 tools) · FastAPI (:9879) · Kumiho-compatible gRPC    │
│  + Hermes / OpenClaw cores + Claude Code MCP                 │
└──────────────────────────────────────────────────────────────┘
                            │
┌──────────────────────────────────────────────────────────────┐
│  RIPPLE ENGINE — Atlas's novel contribution                  │
│  AnalyzeImpact → Reassess → Type-aware Contradictions →      │
│  Adjudication routing (auto / strategic / core-protected)    │
└──────────────────────────────────────────────────────────────┘
                            │
┌──────────────────────────────────────────────────────────────┐
│  TRUST LAYER — Quarantine → Corroboration → Hash-chained     │
│  Ledger. SHA-256 chain with verify_chain() tamper detection. │
└──────────────────────────────────────────────────────────────┘
                            │
┌──────────────────────────────────────────────────────────────┐
│  AGM REVISION — K*2–K*6 + Hansson, Cypher-backed             │
│  49/49 compliance scenarios pass at 100%                     │
└──────────────────────────────────────────────────────────────┘
                            │
┌──────────────────────────────────────────────────────────────┐
│  ATLAS CORE — fork of Graphiti                               │
│  Bitemporal edges. 6 Kumiho typed edges + 8 domain entities  │
└──────────────────────────────────────────────────────────────┘
                            │
┌──────────────────────────────────────────────────────────────┐
│  CONTINUOUS INGESTION — 6 streams, idempotent cursors        │
│  Vault · Limitless · Screenpipe · Claude · Fireflies · iMsg  │
└──────────────────────────────────────────────────────────────┘
Full design docs are checked into the repo at paper/atlas.md and PHASE-5-AND-BEYOND.md. The deeper Phase 0 / Phase 1 specs live in the maintainer's private notes — public summaries are in the paper draft.
Atlas ships with three conc
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface
High-performance code intelligence MCP server. Indexes codebases into a persistent knowledge graph — average repo in milliseconds. 158 languages, sub-ms queries, 99% fewer tokens. Single static binary, zero dependencies.

Universal provider proxy for OpenAI Codex & Claude Code — use any LLM (Claude, Gemini, Grok, DeepSeek, Ollama…) with Codex CLI, App, SDK, and Claude Code

Git-native persistent memory for AI coding agents. Implements Google OKF v0.2 with sub-300µs in-memory BM25 search, embedded MCP server, and progressive disclosure. Slashes token bloat by 80% with zero external databases or dependencies. Built in pure Go.

Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters, with benchmarked context reductions on reviews and large-repo workflows.

Stop your AI from making things up — it proposes, deterministic tools decide, every claim checked against ground truth with evidence. Grounded facts and context survive resets. Reverse engineering is the proving ground. MCP server + CLI.