English | 中文 | 日本語
[!IMPORTANT]
:rocket: Gateway 2.0 (Pre-Release) Portkey's core enterprise gateway is merging into open-source with our 2.0 release. You can try the pre-release branch here.
Read more about what's next for Portkey in our Series A announcement.
The AI Gateway is designed for fast, reliable & secure routing to 1600+ language, vision, audio, and image models. It is a lightweight, open-source, and enterprise-ready solution that allows you to integrate with any language model in under 2 minutes.
What can you do with the AI Gateway?
[!TIP]
Starring this repo helps more developers discover the AI Gateway 🙏🏻

Quickstart (2 mins)
1. Setup your AI Gateway
# Run the gateway locally (needs Node.js and npm)
npx @portkey-ai/gateway
The Gateway is running on http://localhost:8787/v1
The Gateway Console is running on http://localhost:8787/public/
Deployment guides:
 Portkey Cloud (Recommended)
 Docker
 Node.js
 Cloudflare
 Replit
Others...
2. Make your first request
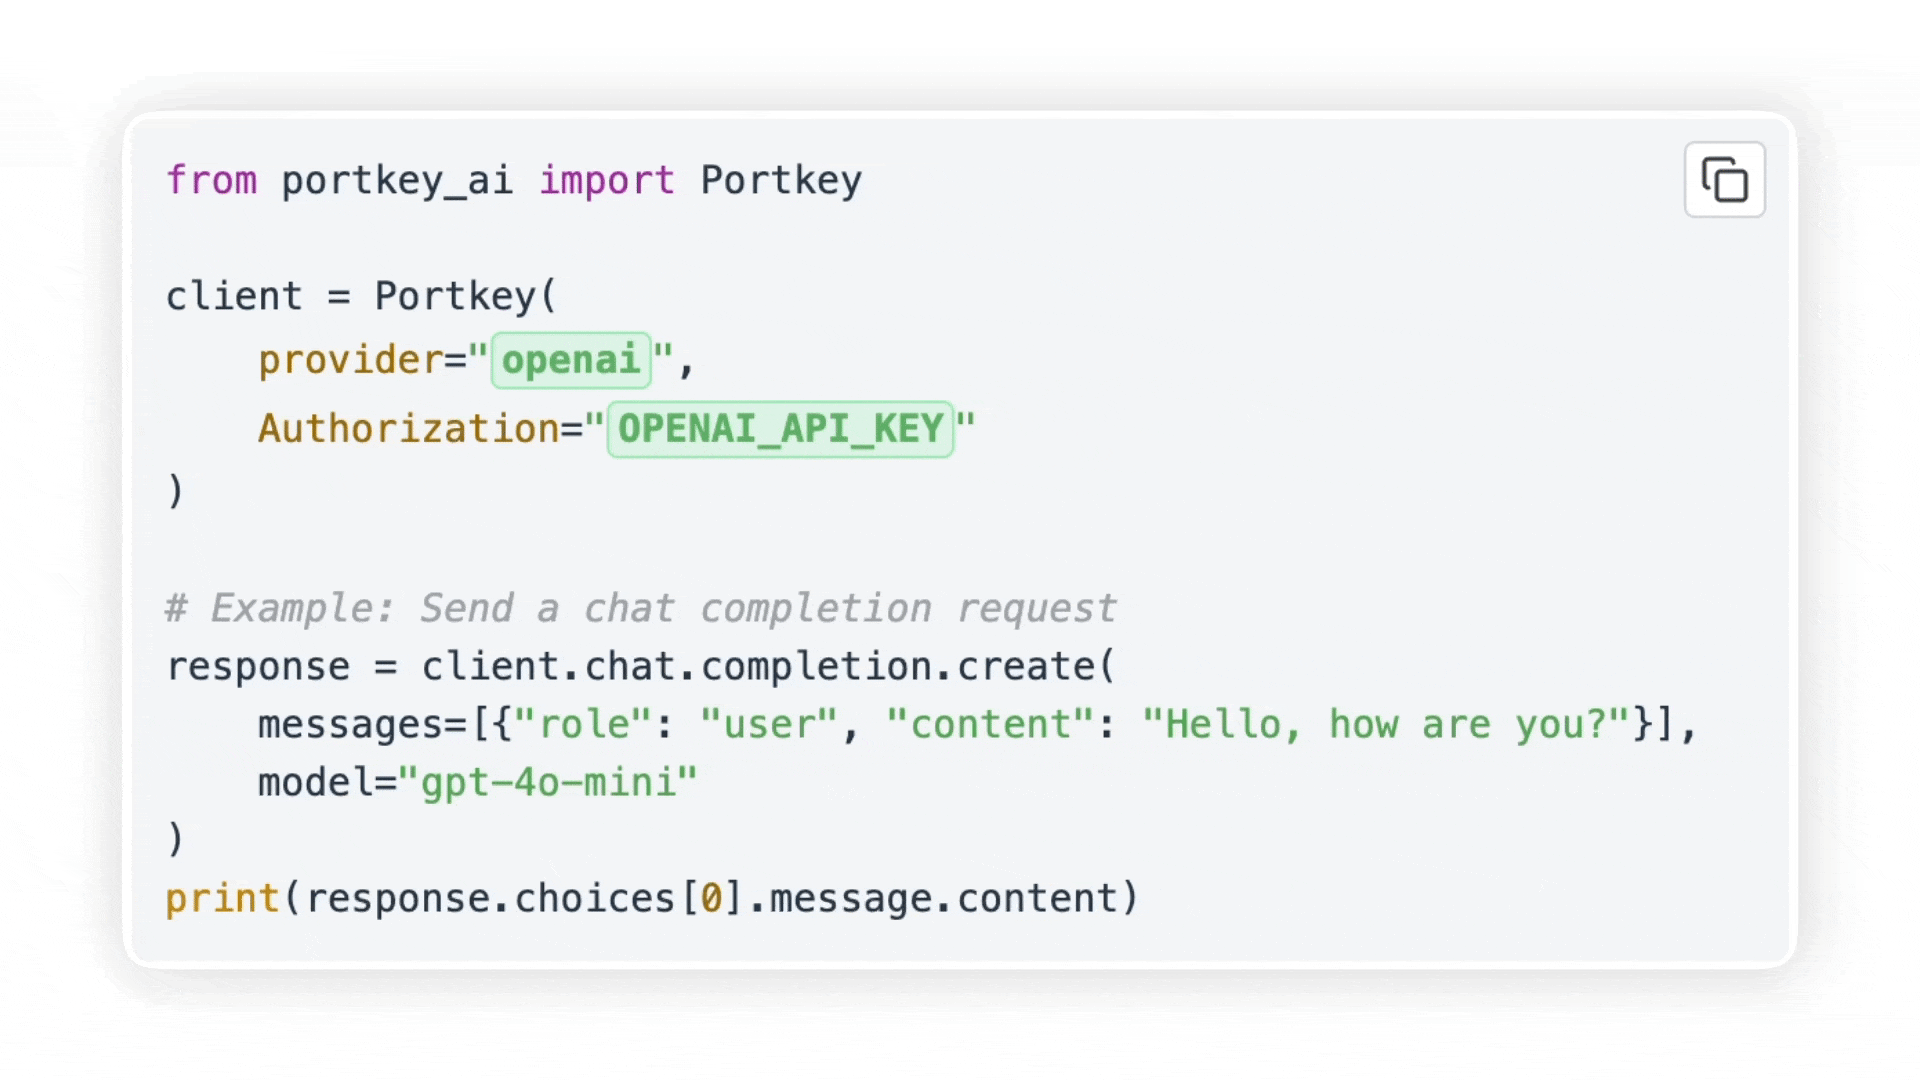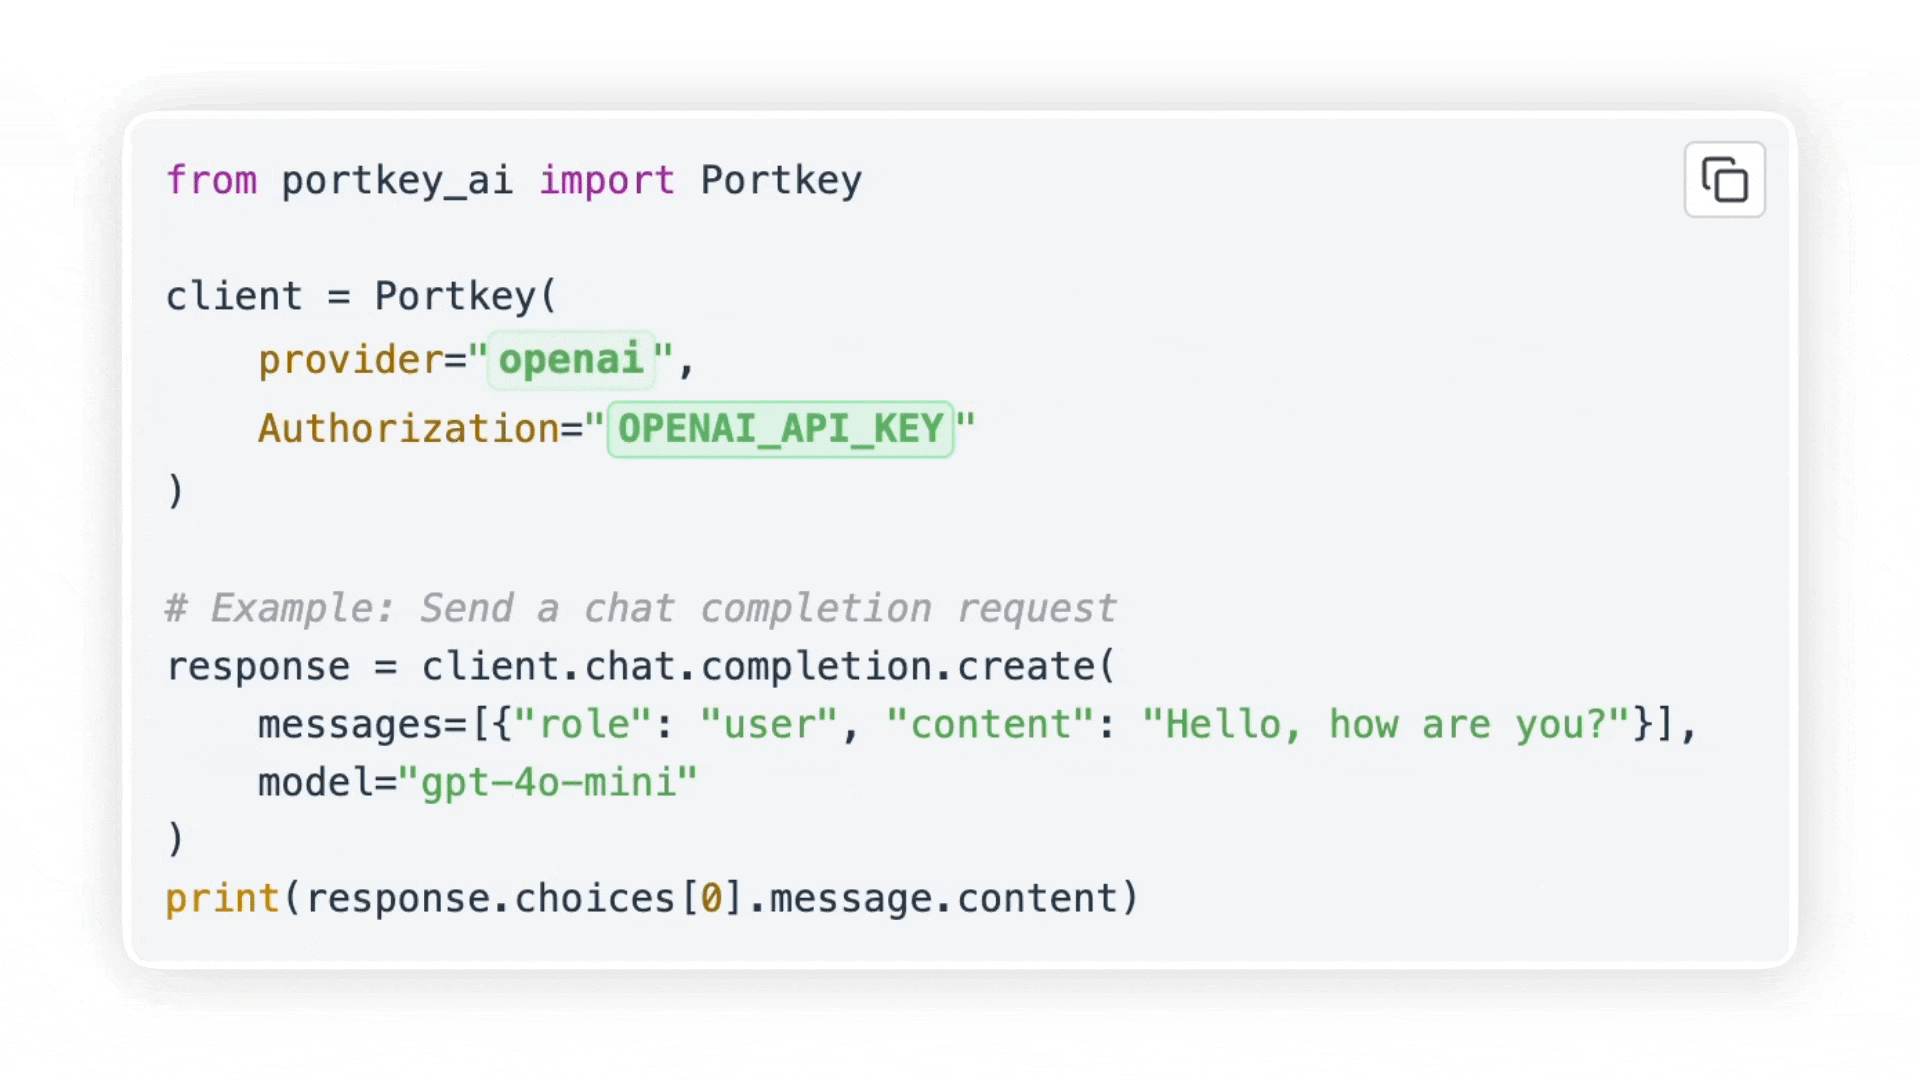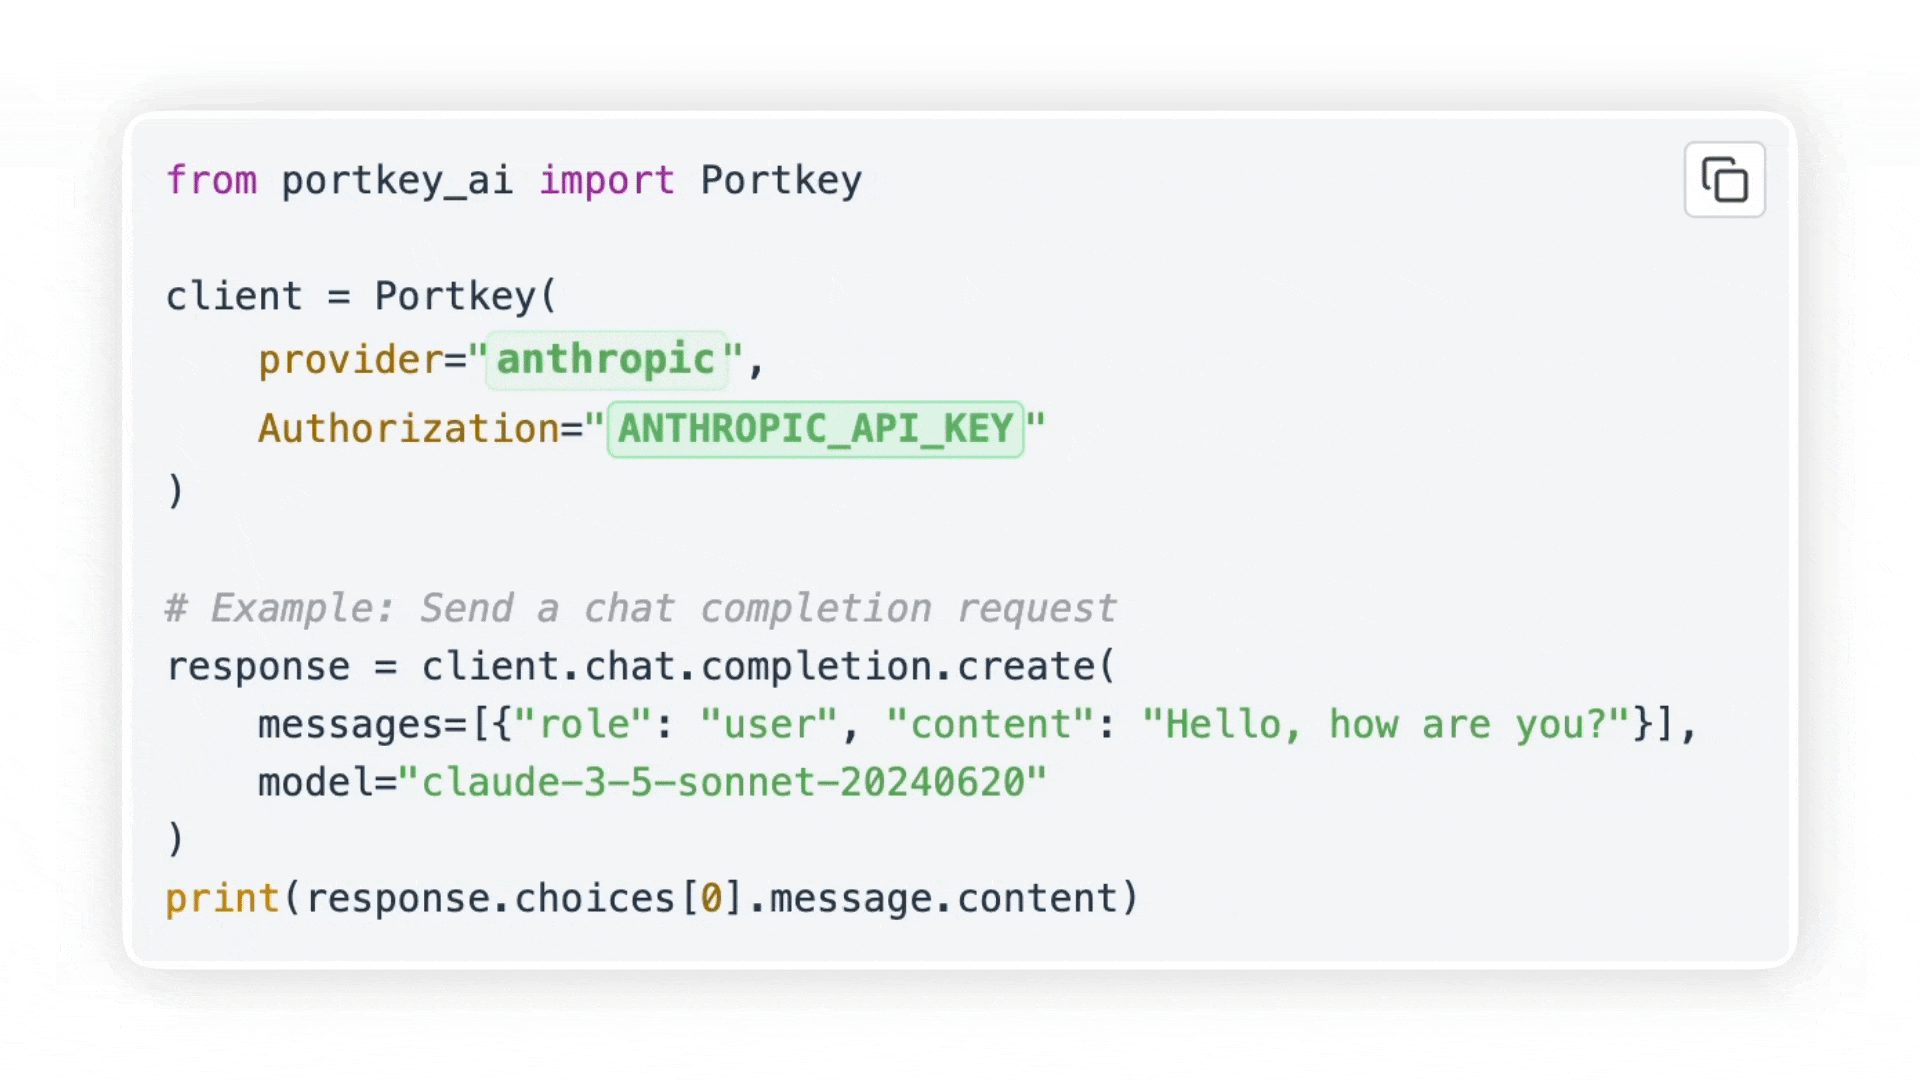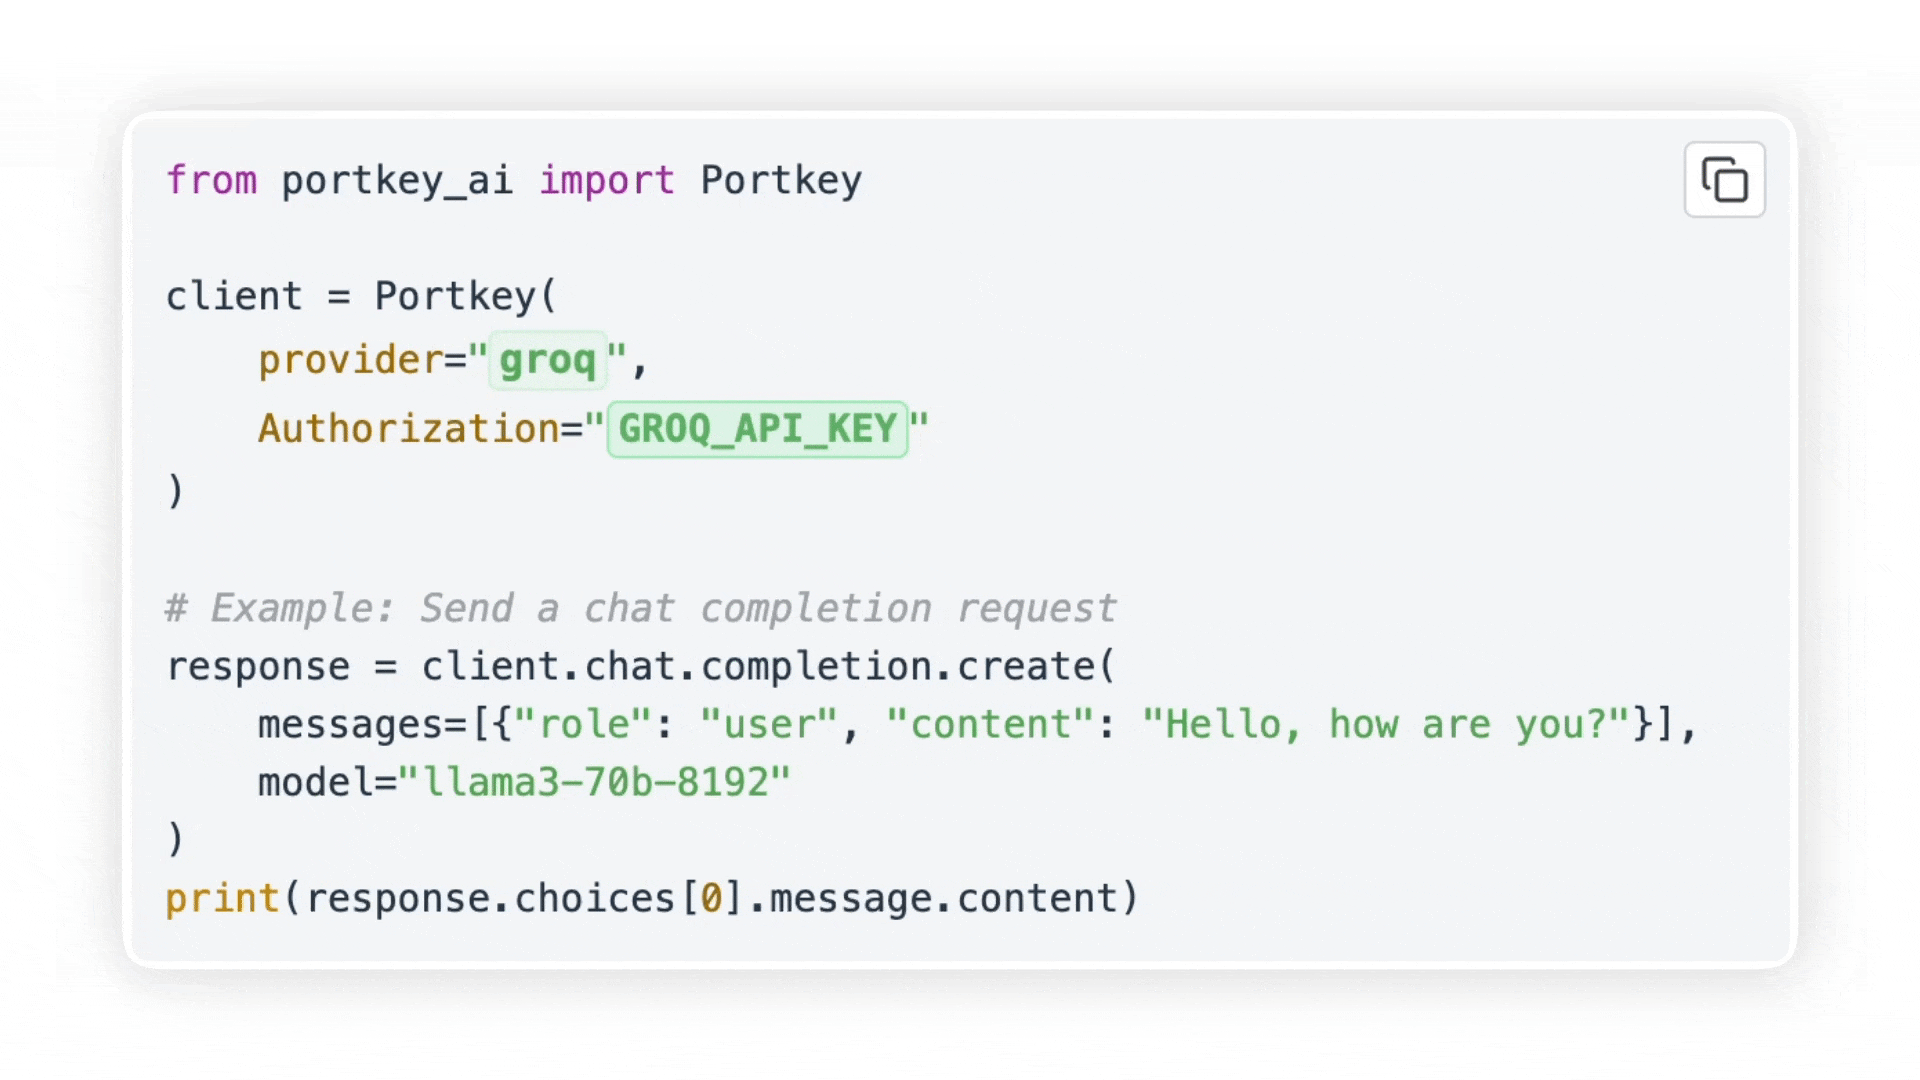
# pip install -qU portkey-ai

from portkey_ai import Portkey

# OpenAI compatible client
client = Portkey(
    provider="openai", # or 'anthropic', 'bedrock', 'groq', etc
    Authorization="sk-***" # the provider API key
)

# Make a request through your AI Gateway
client.chat.completions.create(
    messages=[{"role": "user", "content": "What's the weather like?"}],
    model="gpt-4o-mini"
)
Supported Libraries:
 JS
 Python
 REST
 OpenAI SDKs
 Langchain
LlamaIndex
Autogen
CrewAI
More..
On the Gateway Console (http://localhost:8787/public/) you can see all of your local logs in one place.

3. Routing & Guardrails
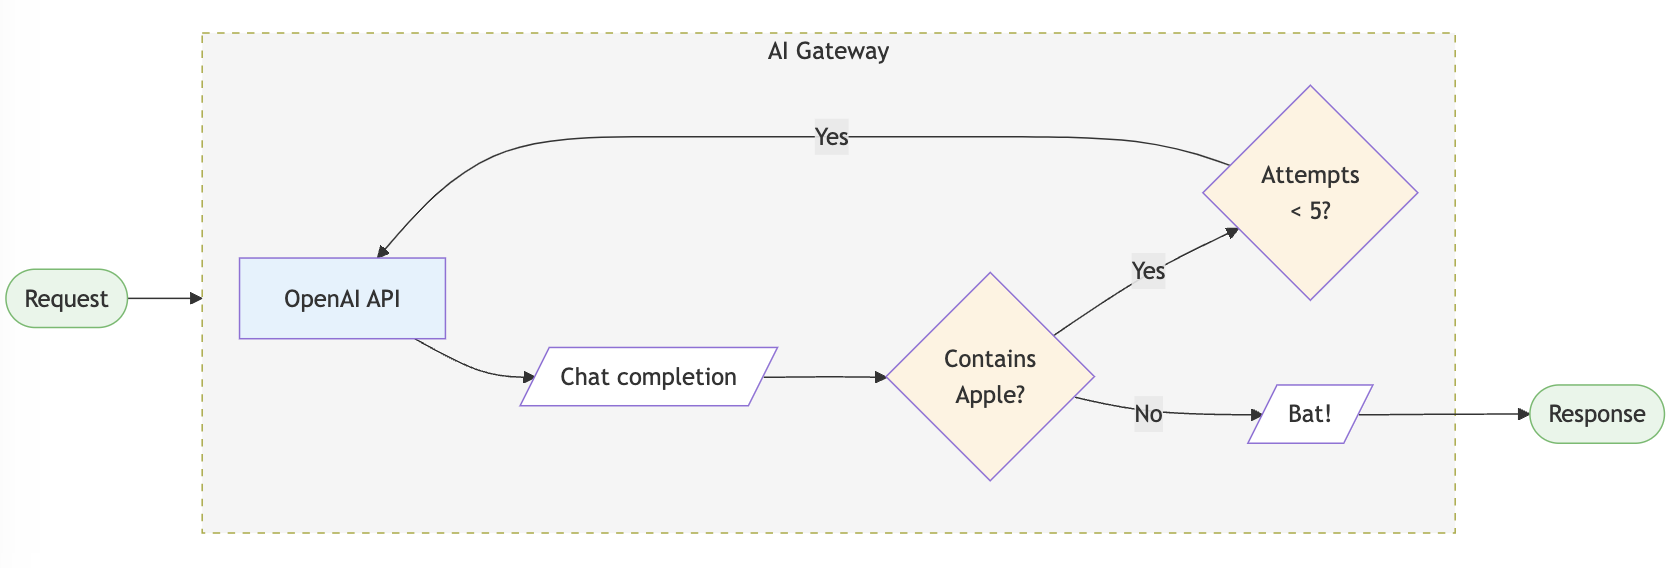
Configs in the LLM gateway allow you to create routing rules, add reliability and setup guardrails.
config = {
  "retry": {"attempts": 5},

  "output_guardrails": [{
    "default.contains": {"operator": "none", "words": ["Apple"]},
    "deny": True
  }]
}

# Attach the config to the client
client = client.with_options(config=config)

client.chat.completions.create(
    model="gpt-4o-mini",
    messages=[{"role": "user", "content": "Reply randomly with Apple or Bat"}]
)

# This would always response with "Bat" as the guardrail denies all replies containing "Apple". The retry config would retry 5 times before giving up.
You can do a lot more stuff with configs in your AI gateway. Jump to examples →
Enterprise Version (Private deployments)
 AWS
 Azure
 GCP
 OpenShift
 Kubernetes
The LLM Gateway's enterprise version offers advanced capabilities for org management, governance, security and more out of the box. View Feature Comparison →
The enterprise deployment architecture for supported platforms is available here - Enterprise Private Cloud Deployments
MCP Gateway
MCP Gateway provides a centralized control plane for managing MCP (Model Context Protocol) servers across your organization.
- Authentication — Single auth layer at the gateway. Users authenticate once; your MCP servers receive verified requests
- Access Control — Control which teams and users can access which servers and tools. Revoke access instantly
- Observability — Every tool call logged with full context: who called what, parameters, response, latency
- Identity Forwarding — Forward user identity (email, team, roles) to MCP servers automatically
Works with Claude Desktop, Cursor, VS Code, and any MCP-compatible client. Get started →
Core Features
Reliable Routing
- Fallbacks: Fallback to another provider or model on failed requests using the LLM gateway. You can specify the errors on which to trigger the fallback. Improves reliability of your application.
- Automatic Retries: Automatically retry failed requests up to 5 times. An exponential backoff strategy spaces out retry attempts to prevent network overload.
- Load Balancing: Distribute LLM requests across multiple API keys or AI providers with weights to ensure high availability and optimal performance.
- Request Timeouts: Manage unruly LLMs & latencies by setting up granular request timeouts, allowing automatic termination of requests that exceed a specified duration.
- Multi-modal LLM Gateway: Call vision, audio (text-to-speech & speech-to-text), and image generation models from multiple providers — all using the familiar OpenAI signature
- Realtime APIs: Call realtime APIs launched by OpenAI through the integrate websockets server.
Security & Accuracy
Cost Management
- Smart caching: Cache responses from LLMs to reduce costs and improve latency. Supports simple and semantic* caching.
- Usage analytics: Monitor and analyze your AI and LLM usage, including request volume, latency, costs and error rates.
- Provider optimization*: Automatically switch to the most cost-effective provider based on usage patterns and pricing models.
Collaboration & Workflows
* Available in hosted and enterprise versions
Portkey Models
Open-source LLM pricing database for 40+ providers - used by the Gateway for cost tracking.
GitHub | Model Explorer
Cookbooks
☄️ Trending
🚨 Latest
View all cookbooks →
Supported Providers
Explore Gateway integrations with 45+ providers and 8+ agent frameworks.
View the complete list of 200+ supported models here
Agents
Gateway seamlessly integrates with popular agent frameworks. Read the documentation here.
*Available on the hosted app. For detailed documentation click here.
Gateway Enterprise Version
Make your AI app more reliable and forward compatible, while ensuring complete data security and privacy.
✅ Secure Key Management - for role-based access control and tracking
✅ Simple & Semantic Caching - to serve repeat queries faster & save costs
✅ Access Control & Inbound Rules - to control which IPs and Geos can connect to your deployments
✅ PII Redaction - to automatically remove sensitive data from your requests to prevent indavertent exposure
✅ SOC2, ISO, HIPAA, GDPR Compliances - for best security practices
✅ Professional Support - along with feature prioritization
Schedule a call to discuss enterprise deployments
Contributing
The easiest way to contribute is to pick an issue with the good first issue tag 💪. Read the contribution guidelines here.
Bug Report? File here | Feature Request? File here
Getting Started with the Community
Join our weekly AI Engineering Hours every Friday (8 AM PT) to:
- Meet other contributors and community members
- Learn advanced Gateway features and implementation patterns
- Share your experiences and get help
- Stay updated with the latest development priorities
Join the next session → | Meeting notes
Community
Join our growing community around the world, for help, ideas, and discussions on AI.