


heygen-com/hyperframesFrameworks & SDKs
Write HTML. Render video. Built for agents.
49k
This repo provides a full pipeline for measuring skill switching difficulty and training models on it. It includes skill labeling, entropy calibration, task generation, supervised warm-up, GRPO training, and checkpoint evaluation.
Builders who are creating benchmarks or training runs for models that need to switch between skills over long tasks.
You can measure which skill combinations are hard and train a model to do better on them.
Labels skills from generated text and merges duplicates into a cleaned skill set.
Computes entropy maps from reference-model performance to score how hard skill switches are.
Generates benchmark task pools, including open-ended and math-focused variants.
Builds supervised fine-tuning traces from task pools before RL training.
Runs GRPO training with rewards that combine final-answer quality and skill-switching plan quality.
Evaluates checkpoints and API models against Skill²-Bench using vLLM or gateway-backed model calls.
# core trainer (installs verl fork + dependencies)
cd skill_entropy_rl && pip install -e . && cd ..

# eval extras
pip install antlr4-python3-runtime==4.11.1 word2number timeout-decorator
export SKILL_ENTROPY_RL_ROOT=/path/to/this/repo
mkdir -p $SKILL_ENTROPY_RL_ROOT/job_log   # SLURM launchers write their logs here (gitignored)
bash label_skills/label_skills.sh                # skill labeling (vLLM)
bash label_skills/deduplicate_skills.sh          # merge + dedupe labels → label_skills/merged_skill_labels/
cd calculate_skill_entropy && bash run.sh       # reference-model calibration → entropy map
bash propose_tasks/propose_tasks_api.sh          # benchmark tasks (API proposer — produced skill2_bench/)
sbatch propose_tasks/propose_tasks.sh            # math RL task pool (vLLM proposer → propose_tasks/math/)
sbatch sft/sft.sh                                # cross-skill SFT (sft_math.sh for math-only)
# regenerate SFT traces from a task pool: sft/generate_skillrl_sft.sh / generate_skillrl_sft_math.sh
# builds train/val parquets, then launches training
sbatch skill_entropy_rl/examples/grpo_trainer/run_skill_entropy_rl.sh           # Skill-Entropy RL
sbatch skill_entropy_rl/examples/grpo_trainer/run_skill_entropy_rl_math.sh      # math RL (needs a stage-2 math pool in propose_tasks/math/)
# chained multi-day runs: skill_entropy_rl/examples/grpo_trainer/launch_chain.sh
Toward Skill-Native LLMs: Skill Entropy for Benchmarking and Training Long-Horizon Reasoning
Yinghui He, Ling Yang, Jiarui Liu, Yongjin Yang, Lechen Zhang,
Yingcheng Wu, Zhenfei Yin, Mengdi Wang, Sanjeev Arora
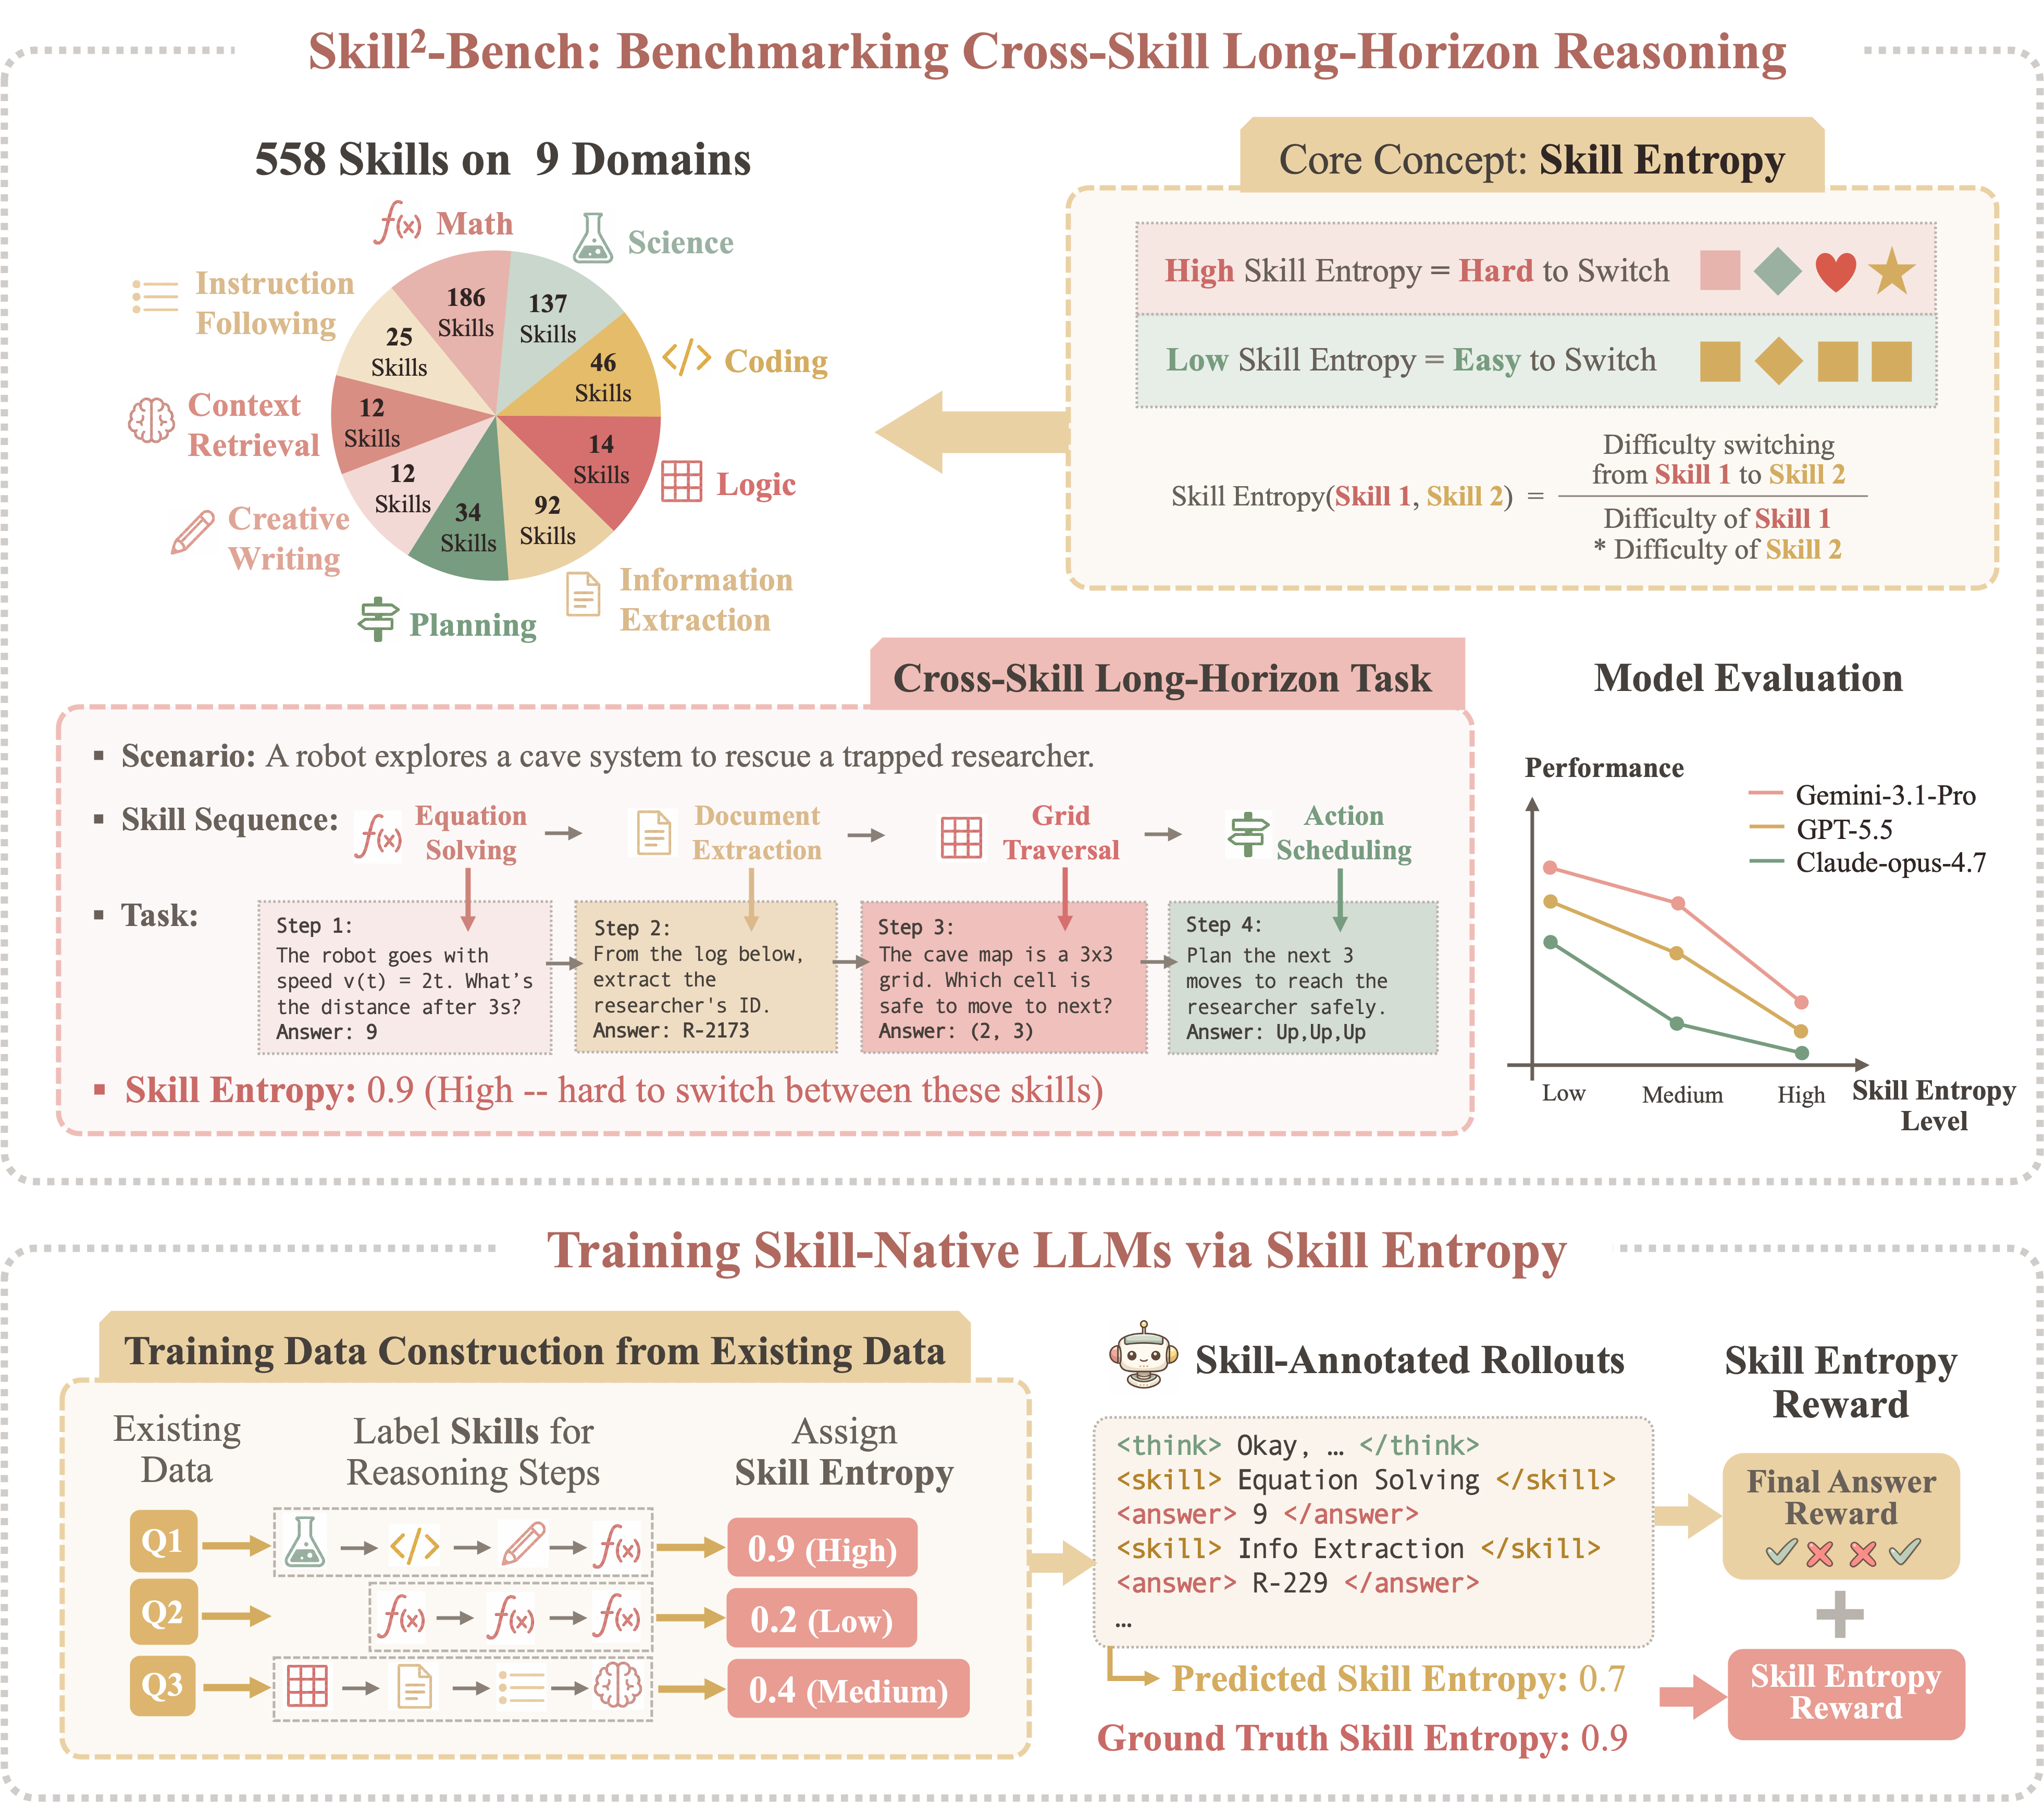
Long-horizon tasks require models to switch between skills, not just execute a single skill well. This repository contains the full pipeline behind the paper:
Python ≥ 3.10, CUDA 12.x, PyTorch 2.8 recommended.
# core trainer (installs verl fork + dependencies)
cd skill_entropy_rl && pip install -e . && cd ..

# eval extras
pip install antlr4-python3-runtime==4.11.1 word2number timeout-decorator
Every script resolves the repo location from one environment variable:
export SKILL_ENTROPY_RL_ROOT=/path/to/this/repo
mkdir -p $SKILL_ENTROPY_RL_ROOT/job_log   # SLURM launchers write their logs here (gitignored)
bash label_skills/label_skills.sh                # skill labeling (vLLM)
bash label_skills/deduplicate_skills.sh          # merge + dedupe labels → label_skills/merged_skill_labels/
cd calculate_skill_entropy && bash run.sh       # reference-model calibration → entropy map
bash propose_tasks/propose_tasks_api.sh          # benchmark tasks (API proposer — produced skill2_bench/)
sbatch propose_tasks/propose_tasks.sh            # math RL task pool (vLLM proposer → propose_tasks/math/)
sbatch sft/sft.sh                                # cross-skill SFT (sft_math.sh for math-only)
# regenerate SFT traces from a task pool: sft/generate_skillrl_sft.sh / generate_skillrl_sft_math.sh
# builds train/val parquets, then launches training
sbatch skill_entropy_rl/examples/grpo_trainer/run_skill_entropy_rl.sh           # Skill-Entropy RL
sbatch skill_entropy_rl/examples/grpo_trainer/run_skill_entropy_rl_math.sh      # math RL (needs a stage-2 math pool in propose_tasks/math/)
# chained multi-day runs: skill_entropy_rl/examples/grpo_trainer/launch_chain.sh
Reward variants (e.g. gated / multi-gold r_ent) are selected with +env.reward_mode=<mode> and implemented in skill_entropy_rl/agent_system/environments/env_package/skill2_bench/reward_variants.py.
bash  scripts/merge_checkpoint.sh                  # first: merge a sharded RL checkpoint to HF format
sbatch evaluation/eval_checkpoint.sh               # Skill²-Bench eval of a checkpoint (vLLM)
bash  evaluation/eval_api_models.sh                # Skill²-Bench eval of API models (Claude/GPT/Gemini via gateway)
@article{he2026skillnative,
  title={Toward Skill-Native LLMs: Skill Entropy for Benchmarking and Training Long-Horizon Reasoning},
  author={He, Yinghui and Yang, Ling and Liu, Jiarui and Yang, Yongjin and Zhang, Lechen and Wu, Yingcheng and Yin, Zhenfei and Wang, Mengdi and Arora, Sanjeev},
  journal={arXiv preprint arXiv:2608.05139},
  year={2026}
}
MIT (see LICENSE).
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Write HTML. Render video. Built for agents.
Ultra-lightweight, open-source, self-hosted personal AI agent framework in Python with WebUI, tools, memory, MCP, multi-agent workflows, automation, and chat apps

SkillOpt is a text-space optimizer that trains reusable natural-language skills for frozen LLM agents through trajectory-driven edits, validation-gated updates, and deployable best_skill.md artifacts.

Omnigent is an open-source AI agent framework and meta-harness: orchestrate Claude Code, Codex, Cursor, Pi, and custom agents — swap harnesses without rewriting, enforce policies and sandboxing, and collaborate in real time from any device.

A theoretical reconstruction of the Claude Mythos architecture, built from first principles using the available research literature.
🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl!