ooples/
token-optimizer-mcp

ooples/token-optimizer-mcpConnectors
Measure token savings per AI coding agent, optimize context, and share a live local knowledge graph across 16 CLI clients.
516
Measure token savings per AI coding agent, optimize context, and share a live local knowledge graph across 16 CLI clients.

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
Cut AI token costs 95%+ on code exploration. The leading MCP server for precise, symbol-level GitHub code retrieval via tree-sitter AST. Works with Claude Code, Cursor & any MCP client. 313B+ tokens saved.

CLI proxy that reduces LLM token consumption by 60-90% on common dev commands. Single Rust binary, zero dependencies

High-performance code-intelligence engine for AI agents and IDE, supports 257 languages, multi repositories, based on graph, with access via CLI, MCP Server, and API. AI coding agents teammate - expose only needed information, cutting token usage up to 50x. 100% local. Discord: https://discord.gg/39MFHu3J5d

Multi-model orchestration subagents for Claude Code — delegates by task scope to Gemini's 1M-token context or GPT's fast iteration, then routes every result back through Claude review.
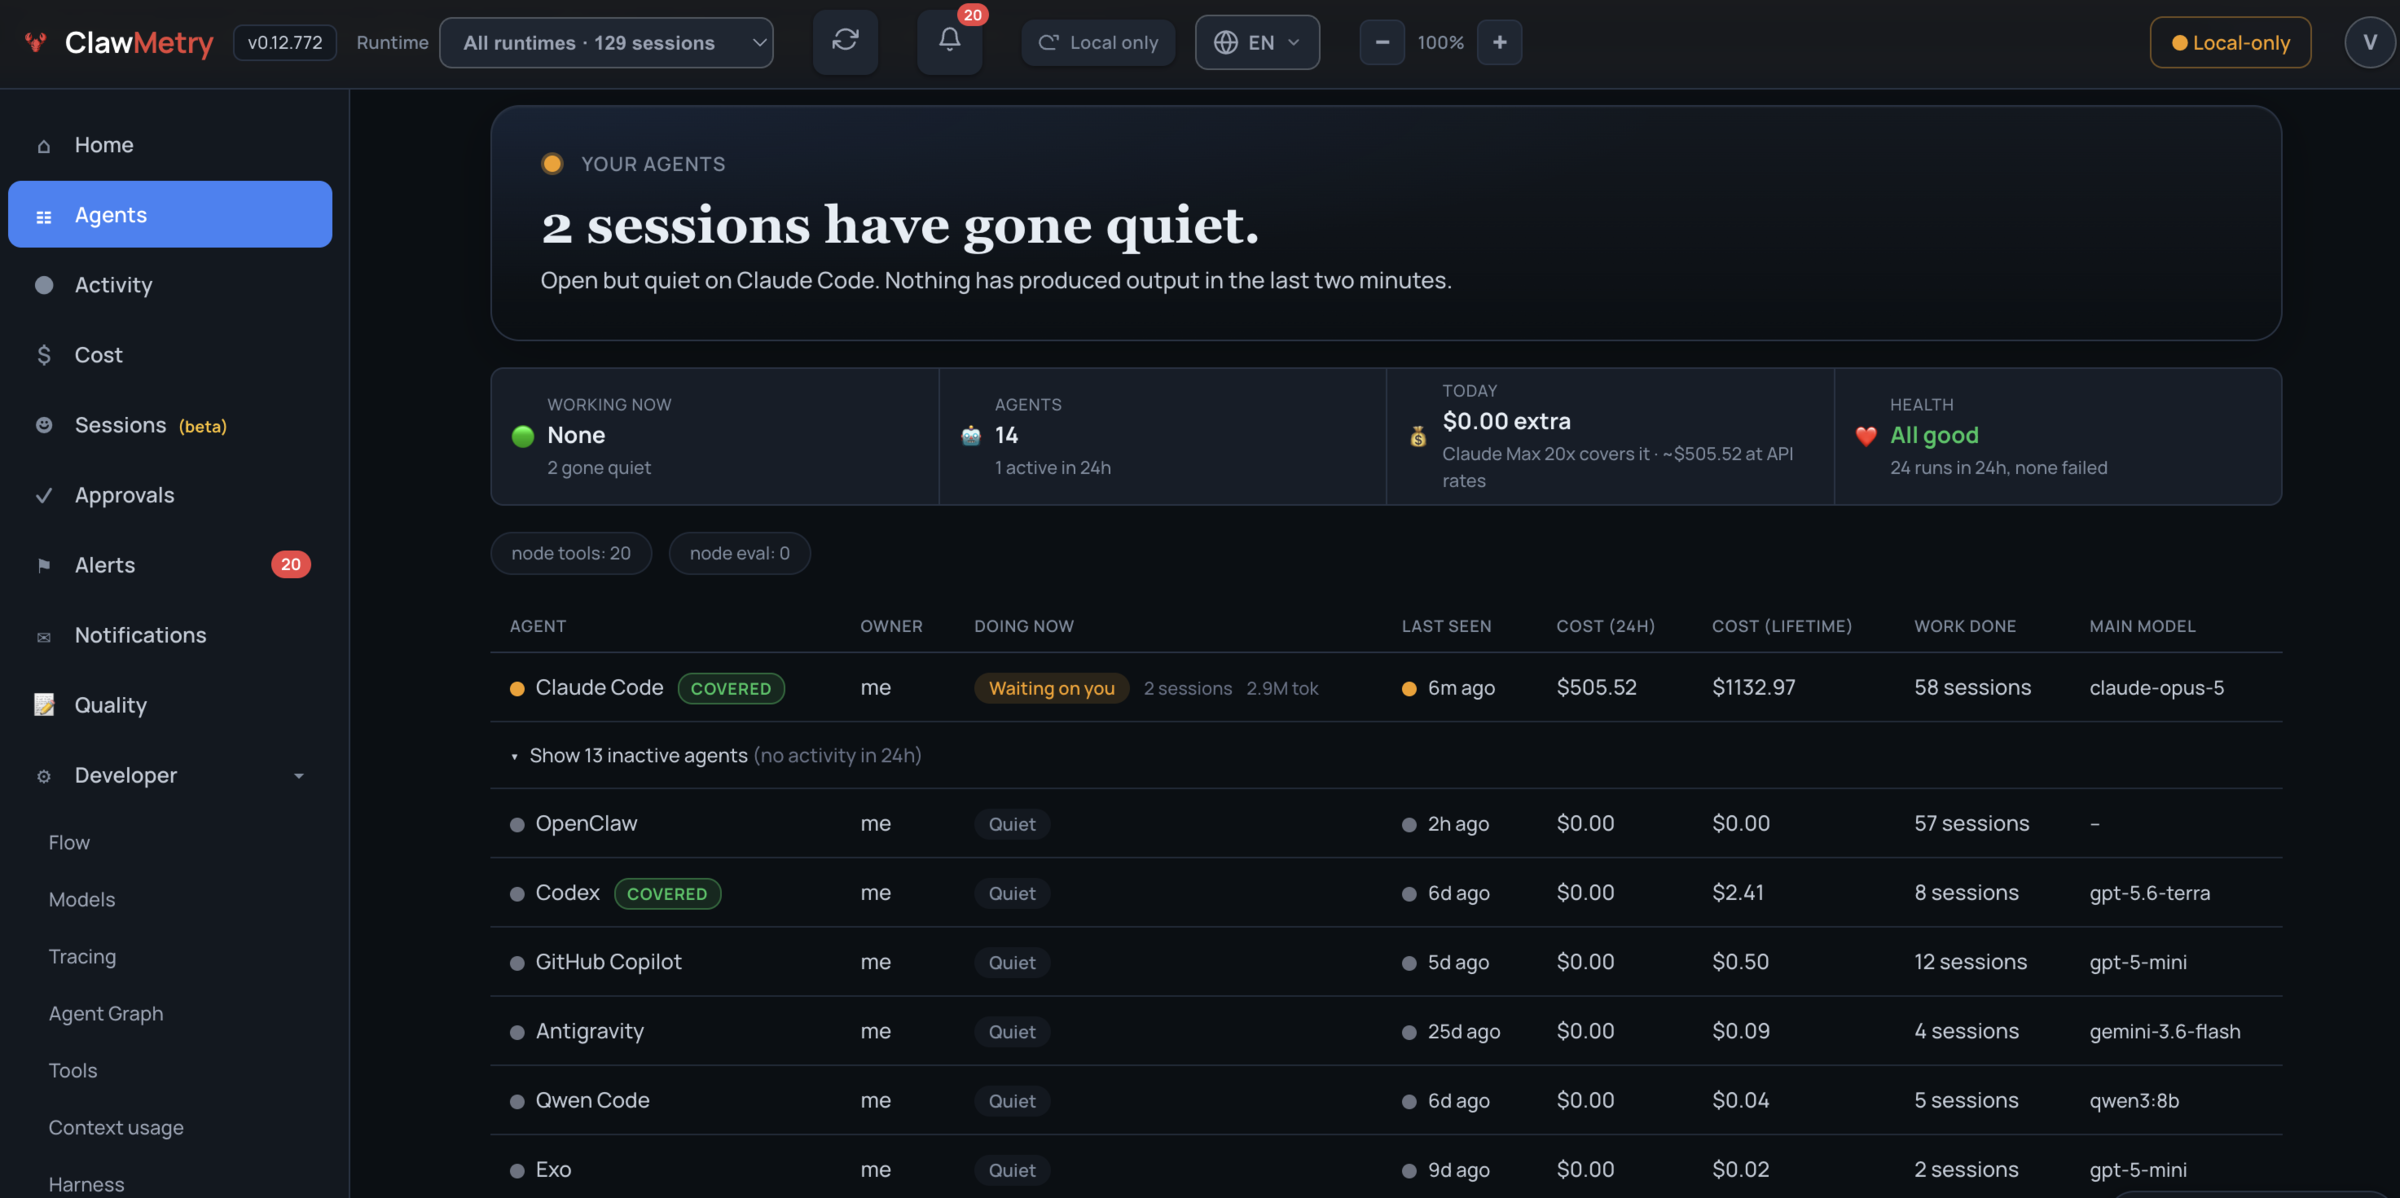
See your agent think. Zero-config observability & governance for 30 AI agent runtimes: Claude Code, OpenAI Codex, Hermes, OpenClaw & 26 more. Live token costs, sessions, tool calls, crons.

LeanCTX — Context Intelligence for AI systems.

Enterprise-grade (40m+ LOC) codebase intelligence, zero-setup, local & private Plugin/Skill/Extension or MCP: hybrid semantic search, polyglot dependency graphs, symbol-level impact analysis & call-flow, interactive HTML viewer, cross-project & branch-aware search, DB/API/infra knowledge. 61% less tokens, 84% fewer calls, 37x faster. Cloud in beta.

Cut AI context cost without trusting the compressor. Every reduction is reversible, byte-exact recoverable, and carries an auditable receipt. Local-first, works through proxy, MCP, SDK, or agent wrapper.