jjang-ai/vmlxTools
vMLX - Use MLX models easily - JANGQ (GGUF for MLX) - Not dependant on mlx_vlm
843
vMLX - Use MLX models easily - JANGQ (GGUF for MLX) - Not dependant on mlx_vlm

Native LLM inference server for Apple Silicon. OpenAI + Anthropic API compatible. No Python. Includes MLX Core macOS app with chat, agent mode, and tool calling.

High-performance OpenAI and Anthropic compatible LLM inference server for Apple Silicon. Native MLX, continuous batching, multimodal models, MCP tool calling, and Claude Code support.
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.

Experiment task scheduling made easy.
Install, run and deploy your own decentralized AI agent service
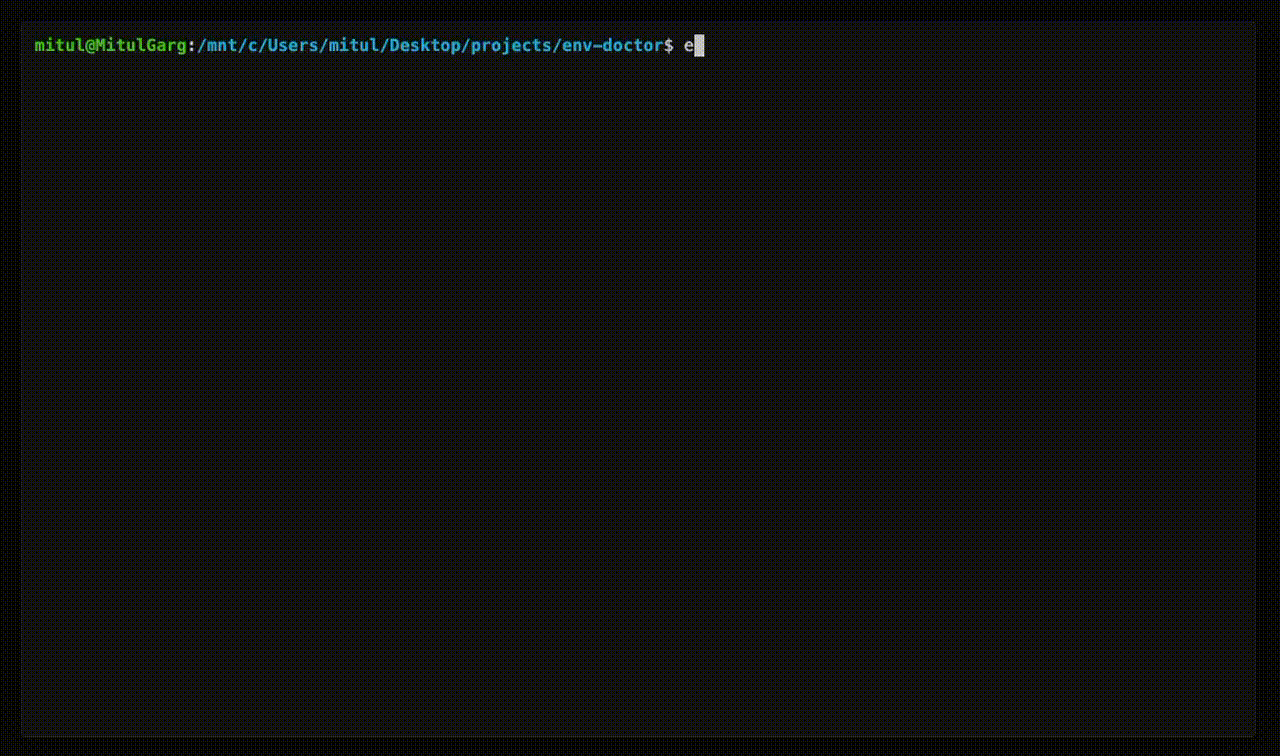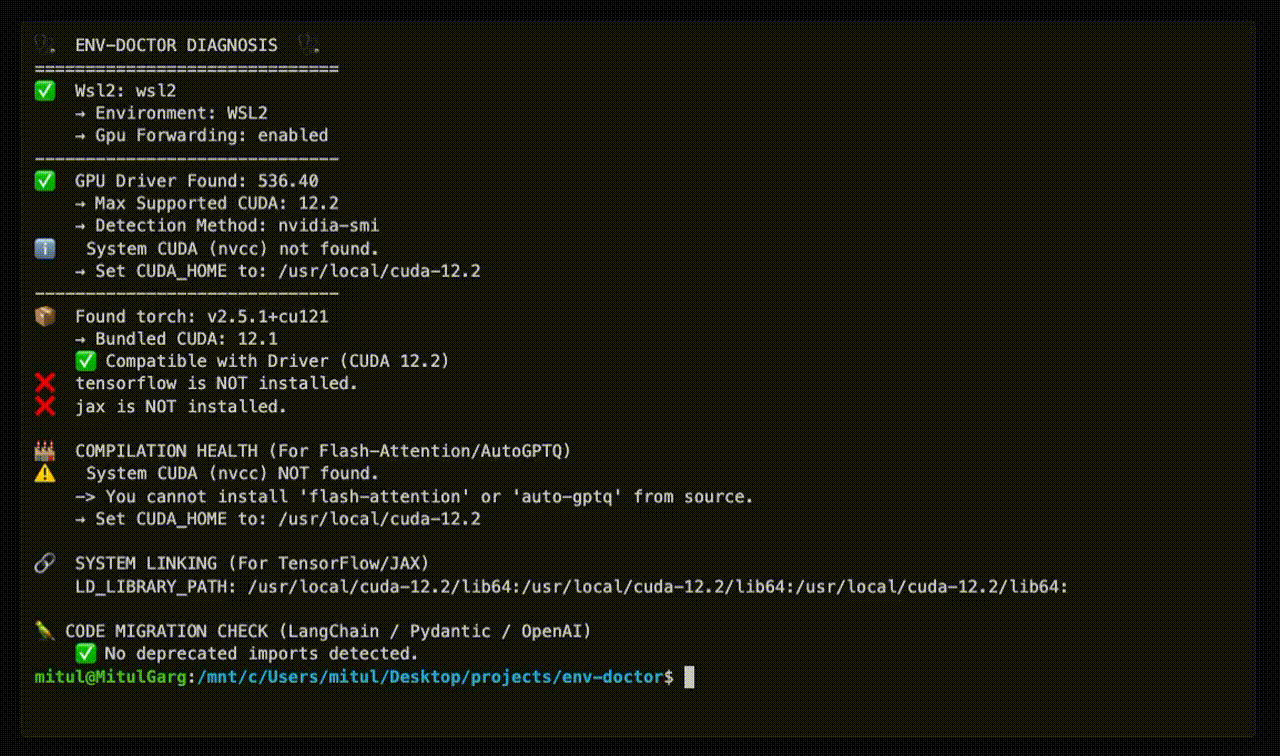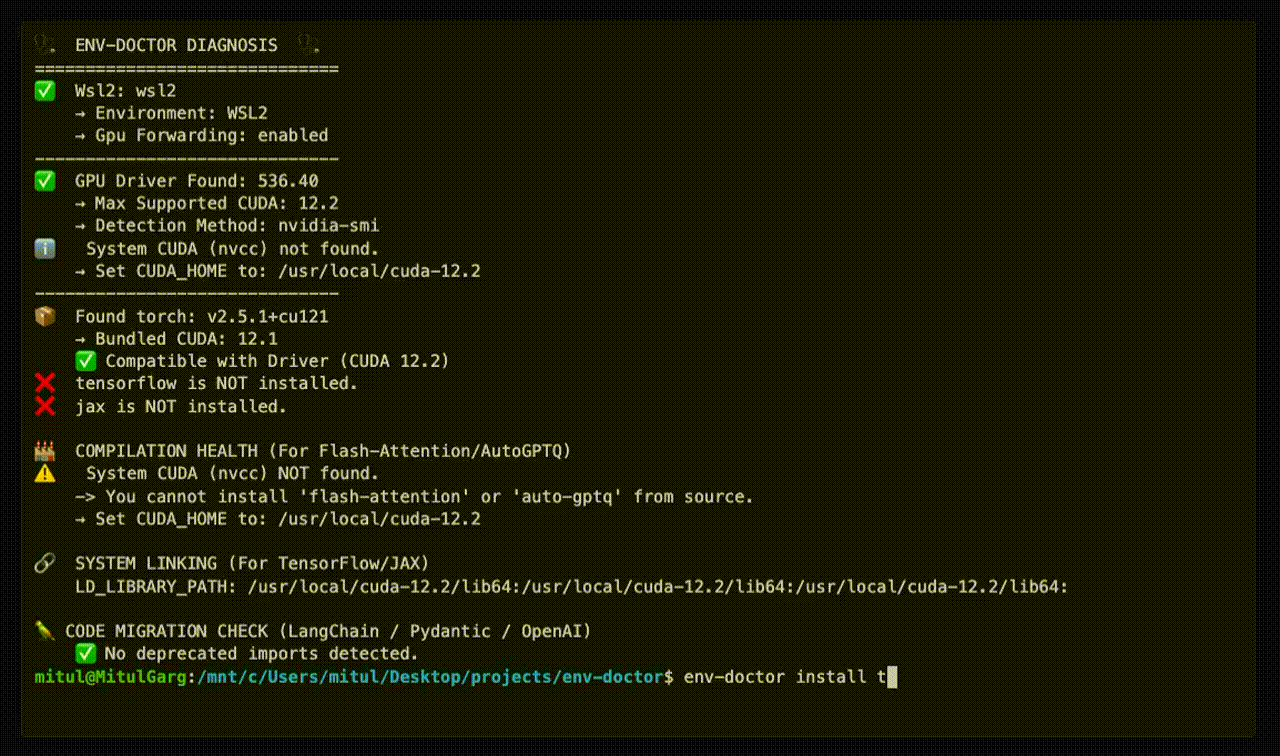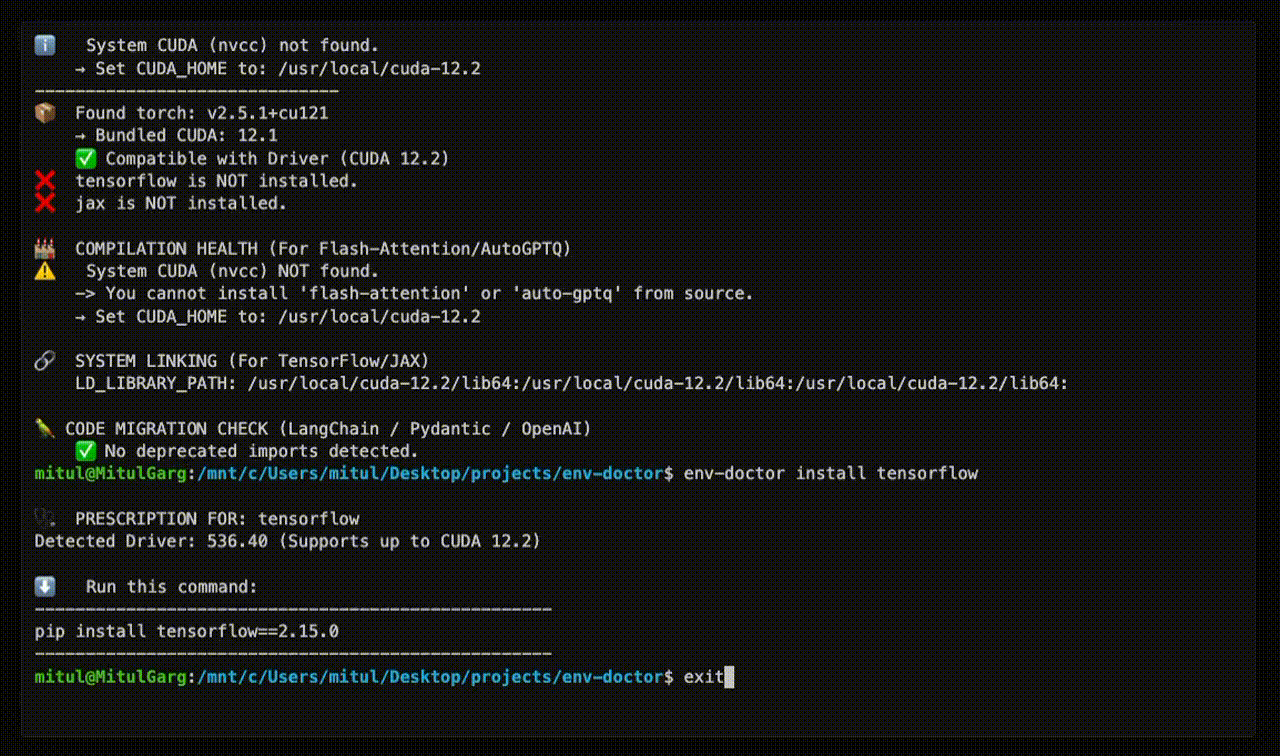
Diagnose and Fix CUDA / GPU environments compatibility issues locally, in Docker, and CI/CD. CLI + MCP server available.
Build, Evaluate, and Optimize AI Systems. Includes evals, RAG, agents, fine-tuning, synthetic data generation, dataset management, MCP, and more.