
rohitg00/ai-engineering-from-scratchTutorials & Guides
Learn it. Build it. Ship it for others.
54k
This cookbook shows how to connect an agent to Stormy’s REST API or MCP server for social data work. It gives copy-paste examples for search, profile lookup, verified email finding, and durable jobs, with the same contract across six networks.
Builders who want their agent to search social platforms, resolve profiles, and find verified emails without juggling separate APIs.
You can use one key and one tool contract to research creators and enrich leads across six social networks.
Shows how to connect Claude Code, Codex, Cursor, Windsurf, and ChatGPT-style MCP clients to `https://stormy.ai/mcp`.
Provides `curl`, Python, and TypeScript examples for `/search`, `/profile`, `/emails`, and `/jobs`.
Includes step-by-step guides for influencer discovery, outreach lists, CRM enrichment, competitor analysis, topic listening, and durable jobs.
Explains rate limits, retries, idempotency keys, top-ups, and billing by outcome.
Lists which fields and actions are available on TikTok, YouTube, Instagram, X, LinkedIn, and Reddit.
export STORMY_API_KEY="stm_live_..." # never commit this
claude mcp add --transport http stormy https://stormy.ai/mcp \
  --header "Authorization: Bearer $STORMY_API_KEY"
Name: Stormy Social Data
MCP URL: https://stormy.ai/mcp
Authentication: OAuth
Open-source, copy-pasteable recipes for the Stormy Social Data API and the Stormy MCP server (Model Context Protocol, Streamable HTTP).
One HTTP contract — search, profile, emails, jobs — across six social networks. No proxy pool, no six vendor SDKs, no scraper to babysit. Point your agent at https://stormy.ai/mcp, or curl the REST base at https://stormy.ai/api/v1.


Jump to: Recipes · MCP quickstart · REST quickstart · Endpoints · Pricing · Errors · FAQ
Every "get social data" project starts the same way: six different APIs, six auth schemes, six rate limits, six response shapes, and a scraper that breaks on a Tuesday. Then you bolt an LLM on top and discover none of it is shaped for an agent — no cost signal, no idempotency, no durable jobs, no machine-readable capability list.
Stormy is that layer, already built. This cookbook is how you use it.
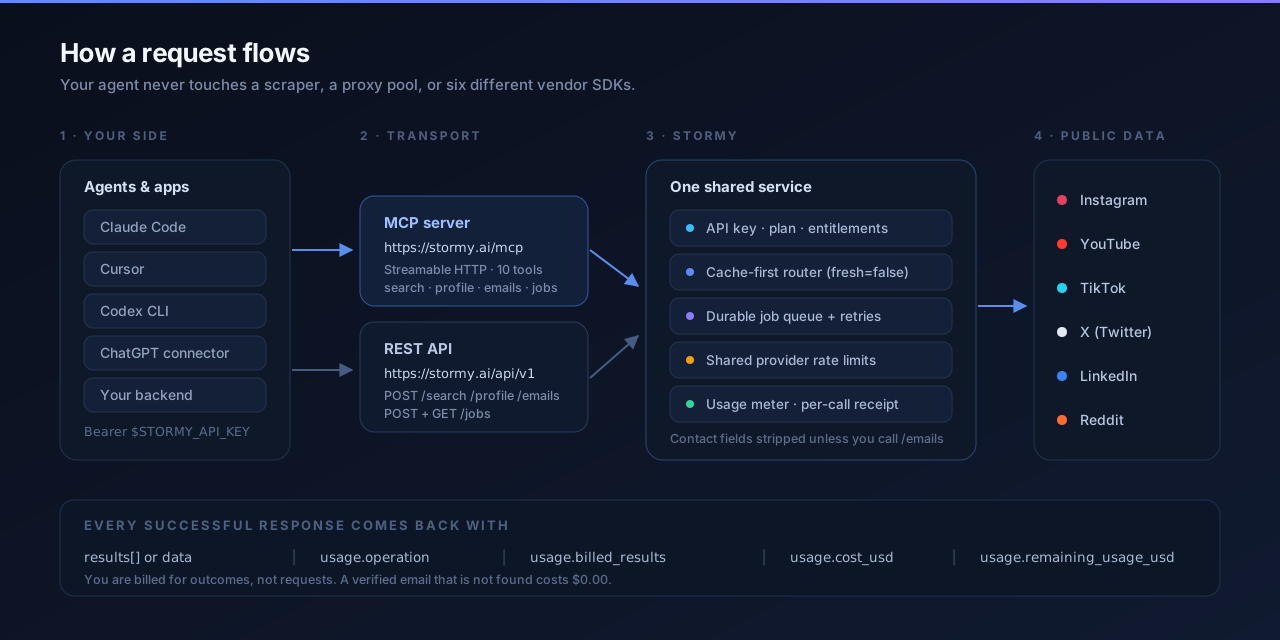
The Stormy MCP server speaks Streamable HTTP at https://stormy.ai/mcp and authenticates with an HTTP bearer token. Get a key at stormy.ai/account and export it:
export STORMY_API_KEY="stm_live_..." # never commit this
claude mcp add --transport http stormy https://stormy.ai/mcp \
  --header "Authorization: Bearer $STORMY_API_KEY"
~/.codex/config.toml)[mcp_servers.stormy]
url = "https://stormy.ai/mcp"
bearer_token_env_var = "STORMY_API_KEY"
mcp.json client{
"mcpServers": {
"stormy": {
"url": "https://stormy.ai/mcp",
"headers": {
"Authorization": "Bearer ${STORMY_API_KEY}"
}
}
}
}
Name: Stormy Social Data
MCP URL: https://stormy.ai/mcp
Authentication: OAuth
| Tool | What it does |
|---|---|
search_people(platform, query, limit=10, fresh=false) | Search one network from a natural-language query |
lookup_profile(target, platform=null, fresh=false, include_posts=false) | Resolve a URL / @handle / channel ID to a normalized profile |
find_emails(platform, targets) | Verified contact emails for 1–25 Instagram, TikTok or YouTube profiles |
estimate_price(quantity=100, include_email=false) | Rate card + a maximum estimate, spends nothing |
account_status() | Plan, remaining prepaid usage, top-up URL |
describe_social_data() | The machine-readable platform / field / pricing / workflow contract |
start_social_job(operation, arguments, idempotency_key, ...) | Queue fresh, bulk or email work durably |
get_social_job(job_id) | Status, progress, poll_after_seconds, result, full timeline |
list_social_jobs(status=null, limit=20) | Recover prior work instead of resubmitting |
cancel_social_job(job_id) | Cancel queued / scheduled / throttled / retrying work |
Then just ask:
Find 25 TikTok creators posting about home espresso, pull their follower counts, and tell me what it cost.
Base URL: https://stormy.ai/api/v1 (also reachable at https://api.stormy.ai/api/v1).
Auth: Authorization: Bearer <key> or X-API-Key: <key>. Never put a key in a URL, a JSON body, a prompt, or an MCP tool argument.
curl -X POST 'https://stormy.ai/api/v1/search' \
  -H "Authorization: Bearer $STORMY_API_KEY" \
  -H 'Content-Type: application/json' \
  -H 'Idempotency-Key: espresso-tiktok-2026-07' \
  -d '{
    "platform": "tiktok",
    "query": "home espresso and coffee gear creators",
    "limit": 25,
    "fresh": true
  }'
import os

import requests

response = requests.post(
    "https://stormy.ai/api/v1/search",
    headers={
        "Authorization": f"Bearer {os.environ['STORMY_API_KEY']}",
        "Idempotency-Key": "espresso-tiktok-2026-07",
    },
    json={
        "platform": "tiktok",
        "query": "home espresso and coffee gear creators",
        "limit": 25,
        "fresh": True,
    },
    timeout=90,
)
response.raise_for_status()
payload = response.json()

for creator in payload["results"]:
    print(creator["handle"], creator["follower_count"])

print("cost:", payload["usage"]["cost_usd"], "USD")
const response = await fetch("https://stormy.ai/api/v1/search", {
  method: "POST",
  headers: {
    Authorization: `Bearer ${process.env.STORMY_API_KEY}`,
    "Content-Type": "application/json",
    "Idempotency-Key": "espresso-tiktok-2026-07",
  },
  body: JSON.stringify({
    platform: "tiktok",
    query: "home espresso and coffee gear creators",
    limit: 25,
    fresh: true,
  }),
});

if (!response.ok) throw new Error(await response.text());
const { results, usage } = await response.json();
console.log(results.length, "creators for", usage.cost_usd, "USD");
{
  "ok": true,
  "platform": "tiktok",
  "query": "home espresso and coffee gear creators",
  "fresh": true,
  "results": [
    {
      "id": "6812...",
      "handle": "@homebarista",
      "nickname": "Home Barista",
      "url": "https://tiktok.com/@homebarista",
      "signature": "Espresso at home, no snobbery.",
      "verified": false,
      "follower_count": 184000,
      "following_count": 312,
      "likes_count": 4210000,
      "video_count": 612
    }
  ],
  "usage": {
    "operation": "fresh_discovery",
    "metered_results": 25,
    "billed_results": 25,
    "cost_usd": "2.00",
    "credits": 200,
    "plan": "paid",
    "remaining_usage_usd": "23.00"
  }
}
Every successful response carries a usage receipt. You are billed for outcomes, not requests.
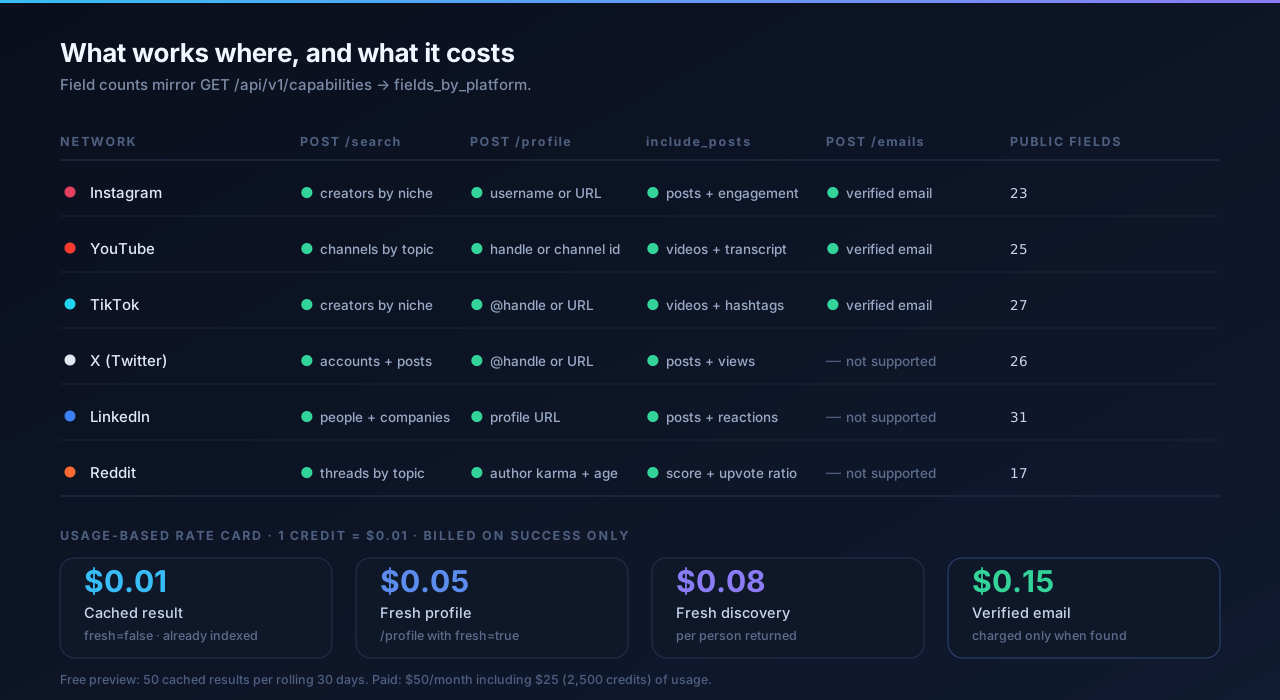
| Network | POST /search | POST /profile | include_posts | POST /emails | Public fields |
|---|---|---|---|---|---|
| TikTok API | Creators by niche | @handle or URL | Videos, views, shares, saves, music, hashtags | ✅ verified email | 27 |
| YouTube API | Channels by topic | Handle or channel ID | Videos, transcripts, captions | ✅ verified email | 25 |
| Instagram API | Creators by niche | Username or URL | Posts, captions, engagement, location | ✅ verified email | 23 |
| X (Twitter) API | Accounts and posts | @handle or URL | Posts, views, bookmarks, conversation ID | — | 26 |
| LinkedIn API | People and companies | Profile URL | Posts, reaction breakdowns, cadence | — | 31 |
| Reddit API | Threads by topic | Author karma and age | Score, upvote ratio, comment count | — | 17 |
Field lists are authoritative in GET /api/v1/capabilities → fields_by_platform. Treat every platform-specific field as nullable — you get it when it is public and the source supplied it.
TikTok — profile: id, sec_uid, handle, nickname, url, signature, avatar_url, verified, follower_count, following_count, likes_count, video_count · posts: video_id, url, description, create_time, duration, views, likes, comments, shares, saves, image_url, is_pinned, music, hashtags, caption_url
YouTube — profile: channel_id, handle, name, url, subscribers, description, videos_count, total_views, profile_image_url, banner_image_url, country, keywords, links · posts: video_id, url, title, description, published_at, duration, views, likes, comments, thumbnail_url, transcript, caption_url
Instagram — profile: username, full_name, biography, profile_pic_url, follower_count, following_count, posts_count, avg_engagement_rate, biolinks, country, is_verified, is_business_account, business_category_name · posts: media_id, post_url, caption, taken_at, like_count, comment_count, image_url, location, location_data, comments
X (Twitter) — profile: id, handle, name, url, description, profile_image_url, verified, location, website, followers, following, posts_count, joined_at · posts: id, url, text, created_at, language, likes, replies, reposts, quotes, views, bookmarks, conversation_id, author
LinkedIn — profile: id, name, linkedin_url, headline, country, country_iso_2, followers, total_posts, posts_last_6_months, posting_frequency, avg_likes, avg_comments, avg_reposts, avg_total_interactions, top_post_text, top_post_interactions, last_post_date, ai_summary, is_suitable_for_promotion, relevant_posts · posts: post_url, text, headline, posted_datetime, total_interactions, num_likes, num_comments, num_reposts, num_reactions_breakdown, poster_name, poster_linkedin_url
Reddit — profile: author, author_url, karma, account_created_at · posts: id, url, permalink, subreddit, author, title, text, created_at, score, upvote_ratio, comments_count, is_self, over_18
Every recipe is a single runnable markdown file with real code and a real cost estimate. Full index with difficulty and pricing: recipes/README.md.
| # | Recipe | Networks | What you get |
|---|---|---|---|
| 01 | Find influencers by niche | TikTok, YouTube, Instagram | A ranked shortlist of creators with follower counts and engagement |
| 02 | Build an outreach list with verified emails | TikTok, YouTube, Instagram | Search → filter → /emails → CSV, paying only for hits |
| 03 | Enrich a CRM from handles | All six | Handles in, normalized profile rows out |
| 04 | Competitor content analysis | TikTok, YouTube, Instagram | Which of a rival's posts actually worked, and why |
| 05 | Monitor a creator over time | Any | A daily snapshot job and a growth delta |
| 06 | Cross-platform audience research | All six | One query fanned out across six networks, merged |
| 07 | Reddit topic listening | Reddit, X | Which threads are moving on a topic you care about |
| 08 | Durable jobs for large collections | All six | 1,000+ results without holding an HTTP connection |
| 09 | Use Stormy from an MCP agent | All six | Prompts + tool policy for Claude Code, Cursor, Codex |
| 10 | Handle errors, rate limits and billing | — | 402 / 429 / 503 handling, headless top-up, idempotency |
| Method | Path | Body | Notes |
|---|---|---|---|
POST | /search | platform, query, limit (1–100, default 10), fresh (default false) | Cache-first. fresh=true calls a live provider |
POST | /profile | target, platform?, fresh, include_posts | Returns data, not results. platform is optional when target is a URL |
POST | /emails | platform (instagram | tiktok | youtube), targets (1–25) | The only endpoint that returns contact data |
POST | /jobs | operation, arguments, delay_seconds (0–604800), priority (−10…10), max_attempts (1–10) | 202 Accepted. operation ∈ search_people, lookup_profile, find_emails |
GET | /jobs/{job_id} | ?include_events=true | Status, progress and the event timeline |
GET | /jobs | ?status=running&limit=20 | List recent jobs |
DELETE | /jobs/{job_id} | — | Cancel non-terminal work |
| Method | Path | Notes |
|---|---|---|
GET | /pricing?quantity=100&include_email=true | Authoritative rate card + a maximum estimate |
GET | /capabilities | Platforms, per-platform fields, endpoints, job statuses, agent policy |
GET | /account | Plan, usage_balance, scopes, top-up URL |
POST | /account/top-up | amount_usd, note? → an instant Stripe checkout_url |
GET POST DELETE | /keys, /keys/{id} | List, mint and revoke API keys |
Legacy aliases /social/search, /social/profile and /social/emails still work; new clients should use the short paths.
Send an Idempotency-Key header on any paid call. Retrying with the same key never duplicates work or charges.
| Resource | URL |
|---|---|
| Capabilities JSON | https://stormy.ai/api/v1/capabilities |
| OpenAPI | https://stormy.ai/openapi.json |
llms.txt | https://stormy.ai/llms.txt |
| Human docs | https://stormy.ai/docs |
One credit is one US cent. You are charged for successful outcomes only — a verified-email lookup that finds nothing costs $0.00.
| Operation | Price | When it applies |
|---|---|---|
| Cached result | $0.01 | fresh=false on /search or /profile |
| Fresh profile | $0.05 | /profile with fresh=true |
| Fresh discovery | $0.08 | Per matching person returned by /search with fresh=true |
| Verified email | $0.15 | Per email actually found by /emails |
Worked examples (straight from GET /pricing):
| Workload | Cost |
|---|---|
| 100 cached profiles | $1.00 |
| 100 fresh profiles | $5.00 |
| 100 fresh matching people | $8.00 |
| 100 verified emails | $15.00 |
| 100 fresh people + their verified emails | $23.00 |
Ask before you spend — estimate_price / GET /pricing is free:
curl 'https://stormy.ai/api/v1/pricing?quantity=250&include_email=true'
| Status | Code | What to do |
|---|---|---|
400 | invalid_request | Fix the body. Unsupported platform, empty query, limit out of 1–100, more than 25 email targets |
401 | invalid_token | Key missing, expired, revoked or wrong |
402 | upgrade_required | Return the upgrade_url to the user |
402 | insufficient_balance | POST /account/top-up with error.recommended_topup_usd, hand back checkout_url, poll GET /account, retry |
404 | job_not_found | Job missing or owned by another account |
429 | rate_limit | Wait Retry-After seconds. Do not retry immediately |
429 | provider cooldown | The shared upstream pool is cooling down — switch to a durable job |
503 | provider_not_configured | Our deployment problem, not your request. Retry later |
Durable jobs never fail on a rate limit: they move to throttled without consuming an attempt and resume after the cooldown. Job statuses are queued, scheduled, running, throttled, retrying, succeeded, failed, cancelled. Poll only after poll_after_seconds, and stop when terminal is true.
Full worked handling in recipe 10.
search and profile responses have email, business_email, contact_email, phone and phone_number recursively stripped at the API boundary. This is enforced server-side, not by convention.POST /emails is the only path to contact data, it is opt-in, it is limited to Instagram / TikTok / YouTube, and it is billed only when a verified email is found.Yes — POST /api/v1/search with "platform": "tiktok", or the search_people MCP tool. You get creator search by niche, @handle → profile resolution, videos with views/likes/shares/saves/music/hashtags, and verified email enrichment. See recipe 01.
Yes. platform: "linkedin" on /search and /profile returns headline, follower count, posting frequency, average likes/comments/reposts, top post and an AI summary; include_posts adds posts with a full reaction breakdown. LinkedIn does not support /emails.
platform: "reddit" searches threads across subreddits and returns score, upvote_ratio, comments_count, permalink and author karma. See recipe 07.
Instagram, TikTok and YouTube. 1–25 targets per call. $0.15 per email actually found; misses are free. X, LinkedIn and Reddit are search/profile only.
No. One STORMY_API_KEY covers Instagram, YouTube, TikTok, X, LinkedIn and Reddit over both REST and MCP, with one rate card, one usage balance and one receipt format.
None, functionally — they are two faces of the same service, entitlements and rate card. MCP is for agents that discover tools at runtime; REST is for your own code. Mix them freely; a job started over REST is visible over MCP and vice versa.
Send a stable Idempotency-Key header (REST) or idempotency_key argument (MCP jobs) derived from the user's intent. Replaying the same key returns the original result and the original charge.
Recipes, fixes and new language ports are welcome. Read CONTRIBUTING.md — the short version: one recipe per file, every snippet must run, no invented parameters, and never commit a key.
MIT. The recipes are yours to lift into production.
Built by Stormy · docs · capabilities · founders@stormy.ai
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Learn it. Build it. Ship it for others.

Bash is all you need - A nano claude code–like 「agent harness」, built from 0 to 1

A visual, example-driven guide to Claude Code — from basic concepts to advanced agents, with copy-paste templates that bring immediate value.

Specification and documentation for Agent Skills
💻 vibe coding 101|The first course for AI-native product builders.
End-to-end, code-first tutorials for building production-grade GenAI agents. From prototype to enterprise deployment.