
JuliusBrussee/
caveman

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
105k
1 add
Skillreaper reads your existing session transcripts and local config to find skills, MCP servers, hooks, and subagents that load but never fire. It reports utilization, explains verdicts, and can quarantine or mute dead items with reversible commands.
Builders who want their agent stack to load less dead context and make better use of the context window.
You can remove unused agent baggage with evidence instead of guesswork, then restore it if you change your mind.
`reap` reports which skills, MCP servers, and agents loaded in the last window, how often they fired, and how much token weight they carry.
`reap why <name>` shows the evidence behind a REAP, MUTE, KEEP, or REVIEW decision before you prune anything.
`reap prune` moves dead items into a `reaped/` quarantine, and `reap restore --all` brings them back.
`reap mute <name>` strips a large description while keeping the skill callable, with `reap unmute` to restore it.
`reap install-hook` adds a Claude Code SessionStart hook that warns when new prune candidates appear.
`reap snapshot` and `reap diff` let you track what changed, including items that come back after being pruned.
`reap route` suggests lazy-load routing for large skill libraries, and `reap apm` emits a proposed `apm.yml`.
/plugin marketplace add thousandflowers/skillreaper
/plugin install skillreaper@skillreaper
# macOS — Homebrew
brew install thousandflowers/tap/skillreaper

# Any platform — npm (downloads the matching prebuilt, checksum-verified)
npm install -g skillreaper

# Any platform — Go (Go ≥ 1.24)
go install github.com/thousandflowers/skillreaper/cmd/reap@latest
Just cut ~22.8k tokens/session of dead context from my AI agent with skillreaper.
One read-only command, 100% local:

  brew install thousandflowers/tap/skillreaper
  github.com/thousandflowers/skillreaper
reap install-hook
skillreaper: 3 skills flagged for pruning since last check. Run reap to review.
S           K           I          L          L
######  #######   ###   ######  ####### ######
##   ## ##       ## ##  ##   ## ##      ##   ##
######  #####   ####### ######  #####   ######
##  ##  ##      ##   ## ##      ##      ##  ##
##   ## ####### ##   ## ##      ####### ##   ##

a generated sample stack, not a real install - run reap for your own numbers

skillreaper · last 30d · 34 sessions
7/378 items fired · 1% utilization
371 never fired · 371 marked REAP · ~22720 dead tokens/session

TOKENS  CATEGORY  NAME                 VERDICT  REASON
185     skill     import-timesheet     REAP     unused
185     skill     render-playlist      REAP     unused
177     skill     review-sitemap       REAP     unused
163     skill     deploy-dataset       REAP     unused
159     skill     validate-manifest    REAP     unused
157     skill     parse-contract       REAP     unused
149     skill     extract-receipt      REAP     unused
145     skill     sync-changelog       REAP     unused
111     skill     summarise-timesheet  REAP     unused
110     skill     export-timesheet     REAP     unused
(361 more marked REAP not shown — use --json for all)

To prune: reap prune   (interactive, reversible via reap restore --all)

1 warning — some evidence was incomplete; those items were held back from a REAP verdict.

measured by skillreaper · github.com/thousandflowers/skillreaper
Real reap --agent output, run against a generated sample stack
(hero-fixture.sh) - not anyone's
install. The numbers further down are measured on mine.
skillreaper finds the unused skills, MCP servers, subagents, hooks and
always-loaded prose quietly filling your context window - proven
from your own session transcripts - and prunes them reversibly.
Runs locally against transcripts you already have. Nothing is ever uploaded.


npx skillreaper
On my own installation, measured 2026-08-23: 382 items loaded, 13 ever fired - 3% utilization. That's ~19,755 dead tokens re-sent in every single session, ~1087k a month of pure token waste, paid for on every request before you type anything.
Measured 2026-08-23 on my own installation; raw output in docs/measurements/. Every "on my own installation" figure on this page comes from that one run.
One command. Zero config. It reads your real session transcripts, finds every skill / MCP / agent your AI loads but never fires, and shows you exactly what it costs you.
skillreaper is a measuring instrument for your agent's context window. Pruning is one of the things you do with the measurement, not the point of it. The whole surface, in the order you use it:
| Stage | Command | What it answers |
|---|---|---|
| Measure | reap | What do I load, what actually fires, what does the dead part cost per session? |
reap gap | What share of each category is ever used, and which MCP tools fire but return noise? | |
reap by-project | Which project is actually firing each skill? | |
| Decide | reap why <name> | Why did this item get this verdict, on what evidence? |
| Act | reap prune | Quarantine the dead items, reversibly |
reap mute <name> | Strip a heavy rarely-used description, keep the skill callable | |
| Engineer | reap route | Propose a lazy-load routing plan for a library too big to prune flat |
reap apm | Emit a proposed APM apm.yml, so a team reproduces one lean set | |
| Compare | reap snapshot | Keep this run, so a later one has something to be measured against |
reap diff | What appeared, left, changed verdict, and did anything come back after a prune |
Everything above the Act row is read-only. You can run the entire measurement side without changing a single file.
| Read-only, changes nothing | Writes, always reversible |
|---|---|
reap 1 | reap prune ↔ reap restore --all |
reap gap | reap mute <name> ↔ reap unmute <name> |
reap by-project | reap keep <name> ↔ reap keep --remove <name> |
reap why <name> | reap install-hook ↔ reap uninstall-hook |
reap route | |
reap apm | |
reap manifest <name> | |
reap share | |
reap snapshot 1 | |
reap diff |
Nothing is ever deleted. reap prune moves files into a reaped/
directory with a versioned manifest, reap mute keeps a backup of the
description it strips, and reap uninstall-hook removes only skillreaper's own
entry, leaving your other hooks alone. Every write is atomic (temp file +
rename) and confined to your Claude directory, so an interrupted prune,
mute, or hook edit leaves the original file intact, never a half-written mix.
1 The only files a read-only command writes are skillreaper's
own: ~/.claude/reaped/nudge-state.json, which the default report
touches so a hint it already showed you does not repeat, and the snapshot
reap snapshot exists to write. Neither touches your stack. Pass
--no-nudge (or set SKILLREAPER_NO_NUDGE=1) and not
even that happens. No command in either column sends anything over the
network.
Three commands, in this order. Only the third one writes anything, and it prints its own undo line.
reap                       # 1. measure: what you load, what fires, what it costs
reap why <name>            # 2. decide: the evidence behind one verdict
reap prune                 # 3. act: quarantine the dead ones, interactive
1. reap prints the report at the top of this page. Every row carries a
verdict:
| Label | Meaning |
|---|---|
REAP(broken) | Invoked but errored - broken, not just cold |
REAP | Zero uses - safe to quarantine |
MUTE | Used rarely + heavy - description stripped, skill stays available |
KEEP | Used, tiny, or manually protected |
REVIEW | Too new or not enough sessions |
Every verdict includes a reason suffix explaining why, and an item whose
evidence was incomplete stays REVIEW rather than being flagged.
2. reap why <name> is how you argue with a verdict before acting on it.
It shows the whole case for one item, so you are not trusting a label:
skill:import-timesheet

verdict      REAP(unused)
reason       zero uses in the evidence window
token weight ~185 tok  (description: 684 chars)
sessions     34 total in window
uses         0
last seen    never
installed    unknown
keep-list    no
claude-md    not referenced
→ safe to prune. run: reap prune
3. reap prune asks before it moves anything, quarantines what you confirm
into reaped/, and ends by printing reap restore --all. If a verdict looks
wrong, reap keep <name> protects the item permanently instead.
The why output above is real, produced
against the same generated sample stack as the report at the top of this page
(hero-fixture.sh) - so the item
names are the fixture's, not anyone's install.
I was running out of context budget on every session. I had accumulated skills, MCP servers, and agents over months most of them experiments I'd forgotten about or be too busy to change it. Every new session loaded all of them, burning tokens before I'd typed a single message.
I needed to know which ones were actually firing and which were just dead weight. Nothing existing told me that from transcript evidence. So I built it.
It now supports every platform in the table below, and ships on Homebrew, npm, and as a static binary for every major OS.
Wrong-tool picks. Buried in a wall of irrelevant options, your agent wastes turns reaching for the wrong tool. More turns = slower, costlier, sloppier runs. This isn't about pennies - it's about work quality.
Wasted tokens. Dead instructions eat context every session and hurt prompt-cache hit rate. A typical setup:
The money line is one measurement of one stack, n=1, and the
weakest number here: 19 755 × 55 × $3.00 ÷ 1e6 - input tokens only, at
claude-sonnet-4-6's $3.00/MTok default, with tokens estimated as
ceil(chars / 3.7) and the monthly session count extrapolated from a
30-day window. Change the model, the price, or how much you work and it moves;
the item and token counts do not. See Limitations.
Measured on my own setup - 55 sessions over 30 days, 2026-08-23. Run reap to see yours.
skillreaper measures both, from evidence - no guessing.
reappoints at the waste. You decide what goes.
100 % local. Zero telemetry, zero network, zero uploads. Reads config files and session transcripts on disk - your data never leaves your machine.
| Before skillreaper | After skillreaper |
|---|---|
| 382 items loaded every session | 15 kept · 13 actually fire |
| 19 755 tok/session dead | Full context budget for real work |
| ≈ 73 000 dead chars ≈ 29 pages every session (at 500 words/pg) | Zero |
| Lower cache hit rate = higher latency | Smaller prompt fits in cache |
My own installation, measured 2026-08-23.
If this looks useful → ⭐ star the repo
Inside Claude Code - adds /skillreaper:reap and /skillreaper:gap, so the
report renders in the conversation instead of a scrollback you have to re-read:
/plugin marketplace add thousandflowers/skillreaper
/plugin install skillreaper@skillreaper
The plugin is a thin wrapper: it drives the same binary, so install that too
with any line below. The skills fall back to npx skillreaper and tell you how
to install permanently if they can't find it.
Install permanently - Homebrew and npm install both names, reap and
skillreaper, so either one works. go install gives you reap:
# macOS — Homebrew
brew install thousandflowers/tap/skillreaper

# Any platform — npm (downloads the matching prebuilt, checksum-verified)
npm install -g skillreaper

# Any platform — Go (Go ≥ 1.24)
go install github.com/thousandflowers/skillreaper/cmd/reap@latest
Already installed it with Homebrew? You don't need the npm package - both put
reapandskillreaperin the same prefix, sonpm install -gstops at an EEXIST link error rather than overwriting brew's copy. Pick one route: to switch to npm, runbrew uninstall skillreaperfirst. Neither affectsnpx skillreaper, which runs from a cache and never links a global command.
Binary downloads - macOS (Intel + Apple Silicon), Linux (amd64 + arm64), Windows (amd64 + arm64) - all on the releases page. Single static binary, no dependencies.
Upgrading, uninstalling, and platform-specific tips → INSTALL.md.
💬 Curious what reap finds in other setups? Share your output →
reap                          # scan + report (read-only)
reap gap                      # loaded-vs-fired utilization + MCP payload quality
reap prune                    # quarantine REAP items (reversible)
reap mute <name>              # strip description, keep skill available
reap unmute <name>            # restore description from backup
reap unmute --all             # restore all muted skills
reap keep <name>              # protect an item from pruning
reap restore --all            # undo every prune
reap why <name>               # explain in detail why an item got its verdict
reap by-project               # skills bucketed by the project that fired them
reap route                    # propose a usage-informed lazy-load routing plan (opt-in)
reap apm                      # emit a proposed APM apm.yml from this repo's firing
reap apm --diff apm.yml       # reconcile: what to add (fired, undeclared) / drop (declared, cold)
reap share                    # print a ready-to-paste line about what you reclaimed
reap snapshot                 # save this run's --json payload for later comparison
reap diff                     # compare the newest two snapshots
reap diff <a> <b>             # compare two named snapshots
reap manifest <name>          # emit a release manifest for one skill
reap install-hook             # install weekly nudge (SessionStart hook)
reap install-hook --dry-run   # preview without writing
reap uninstall-hook           # remove hook, other hooks untouched
reap --json                   # structured JSON output
reap --md                     # markdown report
reap --days 7                 # shorter evidence window
reap --mute-threshold 0.20    # firing rate below which MUTE triggers (default 20%)
reap version                  # print version
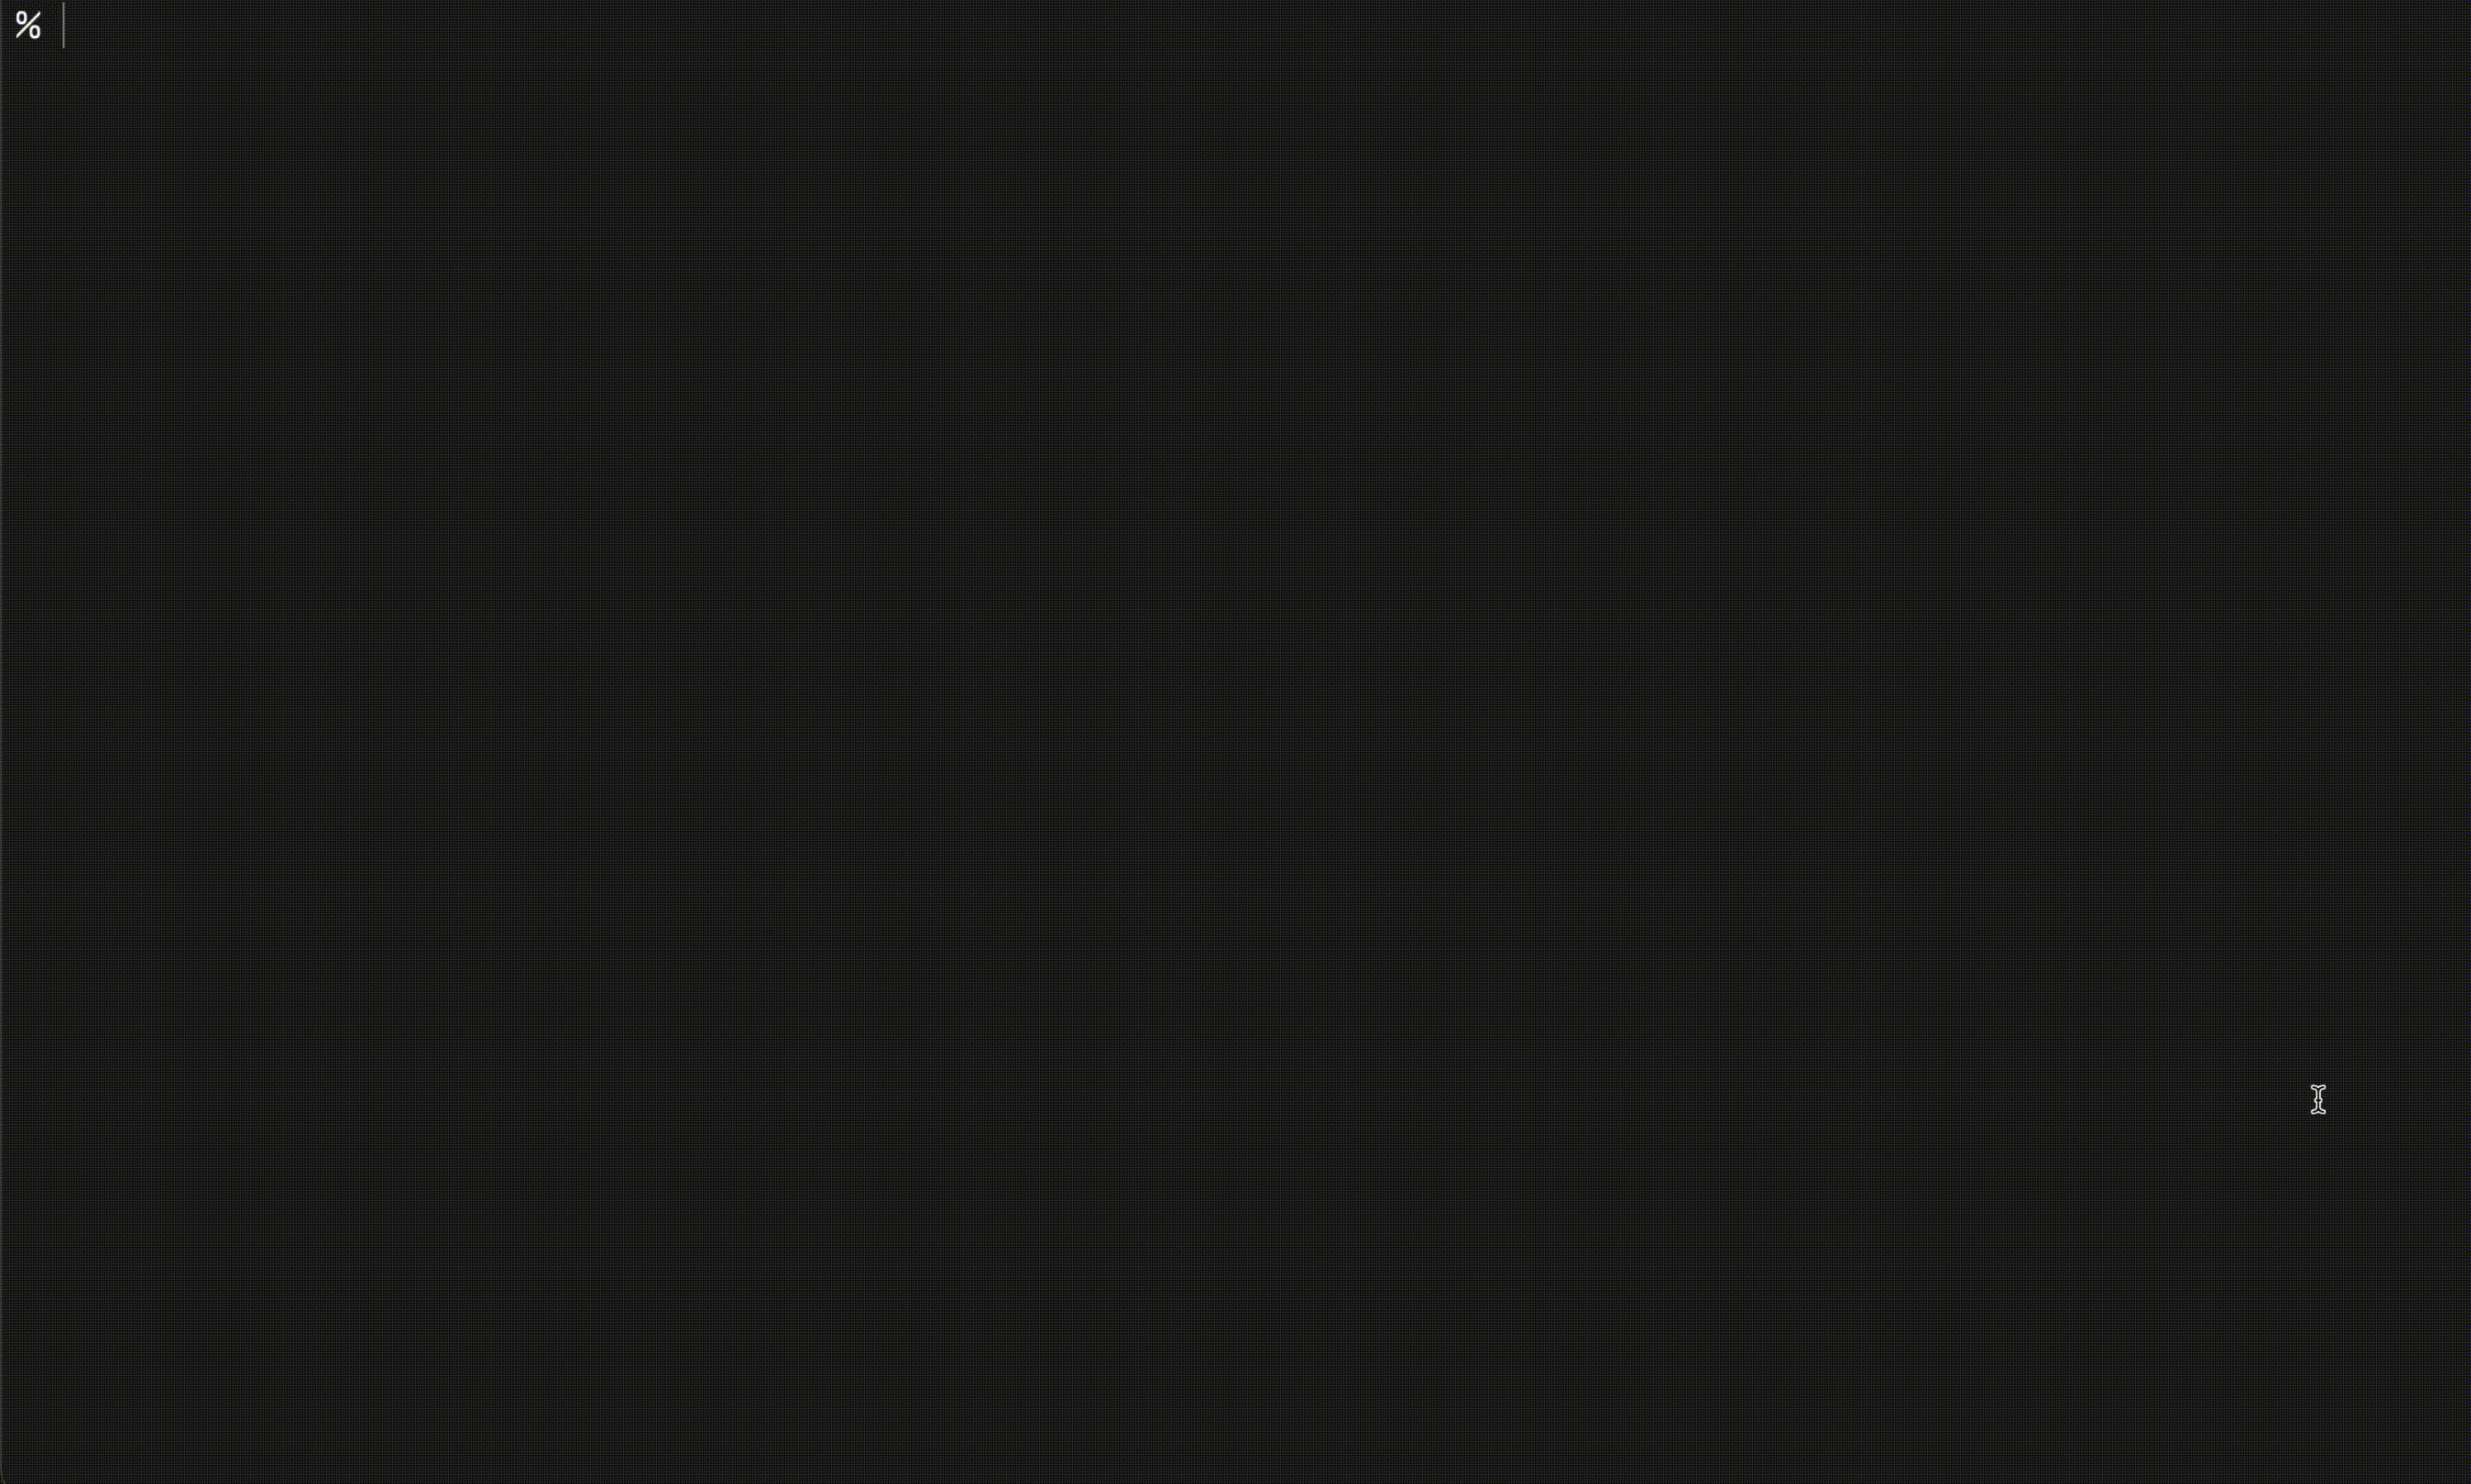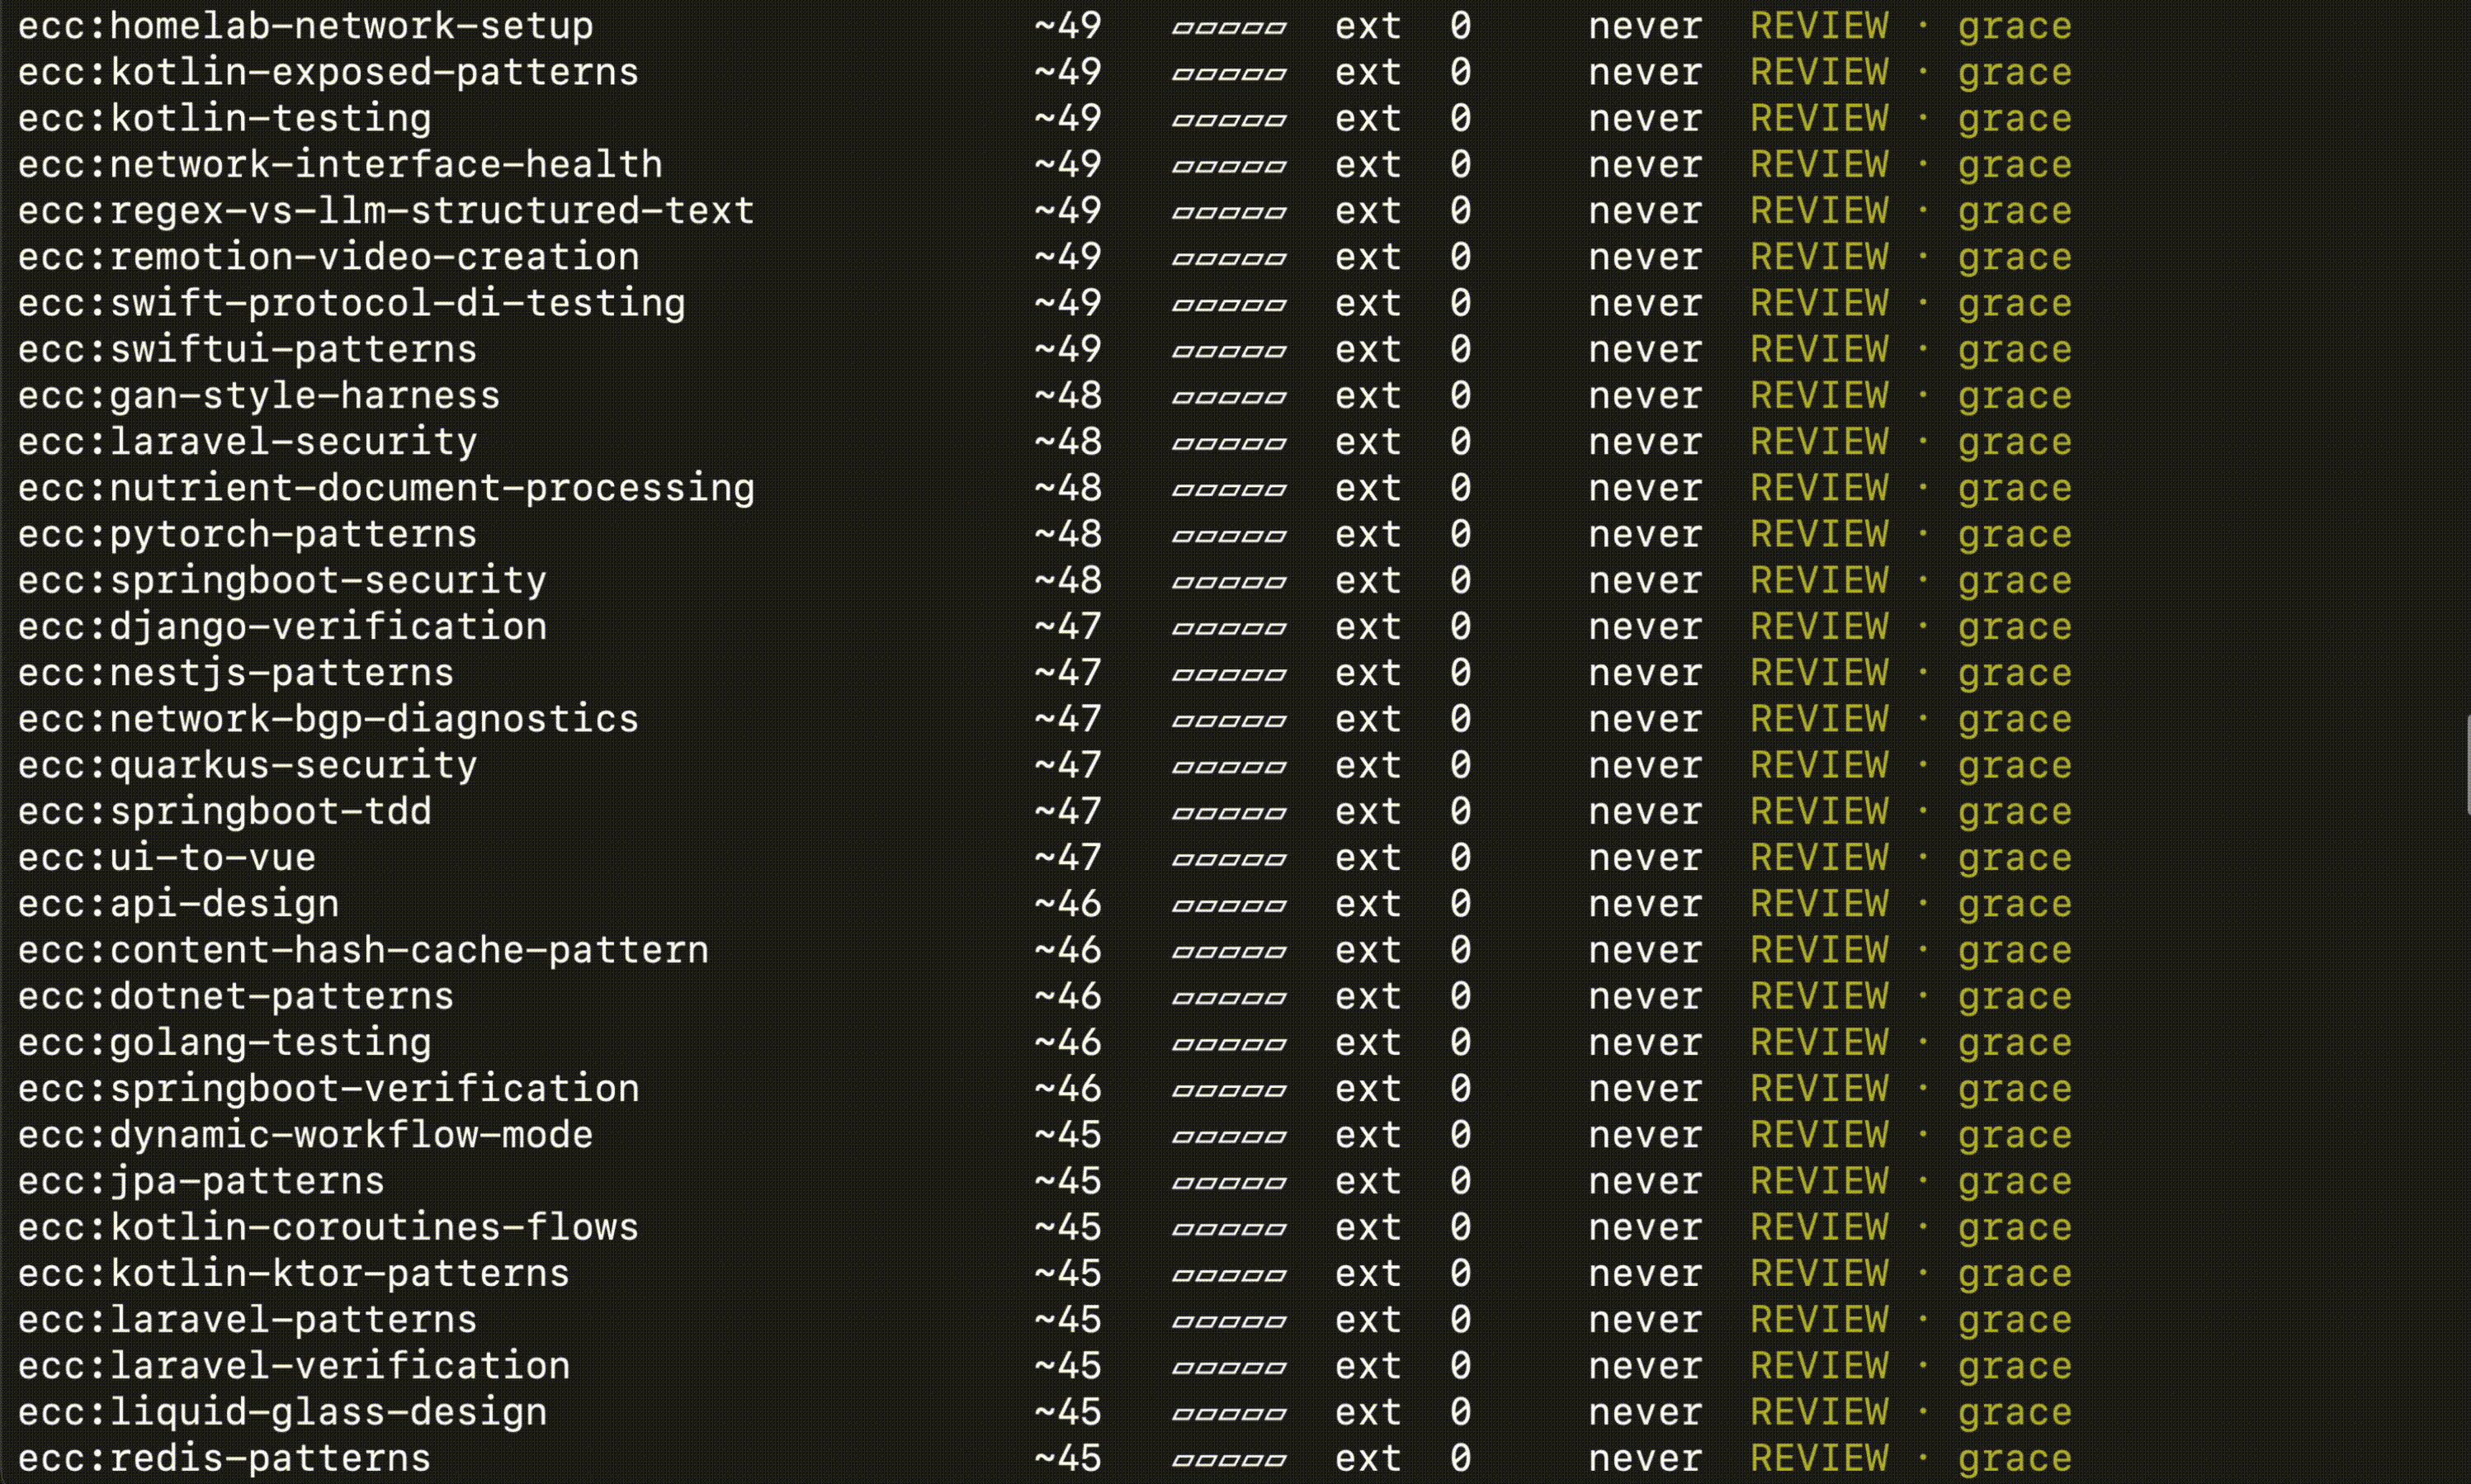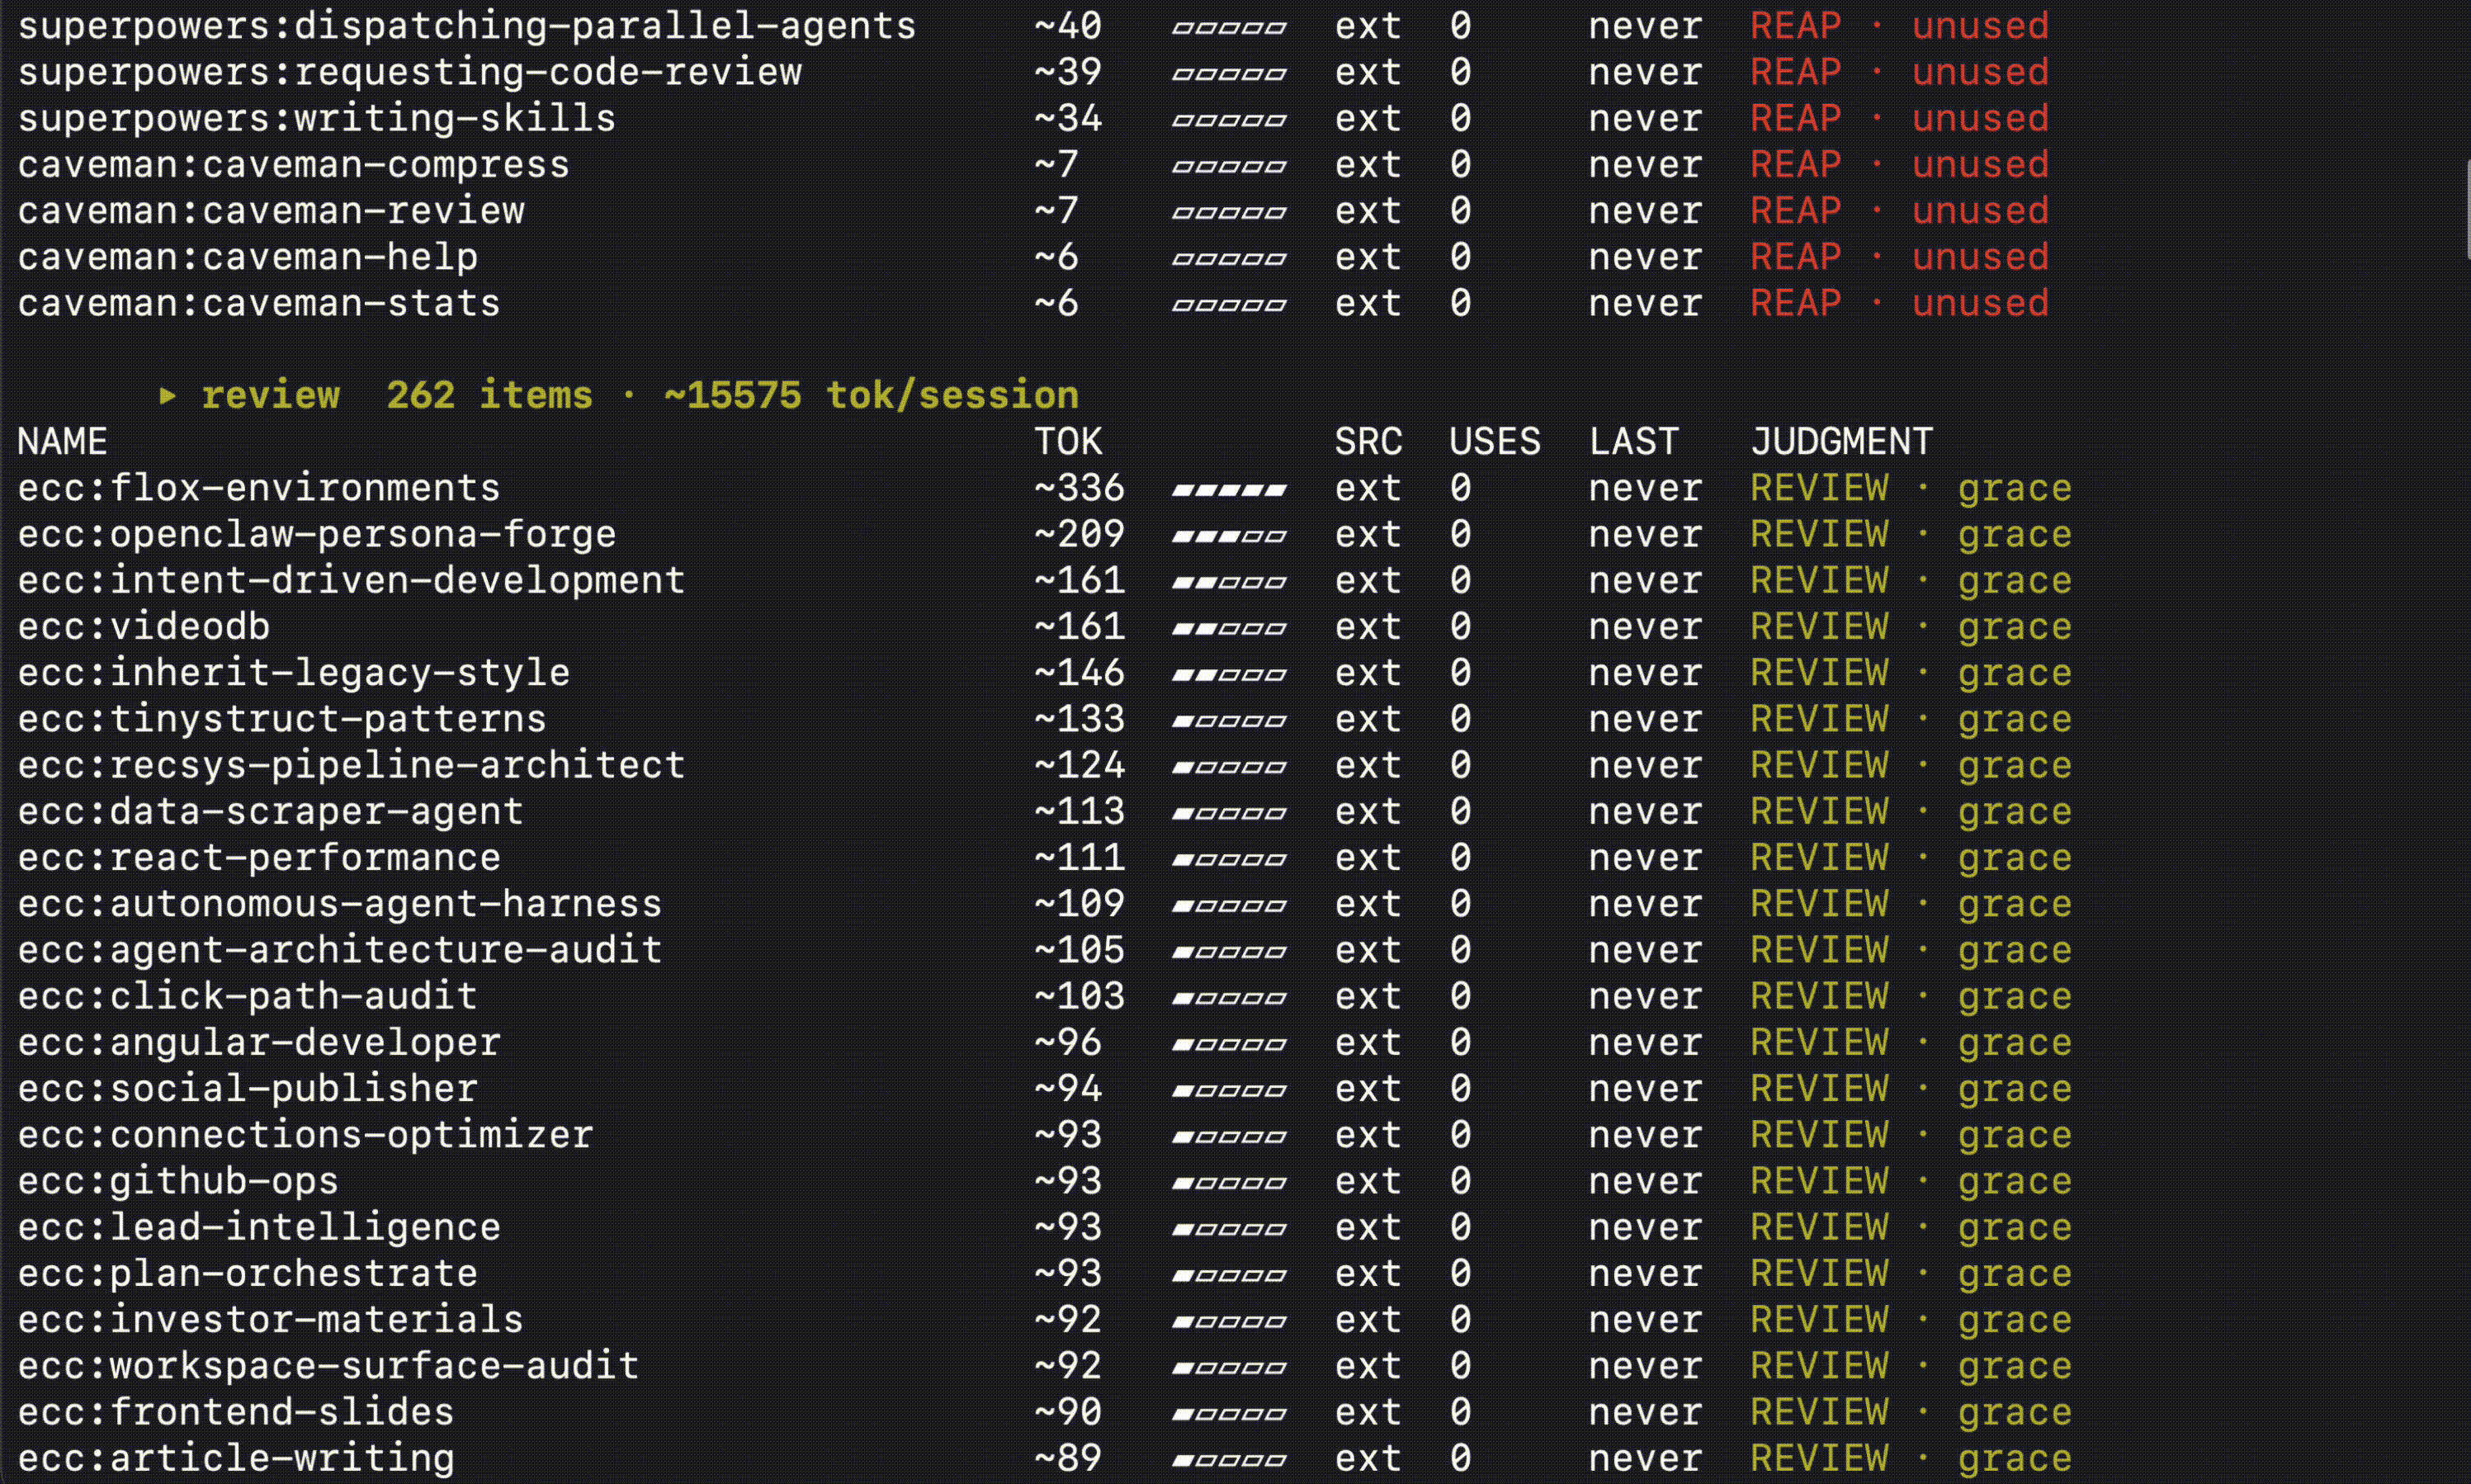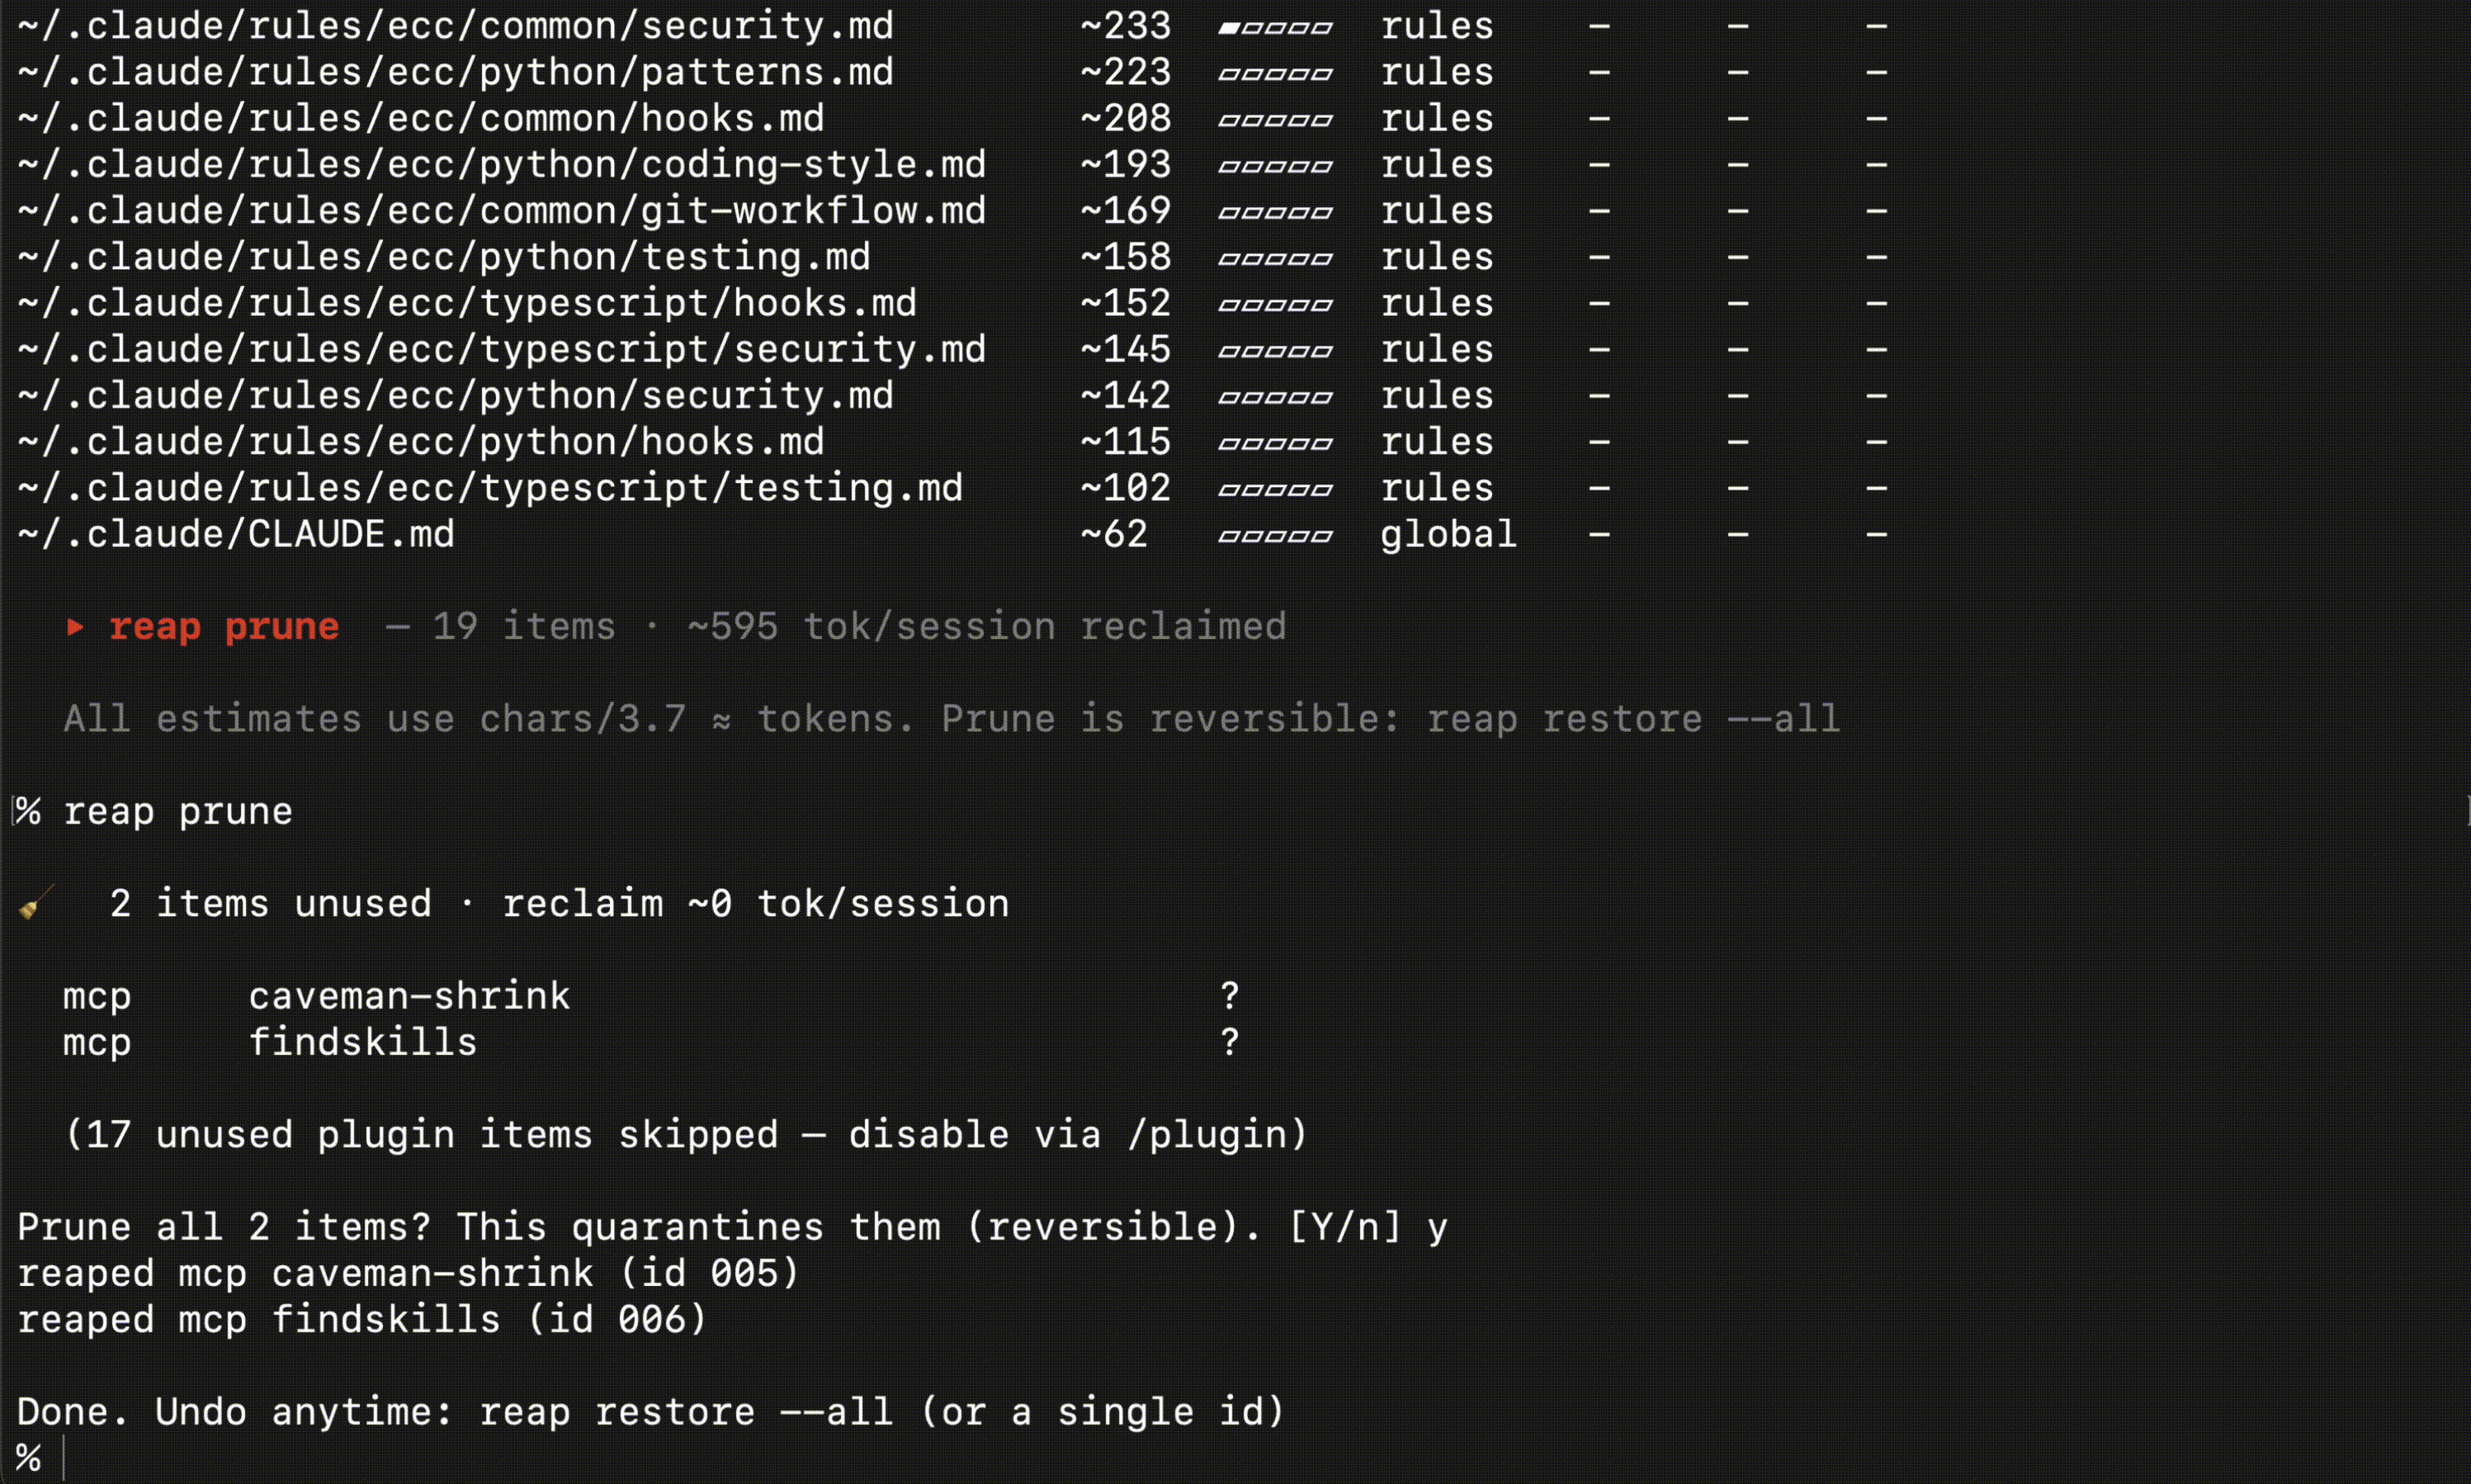
Recorded against a small sample fixture
(demo-fixture.sh), so the
numbers are the fixture's, not a real stack's.
reap share prints one line about what you reclaimed, with the install command
under it. Read-only: it measures and prints, nothing else. --json and --md
are there for anything that wants to post it automatically.
Just cut ~22.8k tokens/session of dead context from my AI agent with skillreaper.
One read-only command, 100% local:

  brew install thousandflowers/tap/skillreaper
  github.com/thousandflowers/skillreaper
Same generated sample stack as the report at the top of this page - the figure is the fixture's, not mine.
Beyond the prune verdicts, reap gap shows your utilization rate -
how much of what you load you actually use.
  ── loaded vs fired · last 30 days · 34 sessions ──────────────────────────────

  CATEGORY  LOADED  FIRED  UTIL              TOK LOADED  TOK USED
  skills       298      6    2%  ▏▱▱▱▱▱▱▱▱▱     ~21,693       278
  mcp           12      1    8%  ▏▱▱▱▱▱▱▱▱▱           ?         ?
  agents        68      0    0%  ▱▱▱▱▱▱▱▱▱▱      ~1,305         0
  ───────────────────────────────────────────────────────────────
  total        378      7    1%  ▏▱▱▱▱▱▱▱▱▱     ~22,998       278

  ~  MUTE — 2 heavy low-use skills, ~102 tok/session recoverable with reap mute
Same generated sample stack as the report at the top of this page, so the two agree. The numbers further up the page are measured on mine.
Each row breaks down by category (skill, MCP, agent) with item count, token weight, and a 10-segment utilization bar. The token column reads loaded → actually used: the left number loads every session, the right is all that is ever touched - the gap between them is dead weight that reloads each time. Low utilization (<10 %) is red, medium (<50 %) yellow, high (≥50 %) green.
The default reap report also includes a compact utilization summary line:
utilization 1% 7/378 items fired · ~278/22998 tok touched (30d)
Same generated sample stack, not my install - as with the two blocks above it.
This is the real gap between what your agent carries and what it fires - complementary to the shock box (which only counts items that are safe to prune right now).
reap gap          # text breakdown
reap gap --json   # JSON output
reap gap --md     # markdown table
The gap view also scores payload quality for MCP tools: when a tool fires,
is the result signal or noise? A fetch/screenshot tool can fire 80× and return
mostly base64 or boilerplate every call - green under load utilization, but
context burned on each call. Tools that fire often and return mostly noise are
flagged ⚑ noisy. This is the second utilization axis (load is the first), and
mute does not catch it.
A skill that looks cold across the whole window is often a skill that is alive
in exactly one repo. reap by-project buckets each fired skill by the project
that fired it, one row per skill-and-project pair, and marks a skill that fired
in exactly one project as repo-local - the case this view exists for, since a
per-repo tool should not be read as global dead weight.
  ── skills by project · last 30 days · 34 sessions ────────────────────────────

  SKILL            PROJECT        FIRINGS  NOTE
  audit-backlog    acme-platform       17  repo-local
  audit-catalog    acme-platform       11  repo-local
  audit-changelog  acme-platform        8  repo-local
  audit-contract   acme-platform        6  repo-local
  audit-dataset    acme-platform        5  repo-local
  audit-invoice    acme-platform        4  repo-local
Same generated sample stack as the blocks above. This
capture is one of the files make renders-check verifies, so it
cannot drift from what the binary prints.
reap by-project          # text table
reap by-project --json   # JSON output
After pruning, a library of hundreds of legit skills still grows resident
context linearly. reap route proposes a category-router organization driven by
real firing evidence, not text similarity: frequently-fired skills stay
exposed; the rare long tail is pushed behind leaf routers (grouped by namespace,
else dominant firing project) loaded on demand. It is strictly opt-in and
secondary to pruning - and below ~150 skills, native loading is usually enough,
so the plan says so. The output is a plan: proposed, never auto-applied.
reap route                      # text plan
reap route --json               # JSON
reap route --md                 # markdown
reap route --route-threshold 0.05   # route skills firing in <5% of sessions
reap route --route-min-skills 200   # only show a plan past 200 surviving skills
reap apm turns this repo's firing evidence into a proposed
APM apm.yml (skills only, first cut).
Read-only: it prints YAML, never edits the repo or runs apm install. KEEP →
include, REAP → omit, REVIEW → never auto-omit. Upstream coordinates are
recovered from apm.lock.yaml when present; otherwise the skill becomes a clearly
marked TODO comment rather than an invented coordinate.
reap apm                        # propose apm.yml (yaml)
reap apm --json                 # JSON
reap apm --md                   # markdown
reap apm --diff apm.yml         # reconcile: add fired-but-undeclared, drop declared-but-cold
A report is a photograph. The questions that recur are comparative: did a pruned item come back, is the bloat growing or shrinking after a prune.
reap snapshot writes the run's --json payload beside the evidence digest.
reap diff compares two of them, newest against previous by default, and
reports what appeared, what left, what changed verdict, and the movement in
dead tokens and utilization.
The case it exists to catch leads the output: an item that is back after being pruned. Plugin and marketplace updates reinstall silently, and that line is read from the prune manifest rather than guessed from the two snapshots, so it says "this tool removed it and it returned" rather than "something is different". An item you restored yourself is not reported, since that was deliberate.
reap snapshot            # save this run
reap diff                # newest vs previous
reap diff <a> <b>        # two named snapshots
reap diff --json         # structured output
Snapshots are never taken automatically. State nobody asked for is the disease
this tool treats; reap install-hook is the place to opt into a periodic one,
once diff has proved useful.
reap install-hook
Installs a SessionStart hook that runs a passive audit at the start of each
Claude Code session. If 7 days have passed and the REAP or MUTE count has grown
since the last check, it prints a single line to stderr:
skillreaper: 3 skills flagged for pruning since last check. Run reap to review.
Nothing else. No blocking. State stored at ~/.claude/reaped/nudge-state.json.
reap install-hook --dry-run prints the exact settings.json it would write
and exits without touching the file. Existing hooks and top-level keys are
merged, never replaced, and the entry carries a marker comment so
reap uninstall-hook can find and remove only its own line:
dry-run — would write /tmp/skillreaper-fixture/settings.json:
{
  "hooks": {
    "SessionStart": [
      {
        "hooks": [
          {
            "type": "command",
            "command": "'/tmp/skillreaper-demo/reap' nudge  # skillreaper-weekly-nudge"
          }
        ]
      }
    ]
  }
}
Real --dry-run output against the same
generated sample stack, so the two paths are the fixture's and a throwaway
build's - yours are your Claude directory and wherever reap is
installed.
reap uninstall-hook removes only the skillreaper entry - other hooks untouched.
| Platform | Full support |
|---|---|
| Claude Code | ✅ |
| Codex CLI | ✅ |
| Hermes | ✅ |
| OpenCode | ✅ (usage evidence needs the sqlite3 CLI; inventory-only without it) |
| Cursor | Inventory only (no local transcripts) |
| OpenClaw | Inventory only (no session history) |
| Gemini CLI | Inventory only (session history is stored in a layout skillreaper does not parse yet, so its items surface as REVIEW, never REAP) |
tool_use blocks and command invocations with timestamps.
OpenCode's SQLite history is read via the sqlite3 CLI (read-only) when it
is on PATH; without it, OpenCode stays inventory-only.ceil(chars / 3.7)) + init parser tool
declarations. Model pricing auto-resolves by model name.reap prune quarantines. reap restore --all undoes.Token counts are approximate. The tool estimates tokens as
ceil(chars / 3.7), based on the average English BPE tokenizer rate.
Real token counts vary by tokenizer (Claude vs GPT vs Gemini) and content
(more code ≈ more tokens per char). This is a documented approximation -
the relative ranking matters more than the absolute number.
Platform format stability. Each supported platform has its own config
layout and transcript format. These change over time as platforms evolve.
Parser updates are an ongoing maintenance reality. The project is architected
for easy fixes (one struct per platform in internal/platform/), but format
changes can lag by days to weeks after a platform update.
OpenCode evidence needs the sqlite3 CLI. OpenCode stores session history
in a SQLite database. skillreaper reads it through the system sqlite3 binary
in read-only mode - the real engine, so WAL-mode databases and overflow pages
are handled correctly (a hand-rolled parser would not). No Go dependency is
added. When sqlite3 is not on PATH, OpenCode items have no usage
evidence: they stay REVIEW (never REAP) with a warning at scan time. The
same safety net applies to any platform with no readable session transcripts.
Incomplete evidence never flags an item. The scanner caps how much it reads per transcript record. If a record is oversized or unreadable, that platform's evidence is marked incomplete and its items stay REVIEW (never REAP/MUTE), with a warning naming the platform - partial evidence can never mistakenly mark a tool as dead.
Not a tool declaration fix. Claude Code's deferred tools reduce the init-time tool declaration overhead. Skillreaper addresses a different problem: always-loaded skill/agent/prose files. If a skill description is 248 characters, it is read into context every session - regardless of lazy tool loading. These two optimizations are complementary, not competing.
internal/platform/cmd/reap/ CLI entry point
internal/
platform/ platform definitions + auto-detection
scan/ inventory scanners (claudemd.go: CLAUDE.md protection)
usage/ transcript parser — tool_use + error tracking
report/ verdict logic (REAP/MUTE/KEEP/REVIEW) + ANSI/JSON/MD renderers
prune/ reversible quarantine
mute/ description strip + backup/restore
safepath/ shared path-confinement boundary (prune/mute/scan)
atomicfile/ crash-safe writes (temp file + rename)
hook/ SessionStart install/uninstall + nudge state
cost/ model pricing
readme/ maintainer-only README figure generator (not shipped)
docs/ demo assets
Tracked as issues, grouped by the problem they solve.
?
today and the total under-counts
(#27).--since / --until and a window that respects the
corpus (#53);
measuring wrong-tool picks
(#55).Not planned: a CI job running reap (a runner has no session transcripts, so it
would measure nothing - the periodic loop is reap install-hook), an
extrapolated annual dollar figure (see docs/decisions.md),
and git commit ranges (transcripts carry timestamps, which --since /
--until already covers).
Included in awesome-go (182k ★, Artificial Intelligence section) and awesome-agent-skills (30k ★). Four external contributors, 19 merged commits. The verdict logic has been ported into another project with attribution in the code (lean-agency).
v0.2.0 ideas were inspired by work from the r/claudeskills community:
Issues · Discussions · Releases · MIT
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman

The best-benchmarked open-source AI memory system. And it's free.

Orca is the ADE for working with a fleet of parallel agents. Run any coding agent with your own subscription. Available on desktop, mobile and remote runtime.

A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Grok Build & Hermes Agent. Only official website: ccswitch.io

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.