

JuliusBrussee/
caveman

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
105k
1 add
Skill Sunset checks local instruction files for stale references, malformed frontmatter, duplicate skills, oversized always-loaded files, and possible secrets. It produces HTML, Markdown, JSON, and agent handoff prompts, while keeping the scan read-only and conservative about retirement claims.
Builders who keep AGENTS.md, CLAUDE.md, or SKILL.md files current across Claude Code and Codex setups.
You can spot stale or risky instruction cleanup candidates before removing rules that still matter.
Scans a directory without editing files, calling an AI API, or requiring provider credentials.
Finds broken links, stale absolute paths, malformed frontmatter, same-name Skills, and oversized always-loaded files.
Separates verified breakage from hypotheses, and labels uncertain obsolescence as `TEST` instead of `RETIRE`.
Generates HTML, Markdown, JSON, Codex and Claude handoff prompts, an experiment template, and a rollback manifest.
Produces bilingual English and Simplified Chinese report files and supports `--lang en` or `--lang zh-CN`.
npx skill-sunset@latest audit --codex --open
npx skill-sunset@latest audit --claude --open
npx skill-sunset@latest audit /path/to/setup --format json --fail-on high




Your
AGENTS.mdonly grows. Which rules are still earning their context?
Skill Sunset is a local, read-only retirement audit for AGENTS.md, CLAUDE.md, and generic SKILL.md instructions. It separates verified breakage and duplicates from unproven “this rule is obsolete” hypotheses. TEST is not RETIRE.
npx skill-sunset@latest audit --codex --open
No global installation is required. No source edits. No AI API. No model quota. No provider credentials.
Third-party integration: HOL Guard v3.0.18 includes a command-safety extension for the installed skill-sunset audit surface. View the merged integration.
If Skill Sunset saves you one risky cleanup pass, star the repository. If a verdict is wrong, share a redacted counterexample.
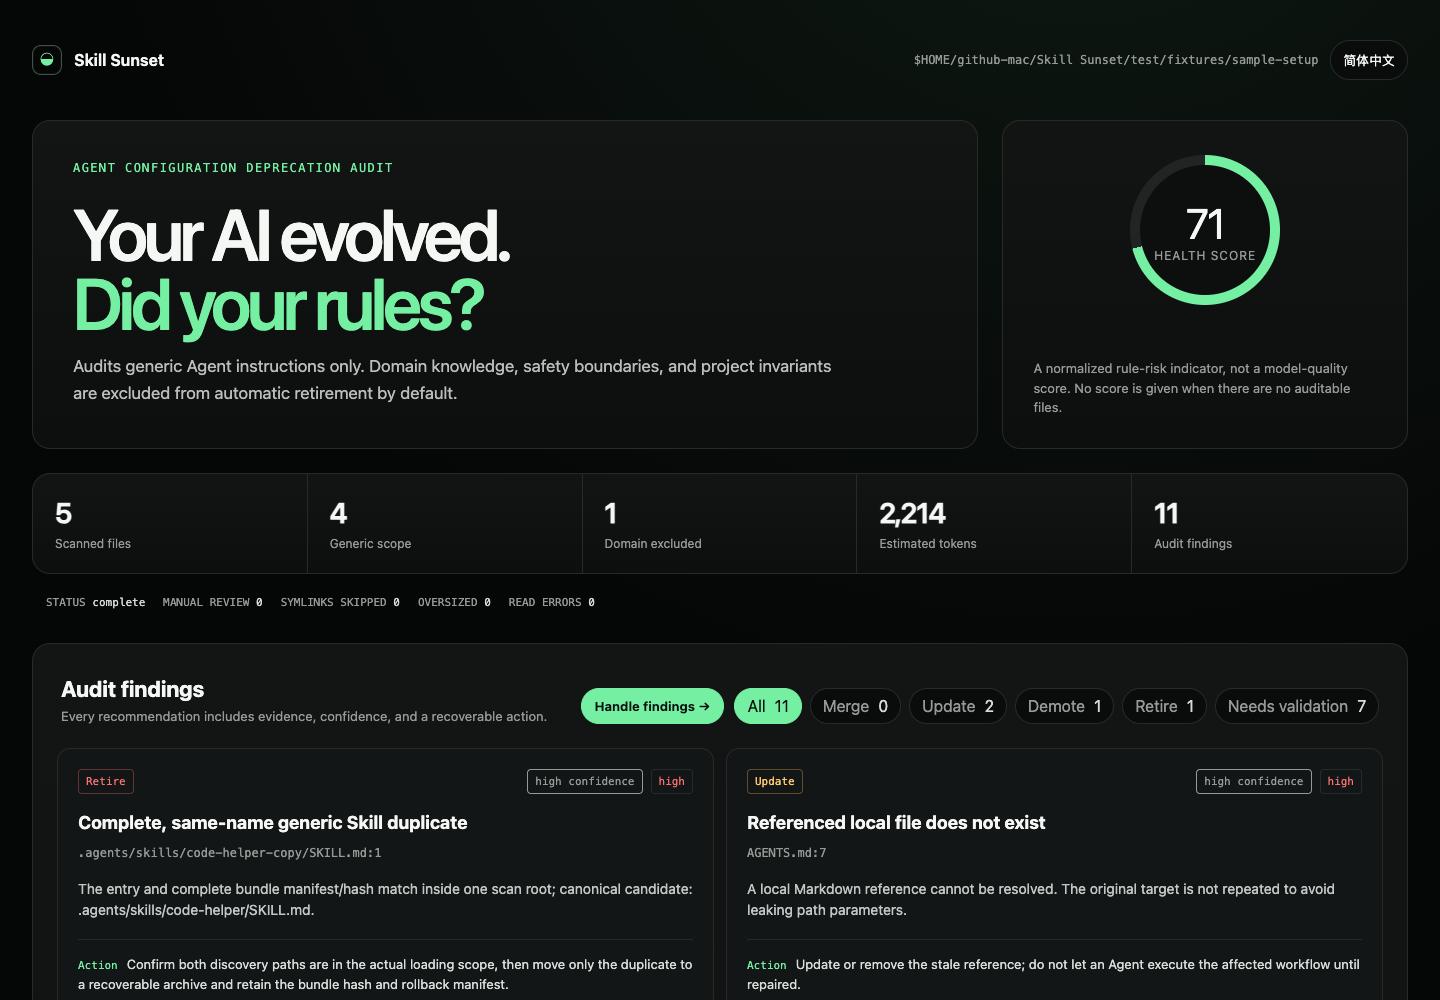
The screenshot comes from a real report generated by the current CLI from test/fixtures/sample-setup: 5 files scanned, 11 findings, with duplicate retirement, stale-reference updates, progressive disclosure, and behavior hypotheses shown separately. Open the animated walkthrough.
Skill Sunset combines deterministic checks with conservative review hypotheses:
TEST instead of claiming they are obsolete;No finding authorizes deletion. TEST means “evaluate this hypothesis,” not “a newer model made this rule unnecessary.”
On 2026-09-01, the current version scanned two Skill directories actively used by the maintainer. Paths, Skill names, and instruction text were redacted:
| Observed problem | Verdict | What it helps prevent |
|---|---|---|
| One Skill contained five Windows-only paths when scanned on macOS | UPDATE | Surface instructions the current OS cannot run; first verify whether the Skill is intentionally Windows-only |
| One always-loaded entry had 2,517 lines and about 17,984 tokens | DEMOTE | Carrying low-frequency documentation into every task |
| Four rules required a tool for every task | TEST | Deleting an untested rule—or retaining unnecessary calls—without comparison evidence |
| One rule named a concrete model | UPDATE | Prompt manual review; this item was kept because it was current and intentional |
Each case has a public, sanitized reproducer: read the full walkthrough or run the fixtures.
| Area | Supported and verified |
|---|---|
| Operating systems | Ubuntu, macOS, and Windows in GitHub Actions |
| Node.js | 20, 22, and 24 |
| Preset targets | Codex (~/.codex) and Claude Code (~/.claude) |
| Instruction files | AGENTS.md, CLAUDE.md, and SKILL.md |
| Agent handoff | Codex and Claude Code prompt artifacts |
| Other setups | Any bounded directory passed explicitly to audit |
Other Linux distributions are expected to work with Node.js 20+, but are not part of the current CI matrix.
Scan Codex configuration:
npx skill-sunset@latest audit --codex --open
Scan Claude Code configuration:
npx skill-sunset@latest audit --claude --open
Scan any bounded directory and keep CI-friendly JSON output:
npx skill-sunset@latest audit /path/to/setup --format json --fail-on high
The CLI defaults to --lang auto. Use --lang en or --lang zh-CN to select the primary report language. Every bundle still contains portable English and Simplified Chinese HTML pages.
Suppose AGENTS.md contains:
Always use Context7 for every task.
[Deployment runbook](docs/deploy.md)
and docs/deploy.md does not exist.
Input and snapshot. Keep a recoverable copy, then audit the directory.
cp AGENTS.md AGENTS.md.skill-sunset.bak
npx skill-sunset@latest audit . --out .skill-sunset --open
Findings. The report can produce:
UPDATE / broken-reference: the runbook target cannot be resolved;UPDATE / context7-assumption: current tool availability needs verification;TEST / unconditional-tooling: “for every task” needs representative old-versus-new evaluation.Change and validate. Verify the real runbook path and current tool list first. Change only the confirmed stale reference; make unconditional tooling a separate candidate. Re-run the audit and the project tests:
npx skill-sunset@latest audit . --out .skill-sunset --format json
npm test
For a TEST item, fill .skill-sunset/experiment-template.json. Validation runs no commands:
npx skill-sunset@latest test .skill-sunset/experiment-template.json --root .
Execution requires a separate --run. A passing experiment proves only its encoded acceptance criteria.
Rollback. If references, tests, or task behavior regress, restore the saved file and re-run the audit:
cp AGENTS.md.skill-sunset.bak AGENTS.md
npx skill-sunset@latest audit . --out .skill-sunset
The generated rollback-manifest.json is intentionally empty until an authorized execution agent records actual changes and hashes.
.skill-sunset/
├── index.html
├── index.en.html
├── index.zh-CN.html
├── audit-report.md
├── audit.json
├── execution-prompt-codex.md
├── execution-prompt-claude.md
├── eval-plan.md
├── activation-checklist.md
├── experiment-template.json
└── rollback-manifest.json
Report contents redact targets below the user home as $HOME/...; other absolute targets are represented as $ABSOLUTE/<name>. The terminal still prints the real local report location so the owner can open it.
activation-checklist.md helps verify whether a runtime actually loads each Skill for two expected paraphrases and rejects one nearby negative case. The core does not read conversation history or call AI. If the runtime exposes no reliable load event, the result stays UNKNOWN; absence of evidence never supports RETIRE.
MERGE: exact duplicates or conflicting same-name Skills.UPDATE: stale paths, references, tools, or version-coupled instructions.DEMOTE: useful always-loaded detail that belongs in progressive disclosure.RETIRE: byte-identical complete generic Skill bundles with the same name inside one scan root; only recoverable archival is recommended.TEST: an obsolescence hypothesis requiring old-versus-new behavioral evaluation before cleanup.Experiment manifests are validation-only unless --run is explicit. Commands run without a shell and receive a minimal non-secret environment allowlist by default. Full environment inheritance—including possible provider credentials—requires the additional --inherit-env flag and trusted commands.
Dry runs and result files retain executable names, argument counts, command hashes, output sizes, and output hashes instead of command arguments or output bodies. Never put credentials in an experiment manifest.
npm test
npm pack --dry-run
node ./bin/skill-sunset.js audit ./test/fixtures/sample-setup --out ./demo-report --open
GitHub Actions runs Gitleaks plus the full operating-system and Node.js matrix. Gitleaks is a publication guard, not proof that every possible credential format can be recognized.
See CHANGELOG.md, CONTRIBUTING.md, and SECURITY.md.
The project is maintained on a best-effort basis without a guaranteed response SLA.
Version 0.3.0 implements static checks, conservative duplicate retirement, localized reports, path redaction, a gated command experiment harness, CI severity exits, adversarial output tests, and a local Skill-activation checklist. Automated session-usage adapters and task-quality adapters remain future evidence layers.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman

The best-benchmarked open-source AI memory system. And it's free.

Orca is the ADE for working with a fleet of parallel agents. Run any coding agent with your own subscription. Available on desktop, mobile and remote runtime.

A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Grok Build & Hermes Agent. Only official website: ccswitch.io

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.