
obra/
superpowers

obra/superpowersSkills
An agentic skills framework & software development methodology that works.
285k
1 add
This repo packages a workflow for taking an idea from rough concept to a sequenced build and a shipped result. The manual skills cover ideation, deep validation, prompt packing, and build iteration; the autonomous skills compose those pieces into a full pipeline or an audit-and-fix pass on an existing repo.
Builders who want Claude Code or Codex to help them choose, validate, plan, and ship work in smaller, safer steps.
You can move from a fuzzy idea to a validated plan and a self-checked build without re-explaining the workflow each time.
Turns a fuzzy idea into a locked concept brief with a success metric, kill criterion, and roadmap.
Runs multi-agent validation for audits, strategy checks, design reviews, and research questions.
Breaks settled scope into self-contained build prompts and handoffs.
Iterates on a running app with build, screenshot, critique, test, and accessibility checks.
Chains ideate, deep-dive, prompt-pack, and build-loop into one autonomous run.
Audits an existing repo, triages what matters, and fixes it to verified local commits.
/plugin marketplace add nelsonwerd/idea-to-ship-skills
/plugin install idea-to-ship@nelsonwerd
git clone https://github.com/nelsonwerd/idea-to-ship-skills.git
cp -r idea-to-ship-skills/skills/* ~/.claude/skills/     # Claude Code
cp -r idea-to-ship-skills/skills/* ~/.agents/skills/     # OpenAI Codex
Composable Agent Skills — for Claude and OpenAI Codex — that take an idea from fuzzy → validated → sequenced build → shipped: by hand, or on autopilot.
Most "build with AI" workflows skip the hard half. They jump straight to code — and skip deciding what's actually worth building, validating it honestly, and planning the build so it ships in safe, verifiable steps. idea-to-ship is that missing front half — plus the autonomous build loop on the far side of it: a small, sharp suite of Agent Skills (they run in Claude and OpenAI Codex), reverse-engineered from real idea→ship journeys (including the mistakes those journeys made), so you don't repeat them.

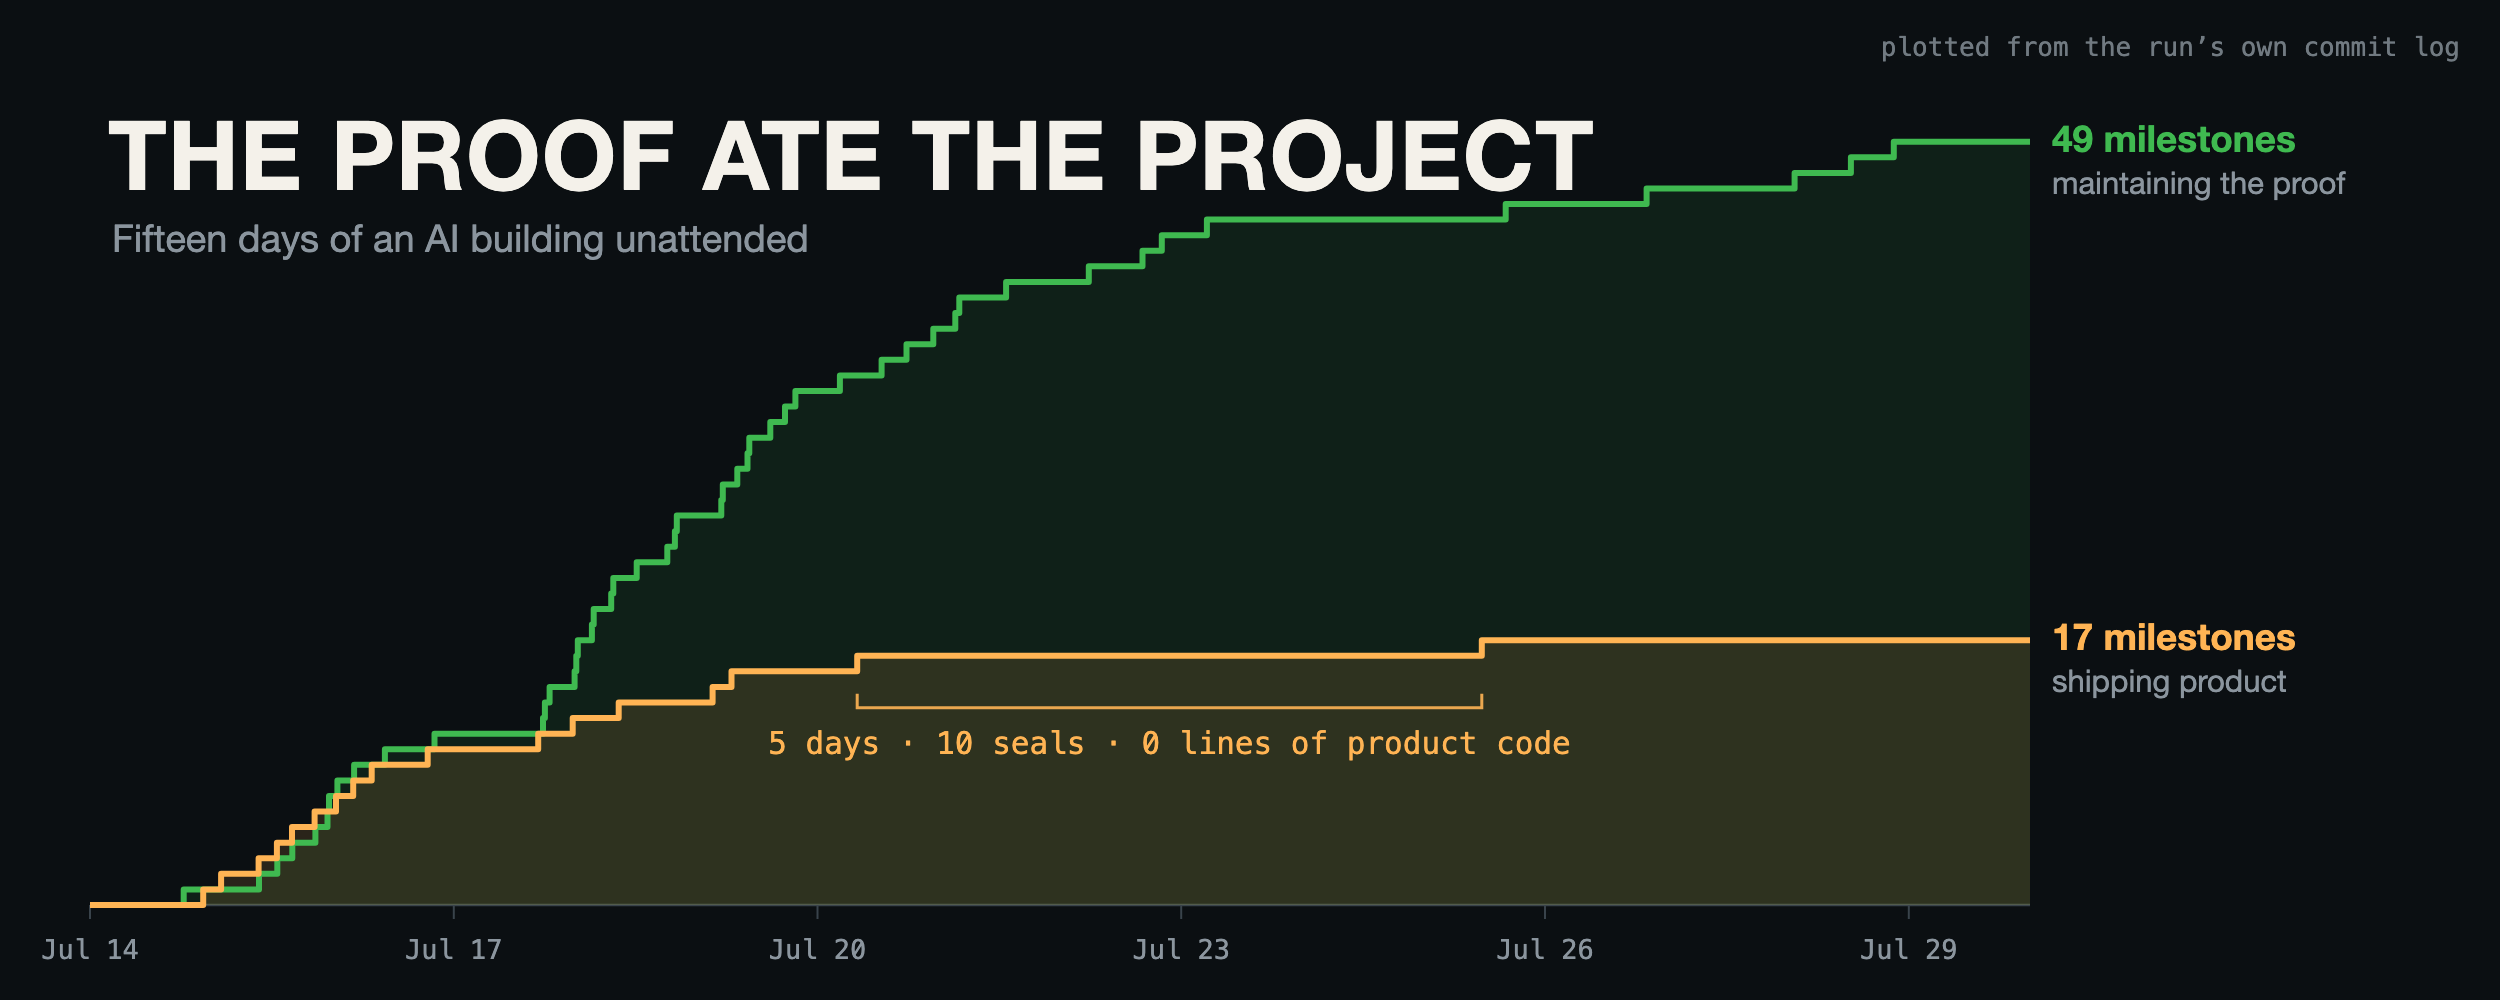
Live right now: autopilot's second stress test — 18+ days autonomous on Codex 5.6, every claim backed by a recorded receipt. See the mid-run debrief, failures included.
They're separate, composable skills on purpose — sharp triggers, lean context, independent use. Run them by hand (the manual tier), or let autopilot fly the whole line for you (the autonomous tier).
Who it's for. Solo and small-team builders who tend to start coding before deciding what's actually worth building — working in Claude or OpenAI Codex. If you've shipped a feature nobody used, rebuilt something and lost the parts that worked, or watched a big change stall halfway, this suite front-loads the discipline that prevents it. Each skill also earns its keep alone. (deep-dive is token-hungry by design — see its note below; it shines most when you're not token-constrained, e.g. on a Claude Max plan.)
ideate — turn a fuzzy idea (or an existing thing you want to improve) into a locked concept + roadmap, captured in one living CONCEPT_BRIEF.md. A blunt, honest co-founder: it forces a success metric and a kill criterion, refuses to spec before the concept survives an honest pressure-test, and hands off cleanly to prompt-pack.deep-dive — the rigor engine ideate leans on for high-stakes validation (and that you can run directly on any codebase, strategy, design, or research question): parallel specialist agents → synthesis → adversarial red-team → a plain-English verdict with honest 1–10 confidence.prompt-pack — turn a settled concept into a sequence of self-contained, independently-shippable build prompts: each does one unit, verifies itself, and leaves the app working before the next. Run them in one chat or spread across many — each prompt is self-contained, so any unit moves cleanly to a fresh chat whenever you want (or need) one. Also writes paste-ready handoffs to resume a chat or relay work to another tool.build-loop — drive a build past "it compiles" to near-finish-line craft: it sees and exercises the running app — render → screenshot → critique → rebuild, multi-pass — and checks the machine facts (build, tests, flows, console, a11y) until acceptance criteria pass or a stop-condition fires (no infinite thrash). When feel is load-bearing the visual design loop runs every iteration. Honest bound: objective craft + a self-graded taste pass, ~80% of the way — not a finished or validated product.→ drive each step yourself, or let autopilot fly the whole line autonomously — in character as a grounded founder-persona — handing back a near-finish-line first draft plus an honest ledger of what only a human or the market can finish.
→ Already have a codebase? audit-and-fix points the same autonomy backwards: audit → triage → fix, skipping ideation entirely (your code is the grounding) and stopping at verified local commits. It's also the natural second pass on an autopilot run — autopilot hands back a first draft with a known correctness/security tail, and that tail is exactly what audit-and-fix is built to attack. (It doesn't close the taste or market half of that tail; those stay human.)
| If you want to… | Type this | You get back |
|---|---|---|
| Decide what to build | "I have an idea for X — help me decide if it's worth building." | docs/CONCEPT_BRIEF.md |
| Investigate something rigorously | "Do a standard design evaluation of X. Research-only." | research/<topic>/ + an executive briefing |
| Turn settled scope into a build plan | "Make a prompt pack from docs/CONCEPT_BRIEF.md." (or "X is too big for one chat — make me a prompt pack.") | docs/<TOPIC>_PROMPT_PACK.md |
| Drive a build to near-finish-line craft | "Loop on this until the core flows pass and the UI holds its design bar." | a self-verified, iterated build + an honest craft ledger |
| Fly the whole pipeline autonomously | "Run autopilot on X." | a CONCEPT_BRIEF, a build pack, a first-draft app + an honest hand-off |
| Audit a repo and fix what's found | "Audit this repo and fix what you find." | an audit + a triage verdict → verified local commits + an honest ledger |
Each works standalone; run them in sequence — or on autopilot — for the full idea→ship pipeline.
ideate → docs/CONCEPT_BRIEF.md (excerpt — the locked concept + honest verdict, edited in place across the session, not regenerated):
- Confidence verdict: 7/10 — would move to 8 if 5 target users confirm the triage pain in interviews; down to 4 if they already tolerate shared Gmail.
- One-line promise: Every client message handled by the right person, fast — without anyone owning a chaotic shared inbox.
- Beachhead persona: 2–6 person creative/client-service studios. (Secondary: solo freelancers — not v1.)
- Success metric: % of client messages with a clear owner + reply within 1 business day.
- Kill criterion: If 5 target studios won't try a 2-week pilot, shelve it.
- Scope OUT / deferred: Outlook, analytics dashboard, mobile app — each named with a one-line reason.
- LOCKED: Layer on existing email, don't replace it — lowers switching cost (the wedge).
deep-dive → research/<topic>/NN-executive-briefing.md (excerpt — verdict-first, after parallel specialists + an adversarial red-team):
TL;DR. Sound core; one blocker before you ship. Confidence: 6/10 — 4 of 7 load-bearing findings externally verified (tests +
git); the rest rest on model judgment.
- [Blocker] Currency rounding diverges between server and client —
pricing.ts:142vsformat.ts:88.- [High] No regression test covers the refund path; a silent change there ships unnoticed.
- Should you proceed? Fix the blocker, add the refund test, then ship Phase 1.
prompt-pack → docs/<TOPIC>_PROMPT_PACK.md (excerpt — one self-contained, independently-shippable unit; reads the brief above):
P2 · Add per-currency rounding — Risk: HIGH Read first:
CLAUDE.md,docs/CONCEPT_BRIEF.md,pricing.ts— verify file:line before editing. What MUST NOT change: the publicformatAmount()signature; existing USD output. Verification:npm test pricing+ manual matrix (regression: USD unchanged · new: JPY 0-decimal, BHD 3-decimal). When done: report files changed + test results. Do not commit — wait for explicit go.
Manual tier — drive each step yourself.
Fuzzy idea → locked concept + roadmap. Two modes: greenfield (a new idea) and refinement (evaluate/improve an existing thing). Triggers: "help me figure out what to build", "is this idea any good", "should I rebuild X", "turn my idea into a plan". → ideate-skill
Multi-agent investigative analysis for questions that deserve more than a one-shot answer: audits, strategy/viability evaluations, design reviews, open research. Triggers: "do a deep dive", "thorough audit", "evaluate this strategy", "is this sound/safe". → deep-dive-skill
Note —
deep-diveis token-hungry by design. A full run fans out 4–6 specialist agents (each writing thousands of words), then synthesis, follow-up verification, a red-team pass, and a briefing — easily 10+ agent calls and tens of thousands of tokens for one analysis. That's the right trade for a high-stakes call, and a great fit on a Claude Max plan (or any setup where you're not token-constrained). On a smaller plan, reach for it deliberately: lean on its built-in Scale heuristics (2–3 lanes for narrow scope, skip the red-team for low-stakes work), or ask for a single-pass review instead.ideateandprompt-packare far lighter.
A big job → ordered, self-contained prompts, each shippable on its own, plus handoffs. Run them in one chat or across many. Triggers: "make a prompt pack", "break this into phases", "I'm running out of context", "write me a handoff". → prompt-pack-skill
Autonomous tier — the pipeline drives itself.
Experimental — and honest about why. The autonomous tier is an early, lightly-proven experiment: genuinely capable and a lot of fun to watch, but not battle-tested — treat it as a promising prototype, not a production tool. It produces a near-finish-line-aimed first draft a human finishes — not a finished or market-validated product. Three limits it doesn't escape: a ~80% craft ceiling with a last-mile correctness/security/taste tail; the grounding firewall (real data may discover the problem and seed the build, but a synthetic persona's reaction never counts as validation); and judgment quality isn't cleanly measurable — its go/kill calls are a signal a human weighs, never proof. Market validation stays the human handoff. Two stress tests so far: a 13.5-hour overnight run on Claude (the case study), and an 18+ day autonomous run on Codex 5.6 that is still going (mid-run debrief).
And it's token-heavy. A single
autopilotrun drives the whole pipeline — adeep-dive, a multi-pass visual loop, a different-model critic — so it can span hours to weeks and a lot of tokens (the 13.5-hour run: ~24.1M fresh / ~784M processed, 97% prompt-cache reads; the ongoing Codex run is in the billions on its root session alone). Both stress tests ran top models at maximum effort (Fable 5 with Ultracode; Codex 5.6 Sol Ultra) — cost scales with model tier, effort setting, and the size of the mandate, and the suite is untested on smaller, faster models. Best on a bigger plan (e.g. Claude Max) or any setup where you're not token-constrained; on a smaller plan, reach for the manual-tier skills directly, or scope the run tight.
Runs ideate → deep-dive → prompt-pack → build-loop end-to-end, in character as a grounded founder-persona — composing the manual-tier skills, never reimplementing them. Hands back a CONCEPT_BRIEF, a validated build pack, a first-draft product, and an honest ledger of what only a human/market can finish. Carries execute-discipline (build only the gated scope; emit a human-only gate, never fake it). Stress-tested on a 13.5-hour unattended run (the case study) and an 18+ day autonomous Codex 5.6 run, still in progress (mid-run debrief). Triggers: "run autopilot", "build this idea→ship autonomously", "fly the whole pipeline end to end". Suite-only — no standalone repo.
Loops build → see → exercise → check → critique → rebuild over the agent's existing tools (headless screenshot + vision to see, Playwright to exercise, axe/Lighthouse to check) until acceptance criteria pass or a stop-condition fires — no infinite thrash. When feel is load-bearing it runs a mandatory, multi-pass visual design loop (render → critique → fix → re-render, every iteration) with a different-model critic as the taste check. Honest bound: it flags ugly/broken/missing reliably but stays self-graded on genuinely good → a human spot-check is the final taste gate; market validation is out of scope. Triggers: "tighten this build", "iterate until it passes", "self-verify the UI". Suite-only — no standalone repo.
Runs deep-dive → triage → prompt-pack → build-loop on a codebase you already have — composing the manual-tier skills, never reimplementing them. autopilot builds something that doesn't exist and risks inventing demand; audit-and-fix repairs something that does and risks breaking working software. Ideation is dropped entirely — your codebase replaces it as the source of truth. Its signature move is the triage verdict: not "here are 30 findings," but what's worth fixing given where you're headed — an opinion, not a menu. Then one gate, and it runs to completion unattended: sequenced units, a red-first regression test per fix, verification receipts, one commit per verified unit. Honest bounds: a receipt records what ran, it never proves correctness; it only fixes what the audit found; the live/real-world tail (real accounts, the first CI run) is never cleared; and it stops at local commits — never pushes, merges, tags, or publishes. Triggers: "audit this repo and fix what you find", "audit and edit", "deep dive then fix the bugs", "autopilot this repo but skip the ideation". Suite-only — no standalone repo.
An optional ground module — real data to seed the persona and the build — is planned; the autonomous tier runs fully without it, and the firewall holds either way.
I pointed autopilot at the heaviest mandate I could write (find your own grounded niche, build a real frontend and backend, hold a serious design bar, don't stop to ask) and went to bed. It ran unattended overnight and came back with Redline: a working design-crit engine for AI-built frontends. Paste a URL, a deterministic render-and-measure pipeline crits the page like a designer would, with typed findings and visual evidence.
The numbers below were re-verified from git, the session transcripts, and a cold re-run of the test wall in an isolated copy. Not self-reports.
And the half that makes this worth reading: the product thesis is unproven (the engine was calibrated and validated on the same 24 sites), and the build shipped with a known, documented, unfixed SSRF vulnerability parked behind a do-not-deploy checklist it could not clear itself. That is the ~80% ceiling, with receipts.
The built product must not be deployed publicly as-is. Details and disclaimers in the case study.
A second, heavier stress test is running now: 18+ days autonomous on Codex 5.6 under one hard rule — every claim has to carry a recorded receipt. The mid-run debrief (receipts and failures both) is at proof-ate-the-project; the live build repo is countershape.
Redline is the stress test — one heavy ask, on purpose. These are the ordinary use: real tools I needed, built with the suite and public, so the claims here have something to check.
audit→fix runs this repo distills were run on wake, so the failures in audit-and-fix's rules table — the non-reproduction that turned out to be luck, the "zero adapter changes" plan that was wrong, the stray binary that staled a receipt — happened in that git history. Every rule was paid for; that's where the receipts are.audit-and-fix leans on: it records what actually ran (argv, real exit code, tree state) and grades claims against a sealed commit. Dogfooded hard — the ongoing Codex stress test surfaced enough recorder bugs to ship didrun v0.2 mid-run, built directly from those findings. The skill needs a receipt tool, not this one; the discipline is portable, the tool is mine.Read the honest version of that claim. These were built with the method
audit-and-fixdistills — not the skill, which postdates them by months. That distinction is load-bearing: the skill's own bounds say itsbuild-loop-per-unit seam has never actually run. So wake is evidence the audit→fix method works and that its rules were earned — it is not evidence the skill is proven. Nothing here has been through it end-to-end yet.
ideate produces a CONCEPT_BRIEF.md — the single artifact prompt-pack consumes to author build prompts. (ideate delivers the what & why; prompt-pack derives the how from your actual code.)ideate delegates to deep-dive when a concept needs heavy, current-sourced validation, and folds the verdict back into the brief.build-loop drives any build — from a prompt-pack step or on its own — toward near-finish-line craft; it's the craft engine the autonomous tier leans on.autopilot composes all four (ideate → deep-dive → prompt-pack → build-loop) to fly the whole pipeline autonomously — orchestration only, never reimplementing them.audit-and-fix composes three of them (deep-dive → prompt-pack → build-loop) in the other direction: deep-dive generates the work instead of validating a brief, and its Tier 0/1/2/3 fix list — already sized for one work session each — becomes prompt-pack's units directly. The two orchestrators share a tier and a discipline, but never each other's risks — and they chain: autopilot → audit-and-fix is the common second pass, aimed at the correctness/security tail autopilot's ~80% ceiling leaves behind.deep-dive to audit a codebase, prompt-pack to sequence a refactor, ideate to gut-check an idea, build-loop to tighten a build — without the others.Which skill for which question? (they overlap on "evaluate / plan" — here's the precedence)
| The user is really asking… | Skill | Then |
|---|---|---|
| What should I build? Is this idea worth pursuing? | ideate | locks a CONCEPT_BRIEF.md; delegates heavy validation to deep-dive mid-funnel |
| Is this correct / safe / viable / evidence-backed? | deep-dive | returns a verdict + confidence; if it was validating a concept, hands a block back to ideate |
| Scope is settled — sequence the build | prompt-pack | reads CONCEPT_BRIEF.md if present; offers ideate first if the idea is unsettled |
| Does this build actually work + hold a craft bar? | build-loop | loops see/exercise/critique until it passes or a stop-condition fires |
| Build the whole thing for me, autonomously | autopilot | flies ideate→…→build-loop in-character; hands back a first draft + an honest ledger |
| Audit my repo and fix what you find | audit-and-fix | audits read-only, triages against your next goal, takes one go, then fixes to verified local commits |
| Genuinely unclear | ask one question | viability direction, rigorous audit, execution-planning, or autonomous build? |
deep-dive vs. audit-and-fix — they overlap on "audit this codebase", so: deep-dive answers "is it sound?" and stops. audit-and-fix answers "is it sound, what's worth fixing given where you're headed — now go fix it." No intent to change the code → deep-dive (it's also far cheaper).
These compose, but each also runs alone — install only the one you need.
These follow the open Agent Skills standard, so they run in Claude and OpenAI Codex — install them all as a Claude Code plugin, drop them into your Codex skills folder, or copy individual skills anywhere. Pick your setup:
| You use… | Get them all by… |
|---|---|
| Claude Code — terminal, the Code tab of the Claude desktop app, claude.ai/code, or a VS Code / JetBrains IDE | the plugin (Option 1), or a manual copy (Option 2) |
| OpenAI Codex — CLI, app, or IDE | copying the skills into ~/.agents/skills/ (Option 2) |
| Claude chat — the Chat tab of the desktop app, or claude.ai (non-coding use) | uploading each skill's .skill zip (in this repo root) under Customize → Skills. Best for ideate; the others want repo/file access (and build-loop/autopilot want the build tools too). |
| Any other agent | pointing it at any skills/<name>/SKILL.md — it's just instructions |
"Claude Code" and "Claude chat" both live in the one Claude desktop app — its Code tab vs its Chat tab (plus their terminal / web / IDE surfaces). Plugins install in Claude Code only; the Chat tab takes uploaded skills under Customize → Skills.
The skill format is portable; some runtime features (parallel subagents, progress tools, web/repo access, a headless browser) are richest in Claude Code and Codex. Each skill still runs everywhere — degraded cells lose mechanics, not method.
| Skill | Claude chat | Claude Code | OpenAI Codex | Other agents |
|---|---|---|---|---|
| ideate | Strong — concept work; brief kept inline when there's no file tree | Best | Strong — with a local workspace for the brief | Works — full method; keep the brief in a file or inline |
| deep-dive | Works (degraded: no repo/file access; lanes run serially) | Best — parallel subagents + web | Strong — same lanes run serially (lower cross-agent independence, so confidence is capped); external claims labeled unverified if no web | Works (degraded: serial lanes, local-only; label external claims unverified) |
| prompt-pack | Limited — best for high-level |
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
An agentic skills framework & software development methodology that works.

Turn any codebase, with its docs, SQL schemas, configs, and PDFs, into a queryable knowledge graph. A /graphify skill for Claude Code, Cursor, Codex, and Gemini CLI: local deterministic AST parsing, every edge explained, no vector store.

Topic in, narrated explainer video out. A Claude Code / Codex skill that turns any topic into a black-canvas motion-graphics explainer video with TTS voiceover, subtitles and a chapter progress bar. Chinese or English; every frame drawn in code with Remotion.
Public repository for Agent Skills
Open-source AI job search: scan job portals, evaluate listings into a structured A-H report with a global 1-5 score, tailor your CV, track applications — runs locally in your AI coding CLI (Claude Code, Codex, OpenCode, Antigravity…)

Production-grade engineering skills for AI coding agents.