
JuliusBrussee/
caveman

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
105k
1 add
LocalAI provides a local-first AI runtime with OpenAI-compatible APIs, a terminal CLI, and built-in agent features. It loads backends on demand, so you can add only the model engines you need for text, vision, audio, image, video, and MCP-based workflows.
Builders who want to run local model servers, connect agents to tools, or keep prompts and data on their own hardware.
You can serve and use multiple AI models locally instead of wiring each app to a separate hosted API.
Serves OpenAI, Anthropic, and ElevenLabs-style endpoints so existing clients can connect with less rework.
Downloads backends only when a model needs them, instead of bundling every engine into one binary.
Includes autonomous agents, tool use, RAG, skills, and Model Context Protocol support.
Runs text, embeddings, vision, audio, image, and video models behind one API.
Supports CPU-only setups and acceleration for NVIDIA, AMD, Intel, Apple Silicon, and Vulkan.
Adds API key auth, quotas, role-based access, and usage tracking.
Supports horizontal scaling with PostgreSQL and NATS, plus P2P inferencing.
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest
docker run -ti --name local-ai -p 8080:8080 --device=/dev/kfd --device=/dev/dri --group-add=video localai/localai:latest-gpu-hipblas
docker run -ti --name local-ai -p 8080:8080 --device=/dev/dri/card1 --device=/dev/dri/renderD128 localai/localai:latest-gpu-intel
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest-gpu-vulkan
# Terminal 1
local-ai run llama-3.2-1b-instruct:q4_k_m

# Terminal 2
local-ai chat --model llama-3.2-1b-instruct:q4_k_m


Deutsch | Español | français | 日本語 | 한국어 | Português | Русский | 中文
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
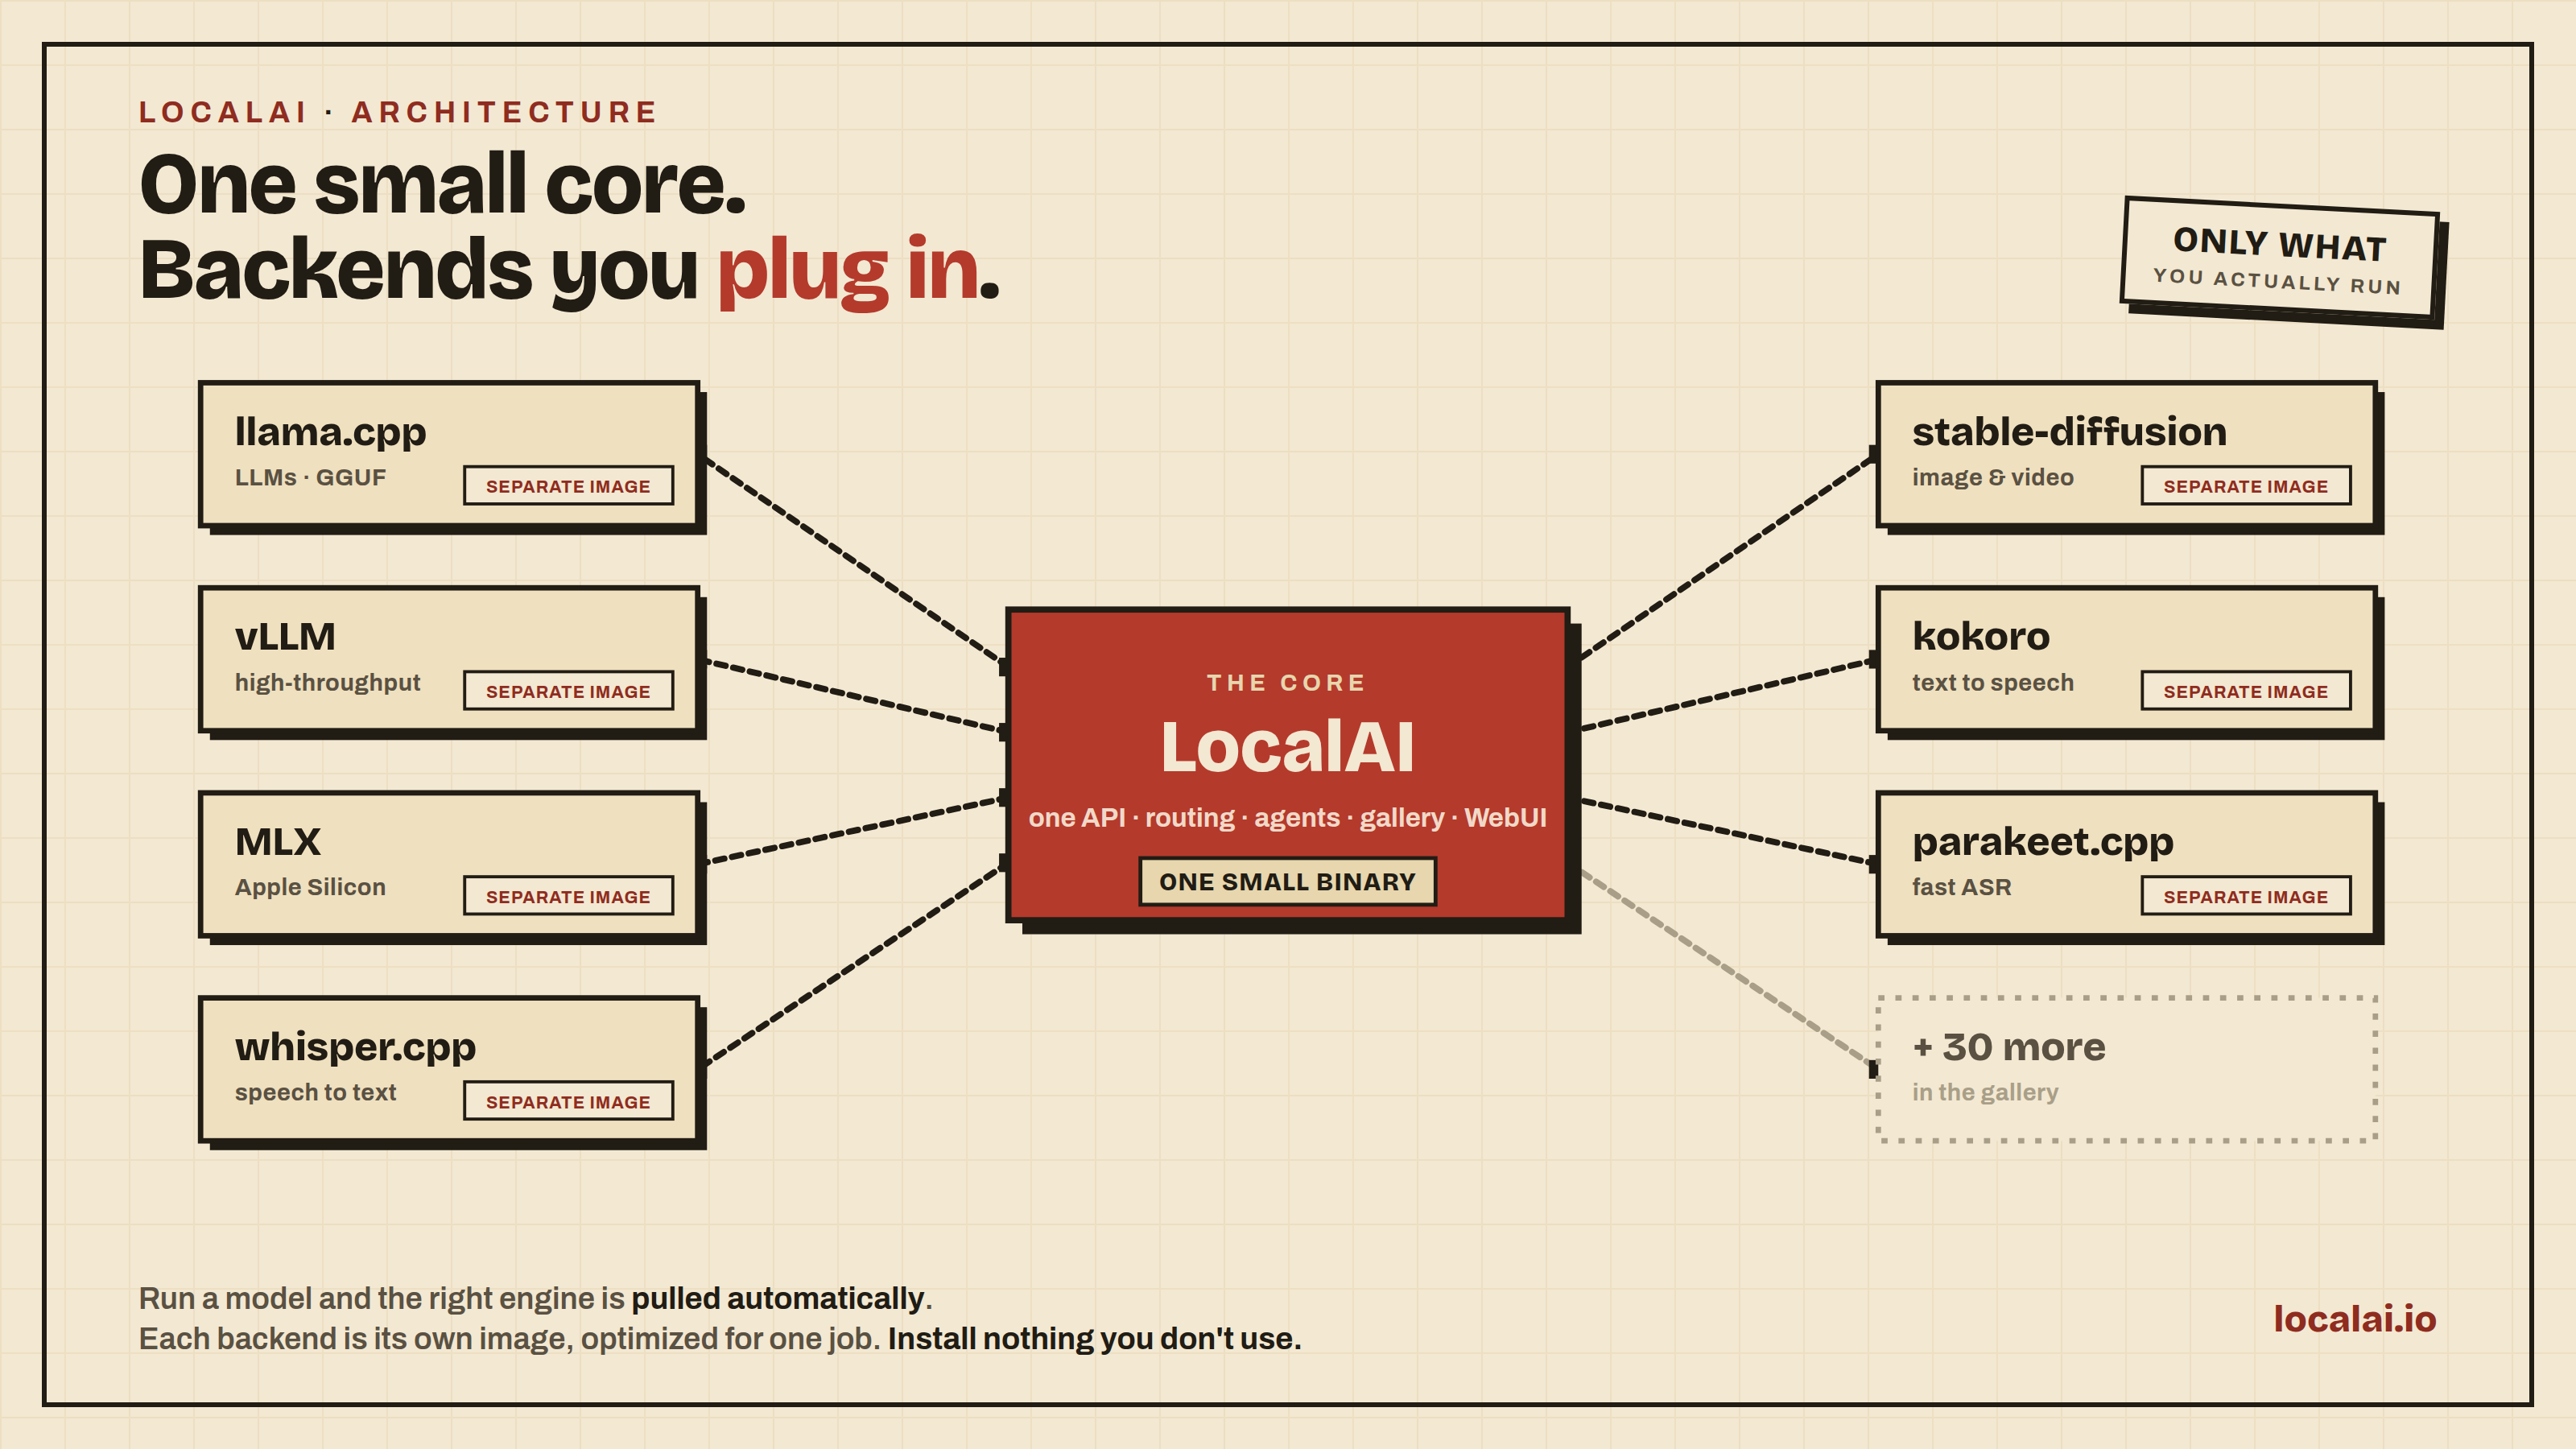
A small core, not a bundle. Each backend wraps a best-in-class engine (llama.cpp, vLLM, whisper.cpp, stable-diffusion, MLX...) in its own image, pulled only when a model needs it. You install nothing you don't use.
Created by Ettore Di Giacinto and maintained by the LocalAI team.
:book: Documentation | :speech_balloon: Discord | 💻 Quickstart | 🖼️ Models | ❓FAQ
https://github.com/user-attachments/assets/08cbb692-57da-48f7-963d-2e7b43883c18
https://github.com/user-attachments/assets/228fa9ad-81a3-4d43-bfb9-31557e14a36c
https://github.com/user-attachments/assets/6270b331-e21d-4087-a540-6290006b381a
https://github.com/user-attachments/assets/cbb03379-23b4-4e3d-bd26-d152f057007f
https://github.com/user-attachments/assets/5ba4ace9-d3df-4795-b7d4-b0b404ea71ee
https://github.com/user-attachments/assets/ed88e34c-fed3-4b83-8a67-4716a9feeb7b

Note: The DMG is not signed by Apple. After installing, run:
sudo xattr -d com.apple.quarantine /Applications/LocalAI.app. See #6268 for details.
Already ran LocalAI before? Use
docker start -i local-aito restart an existing container.
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest
# CUDA 13
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-13

# CUDA 12
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-12

# NVIDIA Jetson ARM64 (CUDA 12, for AGX Orin and similar)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64

# NVIDIA Jetson ARM64 (CUDA 13, for DGX Spark)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64-cuda-13
docker run -ti --name local-ai -p 8080:8080 --device=/dev/kfd --device=/dev/dri --group-add=video localai/localai:latest-gpu-hipblas
docker run -ti --name local-ai -p 8080:8080 --device=/dev/dri/card1 --device=/dev/dri/renderD128 localai/localai:latest-gpu-intel
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest-gpu-vulkan
# From the model gallery (see available models with `local-ai models list` or at https://models.localai.io)
local-ai run llama-3.2-1b-instruct:q4_k_m
# From Huggingface
local-ai run huggingface://TheBloke/phi-2-GGUF/phi-2.Q8_0.gguf
# From the Ollama OCI registry
local-ai run ollama://gemma:2b
# From a YAML config
local-ai run https://gist.githubusercontent.com/.../phi-2.yaml
# From a standard OCI registry (e.g., Docker Hub)
local-ai run oci://localai/phi-2:latest
To work with a running LocalAI server from the terminal, start the built-in agent from another shell. It answers questions, reads your files and runs commands on your machine, asking you to approve anything that changes state. Inside a session, /models lists installed models and /model <name> switches between them. See the Terminal agent docs.
# Terminal 1
local-ai run llama-3.2-1b-instruct:q4_k_m

# Terminal 2
local-ai chat --model llama-3.2-1b-instruct:q4_k_m
Automatic Backend Detection: LocalAI automatically detects your GPU capabilities and downloads the appropriate backend. For advanced options, see GPU Acceleration.
For more details, see the Getting Started guide.
insightface and speaker-recognition backends (PR #10441).llama.cpp prompt cache on by default (repeated system prompts collapse from minutes to seconds), keyless cosign signing of backend OCI images, per-API-key + per-user usage attribution, Distributed v3 with per-request replica routing. Release notesFor older news and full release notes, see GitHub Releases and the blog.
llama.cpp, transformers, vllm ... and more)LocalAI supports 60+ backends including llama.cpp, vLLM, SGLang, transformers, whisper.cpp, diffusers, MLX, MLX-VLM, and many more. Hardware acceleration is available for NVIDIA (CUDA 12/13), AMD (ROCm), Intel (oneAPI/SYCL), Apple Silicon (Metal), Vulkan, and NVIDIA Jetson (L4T). All backends can be installed on-the-fly from the Backend Gallery.
See the full Backend & Model Compatibility Table and GPU Acceleration guide.
Most backends wrap a best-in-class upstream engine. A handful of them are native C/C++/GGML engines (no Python at inference) developed and maintained by the LocalAI project itself:
| Backend | What it does |
|---|---|
| vllm.cpp | From-scratch C++20 port of vLLM for text generation: paged KV cache, continuous batching, prefix caching, safetensors + GGUF loading, engine-enforced structured output, on CPU, CUDA, Metal and Vulkan. Also serves MiniMax-H3 joint video+audio generation |
| parakeet.cpp | C++/GGML port of NVIDIA NeMo Parakeet ASR (tdt/ctc/rnnt/hybrid), with cache-aware streaming transcription |
| moss-transcribe.cpp | C++/GGML port of OpenMOSS MOSS-Transcribe-Diarize: joint long-form transcription, speaker diarization and timestamping in a single pass |
| moss-tts.cpp | C++/GGML port of the OpenMOSS MOSS-TTS family: text-to-speech (MOSS-TTS-Local v1.5, 48 kHz stereo) with reference-audio voice cloning, through the MOSS-Audio-Tokenizer neural codec |
| magpie-tts.cpp | C++/GGML port of NVIDIA's Magpie TTS Multilingual 357M: 22.05 kHz mono text-to-speech in 5 voices and 9+ languages, with the NanoCodec neural codec and tokenizer/G2P embedded in a single GGUF |
| ced.cpp | C++/GGML port of the CED audio-tagging models: sound-event classification (527-class AudioSet) over REST and the realtime API for live recognition |
| voice-detect.cpp | Speaker recognition and voice analysis (ECAPA-TDNN, WeSpeaker, ERes2Net, CAM++, wav2vec2 age/gender/emotion), replacing the Python speaker-recognition backend |
| voxtral-tts.c | Mistral Voxtral-4B-TTS text-to-speech in pure C: 20 preset voices across 9 languages, 24 kHz WAV output, no dependencies beyond libc |
| vibevoice.cpp | Native port of Microsoft VibeVoice for TTS (voice cloning) and long-form ASR with speaker diarization |
| rf-detr.cpp | Native RF-DETR object detection and instance segmentation |
| locate-anything.cpp | Open-vocabulary object detection and visual grounding (LocateAnything-3B) |
| depth-anything.cpp | Depth Anything 3 monocular metric depth + camera pose estimation |
| face-detect.cpp | Face detection, recognition, demographics and anti-spoofing (SCRFD/ArcFace, YuNet/SFace), replacing the Python insightface backend |
| free-splatter.cpp | Pose-free 3D reconstruction (FreeSplatter): turns a handful of plain photos into 3D Gaussians, no camera poses or GPU required |
| trellis2.cpp | C++/GGML port of Microsoft TRELLIS.2: single-image to textured 3D mesh (GLB with PBR materials) |
| privacy-filter.cpp | Standalone GGML PII/NER token-classification engine powering LocalAI's PII redaction tier |
| LocalVQE | Joint acoustic echo cancellation, noise suppression, and dereverberation |
| local-store | Local-first vector database for embeddings (shipped in-tree) |
We also maintain apex-quant, a per-tensor, per-layer quantization recipe for Mixture-of-Experts models that exploits their structural sparsity to produce GGUFs matching or beating Q8_0 quality - and they run out of the box on stock llama.cpp.
LocalAI is maintained by a small team of humans, together with the wider community of contributors.
A huge thank you to everyone who contributes code, reviews PRs, files issues, and helps users in Discord — LocalAI is a community-driven project and wouldn't exist without you. See the full contributors list.
If you utilize this repository, data in a downstream project, please consider citing it with:
@misc{localai,
  author = {Ettore Di Giacinto},
  title = {LocalAI: The free, Open source OpenAI alternative},
  year = {2023},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/go-skynet/LocalAI}},
Do you find LocalAI useful?
Support the project by becoming a backer or sponsor. Your logo will show up here with a link to your website.
A huge thank you to our generous sponsors who support this project covering CI expenses, and our Sponsor list:
A special thanks to individual sponsors, a full list is on GitHub and buymeacoffee. Special shout out to drikster80 for being generous. Thank you everyone!
LocalAI is a community-driven project created by Ettore Di Giacinto and maintained by the LocalAI team.
MIT - Author Ettore Di Giacinto mudler@localai.io
LocalAI couldn't have been built without the help of great software already available from the community. Thank you!
This is a community project, a special thanks to our contributors!
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman

The best-benchmarked open-source AI memory system. And it's free.

Orca is the ADE for working with a fleet of parallel agents. Run any coding agent with your own subscription. Available on desktop, mobile and remote runtime.

A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Grok Build & Hermes Agent. Only official website: ccswitch.io

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.