
JuliusBrussee/
caveman

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
105k
1 add
MCPBench is a benchmark suite for MCP servers. It evaluates servers on web search, database query, and GAIA tasks, and works with both local STDIO servers and remote SSE servers.
Builders who want to compare MCP servers with the same benchmark setup.
You can measure how different MCP servers perform on the same tasks instead of judging them by feel.
Runs the WebSearch task set against MCP servers and reports task completion, latency, and token use.
Evaluates database-focused MCP servers with the DB dataset and matching evaluation script.
Supports GAIA-style tasks through the GAIA benchmark flow.
Works with servers started locally through STDIO or exposed remotely through SSE.
Uses JSON config files in `configs/` to describe MCP pools and server launch details.
conda create -n mcpbench python=3.11 -y
conda activate mcpbench
pip install -r requirements.txt
sh launch_mcps_as_sse.sh YOUR_CONFIG_FILE
sh launch_mcps_as_sse.sh firecrawl.json
sh evaluation_websearch.sh YOUR_CONFIG_FILE
sh evaluation_db.sh YOUR_CONFIG_FILE
sh evaluation_gaia.sh YOUR_CONFIG_FILE


MCPBench is an evaluation framework for MCP Servers. It supports the evaluation of three types of servers: Web Search, Database Query and GAIA, and is compatible with both local and remote MCP Servers. The framework primarily evaluates different MCP Servers (such as Brave Search, DuckDuckGo, etc.) in terms of task completion accuracy, latency, and token consumption under the same LLM and Agent configurations. Here is the evaluation report.
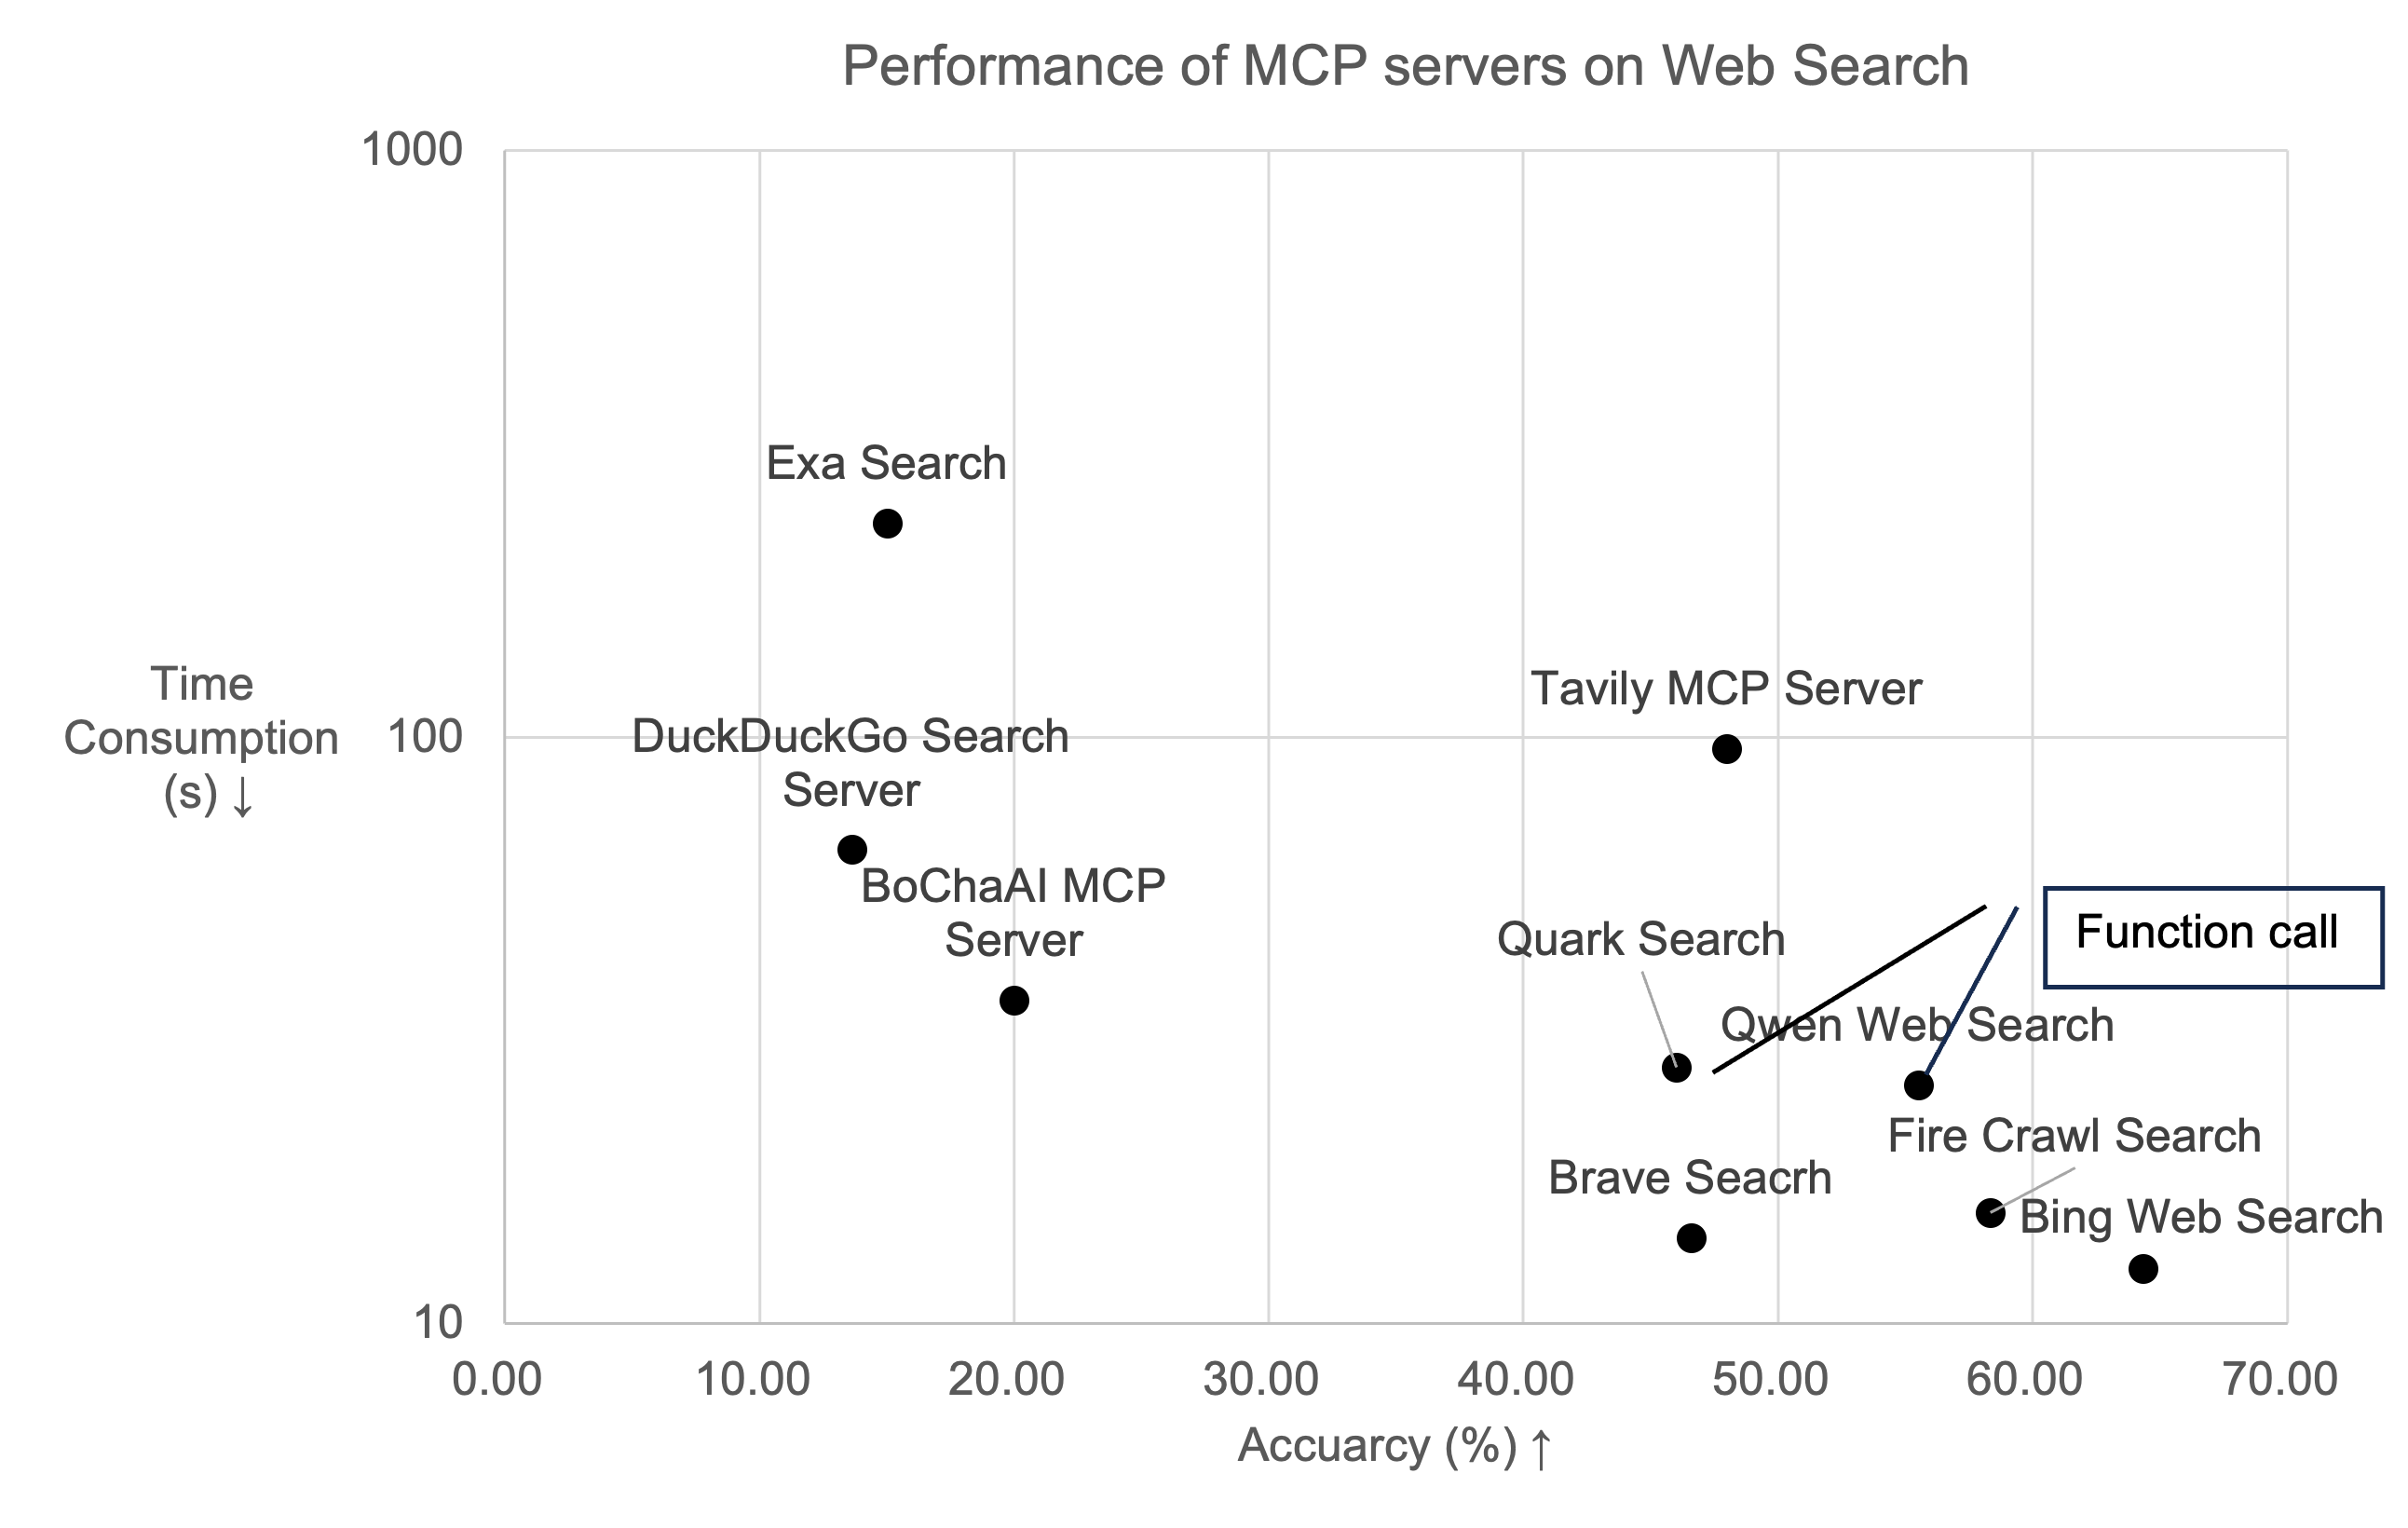
The implementation refers to LangProBe: a Language Programs Benchmark.
Big thanks to Qingxu Fu for the initial implementation!
Sep. 1, 2025 🌟 Modelscope AI hackathon will be hold on Sep. 23rd, ref: https://modelscope.cn/active/aihackathon-mcp-agentApr. 29, 2025 🌟 Update the code for evaluating the MCP Server Package within GAIA.Apr. 14, 2025 🌟 We are proud to announce that MCPBench is now open-sourced.The framework requires Python version >= 3.11, nodejs and jq.
conda create -n mcpbench python=3.11 -y
conda activate mcpbench
pip install -r requirements.txt
Please first determine the type of MCP server you want to use:
First, you need to write the following configuration:
{
    "mcp_pool": [
        {
            "name": "firecrawl",
            "run_config": [
                {
                    "command": "npx -y firecrawl-mcp",
                    "args": "FIRECRAWL_API_KEY=xxx",
                    "port": 8005
                }
            ]
        }
    ]
}
Save this config file in the configs folder and launch it using:
sh launch_mcps_as_sse.sh YOUR_CONFIG_FILE
For example, save the above configuration in the configs/firecrawl.json file and launch it using:
sh launch_mcps_as_sse.sh firecrawl.json
To evaluate the MCP Server's performance, you need to set up the necessary MCP Server information. the code will automatically detect the tools and parameters in the Server, so you don't need to configure them manually, like:
{
    "mcp_pool": [
        {
            "name": "Remote MCP example",
            "url": "url from https://modelscope.cn/mcp or https://smithery.ai"
        },
        {
            "name": "firecrawl (Local run example)",
            "run_config": [
                {
                    "command": "npx -y firecrawl-mcp",
                    "args": "FIRECRAWL_API_KEY=xxx",
                    "port": 8005
                }
            ]
        }
    ]
}
To evaluate the MCP Server's performance on WebSearch tasks:
sh evaluation_websearch.sh YOUR_CONFIG_FILE
To evaluate the MCP Server's performance on Database Query tasks:
sh evaluation_db.sh YOUR_CONFIG_FILE
To evaluate the MCP Server's performance on GAIA tasks:
sh evaluation_gaia.sh YOUR_CONFIG_FILE
For example, save the above configuration in the configs/firecrawl.json file and launch it using:
sh evaluation_websearch.sh firecrawl.json
Our framework provides two datasets for evaluation. For the WebSearch task, the dataset is located at MCPBench/langProBe/WebSearch/data/websearch_600.jsonl, containing 200 QA pairs each from Frames, news, and technology domains. Our framework for automatically constructing evaluation datasets will be open-sourced later.
For the Database Query task, the dataset is located at MCPBench/langProBe/DB/data/car_bi.jsonl. You can add your own dataset in the following format:
{
  "unique_id": "",
  "Prompt": "",
  "Answer": ""
}
We have evaluated mainstream MCP Servers on both tasks. For detailed experimental results, please refer to Documentation
If you find this work useful, please consider citing our project or giving us a 🌟:
@misc{mcpbench,
  title={MCPBench: A Benchmark for Evaluating MCP Servers},
  author={Zhiling Luo, Xiaorong Shi, Xuanrui Lin, Jinyang Gao},
  howpublished = {\url{https://github.com/modelscope/MCPBench}},
  year={2025}
}
Alternatively, you may reference our report.
@article{mcpbench_report,
      title={Evaluation Report on MCP Servers},
      author={Zhiling Luo, Xiaorong Shi, Xuanrui Lin, Jinyang Gao},
      year={2025},
      journal={arXiv preprint arXiv:2504.11094},
      url={https://arxiv.org/abs/2504.11094},
      primaryClass={cs.AI}
}
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman

The best-benchmarked open-source AI memory system. And it's free.

Orca is the ADE for working with a fleet of parallel agents. Run any coding agent with your own subscription. Available on desktop, mobile and remote runtime.

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.

Turn any technical book PDF into a Claude Code skill — ready to study, reference, and use while you work.