A portable writing skill for Claude Code, OpenClaw, Hermes, and any other agentskills.io-compatible agent. Audits and rewrites content to remove AI writing patterns ("AI-isms").
Three modes:
- Rewrite (default) — flags AI patterns and rewrites the text to fix them. A built-in second pass catches patterns that survived the first edit.
- Detect — flags AI patterns without rewriting. Shows which flags are real problems vs. judgment calls. Useful when patterns might be intentional, when auditing content you don't want altered, or when you just want a quick scan.
- Edit — edits a prose file in place (via the Edit tool) with minimal, targeted changes, preserving passages that are already human. Source code, configuration, and generated data are refused because prose rewrites can corrupt structured content. Returns an edits-made + verification report, not the full file.
An optional voice profile (casual / professional / technical / warm / blunt) sets how the prose should sound, independent of the audience context profile.
Quick demo
Input:
Certainly! Acme Analytics, a vibrant startup nestled in the heart of Boulder's thriving tech ecosystem, has secured $40M in Series B funding — marking a watershed moment for the observability landscape. The platform serves as a unified hub, featuring real-time dashboards, boasting sub-second queries, and presenting a seamless integration layer. Moreover, experts believe Acme is poised to disrupt the market. In conclusion, the future looks bright!
Output:
Acme Analytics raised a $40M Series B led by Sequoia. The Boulder-based startup makes an observability platform that runs queries in under a second and plugs into existing monitoring stacks without custom integration work.
What it caught: chatbot opener ("Certainly!"), promotional language ("vibrant," "nestled," "thriving"), significance inflation ("watershed moment"), copula avoidance ("serves as," "featuring," "boasting"), 4 word replacements, vague attribution ("experts believe"), filler ("Moreover"), generic conclusion ("the future looks bright"), over-polished uniformity. 15+ AI tells in one paragraph.
Why a skill, not just a prompt
A one-shot "make this sound human" prompt catches the obvious stuff. This skill is different:
- Structured audit — returns identified issues with quoted text, the rewrite, a change summary, and a second-pass audit in four discrete sections. You see exactly what changed and why.
- Two-pass detection — the second pass re-reads the rewrite and catches patterns that survive the first edit: recycled transitions, lingering inflation, copula swaps that snuck through.
- 112-entry word replacement table across 3 tiers + 10 Tier 3 phrases — not vibes-based. Every flagged word has a specific, plainer alternative. "Leverage" → "use." "Commence" → "start." Tier 1 matches flag unless a listed exception applies, Tier 2 words flag when they cluster, Tier 3 words flag only at high density. Tier 1 itself splits into 1A frequency markers (
delve, tapestry) and 1B clarity edits (in order to, utilize) — same fix, but only 1A is evidence about how a passage was produced, and 1B is weighted lower so a wordiness fix cannot push a document toward an AI classification. Tier 3 phrases (multi-word boilerplate like "the integration of," "decentralized compute") flag on per-phrase repetition or when 3+ distinct phrases stack in one piece — the LLM-self-varies-boilerplate shape.
- 74 pattern categories — representative examples below, each with before/after. Includes structural detection (hashtag stuffing, bare-NP bullet lists, hedge-stacked predictions), AI-tool fingerprints (placeholders, citation markup, UTM params), rhythm/uniformity checks, conversational-register tells, and writer-side tests. The full catalog lives in
references/patterns.md; this count is enforced against it in CI.
- Detect mode — flag patterns without rewriting. See which flags are real problems vs. judgment calls. Useful when patterns might be intentional or you're auditing content you don't want altered.
- Works across platforms — a directory-based skill runs in Claude Code, Cowork (as a plugin), OpenClaw, Cursor (as a ported rule), and other directory-aware agents. See the install paths below.
Installation & Usage
Install the complete skill directory
Use the plugin install below or clone the repository into your agent's skills directory. Keep SKILL.md with references/patterns.md: the entry file loads the catalog before auditing. The bundled scripts/, detector/, and examples/ provide optional mechanical verification.
For a single-file rules field, use dist/avoid-ai-writing.md. It includes every rule and profile, with manual fallbacks for commands unavailable outside the bundle. Do not copy the slim entry file alone. Older installers that fetch only root SKILL.md omit its required reference; use a directory install instead.
Claude Code
Option 1: Clone into skills directory
git clone https://github.com/conorbronsdon/avoid-ai-writing ~/.claude/skills/avoid-ai-writing
Option 2: Copy a self-contained file
Download dist/avoid-ai-writing.md and place it in any directory that Claude Code can read. Reference it in your CLAUDE.md:
- Editing for AI patterns → read `path/to/avoid-ai-writing.md`
Option 3: Use as a slash command
Create a command file (e.g., ~/.claude/commands/clean-ai-writing.md):
---
description: Audit and rewrite content to remove AI writing patterns
---
$ARGUMENTS
Read and follow the instructions in ~/.claude/skills/avoid-ai-writing/SKILL.md
Then use /clean-ai-writing <your text> in Claude Code.
Claude Cowork — install as a plugin
Cowork loads skills only from installed plugins — it doesn't scan ~/.claude/skills/, so a bare clone (the Claude Code steps above) won't be discovered there. This repo doubles as a single-plugin marketplace, so install it as a plugin instead:
/plugin marketplace add conorbronsdon/avoid-ai-writing
/plugin install avoid-ai-writing@conorbronsdon-skills
/reload-plugins   # or restart the session, to activate the skill
In the Cowork desktop app, do the same from Customize → Plugins → Add marketplace from GitHub (conorbronsdon/avoid-ai-writing), then install avoid-ai-writing. The skill auto-triggers from phrases like "remove AI-isms." New releases arrive when the plugin's version is bumped — run /plugin marketplace update to pull them.
The same plugin install works in Claude Code if you'd rather have a versioned, updatable plugin than the file clone above.
Prefer not to install a plugin? Copy dist/avoid-ai-writing.md into a folder connected to your Cowork session and tell the agent to follow ./avoid-ai-writing.md — works as a one-off, no auto-trigger.
OpenClaw
Option 1: Install from ClawHub
clawhub install avoid-ai-writing
Option 2: Clone into skills directory
git clone https://github.com/conorbronsdon/avoid-ai-writing ~/.openclaw/skills/avoid-ai-writing
Cursor
Drop the ported rule into your project's .cursor/rules/:
mkdir -p .cursor/rules
curl -o .cursor/rules/avoid-ai-writing.mdc \
  https://raw.githubusercontent.com/conorbronsdon/avoid-ai-writing/main/cursor-rules/avoid-ai-writing.mdc
See cursor-rules/README.md for activation globs and trigger phrases. Functionally identical to the Claude Code skill — same tier vocabulary, same context profiles, same modes.
Hermes
Drop the skill into Hermes's skills directory — it then appears automatically as /avoid-ai-writing, no registration needed:
git clone https://github.com/conorbronsdon/avoid-ai-writing ~/.hermes/skills/writing/avoid-ai-writing
OpenAI Codex
Codex reads Agent Skills in the same SKILL.md format. Put it in .agents/skills/ at the repo root, or ~/.agents/skills/ to use it across all your projects:
git clone https://github.com/conorbronsdon/avoid-ai-writing .agents/skills/avoid-ai-writing
Native ChatGPT and Codex plugin package
Published in the OpenAI Plugins Directory; install it there for ChatGPT or Codex.
The plugin package keeps the canonical SKILL.md as its editorial authority and provides seven focused Skills:
avoid-ai-writing — uses the canonical audit and rewrite instructionsavoid-ai-writing-router — routes mixed and multi-stage requestsai-writing-detector — runs the bundled deterministic detectorvoice-preserving-rewriter — rewrites returned text while retaining voicefile-edit-in-place — edits only explicitly named filespreservation-verifier — checks meaning and constraints before and after a rewritefalse-positive-reviewer — reviews detector findings that need context
Build and validate the package with:
python3 scripts/package-openai-plugin.py . /tmp/avoid-ai-writing.zip --json
python3 scripts/validate-openai-plugin.py . --json
Other agents
The generated dist/avoid-ai-writing.md (or the Cursor .mdc port) drops into most tools' rules/skills location:
| Tool | Where to put it |
|---|
| Windsurf | .windsurf/rules/avoid-ai-writing.md |
| Cline | .clinerules/avoid-ai-writing.md |
| GitHub Copilot (VS Code) | paste into .github/copilot-instructions.md |
| Claude.ai Projects | paste dist/avoid-ai-writing.md into the project's custom instructions |
| ChatGPT Custom GPTs | paste dist/avoid-ai-writing.md into the GPT's Instructions field |
Triggering the skill
Once installed, ask your assistant to clean up AI writing:
- "Remove AI-isms from this post"
- "Audit this draft for AI tells"
- "Make this sound less like AI"
- "Clean up AI writing in this paragraph"
In rewrite mode (default), the skill returns four sections:
- Issues found — every AI-ism identified, with the text quoted
- Rewritten version — clean version with all AI-isms removed
- What changed — summary of the major edits
- Second-pass audit — re-reads the rewrite and catches any surviving tells
In detect mode, the skill returns two sections:
- Issues found — every AI-ism identified, grouped by severity (P0/P1/P2)
- Assessment — which flags are clear problems vs. patterns that may be intentional or effective in context
Trigger detect mode with: "detect," "flag only," "audit only," "just flag," "scan," or similar.
Pattern reference
Representative examples from the catalog — not the exhaustive list (that's SKILL.md). The skill's human-facing prose catalog and the detector engine use different counts on purpose: the engine implements 54 type categories because it splits the vocabulary tiers and adds stylometric/fingerprint signals (punctuation distribution, function-word entropy, bypass-trick detection) that work as math over a document rather than as a rule you'd look up. The two are mapped in detector/CATEGORIES.md; don't "fix" one count to match the other.
Content Patterns
| # | Pattern | Before | After |
|---|
| 1 | Significance inflation | "marking a pivotal moment in the evolution of..." | "was founded in 2019 to solve X" |
| 2 | Notability name-dropping | "cited in NYT, BBC, and Wired" | "In a 2024 NYT interview, she argued..." |
| 3 | Superficial -ing analyses | "symbolizing... reflecting... showcasing..." | Replace with specific facts or cut |
| 4 | Promotional language | "nestled within the breathtaking region" | "is a town in the Gonder region" |
| 5 | Vague attributions | "Experts believe it plays a crucial role" | "according to a 2019 survey by Gartner" |
| 6 | Formulaic challenges | "Despite challenges... continues to thrive" | Name the challenge and the response |
| 7 | Novelty inflation | "He introduced a term I hadn't heard before" | "He walked through how X works in practice" |
Language Patterns
| # | Pattern | Before | After |
|---|
| 8 | Word/phrase replacements (3 tiers) | "leverage... robust... seamless... utilize" | "use... reliable... smooth... use" |
| 9 | Copula avoidance | "serves as... features... boasts" | "is... has" |
| 10 | Synonym cycling | "developers... engineers... practitioners... builders" | "developers" (repeat the clear word) |
| 11 | Template phrases | "a [adj] step towards [adj] infrastructure" | Describe the specific outcome |
| 12 | Filler phrases | "In order to," "Due to the fact that" | "To," "Because" |
| 13 | False ranges | "from the Big Bang to dark matter" | List the actual topics |
| 14 | Parenthetical hedging | "tools (like X and Y)" | Name them directly or cut |
Structure Patterns
| # | Pattern | Before | After |
|---|
| 15 | Formatting | Em dashes (— and --), bold overuse, emoji headers, bullet-heavy | Commas/periods, prose paragraphs |
| 16 | Sentence structure | "It's not X, it's Y" + hollow intensifiers + hedging | Direct positive statements |
| 17 | Structural issues | Uniform paragraphs, formulaic openings, too-clean grammar | Varied length, lead with the point |
| 18 | Transition phrases | "Moreover," "Furthermore," "In today's [X]" | "and," "also," or restructure |
| 19 | Inline-header lists | "Speed: Speed improved by..." | Write the point directly |
| 20 | Title case headings | "Strategic Negotiations And Partnerships" | "Strategic negotiations and partnerships" |
| 21 | Numbered list inflation | "Here are 7 reasons why..." | Cut to the 2-3 that matter |
| 22 | False concession | "While X has limitations, it's still remarkable" | State the real tradeoff |
| 23 | Rhetorical question openers | "What if there were a better way to...?" | Lead with the claim |
Communication Patterns
| # | Pattern | Before | After |
|---|
| 24 | Chatbot artifacts | "I hope this helps! Let me know if..." | Remove entirely |
| 25 | "Let's" constructions | "Let's explore," "Let's break this down" | Just start with the point |
| 26 | Cutoff disclaimers | "While details are limited in available sources..." | Find sources or remove |
| 27 | Generic conclusions | "The future looks bright," "Only time will tell" | Specific closing thought or cut |
| 28 | Emotional flatline | "What surprised me most," "I was fascinated to discover" | Earn the emotion or cut the claim |
| 29 | Reasoning chain artifacts | "Let me think step by step," "Breaking this down" | State conclusion, then evidence |
| 30 | Sycophantic tone | "Great question!", "You're absolutely right!" | Remove entirely |
| 31 | Acknowledgment loops | "You're asking about," "To answer your question" | Just answer directly |
| 32 | Confidence calibration | "It's worth noting," "Interestingly," "Surprisingly" | Let the fact speak for itself |
Meta Patterns
| # | Pattern | Before | After |
|---|
| 33 | Excessive structure | 5 headers in 200 words, "Overview:", "Key Points:" | Merge sections, use specific headers |
| 34 | Rhythm and uniformity | All sentences 15–25 words, all paragraphs same length | Mix short/long, fragments, questions |
| 35 | Over-polishing | Every irregularity sanded away, perfectly uniform prose | Keep natural disfluency, varied rhythm |
| 36 | Rewrite-vs-patch threshold | 5+ vocabulary flags + 3+ pattern categories + uniform rhythm | Advise full rewrite, not patching |
Structural Detection (v3.4)
Added in v3.4 to catch LLM output that sidesteps the vocabulary tables by substituting synonyms but still leans on structural shapes detectors can identify. Crypto/web3/AI-infra content is where these patterns concentrate most heavily, but the rules generalize to any social-length post.
| # | Pattern | Before | After |
|---|
| 37 | Tier 3 phrases (multi-word boilerplate) | "the integration of," "decentralized compute," "community-driven," "long-term sustainability" stacked across a piece | Replace the repeated phrase with a specific claim, or vary genuinely. Flagged per-phrase at ≥2 hits, or as a cluster when ≥3 distinct phrases appear |
| 38 | Future-narrative closers | "may become one of the most important narratives of the next market cycle" | Pick the falsifiable version. "X may exceed Y by 2027" is a prediction; the template form is not |
| 39 | Hedge-stacked predictions | "could potentially create," "may eventually unlock" | Pick one. Each hedge cancels the next |
| 40 | "Real/actual" adjective inflation | "real on-chain tokenomics," "actual reward sustainability" | Drop the empty intensifier and add the specific claim. Carve-out: "real on-chain settlement, not bridged IOUs" is honest contrastive writing — the AI tell is the unsaid contrast |
| 41 | Hashtag stuffing | 15-tag trailing block: #AI #Crypto #Web3 #Innovation #FutureTech… | 2-3 specific tags max, or none. Empirical threshold: 6+ tags is near-universal in LLM social output, rare in thoughtful human posts |
| 42 | Bullet lists of bare noun phrases | * Stable mining efficiency / Reliable pool connectivity / Optimized RandomX performance / Low failed share rates / Effective hardware utilization / Consistent thermal stability | Convert to prose, or rewrite each item as a full claim with a verb and a number. Carve-out: genuine list content (changelogs, parameter docs, ingredient lists) where bare NPs are correct |
AI-tool fingerprints & later additions (v3.5–3.8)
| # | Pattern | Before | After |
|---|
| 43 | Unfilled placeholders | [Your Name], [INSERT SOURCE], 2025-XX-XX | Fill in with real content or delete — shipped placeholders are a near-definitive tell |
| 44 | Chatbot citation markup | citeturn0search0, oai_citation, contentReference[oaicite:0] | Strip the markup token entirely |
| 45 | AI-tool URL parameters | utm_source=chatgpt.com, utm_source=copilot.com | Strip the tracking parameter; keep the URL if the link matters |
| 46 | Speculative gap-filling | "maintains a low profile," "likely began his career" | Cut the guess, or replace with a sourced fact |
| 47 | Hyphenated modifier stacking | "a high-quality, well-architected, future-proof solution" | Cut to the modifier that matters; the individual hyphens may be correct |
| 48 | Infomercial engagement hooks | "The catch?", "The kicker?", "Here's the thing." | Delete the hook, state the thing |
| 49 | Vocabulary diversity (low TTR) | Narrow, repetitive word range across 200+ words | Broaden the what — name specific things, cite specific cases |
| 50 | Self-labeling significance | "That last move is the contrarian one," "This is the interesting part" | Cut the label; let the explanation carry the weight, or reposition the item so it stands out on its own |
| 51 | List-label periods | - **Intros.** Years of conferences and operator network. (also unbolded: - Intros. Years of...) | Use a colon, not a period, on a list label: - **Intros:** years of conferences and operator network. |
Conversational-register patterns (v3.15)
Added after a real-world exchange in which a maintainer called out an assisted-sounding GitHub issue reply with "I prefer to talk human to human." Both are judgment calls rather than regex-detectable (an ordinary human paragraph and an AI-generated one can look structurally identical; the tell is the register and the redundant context, not a fixed shape) — see the detector/CATEGORIES.md §C note for why a first attempt at a wall-of-text detector was reverted.
| # | Pattern | Before | After |
|---|
| 52 | Wall-of-text replies | A 4+ sentence, sub-150-word reply delivered as one unbroken paragraph with no line breaks — the shape LLMs default to in issue/PR comments, chat, and DMs | Break at thought boundaries. One idea per line-group, the way a person actually types a reply |
| 53 | Recap-flattery opener | "Thanks for all the legwork here — the migration script and the rollback plan you worked through are what made this possible." | Substance first. If thanks is warranted, one plain clause without the recap: "Thanks for the legwork — this looks right to me" |
Share-post framing (v3.20)
| # | Pattern | Before | After |
|---|
| 54 | Lingering-attention claims | "The line I keep coming back to:", "I can't stop thinking about this," "this has been rattling around in my head all week" | Open on the thing itself. Carve-out: keep the frame when a reason follows ("I keep coming back to exit-voice because it predicts who quits") |
Narrated candor (v3.21)
| # | Pattern | Before | After |
|---|
| 55 | Narrated candor | "Two caveats I would rather flag than let you discover later:", "I want to be upfront:" | State the caveats. Judgment-only: the same words carry real content in conflict-of-interest disclosure ("in the interest of full disclosure, I own shares in…"), which a regex cannot separate from the empty frame |
Unnecessary hyphenation (v3.24)
| # | Pattern | Before | After |
|---|
| 56 | Unnecessary hyphenation | "research-impact aggregator," "code-base," "in real-time," "works out-of-the-box" | "research impact aggregator," "codebase," "in real time," "works out of the box." Preserve legitimate modifiers such as "real-time analytics" |
Two writer-side tests round out the catalog (judgment checks, not auto-detected): paragraph-reshuffle immunity (can you swap two body paragraphs without breaking the piece?) and the treadmill effect ("what's actually new in this paragraph?").
Full Example
Before (AI-generated):
Certainly! Here's a comprehensive overview of Acme's Series B.
Acme Analytics, a vibrant startup nestled in the heart of Boulder's thriving tech ecosystem, has secured $40M in Series B funding — marking a watershed moment for the company and the observability landscape at large. The round was led by Sequoia, with participation from Andreessen Horowitz, Y Combinator, and Index Ventures, underscoring the robust investor confidence in Acme's vision.
The platform serves as a unified hub for engineering teams, featuring real-time dashboards, boasting sub-second query performance, and presenting a seamless integration layer. It's not just another monitoring tool — it's a paradigm shift in how organizations navigate complex distributed systems. Experts believe Acme is poised to disrupt the $15B observability market. Studies show that companies utilizing comprehensive monitoring solutions can ascertain issues 40% faster.
- 🚀 Performance: The platform streamlines incident response, empowering engineers to resolve issues faster.
- 💡 Scale: Acme fosters collaboration across teams, from frontend developers to SRE practitioners to platform builders to infrastructure engineers.
- ✅ Adoption: Customer adoption continues to accelerate, reflecting broader industry trends.
Moreover, Acme's approach showcases the potential of modern observability — symbolizing a shift toward proactive monitoring, reflecting years of R&D investment, and highlighting the intricate interplay between data collection and actionable intelligence. Despite challenges common in the crowded monitoring space, Acme continues to thrive. In order to fully capitalize on this momentum, the company plans to expand its go-to-market endeavors.
In conclusion, the future looks bright for Acme Analytics. Only time will tell how this game-changer will reshape the observability paradigm. Feel free to reach out if you'd like more details!
After (cleaned up):
Acme Analytics raised a $40M Series B led by Sequoia. The Boulder-based startup makes an observability platform that runs queries in under a second and plugs into existing monitoring stacks without custom integration work.
The pitch is speed. Their median time-to-resolution is 12 minutes, compared to the 45-minute industry average that Datadog reported in 2024. That gap is why 380 companies are paying for it.
They'll use the money to hire sales reps in EMEA and add log management. The monitoring market is crowded, but Acme's bet is that most teams still stitch together three or four tools and lose time switching between them.
What the skill caught: chatbot artifacts (Certainly!, Feel free to reach out), 3 em dashes, promotional language (vibrant, nestled, thriving), significance inflation (watershed moment), copula avoidance (serves as, featuring, boasting, presenting), 10 word replacements (landscape, robust, seamless, paradigm, streamline, empower, foster, utilize, ascertain, endeavor), synonym cycling (developers/practitioners/builders/engineers), negative parallelism (It's not just X, it's Y), notability name-dropping (Sequoia, a16z, YC, Index stacked for credibility), vague attributions (Experts believe, Studies show), filler phrases (In order to, Moreover), inline-header list with emoji, superficial -ing analysis (symbolizing... reflecting... highlighting...), formulaic challenges (Despite challenges... continues to thrive), generic conclusion (the future looks bright, only time will tell), false range implied in the adoption bullet.
That's 35+ AI tells.
Run the detector
The skill ships a deterministic, zero-dependency detection engine in
detector/ — the same engine the rules above
describe, as runnable code. It works in Node (>=18) and the browser with no
build step.
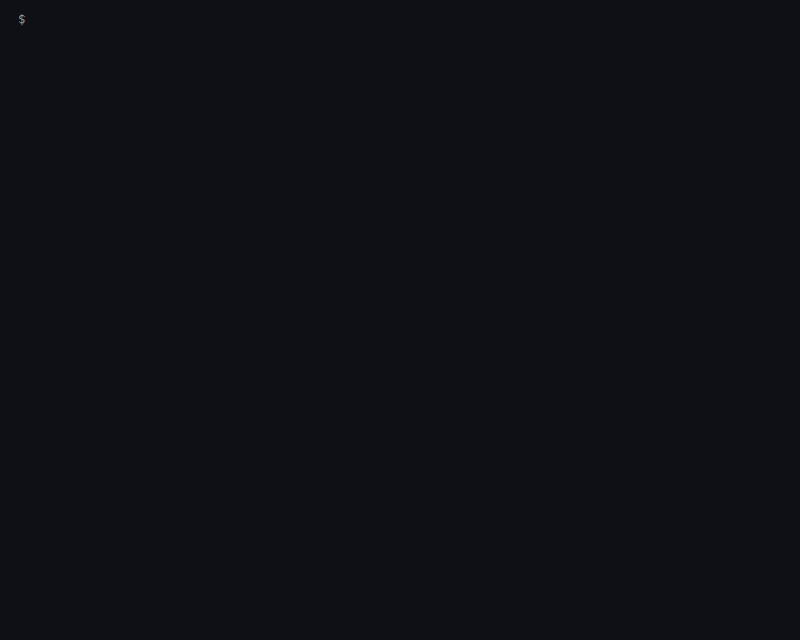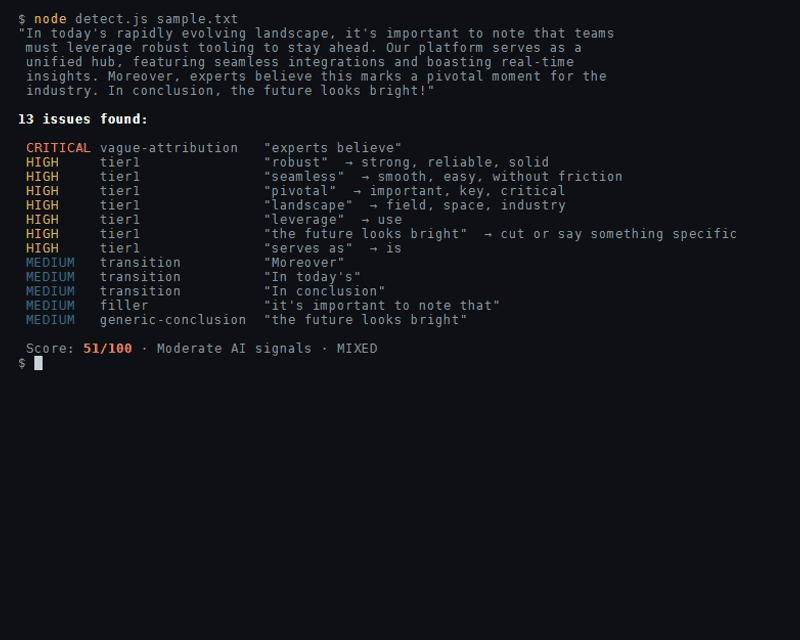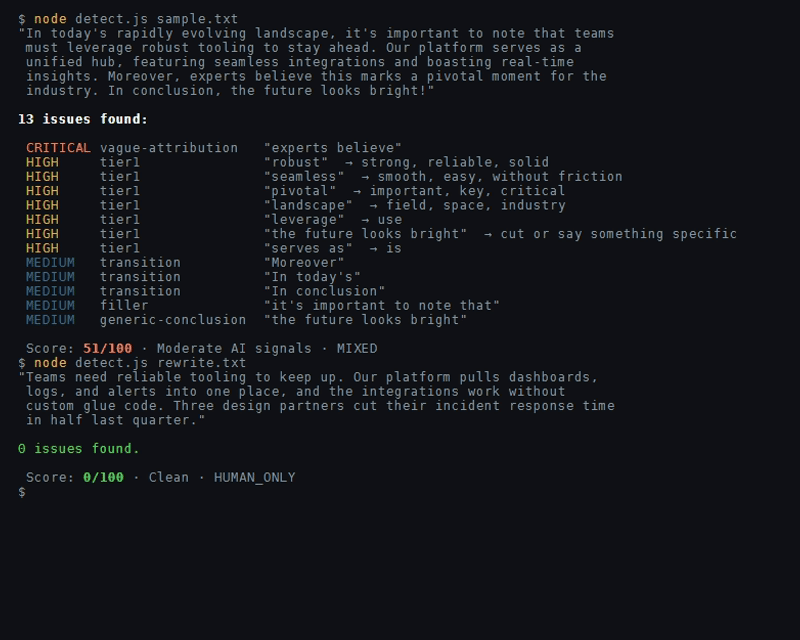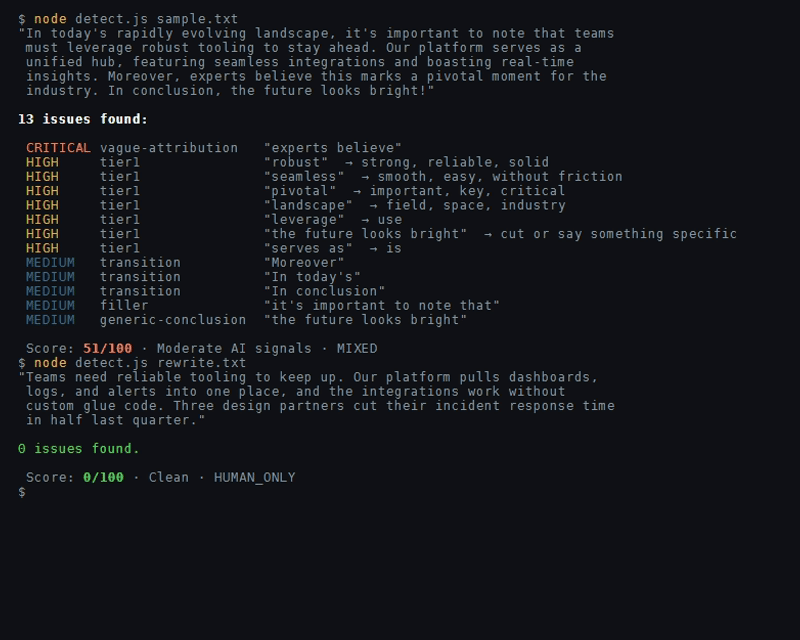
It's also the single source of the numeric score: the skill itself (and detect mode) report which patterns are present and how severe (P0/P1/P2), and the engine is what turns those into one computed 0–100 score. There's deliberately no second, prose-estimated score in SKILL.md — one scorer, not two.
npm test # run the detector's fixtures (no deps to install)
const AIDetector = require("./detector/patterns.js");
const { score, label, issues } = AIDetector.analyzeText("Your text here…");
When the input is a Markdown source file, pass
{ sourceMode: "rendered-markdown" } to exclude initial YAML frontmatter and
HTML comments from the score while keeping issue offsets aligned with the
original file. Plain-text behavior remains the default.
See detector/README.md for the full analyzeText API
and detector/CATEGORIES.md for the rule ↔ category
map that keeps SKILL.md and the engine in sync.
Use the detector over MCP
avoid-ai-writing-mcp
wraps the published detector as a local stdio MCP server. It exposes two
read-only tools: score_text for a compact result and audit_text for the full
list of findings, suggestions, statistics, and highlighted sentence regions.
claude mcp add avoid-ai-writing -- npx -y avoid-ai-writing-mcp@0.1.0
The server calls no model and sends no text to a network service. It
intentionally has no rewrite tool; rewriting stays in the skill, where the
agent can apply the full editorial rules and preservation guardrails. See the
MCP repository for
configuration examples for other MCP hosts.
The engine also ships a preservation validator. detector/validate.js compares
a rewrite against its original and fails when the edit touched something it
shouldn't have: a code block, YAML frontmatter, a blockquote, a table cell,
inline code, a URL, a file path, the heading structure, or when the rewrite ends
with more flagged patterns than it started with.
node detector/validate.js before.md after.md # exits 1 on a preservation error
Does it pass its own pass? PROOF.md scores this repo's
documentation with this repo's detector and publishes the result, including two
defects the scan found in our own work. npm run self-scan reproduces it, and
CI fails when a document drifts past its budget.
House style is a different job
This skill removes AI-writing tells. Enforcing a published style guide is the
different job: it doesn't do that, and it ships no style guides of its own. The
optional --style input takes a house-style config you supply: a register list
the model applies, and a mechanics object whose checkable rules
scripts/check-style.js verifies deterministically (quote form and Latin
abbreviations gate the exit code; heading case, em-dash rate, and number spelling
are advisory). examples/ has the schema. You can skip the input
entirely and put your guide in your agent's context alongside a
voice profile, as instructions rather than as a checked
rule set.
After a rewrite, node scripts/normalize-quotes.js draft.md --reference original.md
prints prose marks normalized to the original document's convention; add --write
to save it. Explicit --quotes straight|curly overrides inference. It shares the
checker's Markdown protection. See the
usage and limits.
If you want Google, Microsoft, Red Hat, or Salesforce style checked in CI,
Vale already covers that. Its
package registry carries
Vale-compatible implementations of those four, alongside ports of proselint,
write-good, and alex. The four style-guide packages are MIT-licensed, though
the guides they implement are not always (see the audit below); the linter ports
vary, and proselint's is BSD-3-Clause. The two tools do different jobs and
compose: Vale gates a document against a rule set, applying fixes one alert at a
time, while this skill rewrites whole passages as you draft.
Paywalled guides (Chicago, APA, MLA, AP) have no machine-readable
implementation here or in Vale, and won't get one here. Nothing in this repo
could verify that a rewrite is Chicago-compliant, so claiming it would fail the
same bar PROOF.md holds every other number to. Passing one of
their names to --style bundles nothing; it falls back to the model's own
knowledge, and SKILL.md instructs it to say so and to claim no compliance.
That is an instruction rather than a checked rule, which is the point: there is
nothing here to check it against. The
license audit
behind that line is public.
More from me
I run agents against my own email, money, and publishing, so I build the
guardrails first.
Follow me on GitHub for new tools and practical examples from maintaining them.
- What I'm building — public projects across agent skills, MCP servers, creator tools, and Mojo.
- Chain of Thought — conversations with the people shipping AI systems.
- repo-audit — checks whether repository claims are enforced, advisory, or guidance.
Credits
Pattern research informed by:
- Pangram Labs AI detection research — structural regularity insights, vocabulary flags from a decoder-only classifier trained on 28M human documents
- Wikipedia's Signs of AI-generated text documentation — the canonical reference for AI writing tells, maintained by Wikipedia editors
- blader/humanizer Claude Code skill
- brandonwise/humanizer — tiered vocabulary system, statistical analysis research (burstiness, sentence length variation, trigram repetition), and rewrite philosophy
- OpenClaw humanizer skill ecosystem — community patterns and vocabulary research
Pull requests get an automated first-pass review from Qodo Merge, free through Qodo's open source program. Thanks to the Qodo team for supporting OSS maintainers.
Authored by Conor Bronsdon · LinkedIn · Chain of Thought podcast
Community / Multilingual
Things the community has built around this skill:
- avoid-ai-writing-multilingual by Jürgen Kraus — German (
SKILL-DE.md), French (SKILL-FR.md), Italian (SKILL-IT.md), Romanian (SKILL-RO.md), and Swedish (SKILL-SV.md) adaptations, grounded in native-language research rather than translated from English.
Built something on top of this skill? Open an issue — happy to link it here.
Disclaimer
This is an independent personal project, not affiliated with, sponsored by, or endorsed by any company. All views expressed are my own.
License
MIT