wshobson/
commands

wshobson/commandsRules & Prompts
A collection of production-ready slash commands for Claude Code
2.6k
A collection of production-ready slash commands for Claude Code
Plugin for JADX to integrate MCP server

Security layer for AI coding agents. Works with Claude Code, Cursor, Windsurf, Gemini CLI, OpenCode, Pi Agent and more.
A collection of agent plugins for improving productivity, automating workflows, and making AI coding agents work better together.
MCP server for JADX-AI Plugin
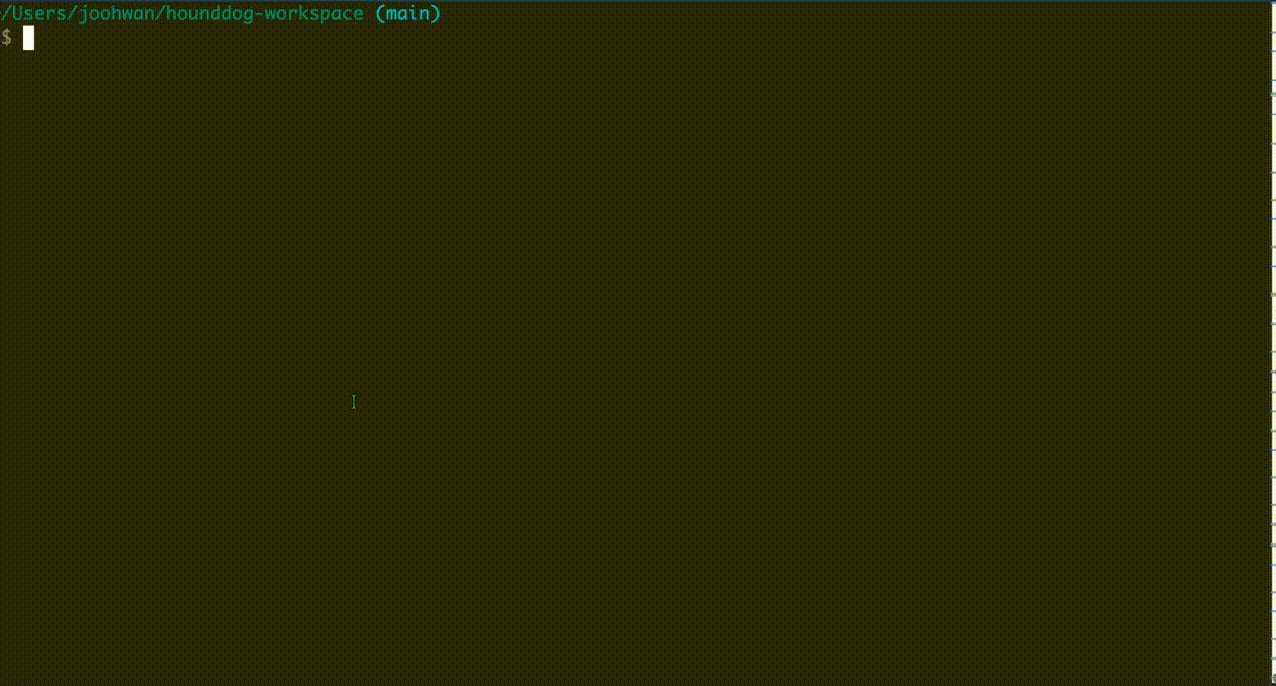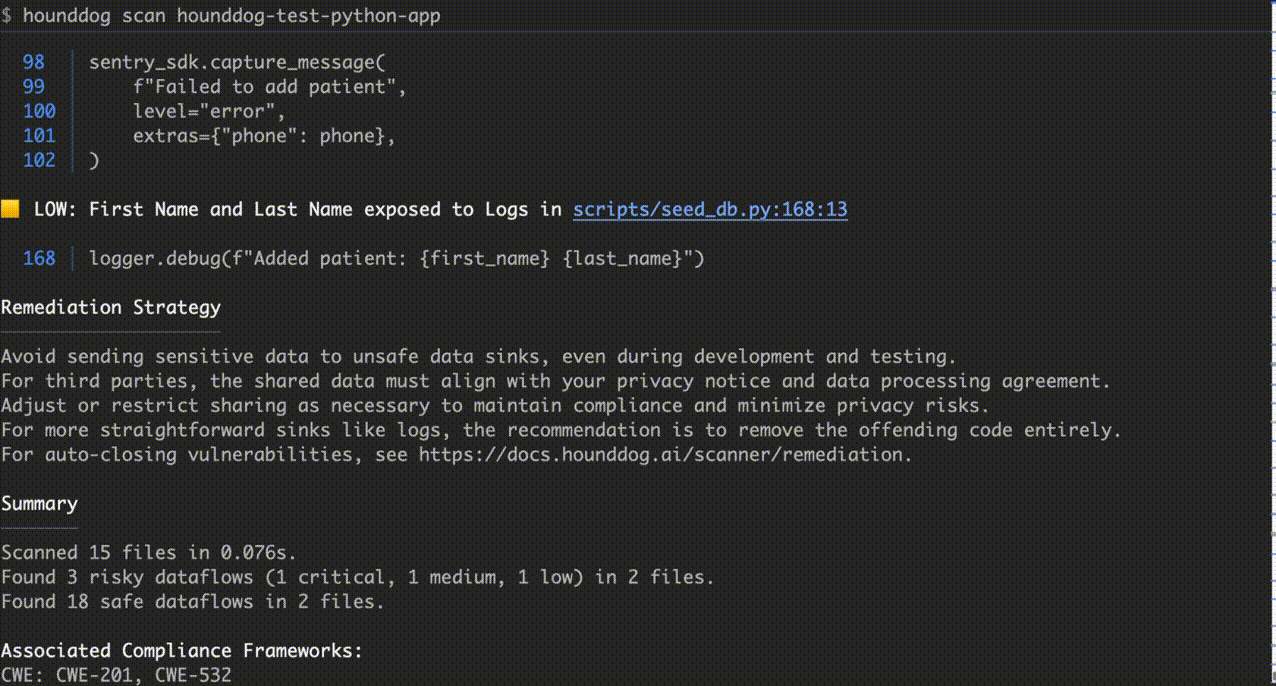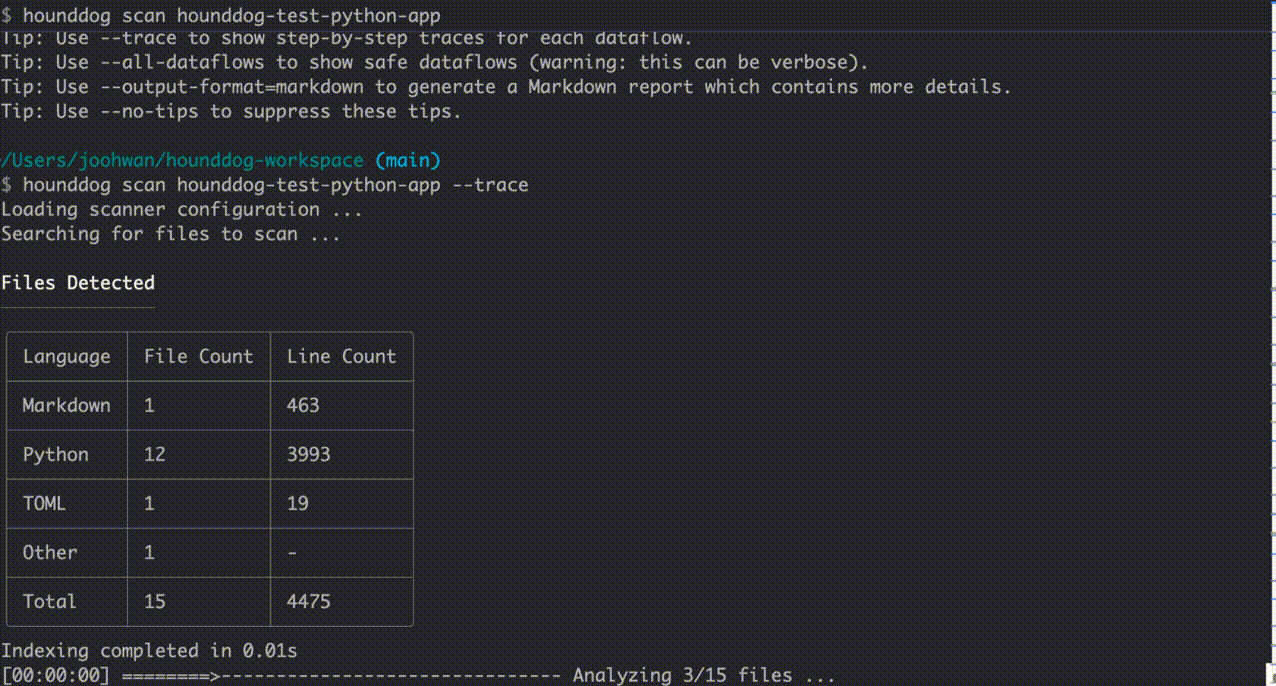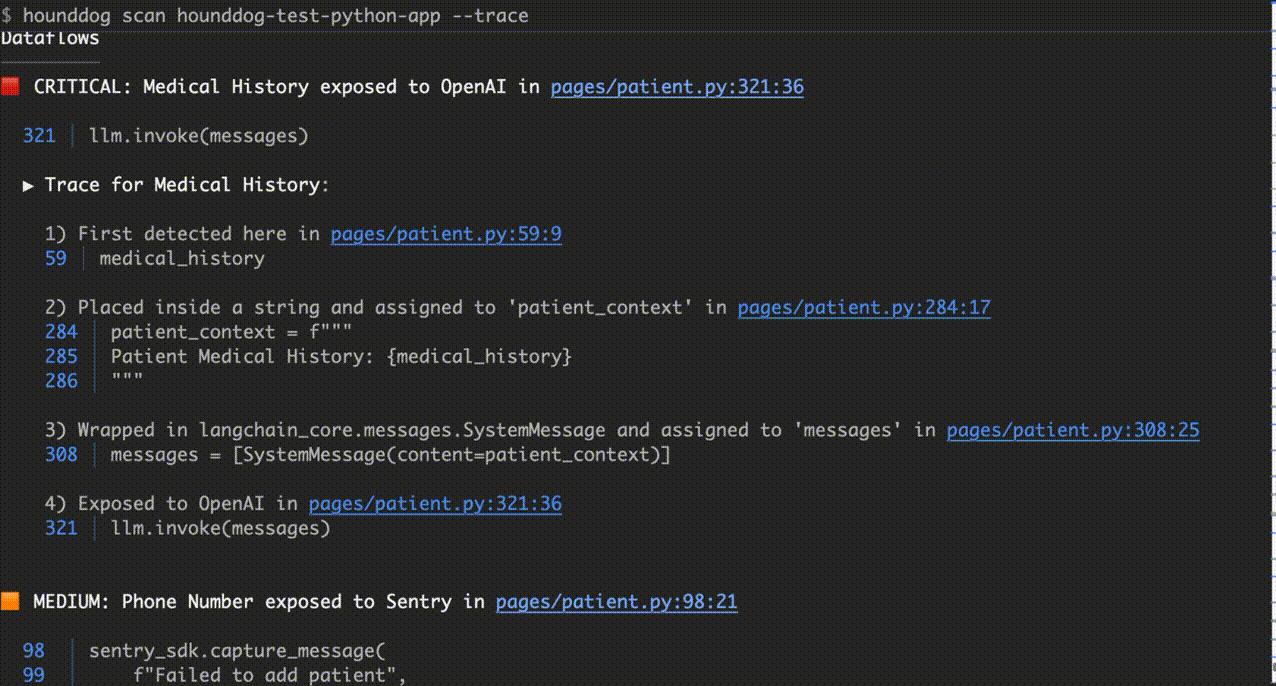
Privacy Code Scanner and Dataflow Context Engine for AI coding agents

AI agent security scanner. Detect vulnerabilities in agent configurations, MCP servers, and tool permissions. Available as CLI, GitHub Action, ECC plugin, and GitHub App integration. 🛡️

A growing collection of MCP servers bringing offensive security tools to AI assistants. Nmap, Ghidra, Nuclei, SQLMap, Hashcat and more.

✨ A customizable copilot-instructions.md ruleset & prompts to guide GitHub Copilot toward secure coding defaults in Java, Node.js, C# and Python. Blocks risky patterns, teaches safe habits.

Claude Code skill for OWASP security best practices (2025-2026). Includes Top 10:2025, ASVS 5.0, Agentic AI security, and 20+ language-specific security quirks.

Governance runtime for Claude Code. Enforces workflow gates at tool time, delivers the engineering rules relevant to the work, and preserves decision provenance across sessions.

Local-first MCP security scanner for AI-generated apps. Scan → fix → rescan from Claude Code, Cursor, Codex, and other agents.

Static Code Analysis for security teams with Inter file taint analysis. Built for finding vulnerabilities, advanced structural search, derive insights and supports MCP

Kubernetes Skill for Claude Code and Codex. LLMs hallucinate a lot with K8s - KubeShark fixes this. It eliminates hallucinations and grounds your Kubernetes, Helm etc official best practices.

Local-only Go static analysis engine with a built-in MCP server. Gives AI coding agents deterministic structural awareness: call graphs, impact analysis, symbol search, and more.
A Free, Open Source MCP server for dynamic custom persona management with public a GitHub collection of personas, skills, templates, and other elements for AI models.
A local MCP runtime that attacks what you own and only reports what it proved. 17 CVEs across 9 projects came out of this repo. Install: npx -y hacker-bob@latest install /path/to/project, then run /bob-evaluate target.com

🐉 Hail Hydra — Multi-headed speculative execution framework for Claude Code. 10 AI agents, 3x faster, ~70% cheaper. Inspired by speculative decoding.

Open-source security skills for AI coding agents. Grounded in OWASP, NIST, MITRE ATT&CK, CIS. Works with Claude Code, Gemini CLI, Cursor, Codex CLI, OpenClaw, Kiro.

Security scanner for AI agent skills. Detect vulnerabilities, malicious patterns, security risks, prompt injection, data exfiltration, and supply-chain risks in Claude Code, Codex, and MCP skills before you install them.

SAIL V2 (Secure AI Lifecycle) as an agent skill — the full 91-risk catalog for AI/agent gap assessments, security roadmaps, and compliance checklists. Installs on Claude Code, Codex, ChatGPT, Antigravity, and any SKILL.md-compatible agent.

EOC: open-source operating system for OpenAI Codex workflows with agents, skills, hooks, rules, memory, safety gates, and cross-harness adapters.

CI-native security testing for MCP servers. Attack simulation, schema drift detection, and health scoring before agents depend on them.
Find and repair substance defects in AI-assisted prose, code, docs, and agent output. Reports defects, never authorship. Structural tests over model judgement, because LLM judges agree with human slop labels at chance.