

JuliusBrussee/
caveman

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
105k
1 add
Kappa Graph extracts concepts, relationships, and evidence from documents, then stores them in PostgreSQL with Apache AGE. It tracks grounding strength, preserves disagreements, and lets agents and humans query the graph through the CLI, MCP server, API, or FUSE filesystem.
Builders who want an agent-friendly knowledge graph with source tracing and confidence scores.
You can ask an agent to use grounded memory instead of re-reading or re-explaining the same sources.
Ingests PDFs, markdown, images, and text, then extracts concepts, relationships, and evidence.
Assigns each concept a support measure so you can see what is well evidenced and what is weak or contested.
Keeps disagreeing sources visible instead of forcing one answer.
Lets AI assistants query the graph as persistent memory through MCP.
Mounts the graph so you can browse semantic data with standard Unix tools like `ls`, `grep`, and `find`.
Includes a web explorer for searching, clustering, and tracing relationships in the graph.
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/client-manager.sh | bash
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/install.sh | bash
git clone https://github.com/aaronsb/knowledge-graph-system.git
cd knowledge-graph-system
./operator.sh init    # Interactive setup
./operator.sh start   # Start containers

A semantic knowledge graph that extracts concepts from documents, tracks how well-supported they are, and remembers where sources disagree.
κ(G) — vertex connectivity of a graph. The minimum number of connections you'd need to cut before the graph falls apart. A measure of how robust the structure is.
Also kg — the unit of mass. Because knowledge here has weight. Grounding scores measure how heavy an idea is: well-evidenced claims carry more than thin ones. Contested concepts weigh differently than unchallenged ones.
The kg CLI, MCP server (for AI assistants), and optional FUSE filesystem:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/client-manager.sh | bash
Or just the CLI: npm install -g @aaronsb/kg-cli
Run your own knowledge graph backend:
curl -fsSL https://raw.githubusercontent.com/aaronsb/knowledge-graph-system/main/install.sh | bash
Or from source:
git clone https://github.com/aaronsb/knowledge-graph-system.git
cd knowledge-graph-system
./operator.sh init    # Interactive setup
./operator.sh start   # Start containers
See Quick Start Guide for details.
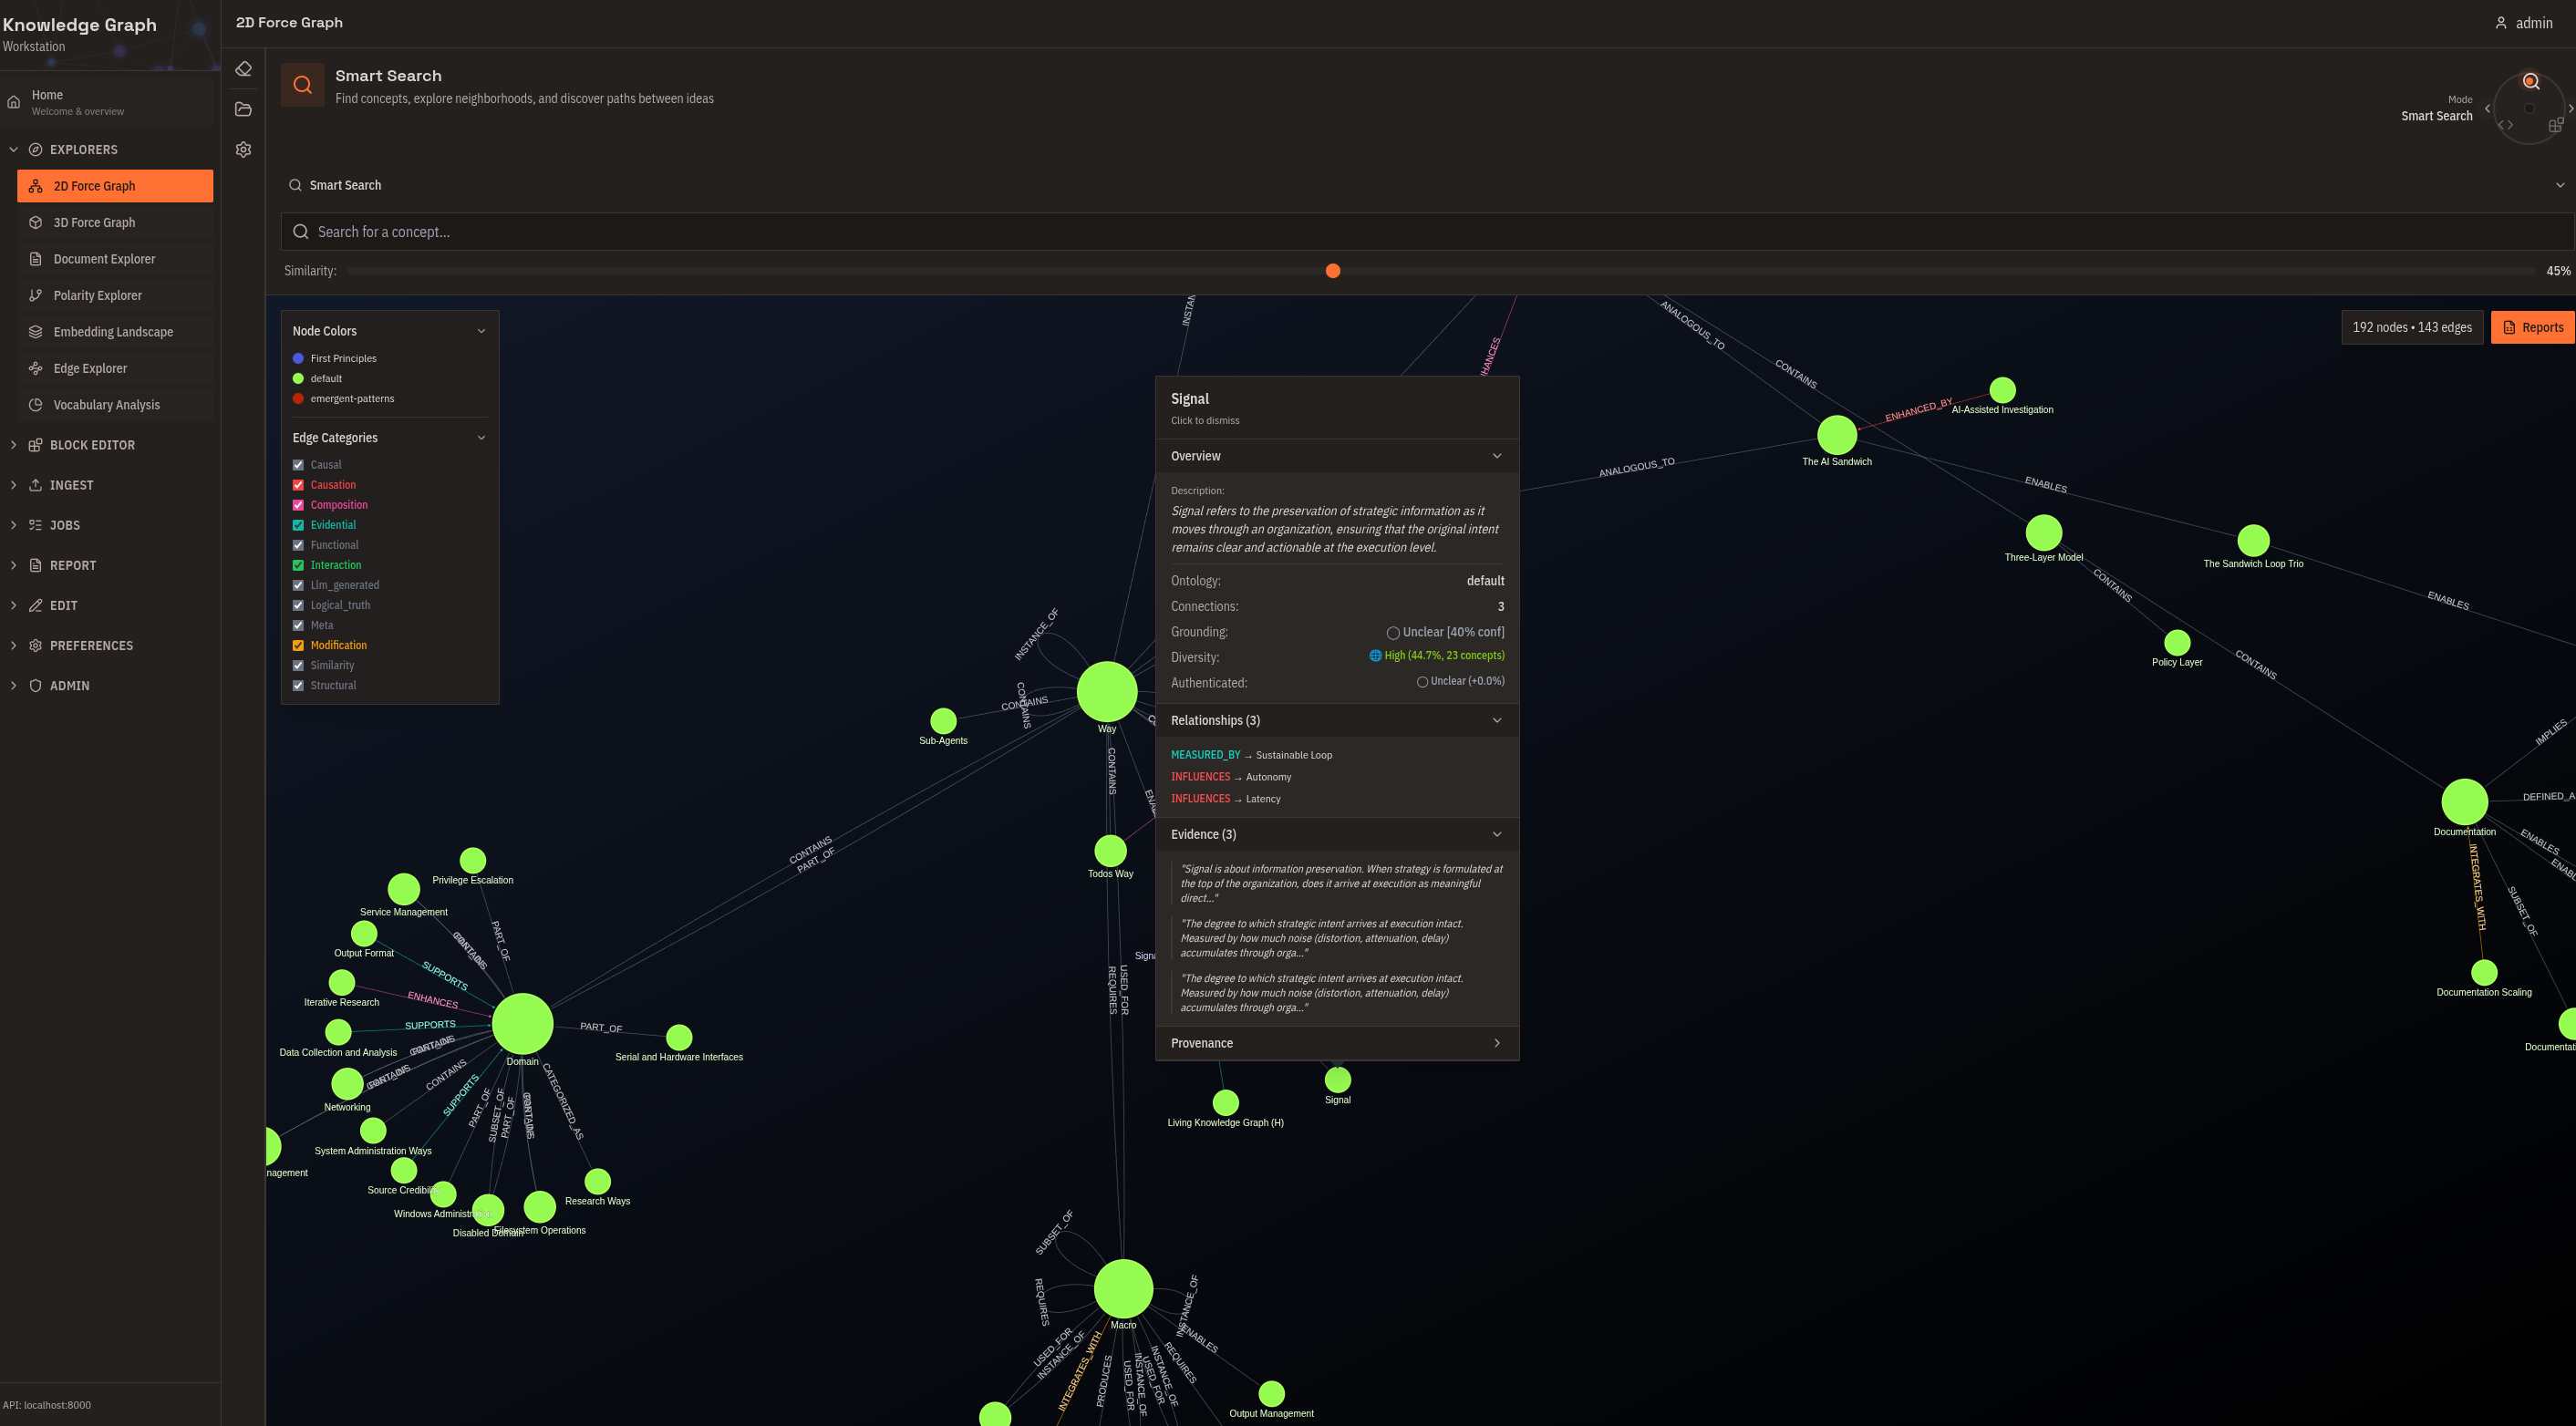
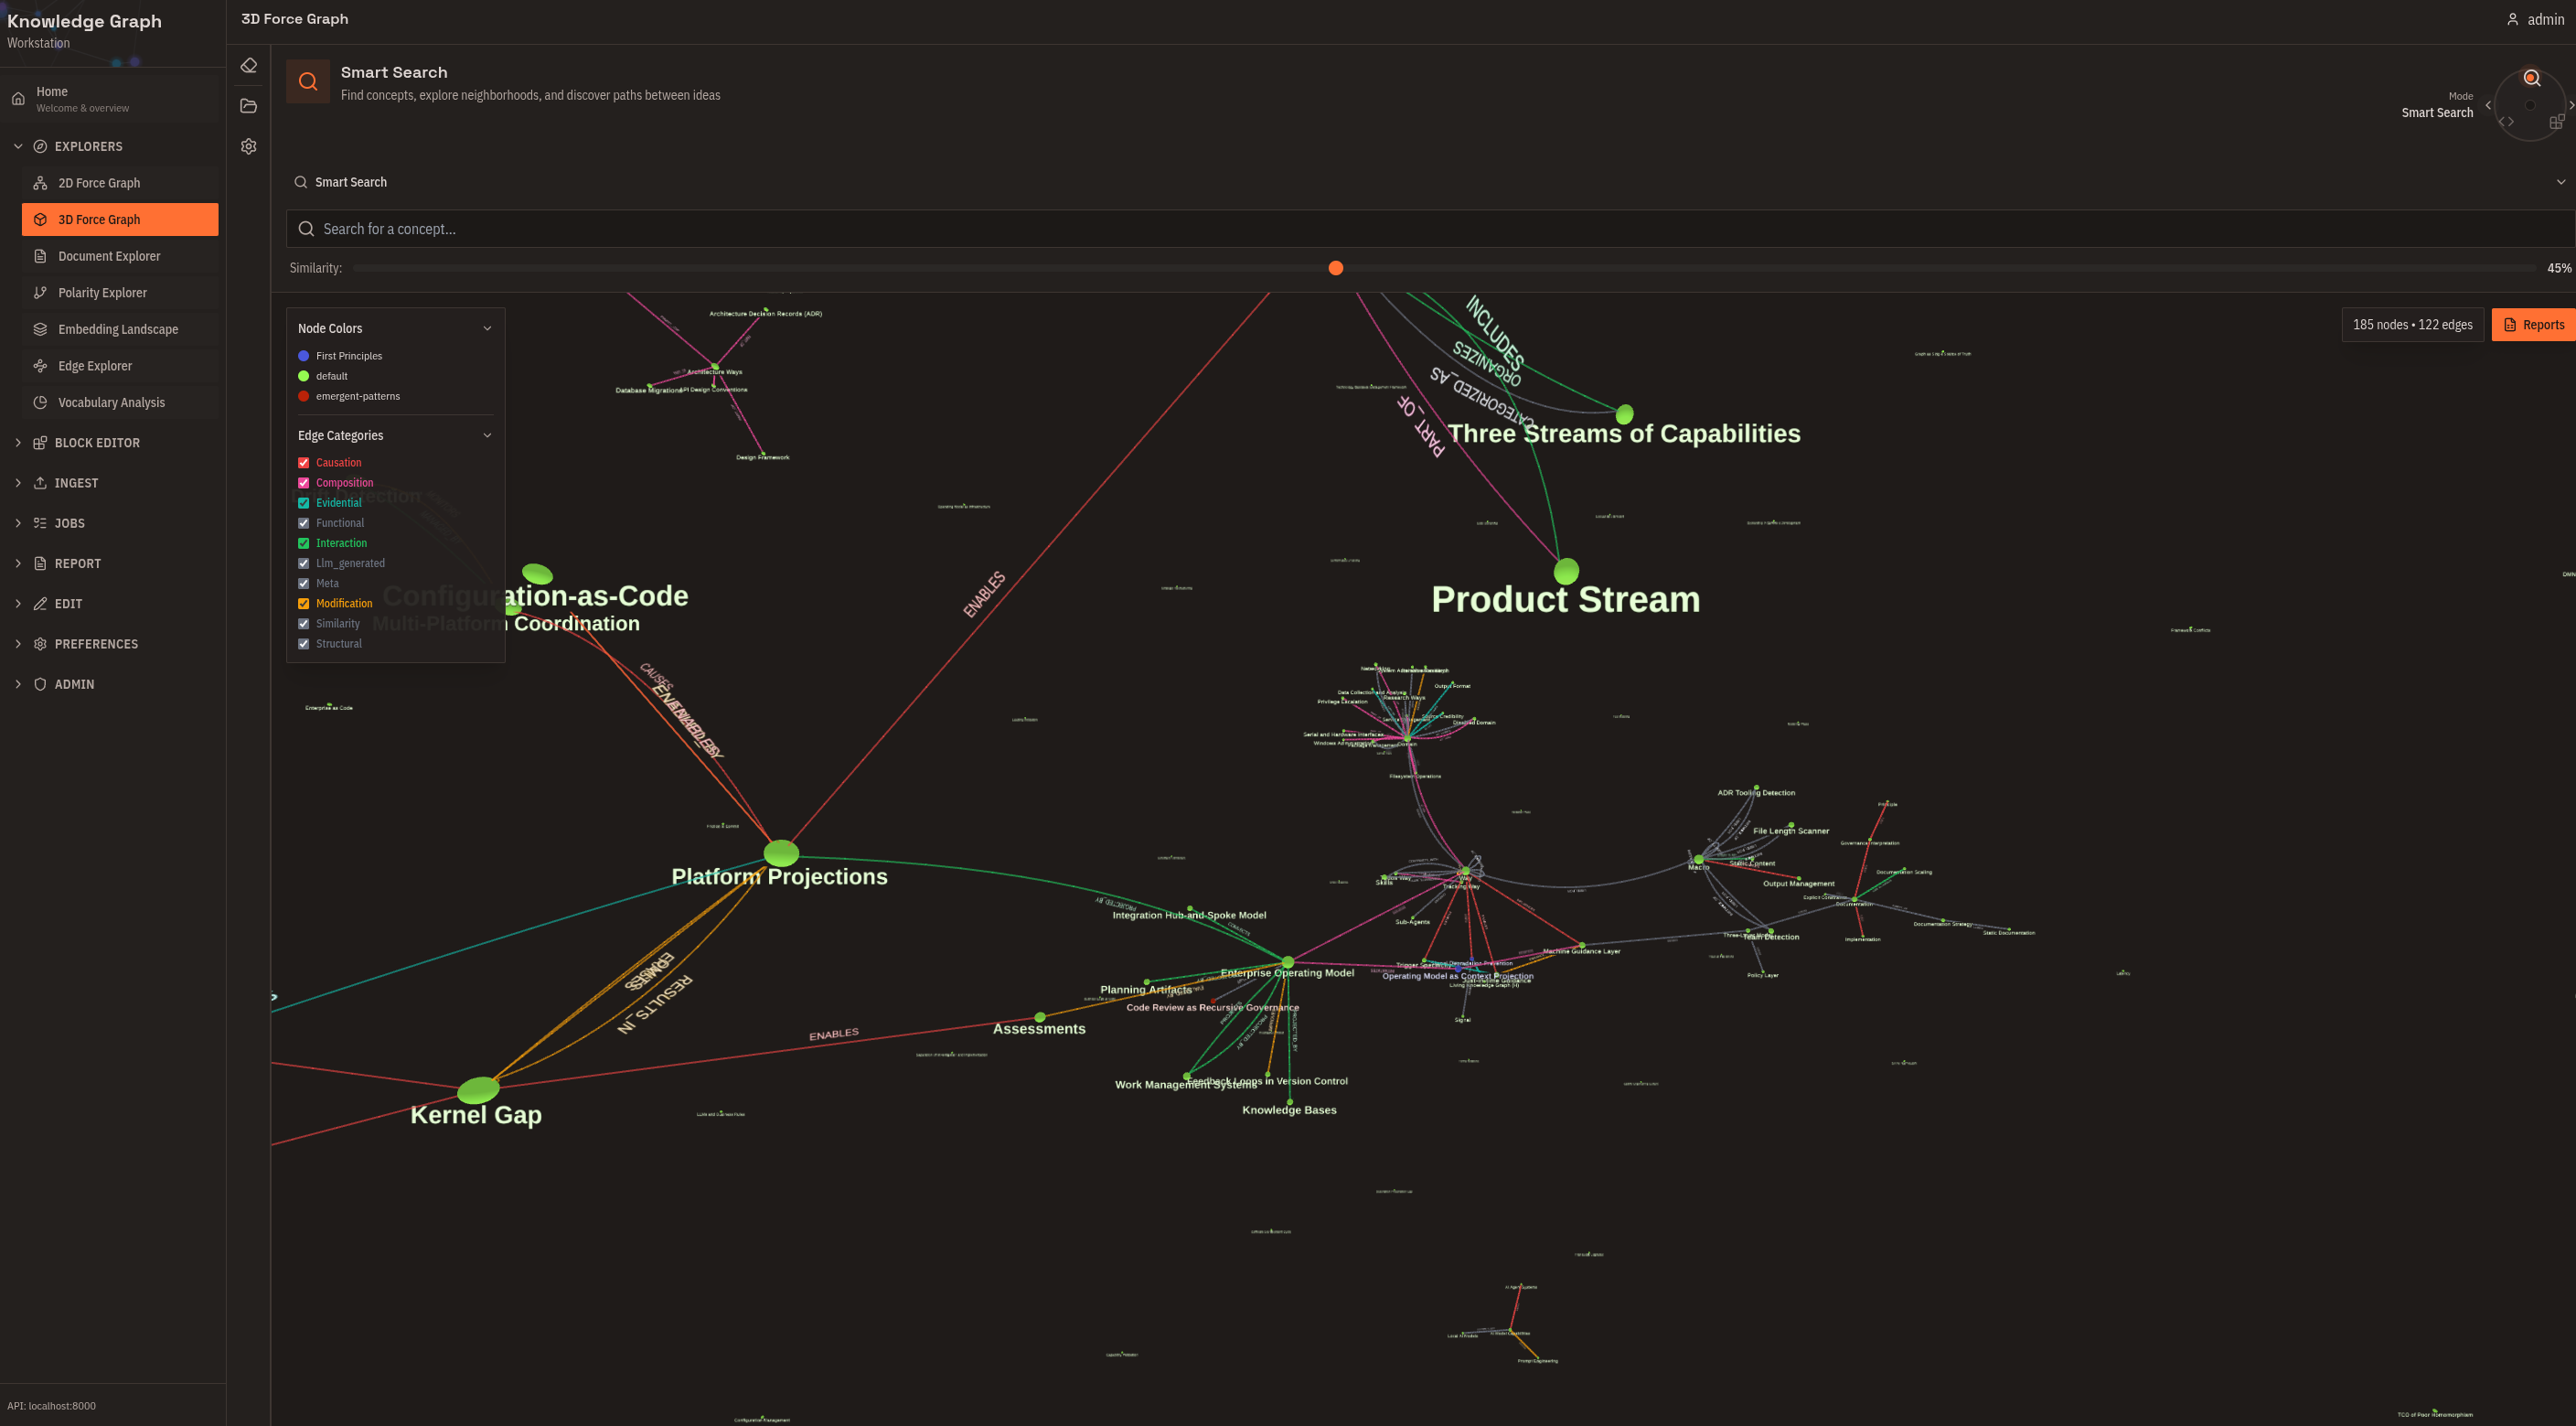 Interactive graph exploration with smart search, concept clustering, and relationship visualization
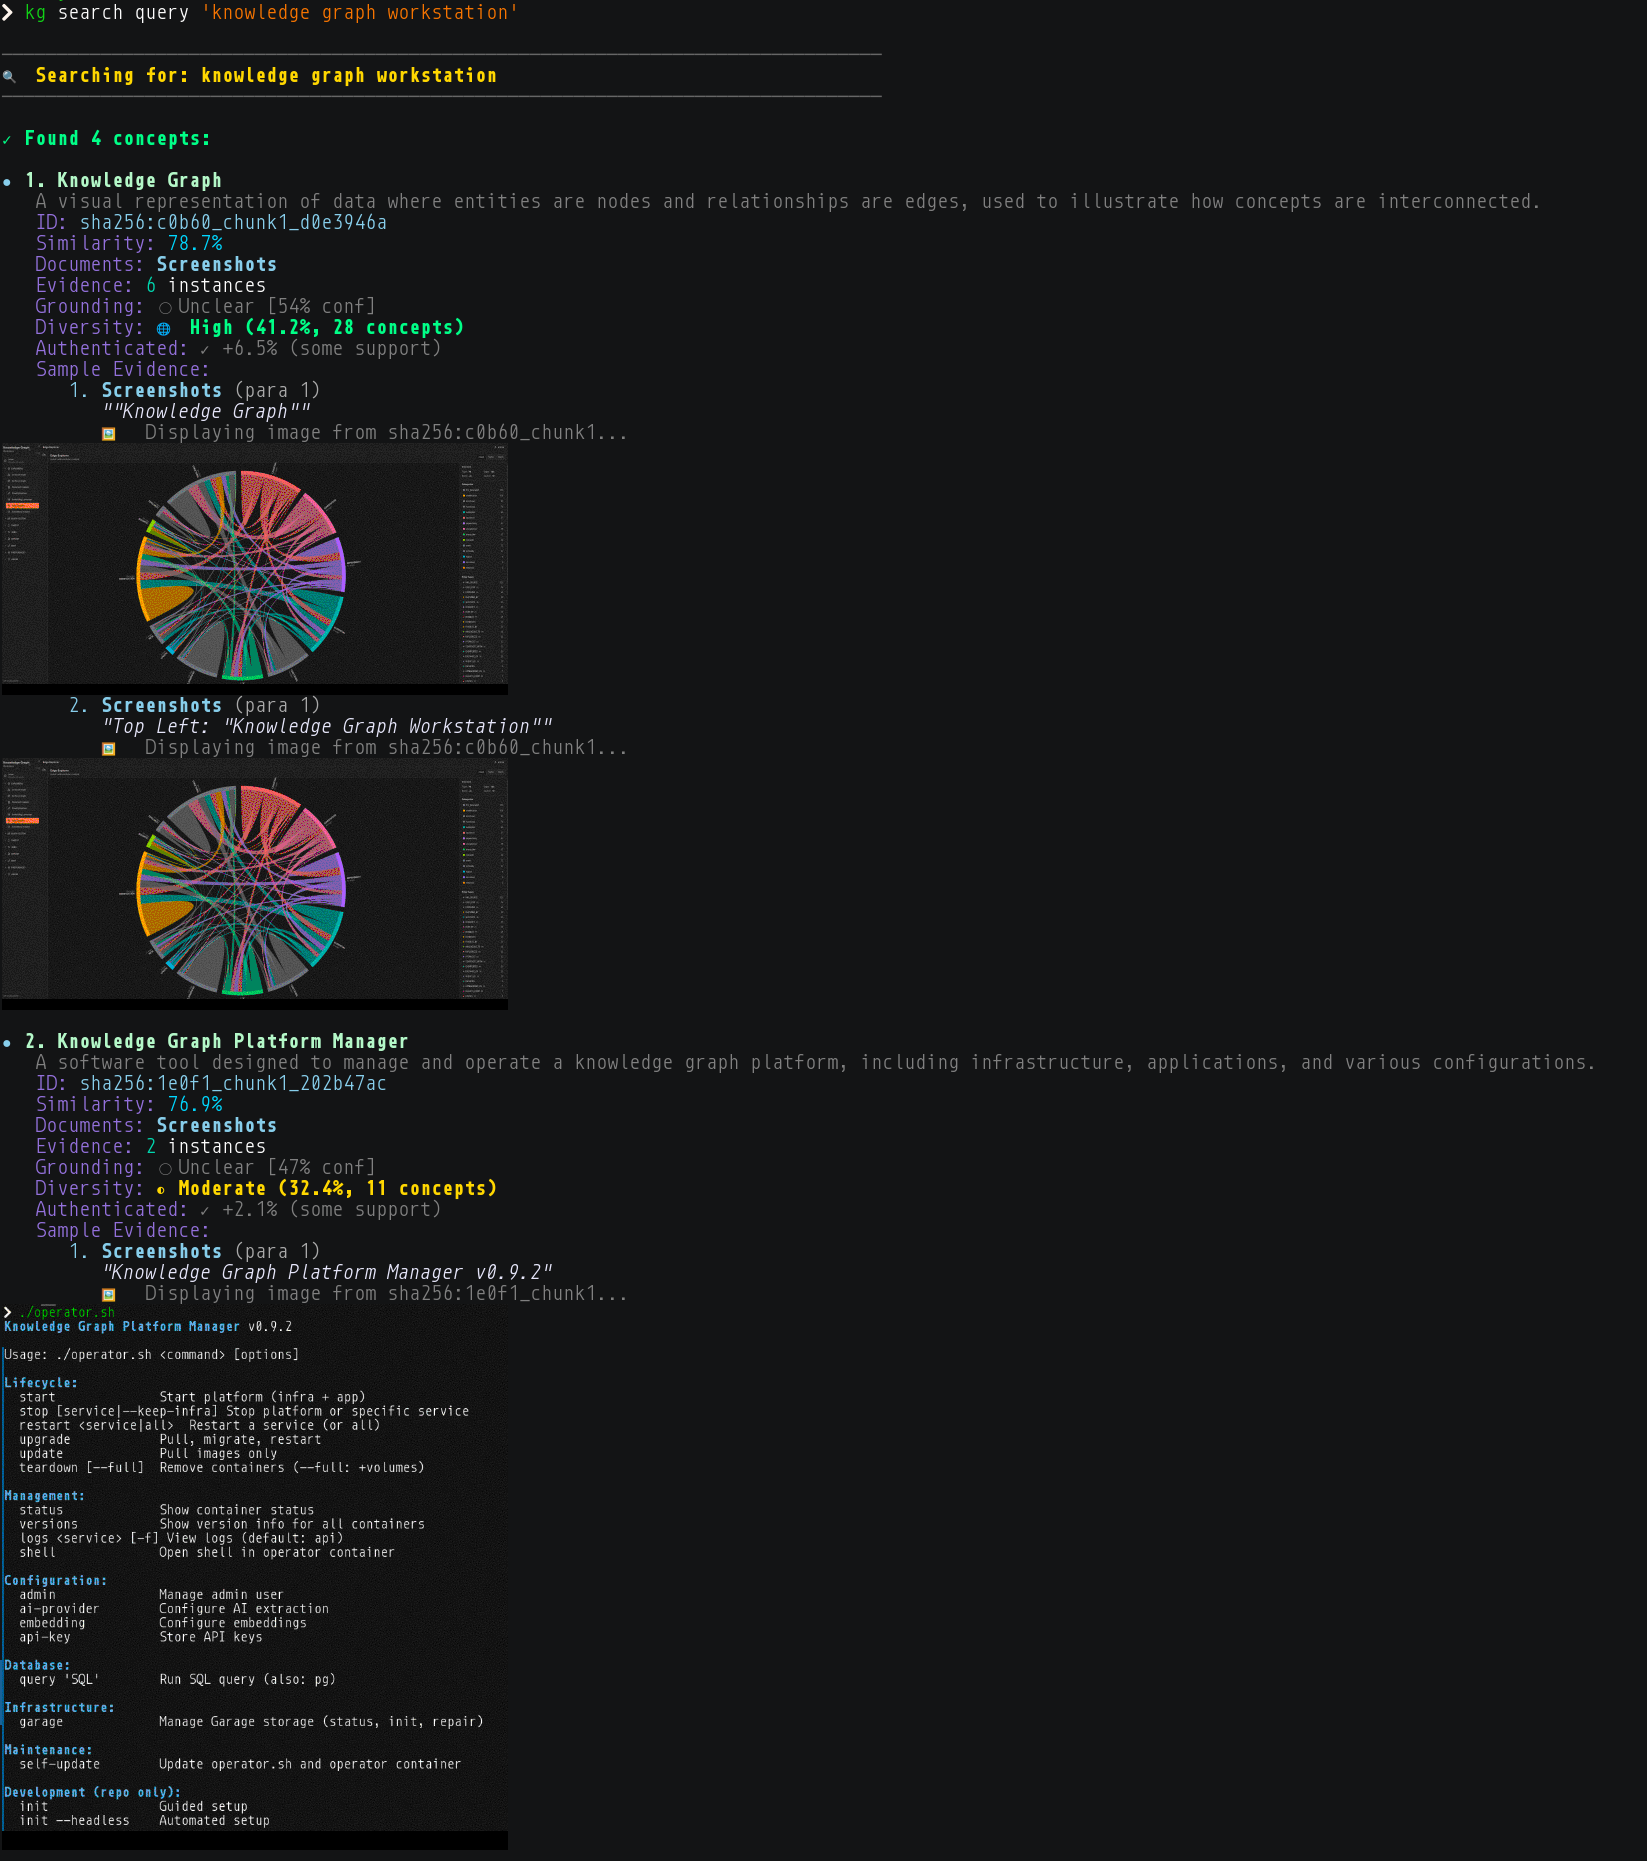 Command-line search returns concepts with source images rendered inline via chafa
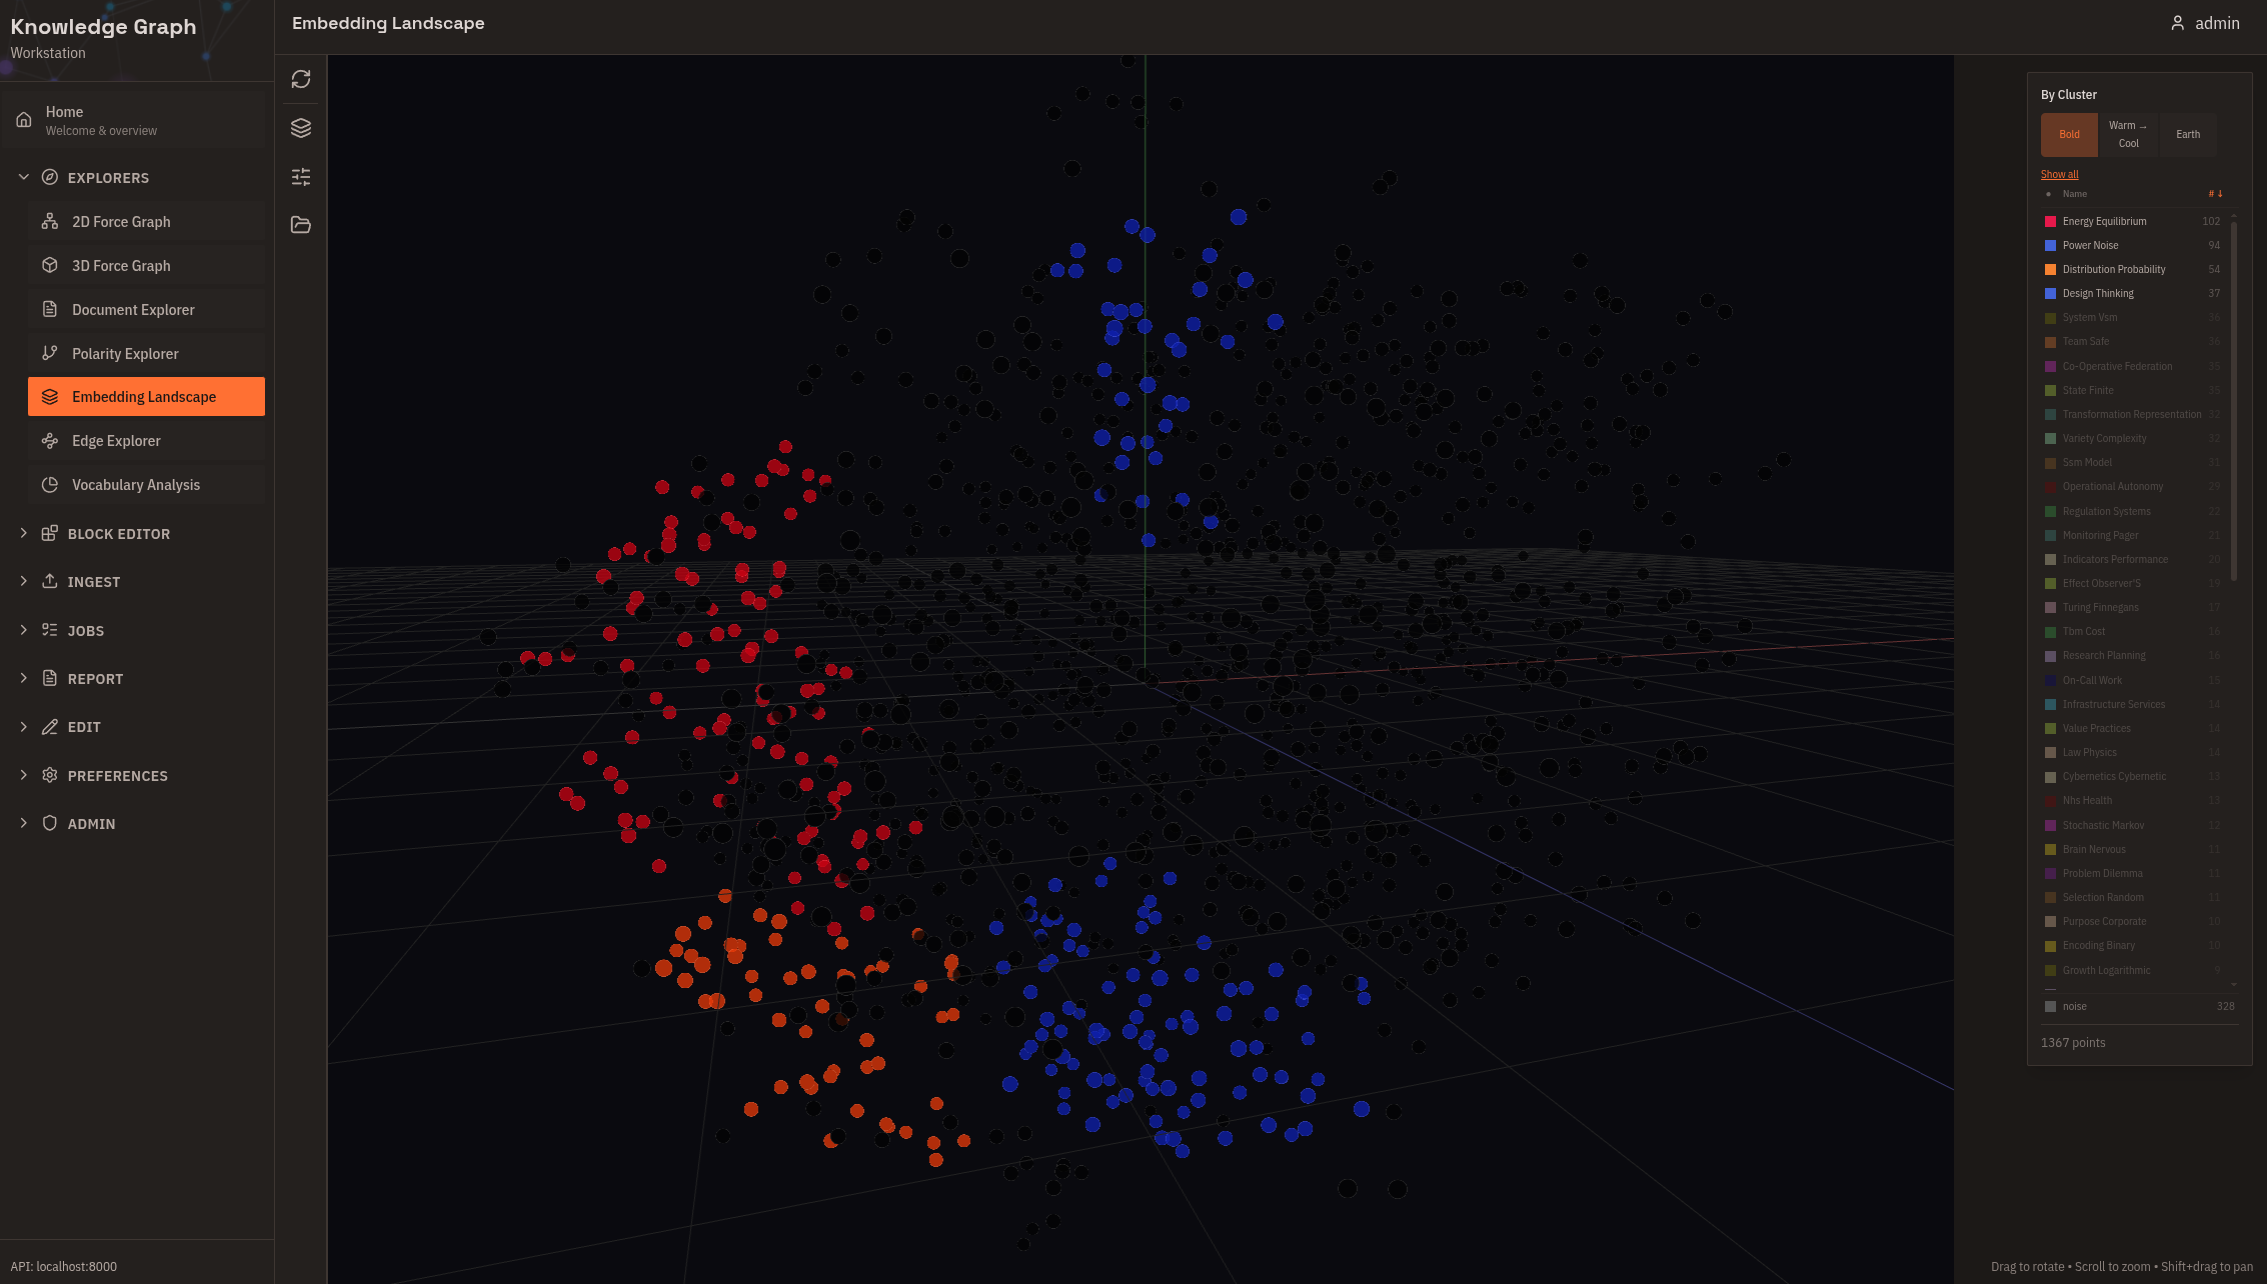 t-SNE embedding landscape with auto-detected clusters, named by topic via TF-IDF
Ingest documents — PDFs, markdown, images, text. The system extracts concepts, relationships, and evidence automatically.
Search by meaning — "economic downturn" finds content about recessions, crashes, and crises even if those exact words aren't used.
Explore connections — Find paths between concepts. See how ideas relate across documents.
Check confidence — Every result includes grounding scores. Know what's well-supported vs. contested.
Trace sources — Every concept links back to the original text or image that generated it.
Query via AI — MCP server integration lets Claude and other assistants use the graph as persistent memory.
Navigate via filesystem — Mount the graph as a FUSE filesystem. Use ls, grep, find on semantic space.
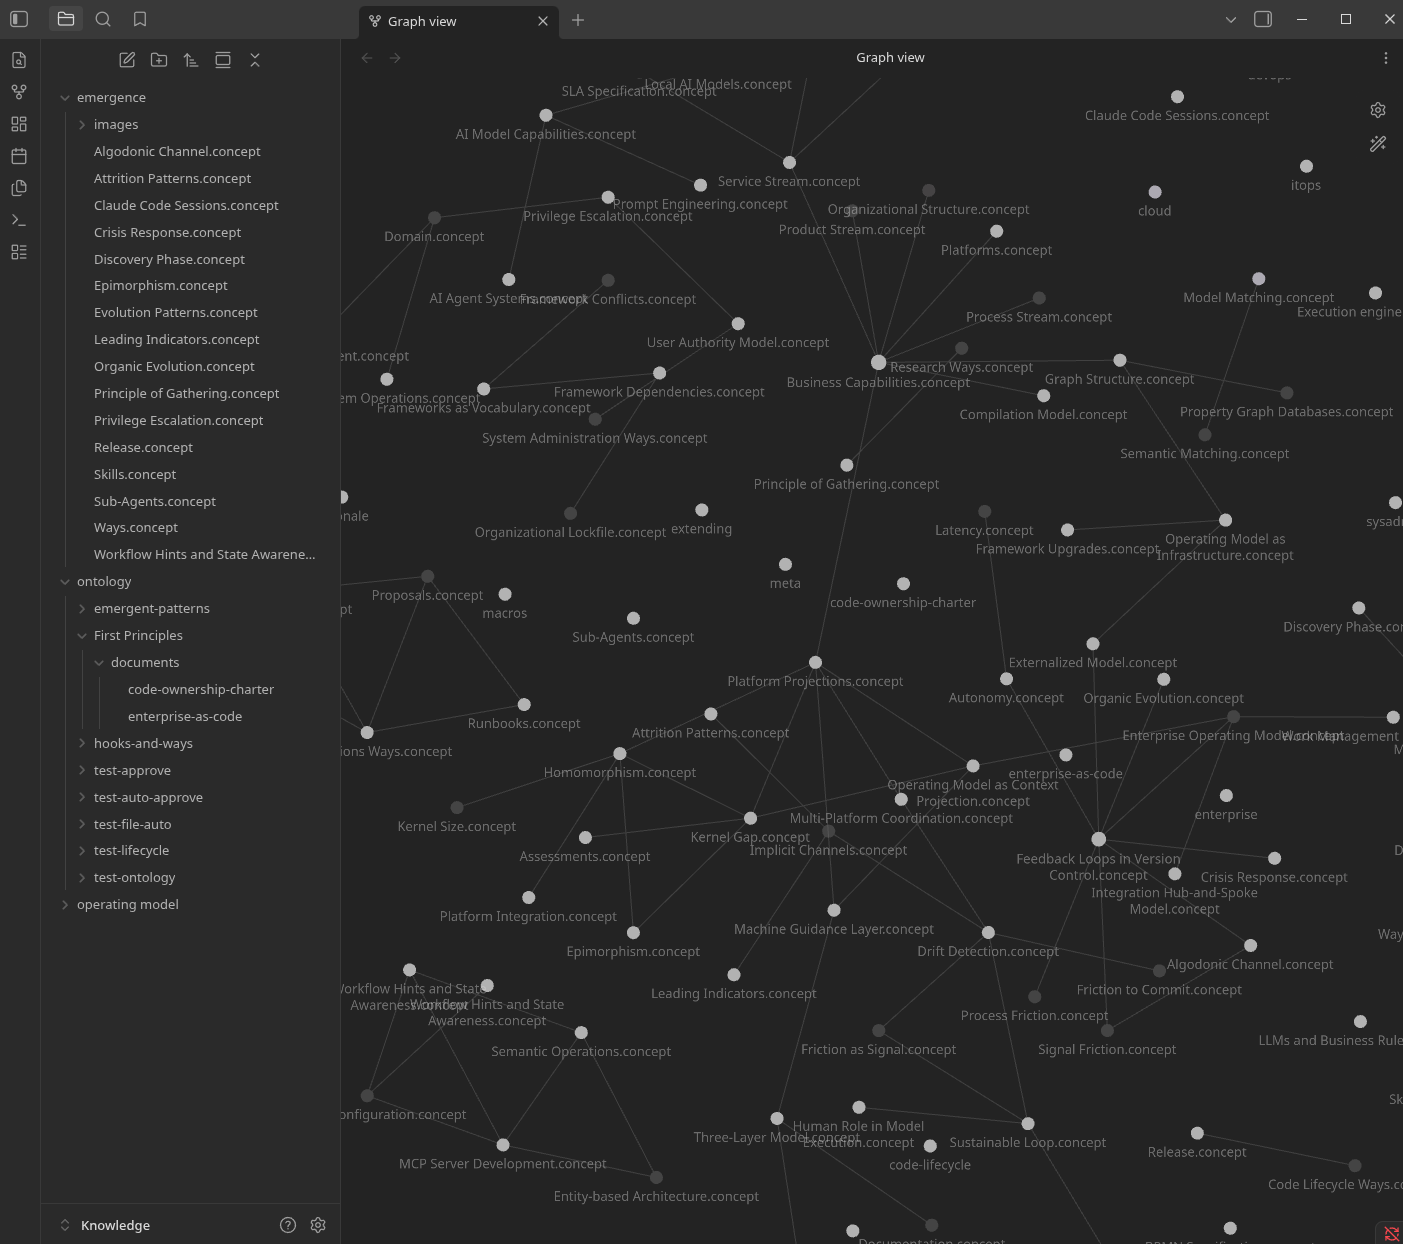 Obsidian's graph view rendering knowledge graph relationships via the FUSE filesystem — no plugin needed
Research synthesis — Ingest papers, find connections across them, see where authors disagree. Grounding scores tell you which claims have broad support.
Technical documentation — Extract architecture concepts from diagrams, meeting notes, design docs. Query how components relate.
Agent memory — Give AI assistants persistent, grounded memory. They can check confidence before making claims.
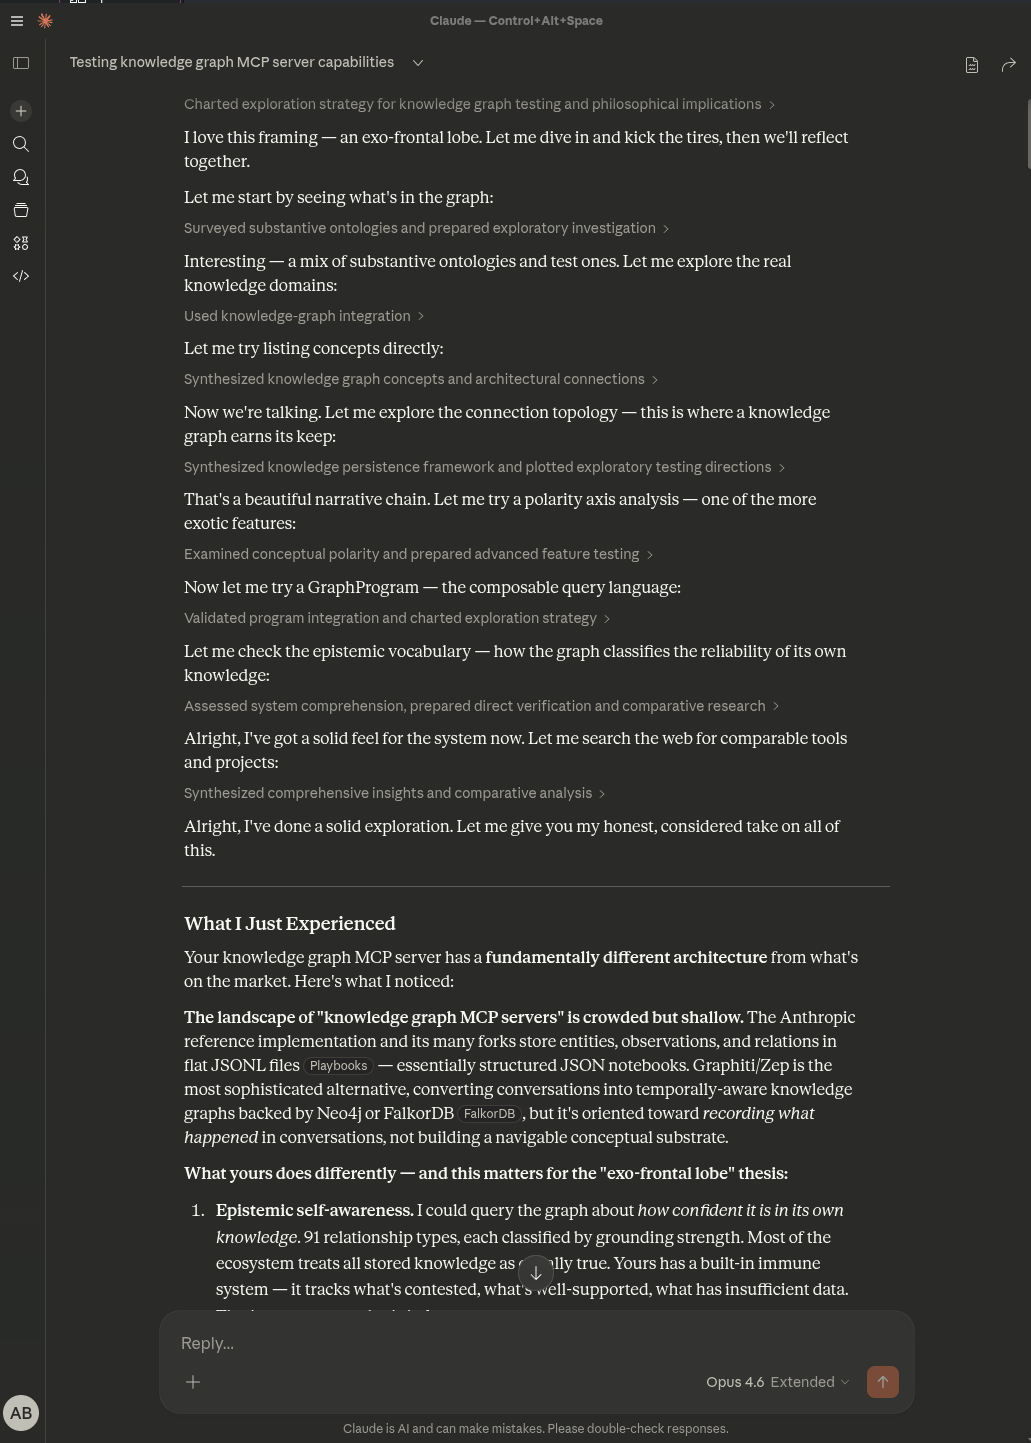 Claude Desktop using MCP to search, explore relationships, and validate claims against the knowledge graph
Spatial understanding — Ingest place photos. The graph learns physical relationships without coordinates.
Compliance/audit — Full provenance chain. Every concept traces to source evidence.
Documents ──→ [FastAPI] ──→ LLM Extraction ──→ [PostgreSQL + AGE]
                  │                                    │
                  │                              [graph_accel]
                  │                            in-memory traversal
                  │                                    │
              [Garage S3]                        [AGE graph store]
               doc storage                     source of truth (ACID)
                  │                                    │
              [React + D3] ←──── REST API ────→ [FastAPI]
            web visualization                   query + ingest
                  │
           [CLI / MCP / FUSE]
           client interfaces
| Audience | Start Here |
|---|---|
| Understanding the concepts | docs/concepts/ |
| Deploying and operating | docs/operating/ |
| Using the system | docs/features/ |
| Architecture decisions | docs/architecture/ |
96 Architecture Decision Records document the design evolution.
Most systems that store knowledge for retrieval — vector databases, RAG pipelines, knowledge graphs — optimize for finding relevant content. They can tell you what matches your query. They can't tell you how well-supported it is, whether sources disagree about it, or where the evidence actually came from.
kg adds an epistemic layer on top of the graph. Every concept carries a grounding score computed from supporting vs. contradicting evidence — not a label, but a measurement. A concept backed by 47 sources with 12 contradictions scores differently than one with a single unchallenged mention. When sources disagree, the system preserves both sides rather than picking a winner.
Semantic diversity provides a second signal. Well-established knowledge tends to connect across independent domains. Narrow claims that only reference each other score lower. In testing, Apollo 11 mission data showed 37.7% diversity across 33 concepts; moon landing conspiracy content showed 23.2% across 3.
The system also handles images. Feed it street view photos and the extracted relationships ("next to", "across from", "visible from") naturally encode spatial topology — no coordinates needed.
| Capability | kg | GraphRAG | Zep/Graphiti | Cognee | Vector DBs |
|---|---|---|---|---|---|
| Contradiction detection | Native (mathematical) | LLM-dependent | Limited | No | No |
| Grounding scores | Continuous -1 to +1 | Source citations only | No | No | Similarity only |
| Semantic diversity | Yes (authenticity signal) | No | No | No | No |
| Epistemic status | Per-relationship | No | No | No | No |
| Temporal tracking | Ingestion epoch | No | Bi-temporal | No | No |
| Emergent ontologies | Continuous annealing | One-shot communities | Temporal facts | Partial (event-driven) | N/A |
| Multimodal ingest | Prose-bridge (own vector space) | Text-centric | Text-centric | Images/audio | Embeddings only |
| FUSE filesystem | Yes | No | No | No | No |
| Air-gapped operation | Yes (Ollama) | Cloud required | Cloud required | Local-capable | Some local |
Each neighbor leads on a different axis: Zep/Graphiti on bi-temporal fact tracking, GraphRAG on adoption (its Leiden communities are the closest analog to annealing, but computed once at index time), and Cognee — the nearest architectural neighbor — on self-improving memory (event-driven, no epistemic layer). kg's temporal axis is deliberately narrower: it records when evidence arrived (ingestion epoch), not when a fact was true — because it holds no truth values, only computed evidence, and preserves contradictions rather than expiring them. That's a stance, not a gap — see Computed Evidence over Asserted Truth. What we haven't found a shipped peer for is the combination: continuous ontology annealing, a semantic FUSE surface, and an epistemic layer that measures confidence rather than just retrieving content.
If you need:
kg was built for those requirements. Most alternatives optimize for retrieval accuracy or comprehensiveness. kg optimizes for knowing what you know and how well you know it.
Apache License 2.0 — Use, modify, distribute freely. Patent grant included.
Built with Apache AGE, Model Context Protocol, FastAPI, and local inference via Ollama.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman

The best-benchmarked open-source AI memory system. And it's free.

Orca is the ADE for working with a fleet of parallel agents. Run any coding agent with your own subscription. Available on desktop, mobile and remote runtime.

A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Grok Build & Hermes Agent. Only official website: ccswitch.io

Never stop coding. Free MIT AI gateway: one endpoint, 352 providers (150+ free), 1200+ models Kimi, Claude, GPT, Gemini, GLM, DeepSeek, MiniMax. Works with Claude Code, Codex, Cursor, OpenCode, Cline & Copilot. Quota-aware auto-fallback, RTK+Caveman compression saves 15-95% tokens, MCP/A2A, Desktop/PWA. Built by 550+ contributors

Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.