Awesome-Self-Evolving-Agents
This repository provides a comprehensive collection of research papers, benchmarks, and open-source projects on Self-Evolving Agents. It includes contents from our survey paper 📖"A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution" and will be continuously updated.
🤗 You're very welcome to contribute to this repository. If you find any missing resources or come across interesting new research works, please don’t hesitate to launch an issue or submit a pull request!
📫 Contact us via emails: {xiangzhishang,yangchengyi}@stu.xmu.edu.cn, qinggangzhang@jlu.edu.cn
📃 Please cite our paper if you find our survey or repository helpful!
@article{xiang2026systematic,
  title={A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution},
  author={Xiang, Zhishang and Yang, Chengyi and Chen, Zerui and Wei, Zhimin and Tang, Yunbo and Teng, Zongpei and Peng, Zexi and Li, Zongxia and Huang, Chengsong and He, Yicheng and others},
  journal={Available at SSRN 6626878},
  year={2026}
}
🎉 News
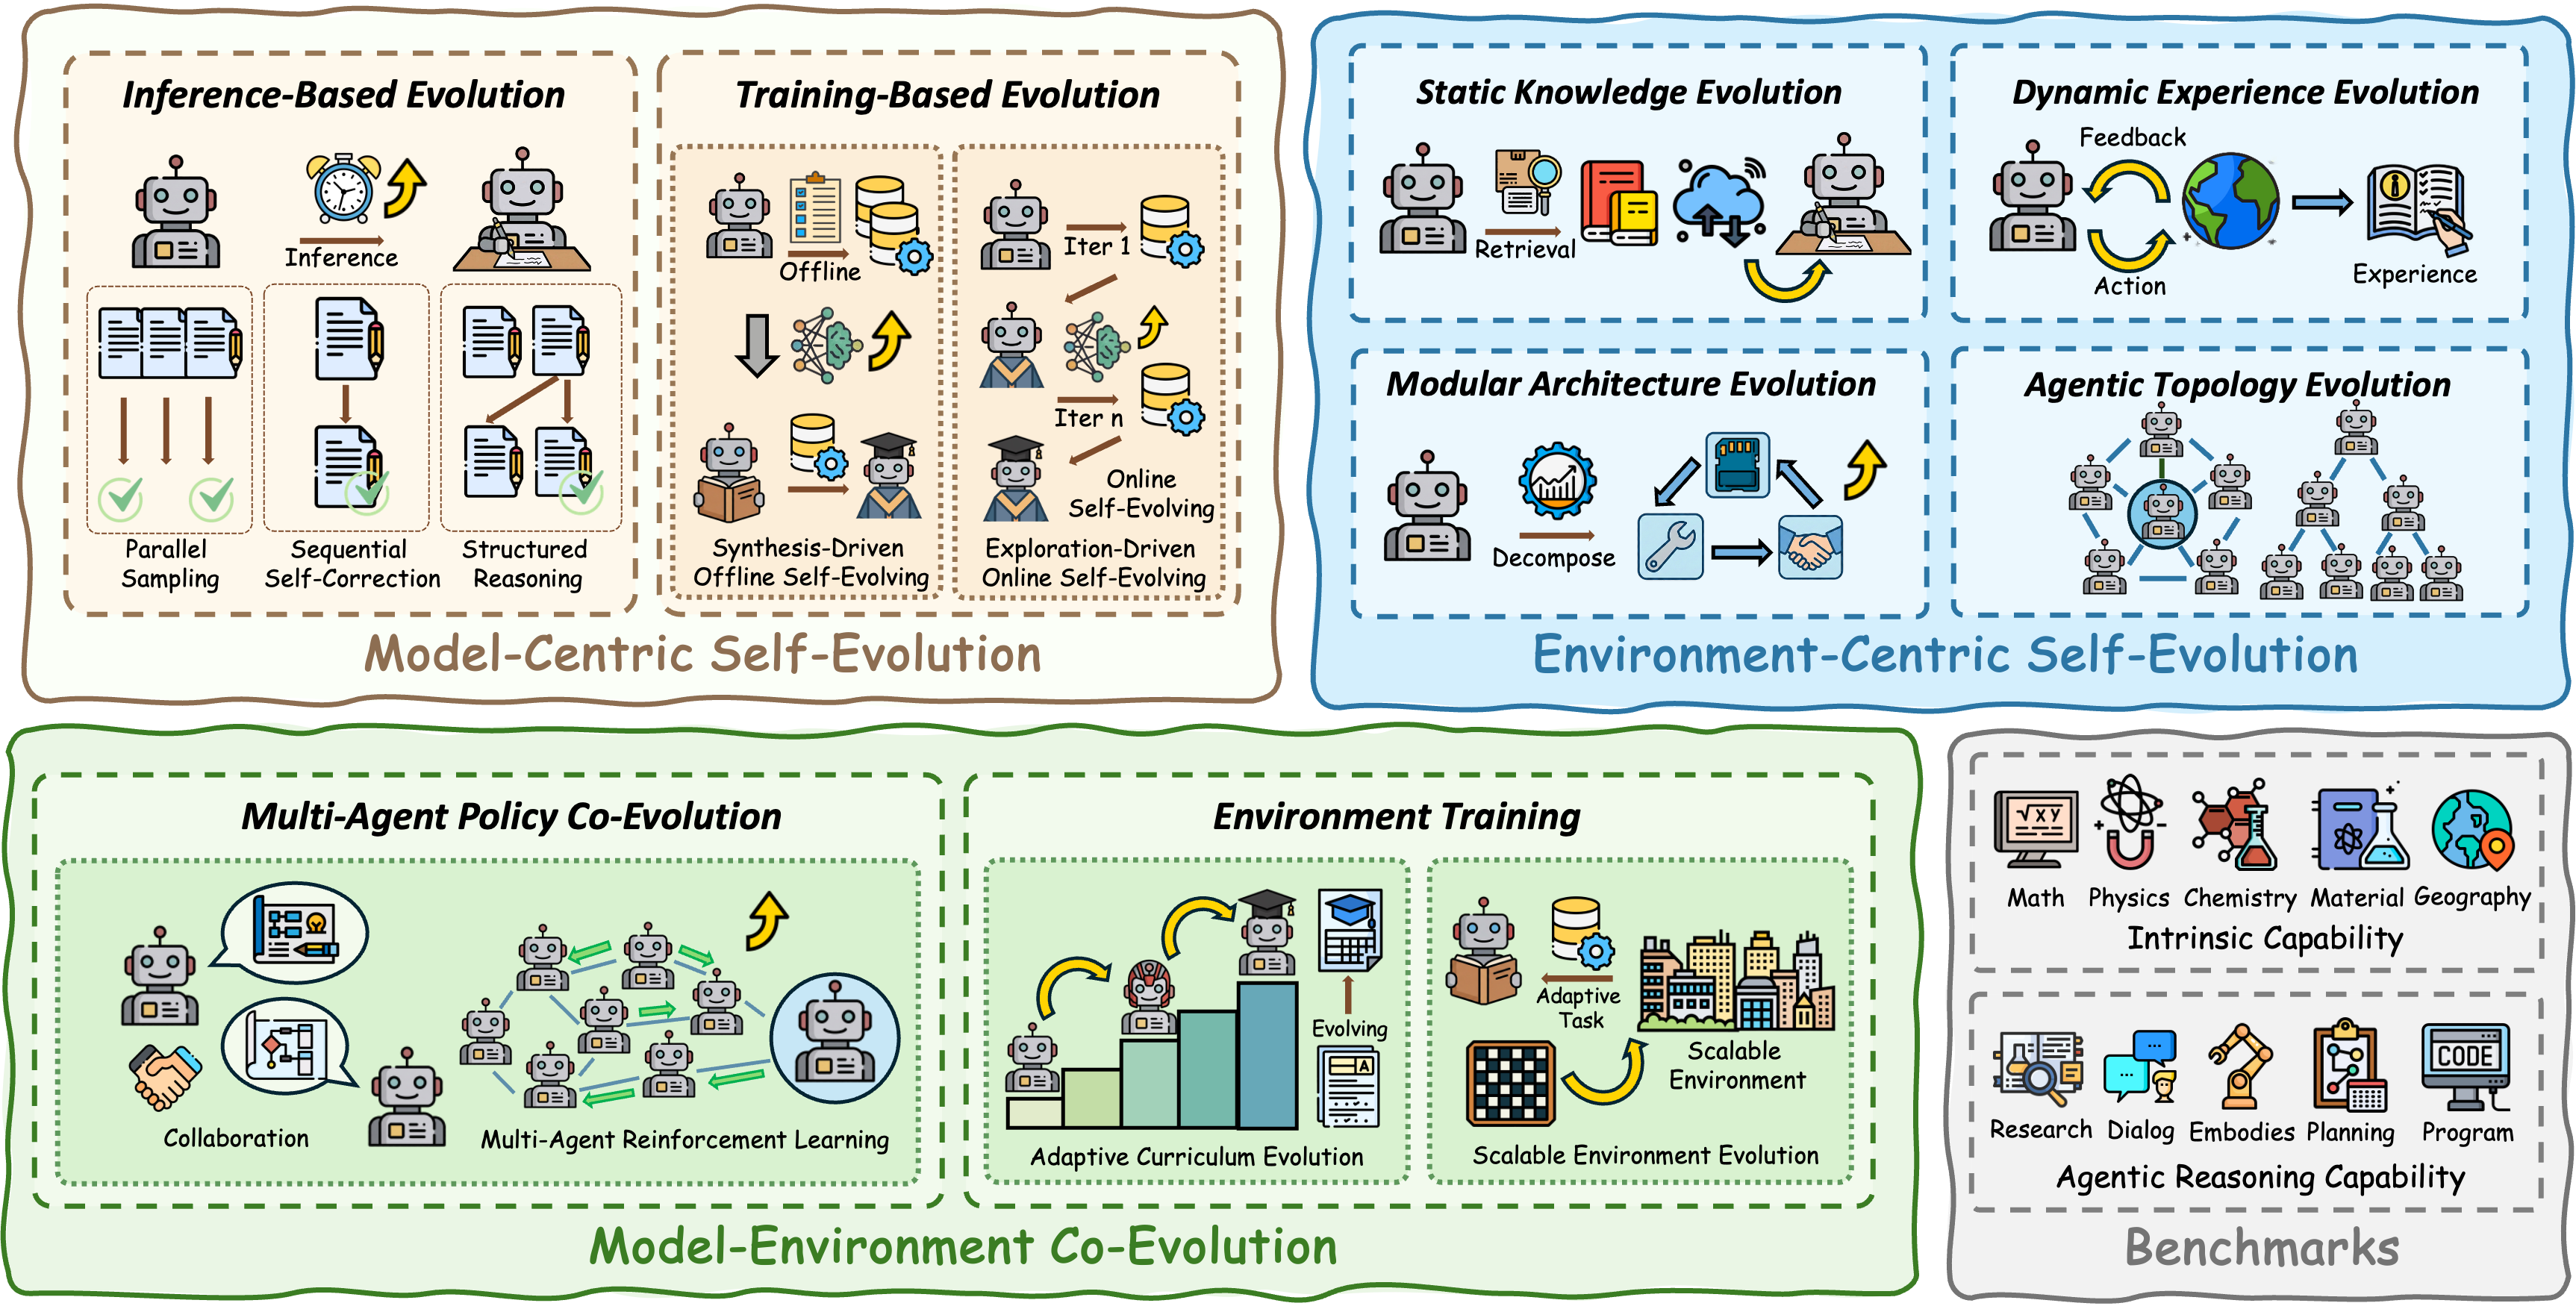
A Comprehensive Taxonomy of Self-Evolving Agents.
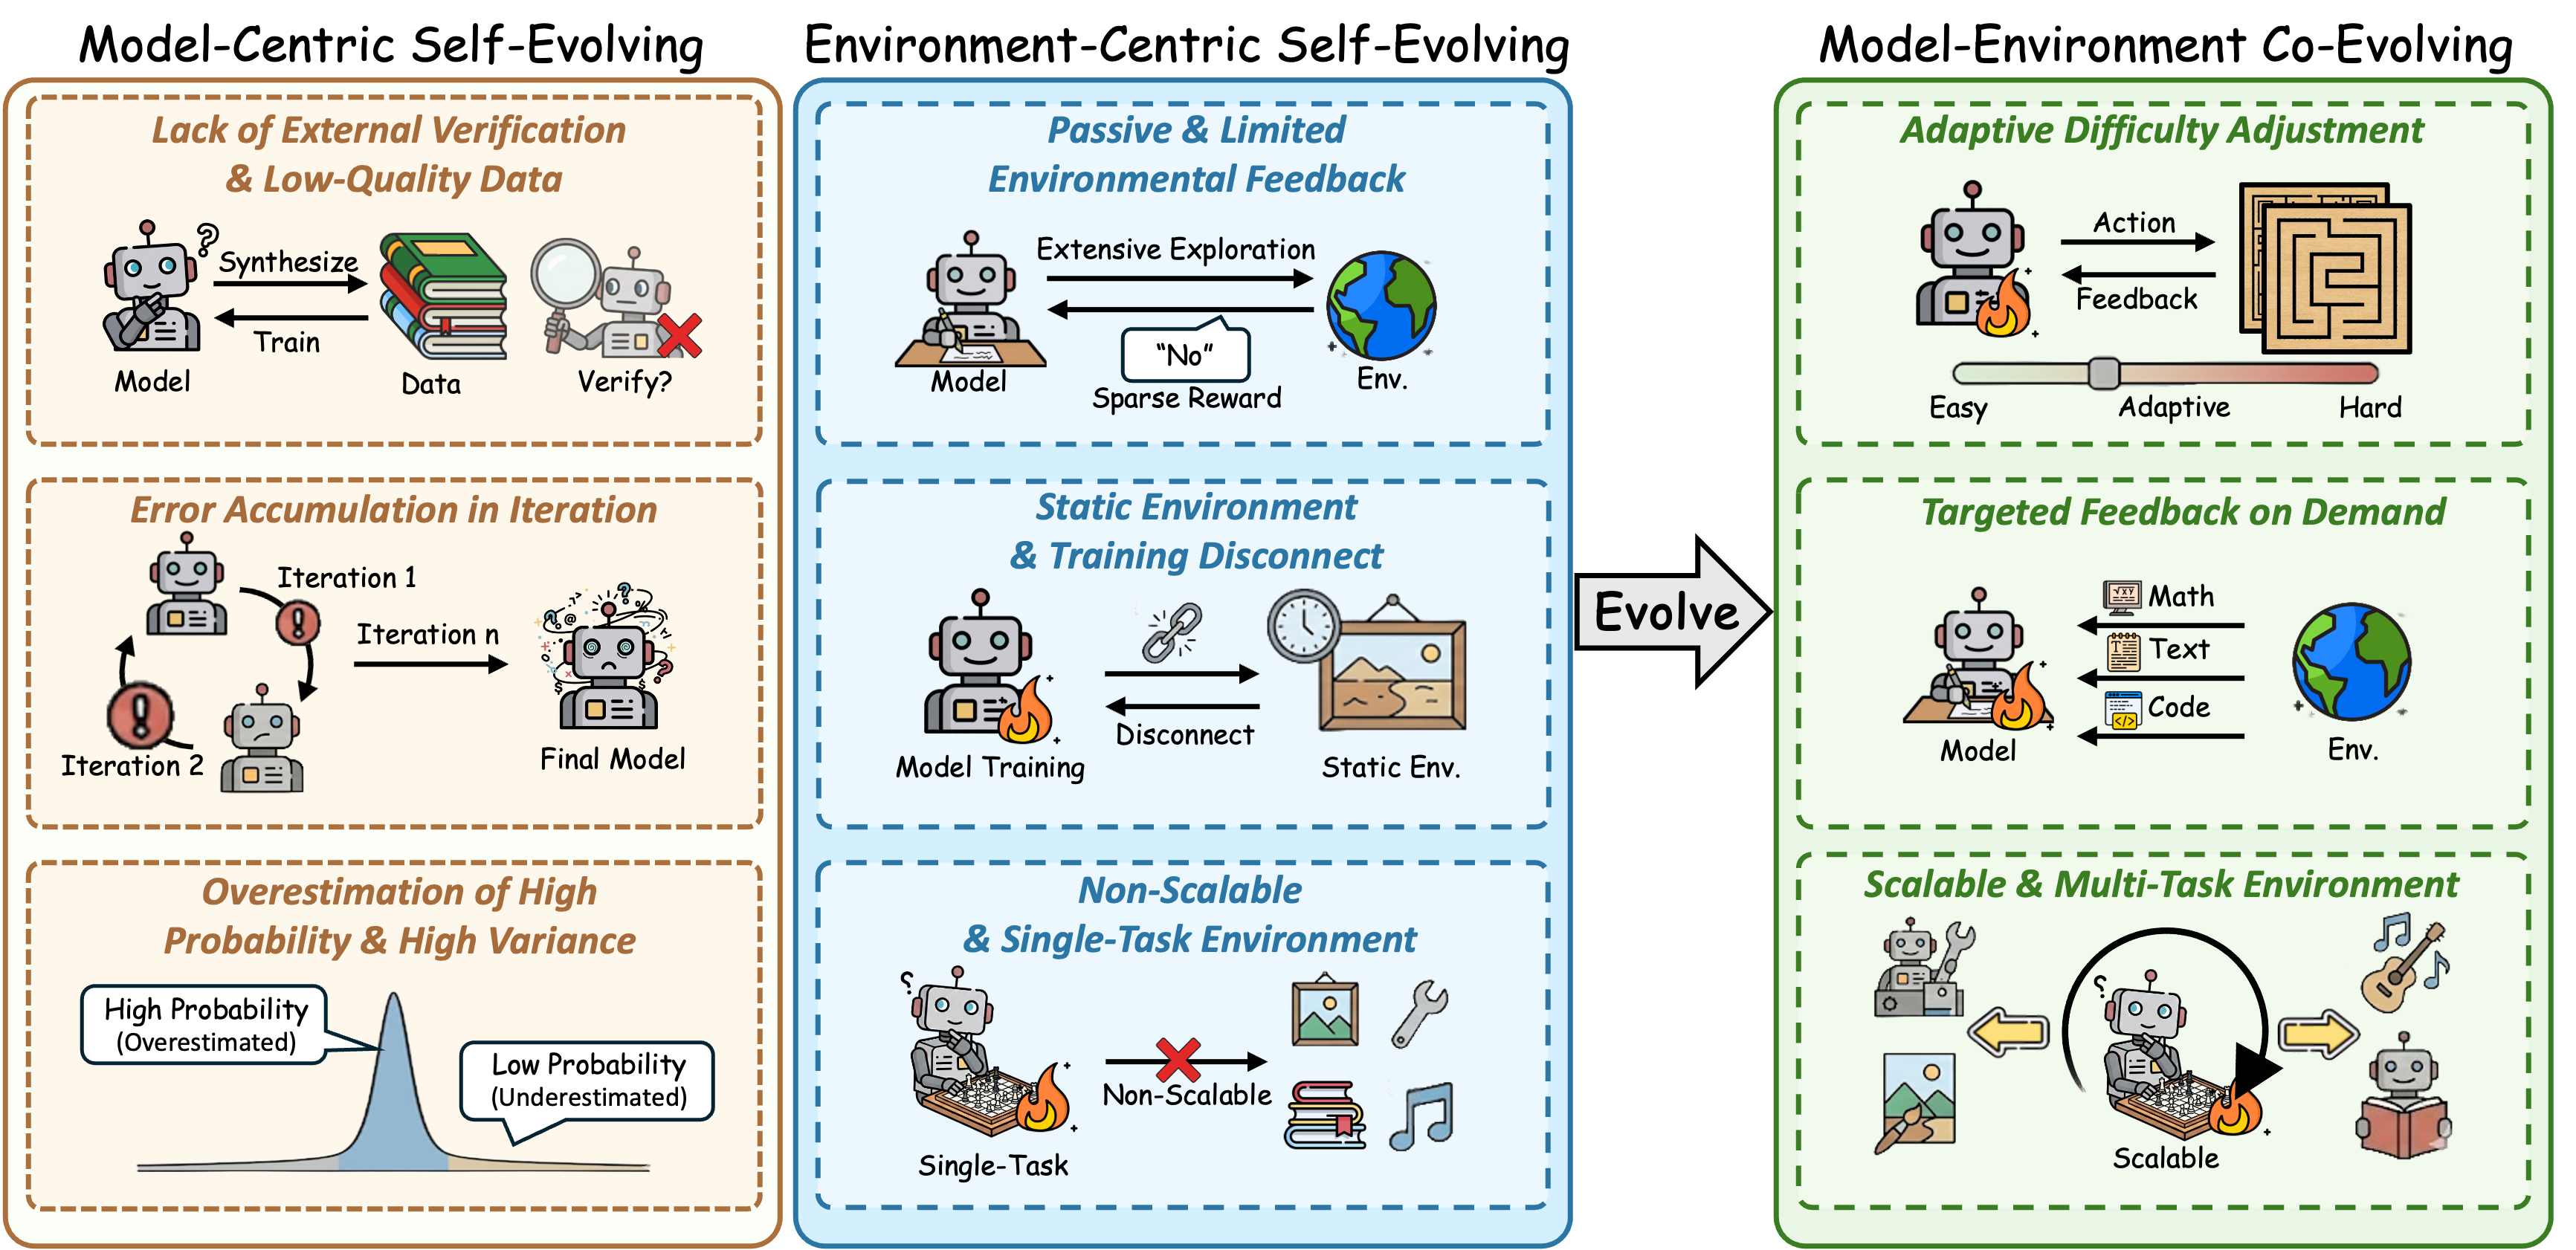
Agentic Self-Evolving represents a paradigm shift in AI development, enabling systems to autonomously improve through three key dimensions:
-
Model-Centric Self-Evolution: Focuses on improving the model itself through inference-based evolution (parallel sampling, sequential self-correction, structured reasoning) and training-based evolution (synthesis-driven offline and exploration-driven online self-evolving).
-
Environment-Centric Self-Evolution: Enhances the agent's interaction with external knowledge and experience through static knowledge evolution, dynamic experience evolution, modular architecture evolution, and agentic topology evolution.
-
Model-Environment Co-Evolution: Enables simultaneous evolution of both the model and its environment through environment training and multi-agent policy co-evolution.
📈 Trends
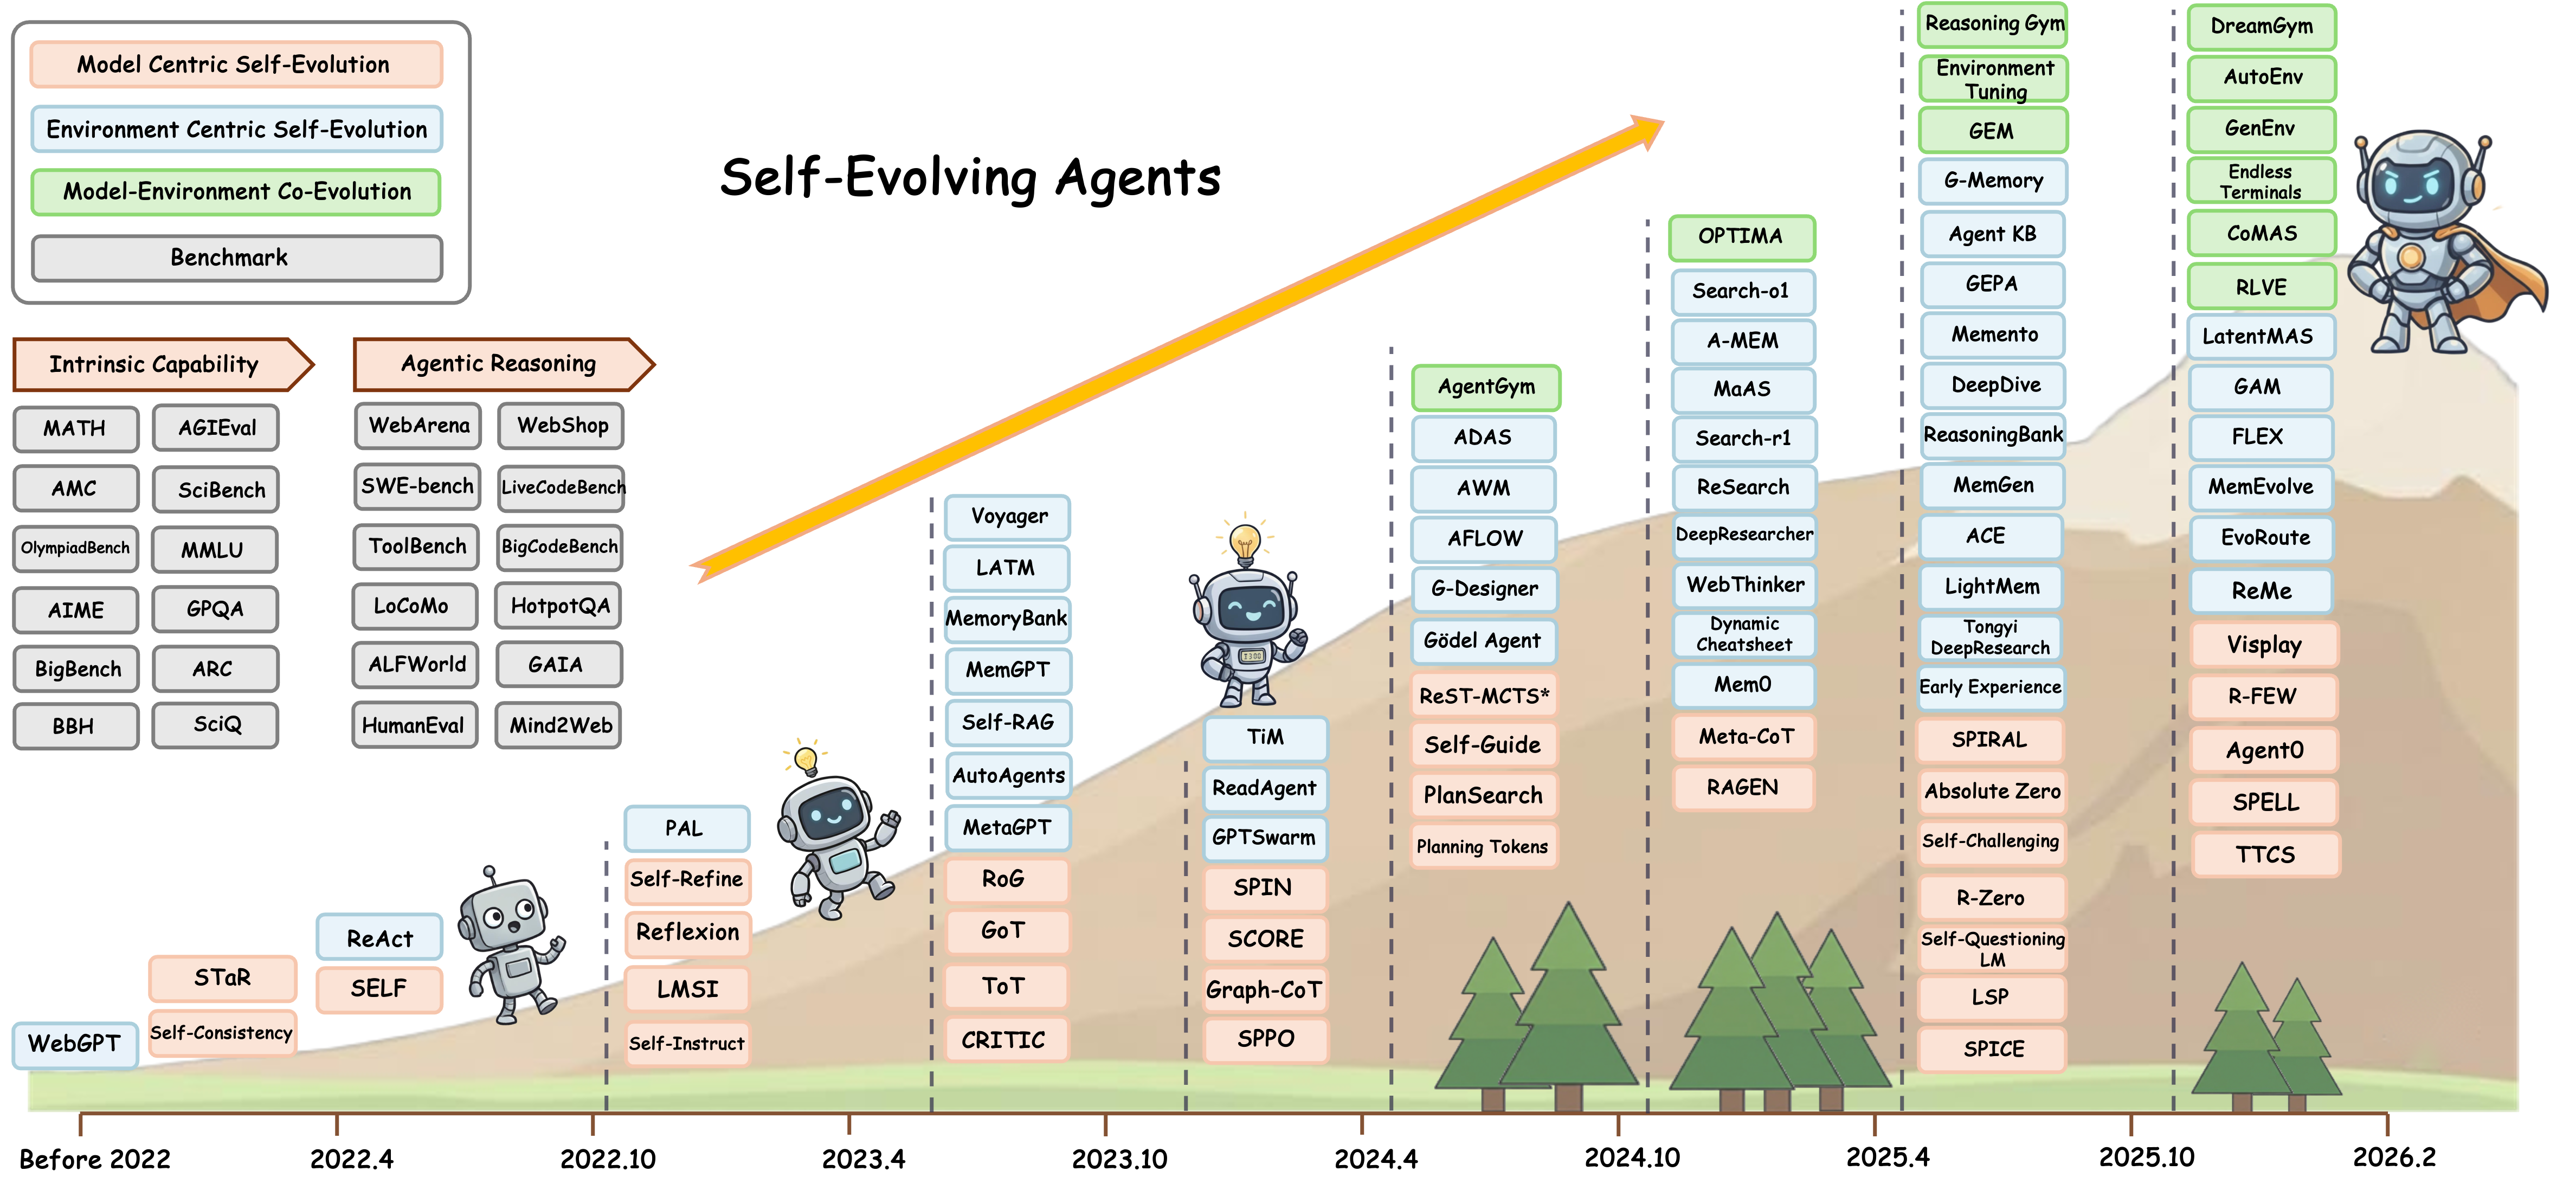
The Development Trends of Self-Evolving Agents with Representative Works.
Table of Content
📚 Related Survey Papers
- (arXiv 2024) A Survey on Self-Evolution of Large Language Models [Paper]
- (TMLR 2026) A Survey of Self-Evolving Agents What, When, How, and Where to Evolve on the Path to Artificial Super Intelligence [Paper]
- (arXiv 2025) A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems [Paper]
- (arXiv 2026) Safety in Embodied AI: A Survey of Risks, Attacks, and Defenses [Paper]
📜 Research Papers
Model-Centric Self-Evolution
Inference-Based Evolution
Parallel Sampling
- (ICLR'23) Self-consistency improves chain of thought reasoning in language models [Paper]
- (NeurIPS'24) Are more llm calls all you need? towards scaling laws of compound inference systems [Paper]
- (arxiv'24) Large language monkeys: Scaling inference compute with repeated sampling [Paper]
- (arxiv'24) Scaling llm test-time compute optimally can be more effective than scaling model parameters [Paper]
- (ACL'23) Llm-blender: Ensembling large language models with pairwise ranking and generative fusion [Paper]
- (EMNLP'23) Selfcheckgpt: Zero-resource black-box hallucination detection for generative large language models [Paper]
Sequential Self-Correction
- (NeurIPS'23) Self-refine: Iterative refinement with self-feedback [Paper]
- (ICLR'24) Teaching large language models to self-debug [Paper]
- (ACL'24 findings) Small language models need strong verifiers to self-correct reasoning [Paper]
- (NeurIPS'23) Reflexion: Language agents with verbal reinforcement learning [Paper]
- (ICLR'24) Critic: Large language models can self-correct with tool-interactive critiquing [Paper]
- (arxiv'25) Evolving deeper llm thinking [Paper]
- (arxiv'25) Towards system 2 reasoning in llms: Learning how to think with meta chain-of-thought [Paper]
- (ICLR'25) Planning in natural language improves llm search for code generation [Paper]
- (ICML'25) Reasoning-as-logic-units: Scaling test-time reasoning in large language models through logic unit alignment [Paper]
Structured Reasoning
- (arxiv'24) Stream of search (sos): Learning to search in language [Paper]
- (NeurIPS'24) Toward self-improvement of llms via imagination, searching, and criticizing [Paper]
- (ICML'24) Alphazero-like tree-search can guide large language model decoding and training [Paper]
- (arxiv'24) Litesearch: Efficacious tree search for llm [Paper]
- (NeurIPS 2023) Tree of thoughts: Deliberate problem solving with large language models, [Paper]
- (ICML'24) Language agent tree search unifies reasoning acting and planning in language models [Paper]
- (ICLR'24) Think-on-graph: Deep and responsible reasoning of large language model on knowledge graph [Paper]
- (ICLR'25) Think-on-graph 2.0: Deep and faithful large language model reasoning with knowledge-guided retrieval augmented generation [Paper]
- (ICLR'24) Reasoning on graphs: Faithful and interpretable large language model reasoning [Paper]
Training-Based Evolution 🔥
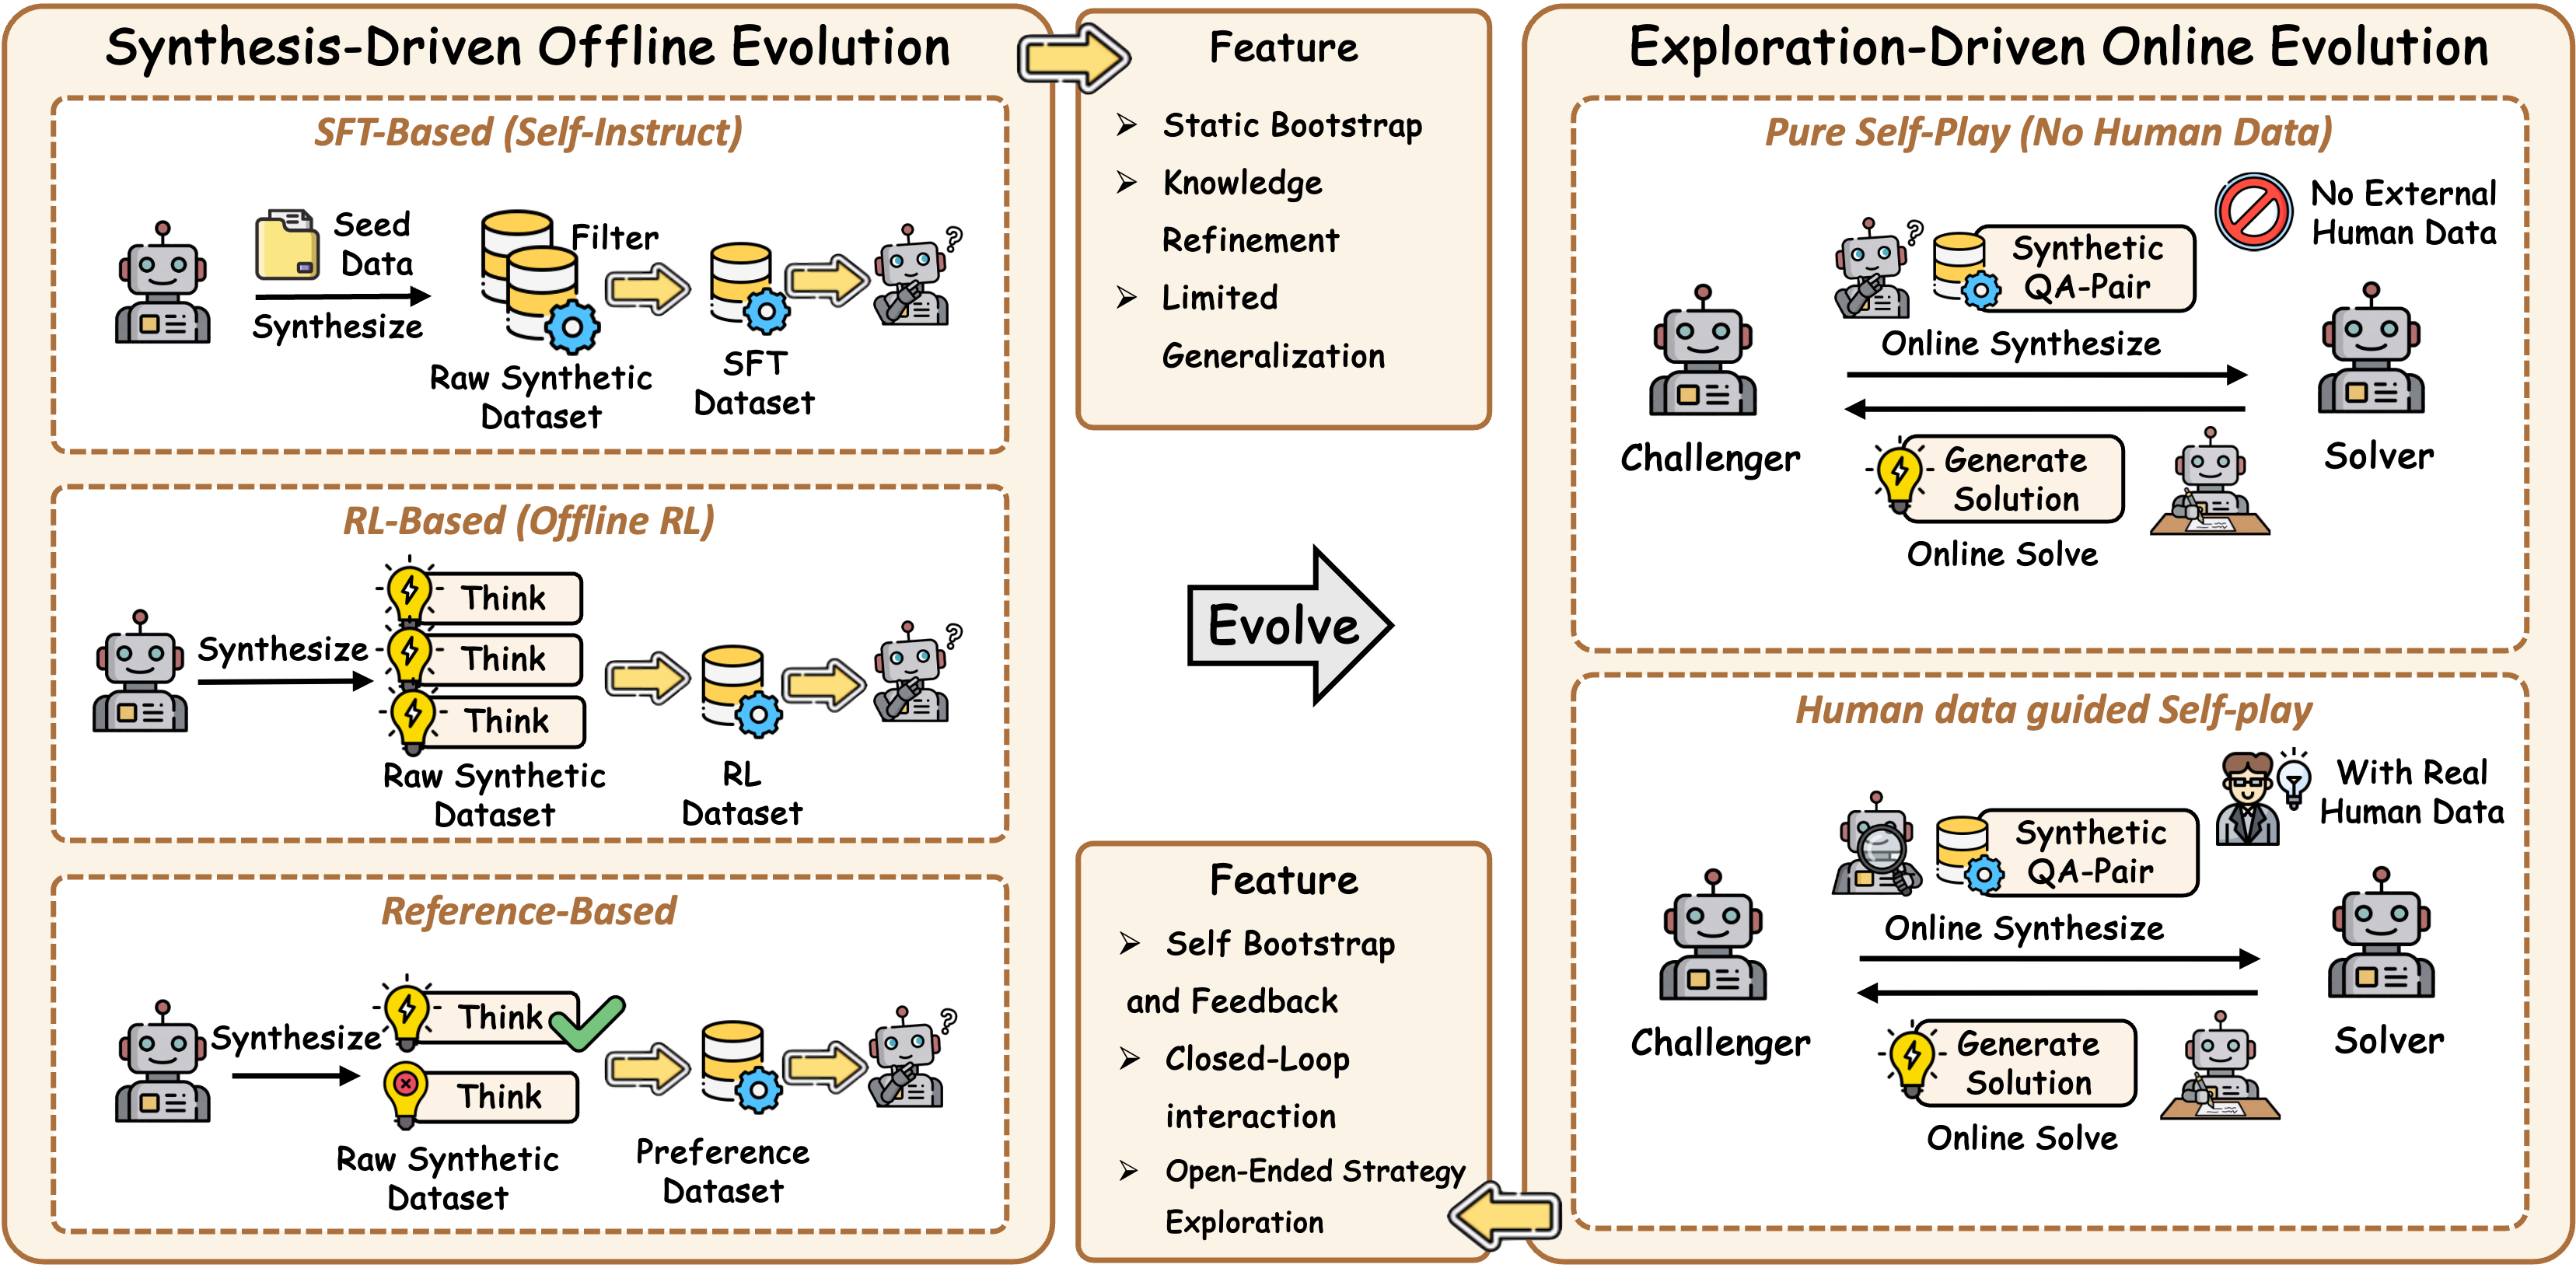
Synthesis-Driven Offline Self-Evolving
- (TMLR'24) Beyond human data: Scaling self-training for problem-solving with language models [Paper]
- (NeurIPS'25 workshop) Learning to solve and verify: A self-play framework for code and test generation [Paper]
- (arxiv'25) Evolving language models without labels: Majority drives selection, novelty promotes variation [Paper]
- (arxiv'25) Test-time offline reinforcement learning on goal-related experience [Paper]
- (arxiv'25) Agent-R: Training Language Model Agents to Reflect via Iterative Self-Training [Paper]
- (ACL'23) Self-instruct: Aligning language models with self-generated instructions [Paper]
- (COLM'24) Self-guide: Better task-specific instruction following via self-synthetic finetuning [Paper]
- (NeurIPS'25) Self-Adapting Language Models [Paper]
- (arxiv'23) Self: Self-evolution with language feedback [Paper]
- (ICML'24) Self-play fine-tuning converts weak language models to strong language models [Paper]
- (ICLR'25) Self-play preference optimization for language model alignment [Paper]
- (NeurIPS'22) Star: Bootstrapping reasoning with reasoning [Paper]
- (EMNLP'23) Large language models can self-improve [Paper]
- (NeurIPS'24) Rest-mcts*: Llm self-training via process reward guided tree search [Paper]
- (ICML'25) Self-improving language models for evolutionary program synthesis: A case study on ARC-AGI [Paper]
- (NeurIPS'25) Sirius: Self-improving multi-agent systems via bootstrapped reasoning [Paper]
- (arxiv'25) Ragen: Understanding self-evolution in llm agents via multi-turn reinforcement learning [Paper]
- (EMNLP'25) Samule: Self-learning agents enhanced by multi-level reflection [Paper]
Exploration-Driven Online Self-Evolving 🔥
- (ECCV'2026) SyncLoop: A Multimodal Dual-Loop Framework for Self-Improving Mathematical Reasoning [Paper]
- (arxiv'26) TTCS: Test-Time Curriculum Synthesis for Self-Evolving [Paper]
- (NeurIPS'25) Co-evolving llm coder and unit tester via reinforcement learning [Paper]
- (arxiv'25) Towards agentic self-learning llms in search environment [Paper]
- (arxiv'25) Multi-agent evolve: Llm self-improve through co-evolution [Paper]
- (ICLR'26) Steporlm: A self-evolving framework with generative process supervision for operations research language models [Paper]
- (NeurIPS'24) Coevolving with the other you: Fine-tuning llm with sequential cooperative multi-agent reinforcement learning [Paper]
- (ICLR'26) R-zero: Self-evolving reasoning llm from zero data [Paper]
- (COLM'26) Vocabulary Dropout for Curriculum Diversity in LLM Co-Evolution [Paper] [Code]
- (arxiv'26) MM-Zero: Self-Evolving Multi-Model Vision Language Models From Zero Data
[Paper]
- (NeurIPS'25) Absolute zero: Reinforced self-play reasoning with zero data [Paper]
- (arxiv'25) Language self-play for data-free training [Paper]
- (arxiv'25) Self-questioning language models [Paper]
- (arxiv'25) SPIRAL: Self-Play on Zero-Sum Games Incentivizes Reasoning via Multi-Agent Multi-Turn Reinforcement Learning [Paper]
- (arxiv'25) Socratic-zero: Bootstrapping reasoning via data-free agent co-evolution [Paper]
- (arxiv'25) Agent0: Unleashing self-evolving agents from zero data via tool-integrated reasoning [Paper]
- (NeurIPS'25) SeRL: Self-Play Reinforcement Learning for Large Language Models with Limited Data [Paper]
- (arxiv'26) Dr. Zero: Self-Evolving Search Agents without Training Data [Paper]
- (ICLR'26) Theoretical Modeling of LLM Self-Improvement Training Dynamics Through Solver-Verifier Gap [Paper]
- (ICLR'26) Search self-play: Pushing the frontier of agent capability without supervision [Paper]
- (arxiv'25) ReVeal: Self-Evolving Code Agents via Iterative Generation-Verification [Paper]
- (NeurIPS'25) Self-challenging language model agents [Paper]
- (ICLR'26) Spice: Self-play in corpus environments improves reasoning [Paper]
- (ICLR'26) Spell: Self-play reinforcement learning for evolving long-context language models [Paper]
- (ICLR'25) Webrl: Training llm web agents via self-evolving online curriculum reinforcement learning [Paper]
- (EMNLP'25) Enabling Self-Improving Agents to Learn at Test Time With Human-In-The-Loop Guidance [Paper]
- (arxiv'25) Ladder: Self-improving llms through recursive problem decomposition [Paper]
- (arxiv'25) Guided self-evolving llms with minimal human supervision [Paper]
- (AAAI'25) Empowering Self-Learning of LLMs: Inner Knowledge Explicitation as a Catalyst [Paper]
- (NeurIPS'25) Spc: Evolving self-play critic via adversarial games for llm reasoning [Paper]
- (ICLR'26) Your agent may misevolve: Emergent risks in self-evolving llm agents [Paper]
Environment-Centric Self-Evolution
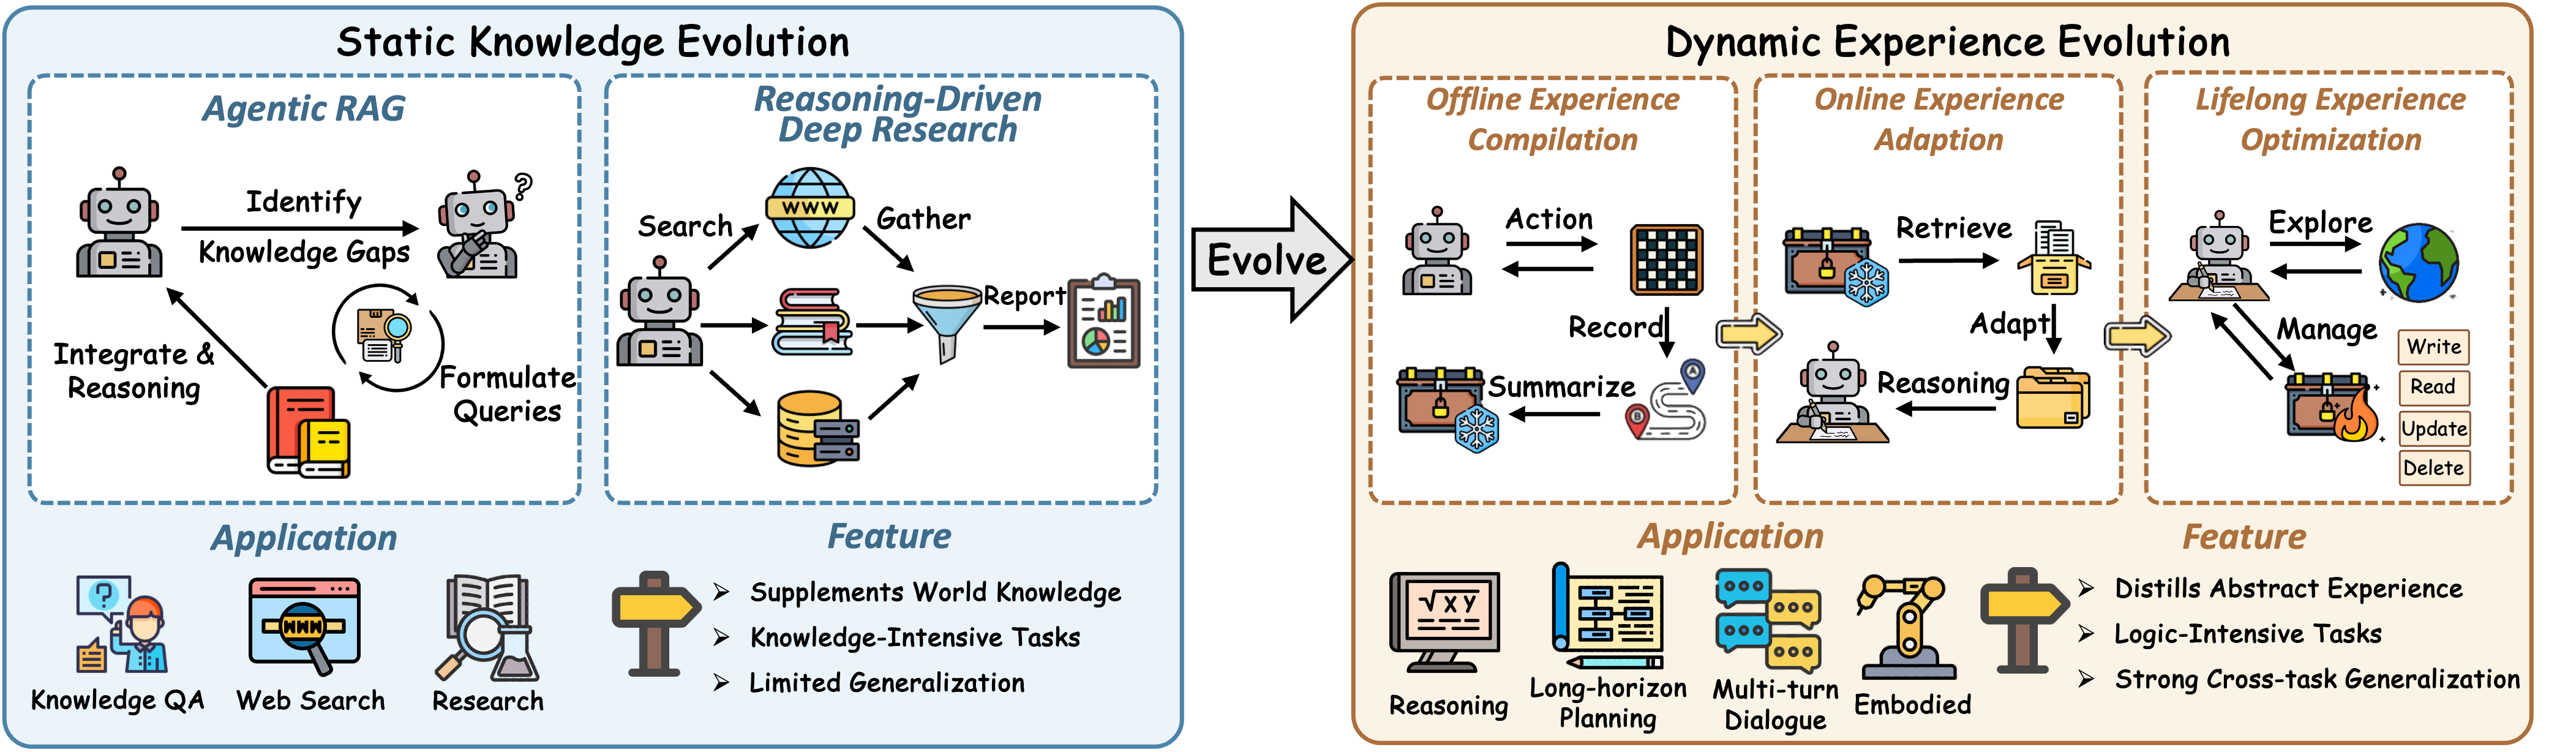
Static Knowledge Evolution
Agentic Retrieval-Augmented Generation
- (ICLR'24) Self-rag: Learning to retrieve, generate, and critique through self-reflection [Paper]
- (ACL'25) Rag-critic: Leveraging automated critic-guided agentic workflow for retrieval augmented generation [Paper]
- (EMNLP'25) Search-o1: Agentic search-enhanced large reasoning models [Paper]
- (COLM 2025) Search-r1: Training llms to reason and leverage search engines with reinforcement learning [Paper]
- (arxiv'25) Learning to reason with search for llms via reinforcement learning [Paper]
- (arxiv'25) R1-searcher: Incentivizing the search capability in llms via reinforcement learning [Paper]
- (ACL'23) Webcpm: Interactive web search for chinese long-form question answering [Paper]
- (NeurIPS'23 workshop)Dspy: Compiling declarative language model calls into self-improving pipelines [Paper]
- (ICLR'25) Mindsearch: Mimicking human minds elicits deep ai searcher [Paper]
- (arxiv'25) Open deep search: Democratizing search with open-source reasoning agents [Paper]
Reasoning-Driven Deep Research
- (arxiv'25) DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents [Paper]
- (arxiv'25) Deep research agents: A systematic examination and roadmap [Paper]
- (ACL'24) Webvoyager: Building an end-to-end web agent with large multimodal models [Paper]
- (arxiv'25) Deepdive: Advancing deep search agents with knowledge graphs and multi-turn rl [Paper]
- (arxiv'25) DeepSearch: Overcome the Bottleneck of Reinforcement Learning with Verifiable Rewards via Monte Carlo Tree Search [Paper]
- (arxiv'25) Hiersearch: A hierarchical enterprise deep search framework integrating local and web searches [Paper]
- (EMNLP'25) Deepresearcher: Scaling deep research via reinforcement learning in real-world environments [Paper]
- (arxiv'25) Sfr-deepresearch: Towards effective reinforcement learning for autonomously reasoning single agents [Paper]
- (arxiv'25) Tongyi deepresearch technical report [Paper]
- (arxiv'25) Webweaver: Structuring web-scale evidence with dynamic outlines for open-ended deep research [Paper]
- (arxiv'25) Webthinker: Empowering large reasoning models with deep research capability [Paper]
- (arxiv'25) Surveyx: Academic survey automation via large language models [Paper]
Dynamic Experience Evolution 🔥
Offline Experience Compilation
- (arxiv'25) Remember me, refine me: A dynamic procedural memory framework for experience-driven agent evolution [Paper]
- (arxiv'25) Get Experience from Practice: LLM Agents with Record & Replay [Paper]
- (arxiv'25) Skillweaver: Web agents can self-improve by discovering and honing skills [Paper]
- (ICML'25) Agent kb: Leveraging cross-domain experience for agentic problem solving [Paper]
- (arxiv'25) From experience to strategy: Empowering llm agents with trainable graph memory [Paper]
- (arxiv'24) Cops: Empowering llm agents with provable cross-task experience sharing [Paper]
- (arxiv'25) Arcmemo: Abstract reasoning composition with lifelong llm memory [Paper]
Online Experience Adaptation
- (arxiv'26) ExpSeek: Self-Triggered Experience Seeking for Web Agents [Paper]
- (arxiv'25) Dynamic cheatsheet: Test-time learning with adaptive memory [Paper]
- (arxiv'25) Memento: Fine-tuning llm agents without fine-tuning llms [Paper]
- (ICLR'26) Gepa: Reflective prompt evolution can outperform reinforcement learning [Paper]
- (ICLR'26) Agentic context engineering: Evolving contexts for self-improving language models [Paper]
Lifelong Experience Evolution 🔥
- (arxiv'25) Xolver: Multi-Agent Reasoning with Holistic Experience Learning Just Like an Olympiad Team [Paper]
- (arxiv'25) Agentevolver: Towards efficient self-evolving agent system [Paper]
- (arxiv'26) Evolving Programmatic Skill Networks [Paper]
- (arxiv'26) Meta Context Engineering via Agentic Skill Evolution [Paper]
- (arxiv'26) Self-Consolidation for Self-Evolving Agents [Paper]
- (ICLR'26) Reasoningbank: Scaling agent self-evolving with reasoning memory [Paper]
- (arxiv'25) Evolver: Self-evolving llm agents through an experience-driven lifecycle [Paper]
- (arxiv'25) Training-free group relative policy optimization [Paper]
- (arxiv'25) Flex: Continuous agent evolution via forward learning from experience [Paper]
- (arxiv'25) Agent learning via early experience [Paper]
- (COLM'25)Inducing programmatic skills for agentic tasks [Paper]
- (arxiv'25) Reinforcement learning for self-improving agent with skill library [Paper]
- (arxiv'25) AccelOpt: A Self-Improving LLM Agentic System for AI Accelerator Kernel Optimization [Paper]
- (ICLR'26) Memgen: Weaving generative latent memory for self-evolving agents [Paper]
- (arxiv'25) Latentevolve: Self-evolving test-time scaling in latent space [Paper]
- (arxiv'26) RetroAgent: From Solving to Evolving via Retrospective Dual Intrinsic Feedback [Paper]
Skill Augmented Evolution 🔥
- (arxiv'26) RewardHarness: Self-Evolving Agentic Post-Training [Paper] [Code]
- (arxiv'26) AutoSkill: Experience-Driven Lifelong Learning via Skill Self-Evolution
[Paper]
- (arxiv'26) SkillRL: Evolving Agents via Recursive Skill-Augmented Reinforcement Learning [Paper]
- (arxiv'26) SkillNet: Create, Evaluate, and Connect AI Skills [Paper]
- (arxiv'26) SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks [Paper]
- (arxiv'26) ARISE: Agent Reasoning with Intrinsic Skill Evolution in Hierarchical Reinforcement Learning [Paper]
- (arxiv'26) Evolving Medical Imaging Agents via Experience-driven Self-skill Discovery [Paper]
- (arxiv'26) OpenSkill: Open-World Self-Evolution for LLM Agents [Paper] [Code]
Modular Architecture Evolution
Interaction Protocol Evolution
- (arxiv'23) Think-in-memory: Recalling and post-thinking enable llms with long-term memory [Paper]
- (EMNLP'23) Mot: Memory-of-thought enables chatgpt to self-improve [Paper]
- (ICML'24) A human-inspired reading agent with gist memory of very long contexts [Paper]
- (ICLR'26) Lightmem: Lightweight and efficient memory-augmented generation [Paper]
- (arxiv'25) General agentic memory via deep research [Paper]
- (arxiv'23) MemGPT: Towards LLMs as Operating Systems[Paper]
- (AAAI'24) Memorybank: Enhancing large language models with long-term memory [Paper]
- (ICLR'26) AgentFold: Long-Horizon Web Agents with Proactive Context Management [Paper]
Memory Architecture Evolution
- (ICML'25) M+: Extending MemoryLLM with Scalable Long-Term Memory [Paper]
- (arxiv'26) MemSkill: Learning and Evolving Memory Skills for Self-Evolving Agents [Paper]
- (arxiv'26) MemRL: Self-Evolving Agents via Runtime Reinforcement Learning on Episodic Memory [Paper]
- (NeurIPS'25) A-mem: Agentic memory for llm agents [Paper]
- (arxiv'25) Mem0: Building production-ready ai agents with scalable long-term memory [Paper]
- (NeurIPS'25) Cam: A constructivist view of agentic memory for llm-based reading comprehension [Paper]
- (arxiv'25) Memory as action: Autonomous context curation for long-horizon agentic tasks [Paper]
- (arxiv'25) Mem-α: Learning Memory Construction via Reinforcement Learning [Paper]
- (arxiv'25) Memevolve: Meta-evolution of agent memory systems [Paper]
- (arxiv'26) EvoRoute: Experience-Driven Self-Routing LLM Agent Systems [Paper]
Tool-Augmented Evolution
- (ICLR'26) Toward Effective Tool-Integrated Reasoning via Self-Evolved Preference Learning [Paper]
- (ICLR'23) React: Synergizing reasoning and acting in language models [Paper]
- (arxiv'21) Webgpt: Browser-assisted question-answering with human feedback [Paper]
- (ICML'23) Pal: Program-aided language models [Paper]
- (TMLR'24) Voyager: An open-ended embodied agent with large language models [Paper]
- (ICLR'24) Large language models as tool makers [Paper]
- (EMNLP'23 findings) Creator: Tool creation for disentangling abstract and concrete reasoning of large language models [Paper]
- (ICLR'24) Craft: Customizing llms by creating and retrieving from specialized toolsets [Paper]
- (ACL'25) Llm agents making agent tools [Paper]
- (ACL'25) Gödel Agent: A Self-Referential Agent Framework for Recursively Self-Improvement [Paper]
- (arxiv'25) Alita: Generalist agent enabling scalable agentic reasoning with minimal predefinition and maximal self-evolution [Paper]
- (arxiv'25) TOUCAN: Synthesizing 1.5M Tool-Agentic Data from Real-World MCP Environments [Paper]
- (arxiv'25) Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly? [Paper]
- (ICLR'26) EvoTest: Evolutionary Test-Time Learning for Self-Improving Agentic Systems [Paper]
- (arxiv'26) Beyond Static Tools: Test-Time Tool Evolution for Scientific Reasoning [Paper]
Agentic Topology Evolution
Offline Architecture Search
- (ICML'24) Language agents as optimizable graphs [Paper]
- (ICLR'25) Scaling large language model-based multi-agent collaboration [Paper]
- (arxiv'24) Autoflow: Automated workflow generation for large language model agents [Paper]
- (ICLR'25) Aflow: Automating agentic workflow generation [Paper]
- (ICLR'25) Automated design of agentic systems [Paper]
- (ICML'25) MAS-GPT: Training LLMs to build LLM-based multi-agent systems [Paper]
Runtime Dynamic Adaptation
- (COLM'25) Malt: Improving reasoning with multi-agent llm training [Paper]
- (arxiv'25) Adaptive Graph Pruning for Multi-Agent Communication [Paper]
- (IJCAI'24) Autoagents: A framework for automatic agent generation [Paper]
- (NAACL'25) Evoagent: Towards automatic multi-agent generation via evolutionary algorithms [Paper]
- (ICML'25) G-designer: Architecting multi-agent communication topologies via graph neural networks [Paper]
- (ICML'25) Multi-agent architecture search via agentic supernet [Paper]
- (NeurIPS'25) Rema: Learning to meta-think for llms with multi-agent reinforcement learning [Paper]
- (ICLR'26) Multi-agent design: Optimizing agents with better prompts and topologies [Paper]
Structural State Evolution
- (NeurIPS'25 workshop) Sedm: Scalable self-evolving distributed memory for agents [Paper]
- (arxiv'26) EvoConfig: Self-Evolving Multi-Agent Systems for Efficient Autonomous Environment Configuration [Paper]
- (NeurIPS'25) G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems [Paper]
- (arxiv'25) Collaborative Memory: Multi-User Memory Sharing in LLM Agents with Dynamic Access Control [Paper]
- (arxiv'25) Latent collaboration in multi-agent systems [Paper]
Model-Environment Co-Evolution 🔥
Multi-Agent Policy Co-Evolution
- (ICLR'26) Stronger-MAS: Multi-Agent Reinforcement Learning for Collaborative LLMs [Paper]
- (AAAI'26) LLM Collaboration with Multi-Agent Reinforcement Learning [Paper]
- (arxiv'26) Decentralized LLM Collaboration with Multi-Agent Actor Critic [Paper]
- (arxiv'26) Group-Evolving Agents: Open-Ended Self-Improvement via Experience Sharing [Paper]
- (arxiv'26) CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery [Paper] [Code]
- (ACL'25 findings) Optima: Optimizing effectiveness and efficiency for llm-based multi-agent system [Paper]
- (ACL'25) Maporl: Multi-agent post-co-training for collaborative large language models with reinforcement learning [Paper]
- (arxiv'25) Marft: Multi-agent reinforcement fine-tuning [Paper]
- (ICLR'26) CoMAS: Co-Evolving Multi-Agent Systems via Interaction Rewards [Paper]
Environment Training 🔥
Adaptive Curriculum Evolution
- (arxiv'25) GenEnv: Difficulty-Aligned Co-Evolution Between LLM Agents and Environment Simulators [Paper]
- (ICLR'26) Don't Just Fine-tune the Agent, Tune the Environment [Paper]
- (arxiv'25) Rlve: Scaling up reinforcement learning for language models with adaptive verifiable environments [Paper]
Scalable Environment Evolution
- (ICLR'26) Scaling agent learning via experience synthesis [Paper]
- (arxiv'25) AutoEnv: Automated Environments for Measuring Cross-Environment Agent Learning [Paper]
- (arxiv'26) Endless Terminals: Scaling RL Environments for Terminal Agents [Paper]
- (NeurIPS'25) REASONING GYM: Reasoning Environments for Reinforcement Learning with Verifiable Rewards [Paper]
- (ICLR'26) Gem: A gym for agentic llms [Paper]
- (arxiv'24) AgentGym: Evolving Large Language Model-based Agents across Diverse Environments [Paper]
- (arxiv'26) ScaleEnv: Scaling Environment Synthesis from Scratch for Generalist Interactive Tool-Use Agent Training [Paper]
- (arxiv'25) Towards General Agentic Intelligence via Environment Scaling [Paper]
- (arxiv'25) Simulating Environments with Reasoning Models for Agent Training [Paper]
- (arxiv'25) Feedback-Driven Tool-Use Improvements in Large Language Models via Automated Build Environments [Paper]
- (arxiv'25) AutoForge: Automated Environment Synthesis for Agentic Reinforcement Learning [Paper]
- (arxiv'26) EnvScaler: Scaling Tool-Interactive Environments for LLM Agent via Programmatic Synthesis [Paper]
- (arxiv'26) Agent-World: Scaling Real-World Environment Synthesis for Evolving General Agent Intelligence [Paper]
🏆 Benchmarks
Self-Evolution Evaluation
Benchmarks that evaluate whether agents can turn capability goals, interaction experience, or harness revisions into improvements on held-out tasks.
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| Aspire | Vague-Goal Self-Evolution | Text | Hidden Downstream Tasks, Model-Weight and Agent-Harness Updates | 🌐 Project | [Paper] |
| S3Gym | Experience-Based Self-Improvement | Text | Seven Games, Self-Testing and Self-Judging, Held-Out Evaluation | 🌐 Project | [Paper] |
| HarnessDev | Agent Harness Creation and Evolution | Text / Code | Runnable Harness Artifacts, Downstream Feedback, Held-Out Evaluation | 🌐 Project | [Paper] |
Intrinsic Capabilities
General Knowledge
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| MMLU-Pro | General Knowledge | Text | Robust Reasoning, 10-Choice | 🤗 HF | [Paper] |
| HotpotQA | General Knowledge | Text | Multi-hop Reasoning, Wiki-based | 🤗 HF | [Paper] |
| MMLU | General Knowledge | Text | Massive Multitask, 57 Disciplines | 🤗 HF | [Paper] |
| MuSiQue | General Knowledge | Text | Connected Multi-hop, Robustness | 💻 GitHub | [Paper] |
| NQ | General Knowledge | Text | Real User Queries, Open-Domain | 💻 GitHub | [Paper] |
| TriviaQA | General Knowledge | Text | Reading Comprehension, Triples | 🤗 HF | [Paper] |
| PopQA | General Knowledge | Text | Long-Tail Knowledge, RAG Focus | 🤗 HF | [Paper] |
| 2WikiMultiHopQA | General Knowledge | Text | Structured Multi-hop, Explanations | 🤗 HF | [Paper] |
| BBH | General Knowledge | Text | Challenging Tasks, CoT Focus | 💻 GitHub | [Paper] |
| AGIEval | General Knowledge | Text | Human-Centric Exams, General | 💻 GitHub | [Paper] |
| ARC | General Knowledge | Visual | Abstraction, Few-Shot Reasoning | 💻 GitHub | [Paper] |
| NarrativeQA | General Knowledge | Text | Long Context, Story Understanding | 💻 GitHub | [Paper] |
| LongBench | General Knowledge | Text | Long Context, Multi-Task Eval | 💻 GitHub | [Paper] |
| HLE | General Knowledge | Multimodal | Frontier Knowledge, Un-googleable | 🤗 HF | [Paper] |
Scientific Reasoning
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| GPQA | Scientific Reasoning | Text | Google-Proof, PhD-Level Experts | 💻 GitHub | [Paper] |
| SuperGPQA | Scientific Reasoning | Text | 285 Disciplines, Light Industry/Agri | 🤗 HF | [Paper] |
| SciBench | Scientific Reasoning | Text | College Science, Calculation | 💻 GitHub | [Paper] |
| ChemBench | Scientific Reasoning | Text | Chemistry, Autonomous Labs | 💻 GitHub | [Paper] |
| SciQA | Scientific Reasoning | Text | Scientific QA, Knowledge Graph | 🤗 HF | [Paper] |
Mathematical Reasoning
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| AIME | Mathematical Reasoning | Text | Competition Math, Hard Difficulty | 🤗 HF | [Paper] |
| OlympiadBench | Mathematical Reasoning | Multimodal | Visual Reasoning, Olympiad-Level | 💻 GitHub | [Paper] |
| GSM8K | Mathematical Reasoning | Text | Grade School Math, Chain-of-Thought | 🤗 HF | [Paper] |
| MATH | Mathematical Reasoning | Text | Challenging Math, Diverse Topics | 🤗 HF | [Paper] |
| AMC | Mathematical Reasoning | Text | Pre-Olympiad, Competition Math | 🤗 HF | [Paper] |
Code Generation
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| LiveCodeBench | Code Generation | Text | Contamination-Free, Dynamic | 💻 GitHub | [Paper] |
| BigCodeBench | Code Generation | Text | Complex Libraries, Instruction | 💻 GitHub | [Paper] |
| HumanEval | Code Generation | Text | Functional Correctness, Synthesis | 💻 GitHub | [Paper] |
| MBPP | Code Generation | Text | Basic Programming, Semantic | 💻 GitHub | [Paper] |
| EvalPlus | Code Generation | Text | Rigorous Eval, 80x Test Cases | 💻 GitHub | [Paper] |
| MultiPL-E | Code Generation | Text | 18+ Languages, Parallel Corpus | 💻 GitHub | [Paper] |
| CRUXEval | Code Generation | Text | Execution Simulation, CoT Focus | 💻 GitHub | [Paper] |
Agentic Reasoning Capabilities
Web Navigation
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| ClawBench | Web Navigation | Multimodal | Live Websites, Everyday Tasks, Auditable Traces | 💻 GitHub | [Paper] · [Project] |
| WebArena | Web Navigation | Text | Realistic Tasks, Long-Horizon | 💻 GitHub | [Paper] |
| WebShop | Web Navigation | Text | E-commerce, Decision Making | 💻 GitHub | [Paper] |
| MT-Mind2Web | Web Navigation | Text | Multi-Turn, Generalization | 🤗 HF | [Paper] |
| Mind2Web | Web Navigation | Text | Generalist Agent, Real Websites | 💻 GitHub | [Paper] |
| WebVoyager | Web Navigation | Multimodal | End-to-End, Visual Navigation | 💻 GitHub | [Paper] |
| VisualWebArena | Web Navigation | Multimodal | Visual/HTML, Interactive | 💻 GitHub | [Paper] |
Tool Usage
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| ToolLLM | Tool Usage | Text | Large-Scale APIs, Instruction Tuning | 💻 GitHub | [Paper] |
Unified Frameworks
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| AgentGym | Unified Frameworks | Multimodal | Interactive Learning, Diversity | 💻 GitHub | [Paper] |
| AgentBoard | Unified Frameworks | Multimodal | Analytic Dashboard, Unified | 💻 GitHub | [Paper] |
| Reasoning Gym | Unified Frameworks | Text | Algorithmic, Dynamic Tasks | 💻 GitHub | [Paper] |
| ALFWorld | Unified Frameworks | Text | Text-World, Household Tasks | 💻 GitHub | [Paper] |
| AgentBench | Unified Frameworks | Text | Comprehensive, Multi-Environment | 💻 GitHub | [Paper] |
| GAIA | Unified Frameworks | Multimodal | General Assistant, Hard Tasks | 🤗 HF | [Paper] |
| DeepResearch Bench | Unified Frameworks | Text | Long-form Research, Citation Eval | 💻 GitHub | [Paper] |
Software Engineering & OS Operations
| Name | Domain | Modality | Feature | Link | Paper |
|---|
| SWE-bench | Software Engineering | Text | Real GitHub Issues, Patch Gen | 💻 GitHub | [Paper] |
| Terminal-Bench | OS Operations | Text | Linux Command Line, Security | 💻 GitHub | [Paper] |
| OSWorld | OS Operations | Multimodal | GUI/Desktop, Cross-App | 💻 GitHub | [Paper] |
💻 Open Source Libraries
Foundational Agent Orchestration
| Library | Key Features | Link | Paper |
|---|
| LangGraph | Enables multi-actor applications with cyclic graphs for complex looping logic | 💻 GitHub | [Paper] |
| LlamaIndex | Integrates private data with LLMs via robust connectors and query engines | 💻 GitHub | [Paper] |
| AutoGen | Automates tasks via customizable agents using conversation and tool integration | 💻 GitHub | [Paper] |
| MetaGPT | Encodes SOPs into LLMs for role-based software development | 💻 GitHub | [Paper] |
| OpenProgram | Lets agents create and refine executable workflows while the runtime manages models, tools, memory, context, permissions, and multi-agent coordination | 💻 GitHub | [Paper] |
| Aeon | Runs autonomous coding agents inside GitHub Actions for continuous, self-directed task execution without approval loops | 💻 GitHub | [Website] |
| AgentDescent | Optimizes a shared library of skills, prompts, and harness modules by running N workers that propose diffs in parallel, with a barrier-free asynchronous aggregator that resolves conflicts and accepts merges on a Beta posterior over held-out reward | 💻 GitHub | [Docs] |
Distributed Training
| Library | Key Features | Link | Paper |
|---|
| Megatron-LM | Facilitates high-performance training utilizing multi-dimensional parallelism | 💻 GitHub | [Paper] |
| DeepSpeed | Optimizes memory efficiency featuring ZeRO technology | 💻 GitHub | [Paper] |
Post-training & Alignment
| Library | Key Features | Link | Paper |
|---|
| slime | High-Performance Training and Flexible Data Generation | 💻 GitHub | |
| VeRL | Provides a HybridFlow-based RL library with 3D-HybridEngine | 💻 GitHub | [Paper] |
| OpenRLHF | Supports distributed RLHF based on Ray and vLLM frameworks | 💻 GitHub | [Paper] |
| TRL | Offers a full-stack library for SFT, Reward Modeling, and RL alignment | 💻 GitHub | [Paper] |
Efficient Fine-tuning
| Library | Key Features | Link | Paper |
|---|
| LLaMA Factory | Provides a unified "code-free" WebUI supporting 100+ models | 💻 GitHub | [Paper] |
| Unsloth | Accelerates training via manually derived backpropagation and Triton kernels | 💻 GitHub | [Paper] |
Inference & Serving
| Library | Key Features | Link | Paper |
|---|
| vLLM | Serves models with high throughput utilizing PagedAttention | 💻 GitHub | [Paper] |
| SGLang | Manages structured generation using RadixAttention for aggressive cache reuse | 💻 GitHub | [Paper] |
🚀 Applications
Automated Scientific Discovery
| Application | Domain | Environment | Evolution Mechanism | Core Technology | Breakthrough Results | Link | Paper |
|---|
| Agon | Omnidisciplinary Research | Prompt-driven research workspace | Generate/Critique loops | Prompt Economy | 30-day unattended run | 💻 GitHub | [Paper] |
| The AI Scientist | Academic Research | Simulated review system | Gen-Review cycle | Auto peer-review | Paper auto-generation | 💻 GitHub | [Paper] |
| AlphaProof | Logic & Math | Lean verifier | Search-Verify loop | Prover net | IMO 2024 silver-level | 🌐 Web | [Paper] |
| ChemCrow | Chemistry | Lab tools | Plan-Safety-Execute loop | Robotics control | Generalized lab automation | 💻 GitHub | [Paper] |
| Coscientist | Automated Science | Lab env; hardware APIs | Hypothesis–Debate loop | Multi-agent debate | Zero-shot hardware control | 💻 GitHub | [Paper] |
| GNoME | Materials Science | DFT simulation space | Active learning loop | GNN predictor | 2.2M stable crystals | 💻 GitHub | [Paper] |
| A-Lab | Materials Science | Robotic lab | Active-learning synthesis | ML-guided planning | 71% synthesis success | 🌐 Web | [Paper] |
| CRESt | Catalysis Discovery | Multimodal robotic lab | Multimodal BO loop | KABO; VLM | 9.3× cost-performance gain | 🌐 Web | [Paper] |
| FARS | Academic Research | Open research workspace | Hypothesis loop | Multi-agent automation | Auto paper generation | 🌐 Web | [Paper] |
Autonomous Software Engineering
| Application | Domain | Environment | Evolution Mechanism | Core Technology | Breakthrough Results | Link | Paper |
|---|
| agent-qa | Software QA | Browser; mobile apps; CI | Experience-backed run memory | Playwright; Appium; MCP/skills | Self-healing regression detection | 💻 GitHub | [Docs] |
| SWE-agent | Software Engineering | Terminal; codebase; CI | Error-feedback correction | ACI interface | High bug-fix success rate | 💻 GitHub | [Paper] |
| Claude Code | Long-term Engineering | Project history | Skill accumulation | Skill memory | Senior-level coding | 🌐 Web | [Paper] |
| Manus | Software Engineering | Cloud VM sandbox | Plan-Act-Verify loop | CodeAct | Human-like env interaction | 🌐 Web | [Paper] |
| OpenClaw | Local Agents | Local FS | Community skill | Skill hub | Long-term local adaptation | 🌐 Web | [Paper] |
| Ouroboros | Software Engineering | Local desktop; CLI; project workspaces | Reviewed self-modification | Durable identity and memory | Continuity across tasks and restarts | 💻 GitHub | [Paper] |
| Devin | Software Engineering | Browser; terminal; IDE | Web-based correction | Tool autonomy | Fully autonomous SWE | 🌐 Web | [Paper] |
| Cursor | Human-AI Coding | Repo index; shadow env | Human-AI co-evolution | Shadow workspace | Productivity co-adaptation | 🌐 Web | [Paper] |
| hmharness | HarmonyOS Development | Terminal; HarmonyOS toolchain; emulator | Bench-gated skill evolution; canary A/B deployment | Zero-dependency agent kernel (7 npm packages) | 30-day self-feeding evidence protocol | 💻 GitHub | [Docs] |
Open-World Simulation
| Application | Domain | Environment | Evolution Mechanism | Core Technology | Breakthrough Results | Link | Paper |
|---|
| Voyager | Gaming (Minecraft) | Minecraft open world | Explore–Code–Store | Auto curriculum | 15.3× faster progression | 💻 GitHub | [Paper] |
| GITM | Gaming (Minecraft) | Minecraft open world | Decompose-Plan-Act | Text memory | +47.5% success (Diamond) | 💻 GitHub | [Paper] |
| Cradle | General Computer Control | GUI interface | Observe-Plan-Act loop | MLLM; skill curation | API-free computer control | 💻 GitHub | [Paper] |
| Project Sid | Digital Civilization | Multi-agent society | Social norm co-evolution | PIANO | Emergent economy & laws | 💻 GitHub | [Paper] |
| Generative Agents | Social Simulation | Virtual town sandbox | Observe-Reflect-Plan | Reflection | Emergent group activities | 💻 GitHub | [Paper] |
| SIMA | Embodied AI | Generative 3D worlds | GenEnv feedback loop | World model | Embodied data reduction | 🌐 Web | [Paper] |
| Genie | World Modeling | Text-to-3D worlds | Interactive world loop | Generative world model | Persistent 3D worlds | 🌐 Web | [Paper] |
🍀 Citation
If you find this survey helpful, please cite our paper:
@article{xiang2026systematic,
  title={A Systematic Survey of Self-Evolving Agents: From Model-Centric to Environment-Driven Co-Evolution},
  author={Xiang, Zhishang and Yang, Chengyi and Chen, Zerui and Wei, Zhimin and Tang, Yunbo and Teng, Zongpei and Peng, Zexi and Li, Zongxia and Huang, Chengsong and He, Yicheng and others},
  journal={Available at SSRN 6626878},
  year={2026}
}


