
DietrichGebert/ponytailPlugins
Makes your AI agent think like the laziest senior dev in the room. The best code is the code you never wrote.
138k
1 add
Codex Autoresearch adds a measured experiment loop to Codex. You give it a benchmark, checks, a scope, and a budget, and it records the baseline, evaluates candidate changes, and keeps a patch only when the evidence supports it.
Builders who want Codex to try many small code changes against a measurable target.
You can improve runtime, build speed, memory use, or other metrics with a reviewable experiment trail.
Measures a baseline before changes and rechecks each candidate against the same benchmark.
Uses an approved contract with goal, metric, checks, scope, noise rules, and time or packet limits.
Leaves accepted changes with the evidence needed to review what improved and why.
Shows what improved, what passed, what is blocked, and the next action from the same session state.
Keeps temporary packet state under `.git/autoresearch/` in Git repos and supports cleanup on discard or failure.
/plugins
codex plugin marketplace add TheGreenCedar/AgentPluginMarketplace --ref main
/goal @Codex Autoresearch help me design a trustworthy benchmark for my indexer's speed and memory use.
Do this as a direct review first. Do not create a session until I approve a complete repeated experiment contract.
Install - Try it - How it works - Dashboard - Docs
Codex Autoresearch helps improve local code against a repeatable benchmark. Give it a workload, correctness checks, an edit boundary, and a time budget. It records the baseline, evaluates small changes, and leaves a reviewable patch with the evidence behind it.
Use it for bounded performance or resource-use experiments: faster tests, lower build time, less memory, or higher throughput on a defined workload. Reviews, documentation, product research, and one-off fixes normally stay ordinary Codex work.
Version 3.0 also supports investigations where you know the outcome you want but have not settled on a method. You accept the objective, allowed changes, evidence requirements, and budget once. Preparation, failed attempts, repairs, confirmation, and delivery all use that same allowance. Goals without a numeric metric can use explicit conditions and counterexamples. See Bounded investigations, or use the short benchmark path below.
The 3.0 release is based on engineering verification. No model-driven comparison has been run, so it makes no claim of better outcomes or lower cost than ordinary Codex or 2.9.0. The optional comparison protocol and collection harness stays disabled unless a study receives a separate budget.
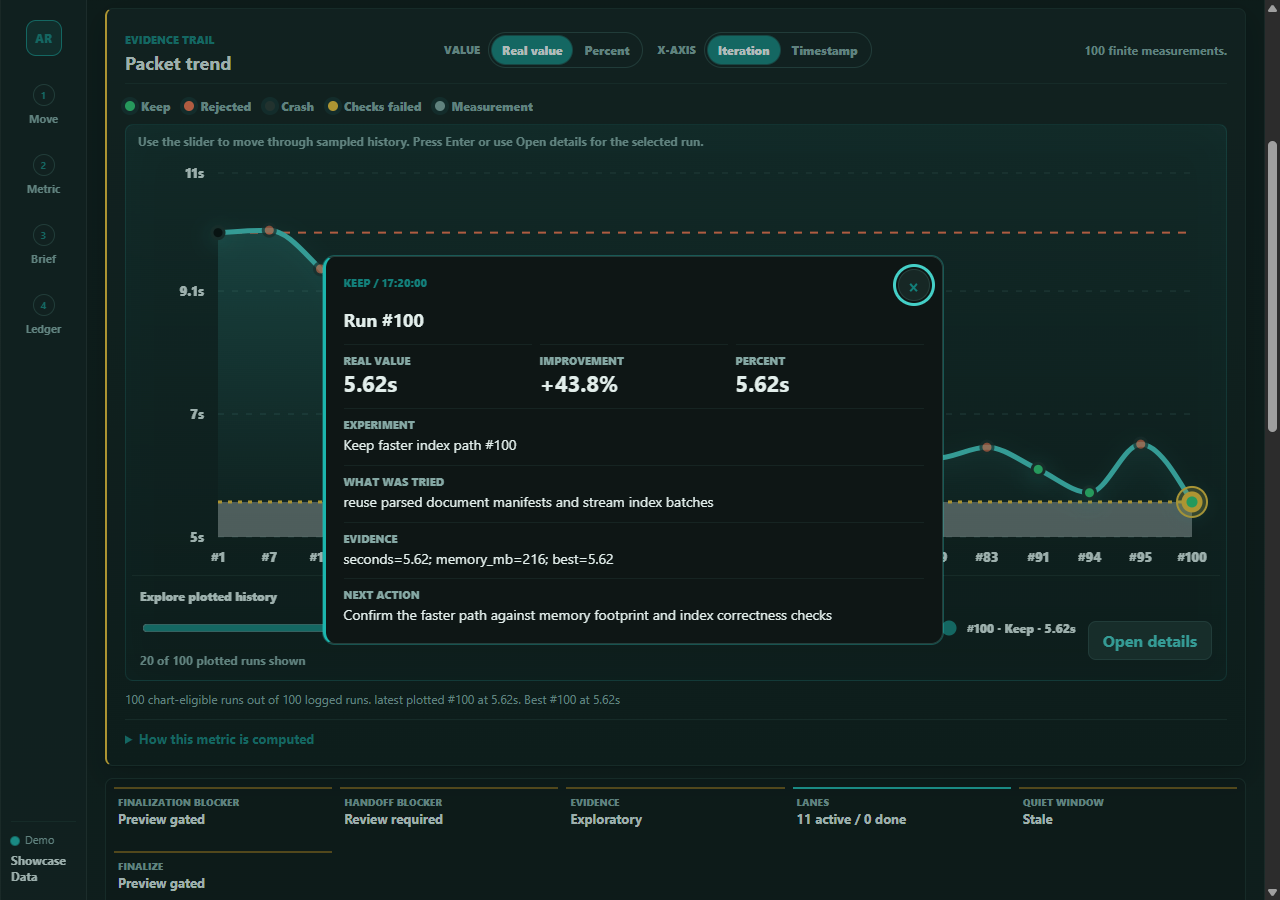
The screenshot uses synthetic example data.
The loop is inspired by karpathy/autoresearch and pi-autoresearch. This version is built around Codex, local repositories, and ordinary reviewable Git work.
Open the plugin picker in Codex:
/plugins
Choose TheGreenCedar -> codex-autoresearch -> Install plugin, then start a new Codex task in the repository you want to improve.
If your Codex build supports marketplace management from the terminal, you can register the source marketplace first:
codex plugin marketplace add TheGreenCedar/AgentPluginMarketplace --ref main
The marketplace lives in TheGreenCedar/AgentPluginMarketplace; this repository is the plugin source.
After installing the plugin, open Codex in the repository you want to improve and give it a goal, a benchmark, and a boundary. Use this as a starting point for the contract:
/goal @Codex Autoresearch run a measured loop to reduce parser runtime.
Benchmark: node bench/parser.mjs
Metric: seconds (s), lower is better
Checks: node --test tests/parser.test.mjs
Scope: src/parser.mjs
Protect bench/parser.mjs and tests/parser.test.mjs.
Measure two baselines and repeat each candidate before a keep.
Stop after 5 packets or 30 minutes; repeat measurements count toward that limit.
Propose the complete contract for approval before setup or execution.
Codex first presents the workload, checks, scope, and budget for review. After you accept the contract, Autoresearch measures the baseline before any candidate change. Commands and paths in the example must match your project.
If you do not know what the benchmark should be, say what outcome you want and ask Codex to propose one:
/goal @Codex Autoresearch help me design a trustworthy benchmark for my indexer's speed and memory use.
Do this as a direct review first. Do not create a session until I approve a complete repeated experiment contract.
Codex can inspect a few relevant project files to propose commands and paths, citing where each came from. Those proposals are unaccepted until you review the complete contract. Missing goals, metric meaning, budgets, and product tradeoffs remain decisions to make before a run.
The normal route starts with fit:
fit -> continue directly | ask for contract input | run accepted loop
Architecture reviews, documentation, UX, product study, open-ended research, taste, and one-shot fixes normally continue directly. In direct mode Codex states the outcome and uncertainty, gathers the cheapest useful evidence, does the task, verifies it, and bounds the claim. Autoresearch creates no session files or other state in that path, and an unrelated existing session remains untouched.
When repeated measurement does fit, the loop is short:
setup -> accept contract -> state -> next -> log -> state -> finalize-preview
Setup prepares an experiment contract for explicit acceptance: goal, repository and checkout, typed metric semantics, evaluator, independent checks, scope, noise, keep and stop rules, and budgets. state compiles the current files and Git state into one decision. next may run only the evaluator and checks accepted by that contract. log records whether the result was a baseline, a keep, a discard, or a failure, then returns the resulting decision. When there is useful work to review, finalize-preview supplies the current accepted changes, exclusions, and blockers for a compact evidence receipt. A single coherent change can be handed off on the existing branch; separating mixed experiment history into new branches is an advanced step.
The benchmark must print at least one line in this form:
METRIC seconds=12.34
The primary metric decides whether the result moved in the right direction. Checks protect correctness. Secondary metrics can catch known tradeoffs such as lower runtime with much higher memory use.
Autoresearch stores the session record in the target project. In a Git repository, temporary packet state lives under .git/autoresearch/; outside Git it falls back to local worktree files. State, doctor, recommendations, finalization, and the dashboard all use the same snapshot and decision. They retry if the sources change during a read.
Some commands can change Git state. Keeping a result can create a commit limited to configured paths. Discards, crashes, and failed checks can clean up the configured or explicitly supplied experiment paths. A plain measurement never stages, commits, or reverts anything. Finalization begins with a read-only preview, and review branches are created only after approval. The details are in Trust.
Autoresearch is a good fit when you can measure the outcome repeatedly, keep the benchmark reasonably stable, protect correctness with checks, and name the part of the repository Codex is allowed to change. It is especially useful when several small attempts are more likely to teach you something than one large rewrite.
It is probably the wrong tool for a one-off edit, a result that is mostly a matter of taste, or a benchmark so slow and noisy that another measurement adds little information.
The optional dashboard shows what improved, what passed, what is blocked, and the next action. Audit details are available when you need to trace a result. It is read-only; commands still run through Codex and the CLI.
Ask Codex to serve it for a live readout or export a snapshot for review.
Autoresearch does not have a hosted backend of its own, but it runs inside a Codex session. The Codex service or model provider is a separate data path governed by its own settings and terms. Commands you approve run with your local permissions: a benchmark can read files, start processes, use credentials available through explicit packet variables or operating-system stores, contact external services, and cost money if those services charge for use. Packet processes receive a minimal environment by default; inheriting the caller's full environment requires --packet-env-mode inherit.
Keep secrets out of command lines, output, experiment notes, and artifacts. Redaction is best-effort, not a security boundary. Treat ledgers and dashboard exports as project records that may contain paths, command names, output excerpts, and notes about what Codex tried.
Read Trust, Privacy, and Terms before using the plugin on sensitive repositories or expensive workloads.
The Docs index has the rest, including workflow diagrams and the architecture.
Use /plugins to refresh or uninstall the workspace plugin. Where terminal marketplace management is available, these commands manage the source registration:
codex plugin marketplace add TheGreenCedar/AgentPluginMarketplace --ref main
codex plugin marketplace upgrade TheGreenCedar
codex plugin marketplace remove TheGreenCedar
Removing a marketplace registration may not uninstall a plugin that is already installed in a workspace. Use the plugin UI for that.
Source development requires Node.js 24 or newer, npm, and Git. See Contributing for local setup and verification. Packaging and release work is covered in Maintainers, and user-facing changes are recorded in CHANGELOG.md.
Apache License 2.0. Copyright (c) 2026 Albert Najjar.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
Makes your AI agent think like the laziest senior dev in the room. The best code is the code you never wrote.

Graphs that teach > graphs that impress. Turn any code into an interactive knowledge graph you can explore, search, and ask questions about. Works with Claude Code, Codex, Cursor, Copilot, Gemini CLI, and more.

OmO: Just type "mass ulw" keyword with your prompt. Now you are the master of graph engineering.
Persistent Context Across Sessions for Every Agent – Captures everything your agent does during sessions, compresses it with AI, and injects relevant context back into future sessions. Works with Claude Code, OpenClaw, Codex, Gemini, Hermes, Copilot, OpenCode + More
Opinionated Oxlint rules for rejecting low-evidence TypeScript and JavaScript patterns
Teams-first Multi-agent orchestration for Claude Code