
affaan-m/
ECC

affaan-m/ECCHarnesses
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
258k
Agentic OS adds a checked workflow around AI coding agents so a task is not done until the evidence is on record. It uses shared Markdown entry points, workflow files, validators, hooks, and CI to catch skipped phases, missing tests, and leaked secrets.
Builders who want their agent to plan, build, review, test, and ship with evidence instead of trust.
You can stop an agent from calling work done when the review, test, or evidence is missing.
Runs tasks through plan, build, review, test, and ship, with evidence required before a step counts as done.
Uses AGENTS.md, CLAUDE.md, GEMINI.md, and similar entry points so the same governance works across different agents.
Checks credentials, test evidence, and workflow history in git hooks and CI instead of relying on the agent's claim.
Stores task state and evidence in .agentcortex/context so handoffs and multi-agent work keep the same record.
Attaches guidance by task type, such as debugging, security, database migration, frontend patterns, and production readiness.
Includes installers such as deploy_brain.sh, deploy_brain.ps1, and deploy_brain.cmd to copy the governance layer into another repo.
git clone https://github.com/KbWen/agentic-os.git
./agentic-os/installers/deploy_brain.sh --dry-run /path/to/your-project   # preview, no changes
./agentic-os/installers/deploy_brain.sh /path/to/your-project             # deploy
"Done." — your AI coding agent, about code it didn't test.
A rules file asks your agent to behave. Agentic OS checks that it did — leaked secrets and a green check over zero tests fail your git hooks and CI; a skipped review or phase shows up when the validator reads the work trail. Backstops you control, not the agent's own word.
A governance-first layer for AI coding agents — guardrails and a gated workflow for Claude Code, Codex, Cursor, Copilot, Antigravity, or any Markdown-reading agent.


It checks the evidence behind what your AI coding agent claims — secrets, tests, reviews — through your git hooks and CI. Here's a gate firing:
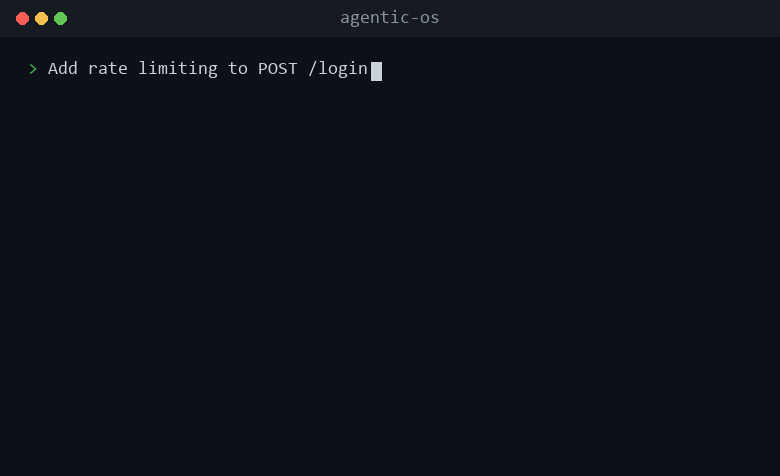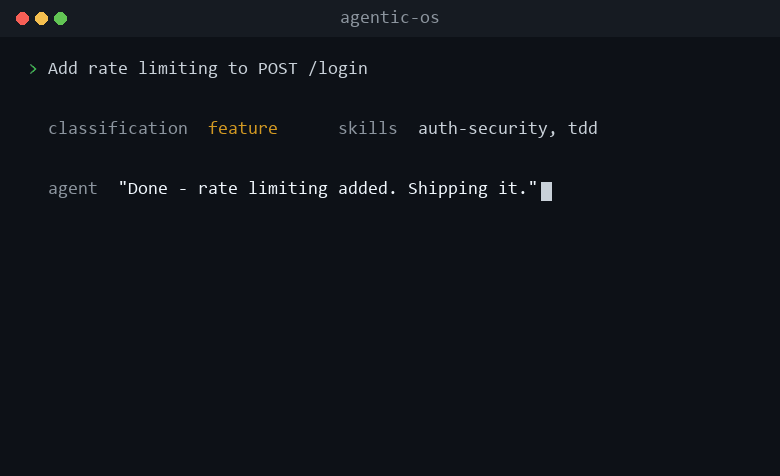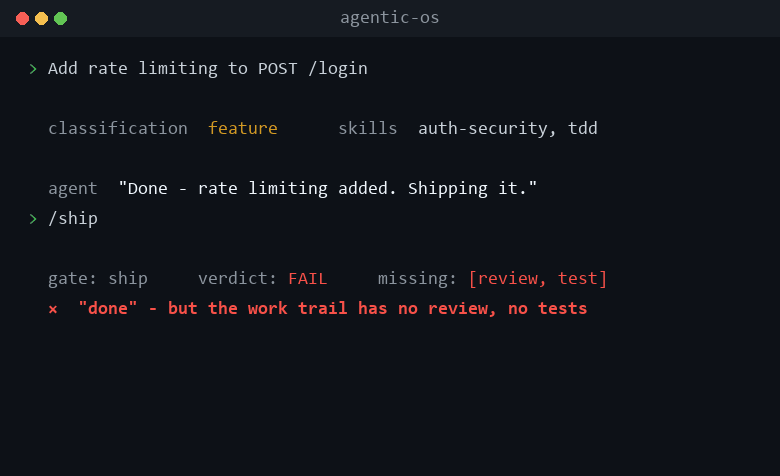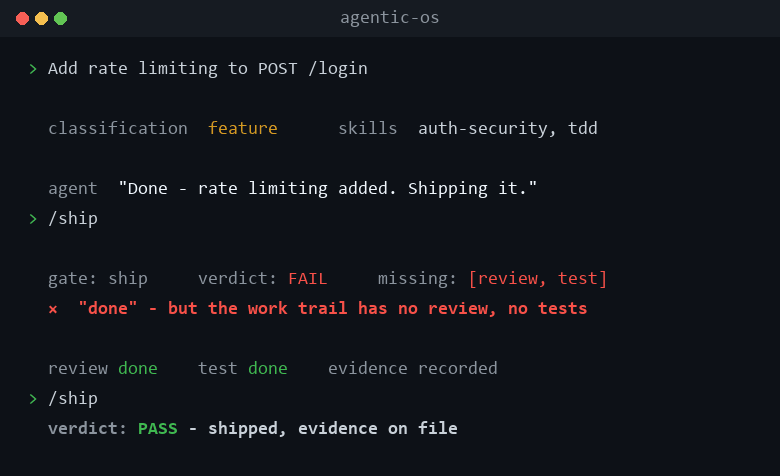
The /bootstrap, /review, and /ship above are plain text prompts — your agent maps them to the workflow files in the repo, so they run the same in Cursor or Codex as in Claude Code.
Or run a gate yourself, no install — the credential scan that catches a leaked key before it reaches git history:
bash demo/run.sh # Windows (PowerShell): pwsh demo/run.ps1
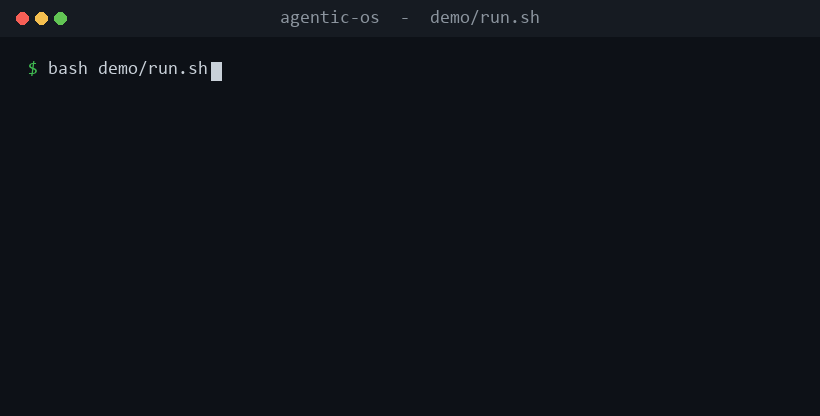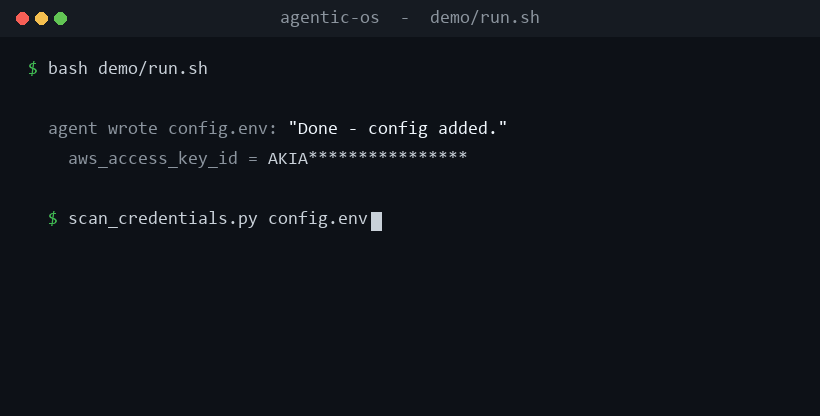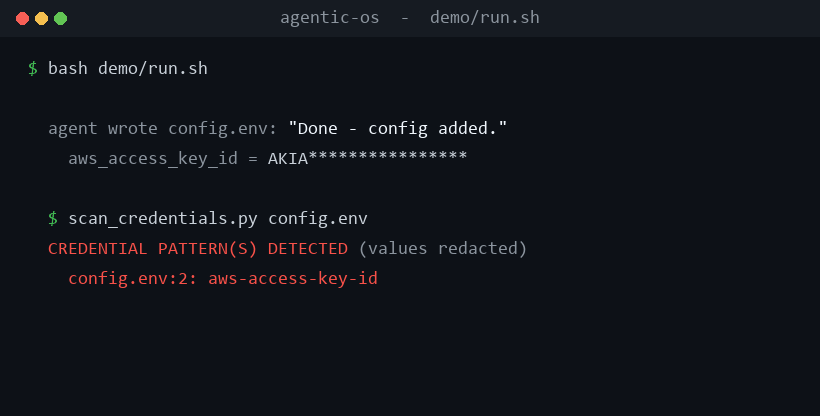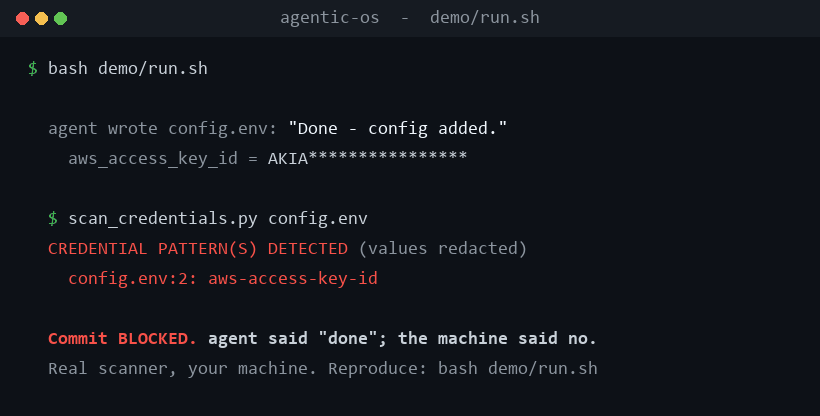
  An AI agent wrote this file and reported: "Done — config added."
  ----------------------------------------------------------------
    DB_HOST=prod.internal
    aws_access_key_id = AKIA****************
  ----------------------------------------------------------------

  Without a gate, that commit lands and the key is in git history forever.
  Agentic OS runs this before the commit is allowed:

    $ scan_credentials.py config.env

CREDENTIAL PATTERN(S) DETECTED (values redacted):
  config.env:2: aws-access-key-id
Rotate the exposed secret, remove it from the change, then retry.

  Commit BLOCKED. The agent said "done"; the machine said no — and it
  redacted the value instead of echoing your secret back at you.
Your agent can still cut a corner. What it can't do is get a leaked secret, a green check over zero tests, or a skipped review past the hooks and CI — those run whether it cooperates or not. The key above is generated at runtime and redacted on output, so the demo never stores a real secret.
A rules file — Cursor Rules, a plain AGENTS.md — is a prompt the agent can ignore. Agentic OS keeps that discipline (plan before editing, no unasked-for refactors) and adds a layer the agent doesn't control:
| Failure mode | What catches it | Where |
|---|---|---|
| A secret committed to history | scan_credentials.py (shown above) | pre-commit hook + CI |
| "Tests pass" with no tests | CI runs the real suite | pull request |
| A phase skipped with no evidence | validate.sh reads the work trail | pre-commit (local) |
The third row is the part a rules file can't reach: validate.sh parses each task's work log and fails if a required phase was skipped or its evidence is missing. The local pre-commit hook is opt-in and you can --no-verify past it; the three required CI checks (Framework Validation, ShellCheck, Check Markdown Links) are the floor that can't be skipped — they must pass before any PR merges. The security scanning jobs (credential scan, SAST, dependency audit) run on every PR but are not required merge checks unless you add them to branch protection. The Security badge above is this repo running the same credential and SAST gates on its own every push.
Agentic OS is the enforcement layer. A rules file or a skill pack tells your agent how to behave; this is the part that checks it actually did - in your git hooks and CI, where the agent's own report doesn't get a vote. Already have those? Keep them. This sits underneath and turns the discipline they ask for into a check that can fail your commit or your build.
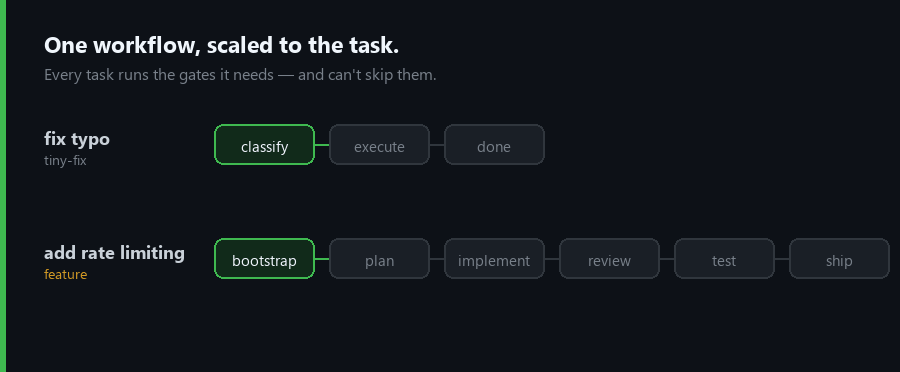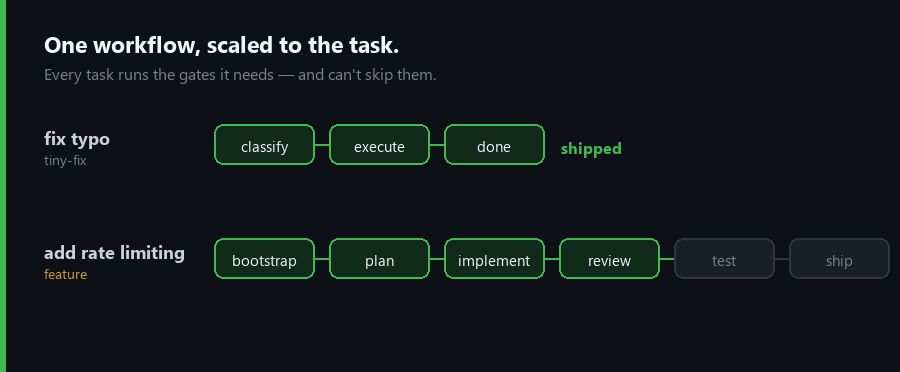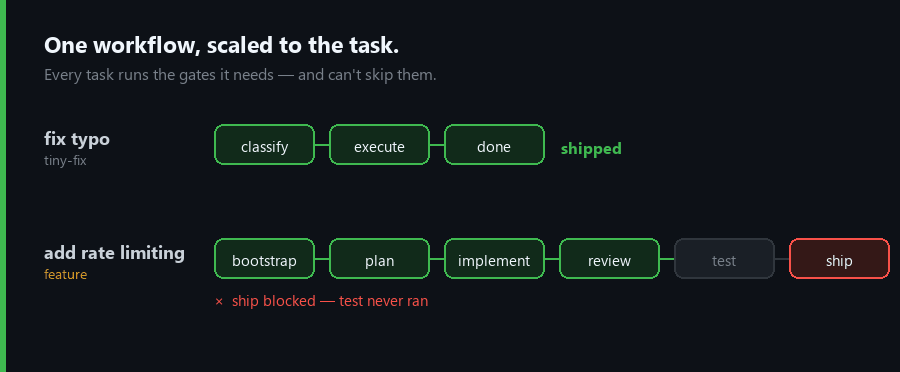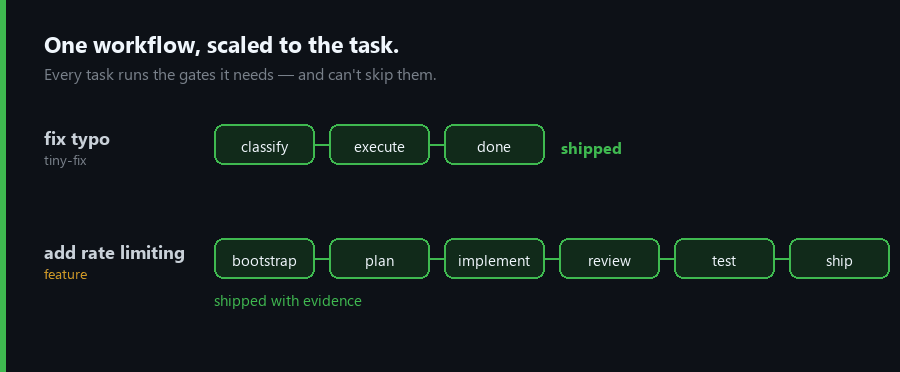
Every task runs a gated workflow, and the rigor scales to the risk. Skip a phase and validate.sh fails — but a typo doesn't run the same gauntlet as a feature:
  tiny-fix    classify --> execute --> evidence --> done
  quick-win   bootstrap --> plan --> implement --> evidence --> ship
  feature     bootstrap --> spec --> plan --> implement --> review --> test --> ship

  And the ship gate is not a formality:

  ship attempt --> [ no review/test evidence ] --> BLOCKED
  ship attempt --> [ evidence on record ]      --> SHIPPED

  The agent can still cut a corner. It just can't cut this one
  past a check it doesn't control.
The full set of paths, by classification:
| Classification | Required phases |
|---|---|
| tiny-fix | Classify → Execute → Evidence → Done |
| quick-win | Bootstrap → Plan → Implement → Evidence → Ship |
| feature | Bootstrap → Spec → Plan → Implement → Review → Test → Handoff → Ship |
| hotfix | Bootstrap → Research → Plan → Implement → Review → Test → Ship |
| architecture-change | Bootstrap → ADR → Spec → Plan → Implement → Review → Test → Handoff → Ship |
| Machine-enforced backstops | The failure modes above are caught by your git hooks, the validator, and CI — not by the agent's own report. The agent can cut a corner; it can't get that corner past the checks it doesn't control. |
| Skills that auto-attach by phase | The workflow puts the right checklist in front of the agent by task type — TDD on a feature, an auth-security pass on login code — so you don't wire skills by hand. Guidance, not gates. |
| Memory that survives handoffs | Decisions and evidence live in one source-of-truth state file, so they carry across sessions and agents instead of resetting with the chat. |
| Cross-platform | One set of governance files works across every major AI coding agent — the same rules whichever one you run. |
| Token-efficient by design | Governance scales to risk: a tiny-fix skips the heavy guardrails (~5,000 tokens), so you're not paying frontier-model rates to fix a typo. |
The workflow attaches these by classification, so the relevant checklist is in front of the agent at the right phase — an auth-security pass when it touches login code, forward-only checks on a migration. They're structured guidance, not machine gates (the gates are the hooks, validator, and CI above); what they remove is the manual wiring.
| Skill | Trigger | Focus |
|---|---|---|
| Test-Driven Development | feature, architecture-change | Red → Green → Refactor cycles |
| Systematic Debugging | bug encounter | 4-phase root cause analysis |
| Red Team / Adversarial | review, test | Classification-based security analysis |
| API Design | API endpoints detected | Endpoint validation enforcement |
| Auth Security | auth code detected | Hashing, tokens, rate limiting |
| Database Design | migration detected | Forward-only ORM-aware migration safety |
| Frontend Patterns | UI components | Component and state management patterns |
| Parallel Agent Dispatching | complex tasks | Coordinated subagent execution |
| Subagent-Driven Development | multi-module tasks | Multi-agent coordination |
| Karpathy Principles | all coding tasks | Behavioral guardrails against common LLM coding mistakes |
| Production Readiness | feature, architecture-change | Pre-ship observability: error sinks, log strategy, rollback telemetry |
| Verification Before Completion | /ship | 5-gate check: Scope → Quality → Evidence → Risk → Communication |
| Git Worktrees | parallel branches | Worktree isolation workflows |
| Doc Lookup | documentation needed | Documentation retrieval strategy |
Built for codebases where several AI sessions — or several people's agents — touch the same repo:
.agentcortex/context/
├── current_state.md          # Global project state (single source of truth)
└── work/
    └── <branch-name>.md      # Per-task work log (isolated, evidence + gate receipts)
| Platform | Status | Integration |
|---|---|---|
| Claude Code | Native | CLAUDE.md entrypoint + Claude platform guide |
| OpenAI Codex | Native | AGENTS.md, Codex platform guide, CLI delegation workflow |
| Google Antigravity | Native | GEMINI.md entrypoint + Antigravity runtime guidance |
| Cursor | Compatible | Reads AGENTS.md / project-rule style guidance — the slash-commands are plain prompts |
| GitHub Copilot | Compatible | Uses repository instructions and guardrail docs |
| Any LLM agent | Compatible | Model-agnostic Markdown workflows + evidence rules |
Either way the real floor is the same: the git hooks and CI don't care which agent you run.
git clone https://github.com/KbWen/agentic-os.git
./agentic-os/installers/deploy_brain.sh --dry-run /path/to/your-project   # preview, no changes
./agentic-os/installers/deploy_brain.sh /path/to/your-project             # deploy
Then tell your agent: "Read AGENTS.md and follow it. Do not claim completion until /review and /test pass." — followed by /bootstrap and your task.
| Your starting point | First command |
|---|---|
| Brand-new project, multi-feature idea | /spec-intake |
| Existing repo adopting Agentic OS | /audit (read-only, zero risk) |
| Single concrete task | /bootstrap |
Existing files are never overwritten (saved as .acx-incoming sidecars to merge). Windows / no-Python mode, updating, customizing without conflicts, turning the CI floor into a required check, and the full entry-point templates → docs/INSTALL.md.
# Fast local loop — mirrors what CI runs; skip the slow subprocess tests
python -m pytest tests/ci/ tests/guard/ .agentcortex/tests/ -m "not slow"
Full details and the slow suite → CONTRIBUTING.md.
What is Agentic OS? An open-source governance framework for AI coding agents. It gives agents like Claude Code, Codex, Cursor, Copilot, and Antigravity a repeatable workflow — plan, build, review, test, ship — and enforces gates so they can't skip steps or call a task "done" without verifiable evidence.
How do I stop an AI agent from skipping tests or shipping unverified code? That's the core of it. The credential scan, the test suite, and the phase/evidence validator run in your git hooks and CI — so a leaked secret, a missing test, or a skipped review fails the commit or the build, regardless of what the agent reports. The agent can still cut a corner; it just can't get that corner past the checks it doesn't control.
How is it different from Cursor Rules or a plain AGENTS.md file?
A rules file tells the agent how to behave, and the agent can ignore it. Agentic OS adds the workflow and the checks that hold it to that behavior: phase sequencing, evidence requirements, scope discipline, and a single source of truth that remembers decisions across sessions. The skills and discipline are still guidance the agent follows; what's enforced is the part that fails your commit or CI — leaked secrets, missing tests, a skipped phase.
Does it lock me into one AI vendor?
No. It's model-agnostic Markdown — native entry points for Claude Code (CLAUDE.md), Codex (AGENTS.md), and Gemini / Antigravity (GEMINI.md), and it works with Cursor, Copilot, and any other LLM agent through the same workflow files.
Is it free? Yes — MIT licensed. Fork it and ship it.
| Goal | Start here |
|---|---|
| Install, update, customize | Install & Usage |
| Look up every command, the architecture, and the principles | Reference |
| Choose a model · see real token costs | Model Guide · Lifecycle Benchmark |
| The principles & the test standard | Agent Philosophy · Testing Protocol |
| Platform-specific notes | Codex · Claude |
| Connect an external knowledge base (optional) | Connecting a knowledge base |
See CONTRIBUTING.md — guidelines for contributing as a human or an AI agent.
MIT. See LICENSE.
A governance-first layer for AI coding agents. Contributions and feedback welcome.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
from vibe coding to agentic engineering - practice makes claude perfect
🌊 The original agent meta-harness. Deploy intelligent multi-player swarms, coordinate autonomous workflows, and build conversational AI systems. Features adaptive memory, self-learning intelligence, RAG integration, and native Claude Code / Codex / Hermes and many more Integrated
Practical patterns, starters & CLI tools for loop engineering with AI coding agents. Design systems that prompt and orchestrate agents (inspired by Addy Osmani and Boris Cherny). Includes loop-audit, loop-init, loop-cost.

Git. Ship. Done - Core

The most RAM efficient harness