
affaan-m/
ECC

affaan-m/ECCHarnesses
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
258k
omd sits under a coding agent and turns a job into a typed graph of nodes. Each node can use a chosen model, a command, or a verifier, and the run is accepted by outside checks like exit codes and file writes instead of the model's own word. It ships as a Bun CLI and MCP server, so you can drive it from Claude Code or another MCP host. The repo also includes ready-made client skills and docs for pipelines like review, debug, research, and delivery.
Builders who want Claude Code or another MCP-capable agent to run work through reusable graphs, checks, and model handoffs.
You can make agent-led work finish with deterministic checks, second opinions, and resumable runs instead of trusting a single model turn.
Runs work as a zod-validated graph of nodes with declared inputs and outputs.
Lets you pick a model for each node, with explicit pins, templates, or auto-assignment across seats.
Uses command exit codes, write-set reconciliation, and artifact checks to decide whether work is done.
Can send the result to a different model family for a second opinion when an exit code is not enough.
Reloads a saved graph state and reruns only the changed nodes.
Runs as a CLI first and an MCP server second, so the same binary can be used from terminals, CI, and hosts.
Ships reusable skills such as `omd-review`, `omd-debug`, `omd-research-deep`, and `omd-deliver`.
git clone https://github.com/AbyssCN/oh-my-dag.git && cd oh-my-dag
bun install && bun link
omd init
cd <your-project> && claude mcp add omd -- omd mcp
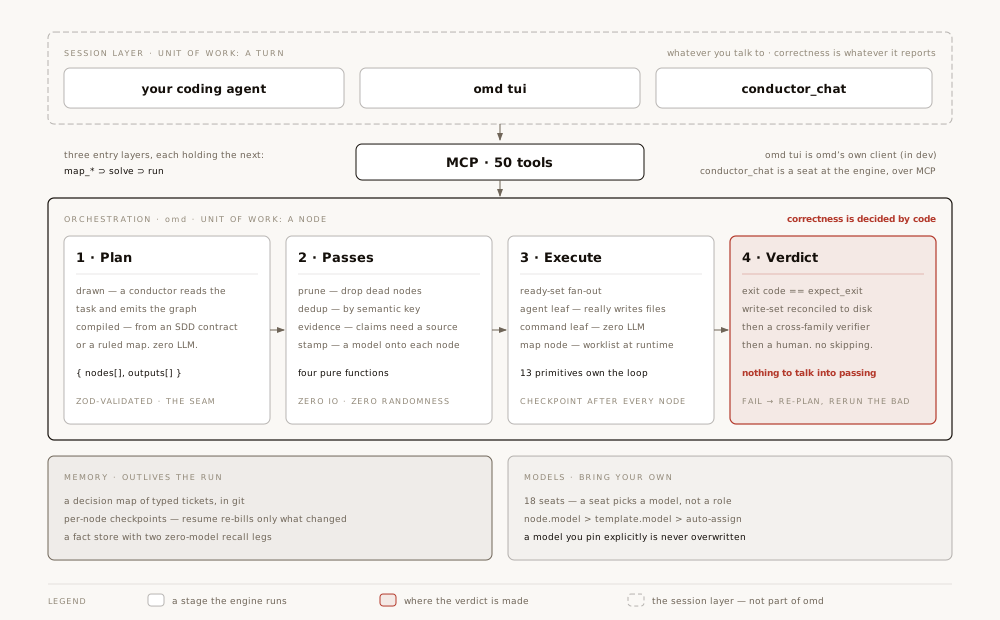
The orchestration layer under your coding agent.



English · 简体中文 · Why omd exists · Give this to your agent
Your agent says it's done. omd doesn't take its word for it.
50 MCP tools · 13 control-flow primitives · 18 model seats · 22 shipped pipelines · 6,818 tests.
git clone https://github.com/AbyssCN/oh-my-dag.git && cd oh-my-dag
bun install && bun link
omd init
Then point your agent at it:
cd <your-project> && claude mcp add omd -- omd mcp
omd init asks for keys, offers three preset model matrices, probes each provider, and writes .env. First server start drops 22 skills into ~/.claude/skills/ — idempotent, never clobbers one you edited. Not on npm yet, so the clone is the install.
After install, omd is a CLI first, MCP server second. The same omd binary runs every MCP
tool as a named subcommand, an escape hatch (omd call), and a diagnostic (omd doctor) — so
cron, CI, TUI and any non-MCP host can drive the engine without spawning an MCP server. See
the CLI guide for the full command reference.
Then tell your agent: read docs/driving-omd.md, then use omd to… — that file is the operating guide, written for the agent rather than for you.
Every coding harness shipping today owns the turn. Sample the model, run its tools, feed the result back, repeat, and stop when the model says it's finished. They compete on context compaction and sandbox depth, and they compete well — but the forward pass that wrote the code is the same one grading it. There is nowhere else for a verdict to come from without leaving the session.
omd leaves it. The unit of work is a node in a typed graph, and the graph is a file: { nodes[], outputs[] }, zod-validated. A node has declared inputs, so it can be scheduled, checkpointed, resumed, priced, and judged on its own. A turn has none of that.
Keep the agent you already use. omd is what it calls when the job is bigger than one conversation.
Most harnesses end a task when the model writes "done". omd ends one when a command node exits with the code the plan declared — tsc, your suite, your script. Zero model in that node, so nothing can be argued into passing. Two more checks run beside it without asking: write-set reconciliation compares the files a node claims it wrote against the ones it actually touched, and an artifact gate looks on disk for the file it named. A node that reports a file it never created fails there.
A test that passes against everything is indistinguishable from a test that passes for the right reason — unless you check. So before an acceptance command is believed, the engine runs it twice in a throwaway copy of the repo: once before any work exists, and once against a deliberately wrong artifact the classifier had to hand over alongside the command. Green either time and the goal is demoted to exploratory instead of banking a fake pass.
This gate found its own bug that way. It fired zero times across 69 runs — and a number that never moves is usually measuring the ruler, not the thing. The "wrong world" had been an empty temp dir, where bun test fails no matter what you put in it. Now it's a real repo copy.
node.model beats template.model beats auto-assign, and a model you pin explicitly is never overwritten — stamp-pass.ts:66. Cheap models where volume is high and an oracle catches mistakes, a strong one where being wrong is expensive, and a different family wherever something needs a second opinion. Auto-assign fills the 18 seats by channel economics; pin any of them and every resolver reads that one value.
When no exit code can settle it — is this summary faithful? does this design meet the contract? — a verifier reads the result against the original requirement. It runs on a different model family than the author on purpose: same family, same blind spots, and the bad plan it wrote is a bad plan it can't see. Its brief is to attack the result, not to bless it. Fail escalates: stronger conductor, re-plan, and only the rejected nodes re-run.
Every finished node lands on disk atomically. dag_resume reloads the plan from that checkpoint, re-hashes each node's inputs, and keeps every unchanged node green — and unbilled. Only the rest runs again. solve --detached hands the loop to a worker process that outlives your session: close the client, the graph keeps going.
omd_web searches and fetches with zero LLM in the loop. Full text lands on disk; only an index comes back to your context. Gaps close by re-crawling the source that's missing, never by a model filling one in from memory. On the same question, a cheap-seat run cost $2.19 and reproduced 13 of the 15 facts a 106-agent frontier workflow had verified — because coverage is decided by retrieval, and retrieval is the part with no model in it.
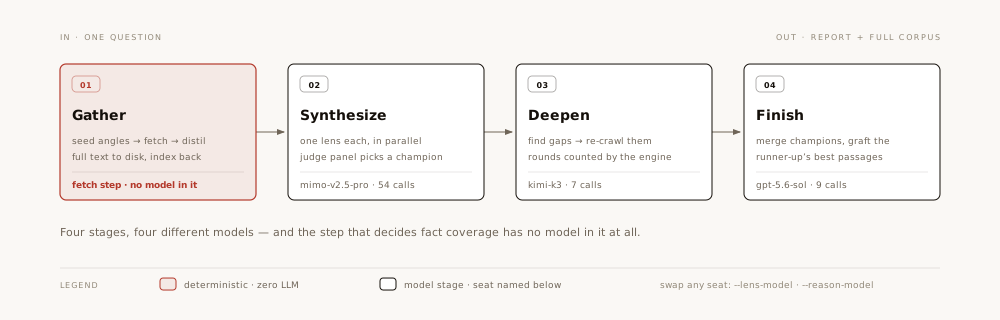
A skill in your harness is a prompt — it can only ask the one model in front of you to behave differently. A pipeline picks a model per stage, and puts a deterministic command on the end.
/omd-research-deep | seeded crawl → lens fan-out → judge panel → gap rounds. Four stages, four models |
/omd-grill → /omd-contract | argue the design, then write the spec the engine executes |
/omd-review | multi-dimension diff review, every finding falsified cross-model |
/omd-debug | reproduce → scope lock → parallel hypotheses → verify |
/omd-path · /omd-rule · /omd-deliver | a decision map in git, ruled by you, delivered on your trigger |
Build your own the same way — hand dag_run_plan a graph and name the model on each node:
{
  "nodes": {
    "draft_a":  { "goal": "…", "executor": "leaf", "model": "deepseek:deepseek-v4-pro" },
    "draft_b":  { "goal": "…", "executor": "leaf", "model": "minimax-cn:MiniMax-M3" },
    "critique": { "goal": "…", "executor": "leaf", "model": "openai-codex:gpt-5.6-sol",
                  "depends_on": ["draft_a", "draft_b"] },
    "gate":     { "goal": "run the suite", "executor": "command",
                  "command": "bun test", "expect_exit": 0, "depends_on": ["critique"] }
  },
  "outputs": ["gate"]
}
Cross-family best-of-N with a hard gate on the end, and you chose every seat in it.
map_deliver is a trigger you pull. Automation researches, fetches, plans and argues on its own; it does not decide to start writing files. For anything unattended — and anything that touches the open web — pass branchStrategy: 'branch' and the run gets its own git worktree plus a jail. The engine never merges that branch back. You read the diff.
| Driving omd | the operating guide — hand it to your agent |
| Why omd exists | the long argument: which layer, and who decides correctness |
| Getting started · CLI guide · MCP tools · Model config · Skills · Deep research | install, the CLI / tool surface, the seats |
| Architecture · DAG engine · Goal loop · Primitives | node kinds, the four pure passes, scheduling, isolation |
| Silent failures | every defect family this engine shipped with no red light |
MIT — see LICENSE.
Sign in to join the discussion.
No comments yet. Be the first to say what this is good for.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
The job search that runs on your machine. AI job application framework built on Claude Code: evaluate postings, tailor CVs, write cover letters, prep interviews. Fork it and own it.
from vibe coding to agentic engineering - practice makes claude perfect
🌊 The original agent meta-harness. Deploy intelligent multi-player swarms, coordinate autonomous workflows, and build conversational AI systems. Features adaptive memory, self-learning intelligence, RAG integration, and native Claude Code / Codex / Hermes and many more Integrated
Practical patterns, starters & CLI tools for loop engineering with AI coding agents. Design systems that prompt and orchestrate agents (inspired by Addy Osmani and Boris Cherny). Includes loop-audit, loop-init, loop-cost.

Git. Ship. Done - Core