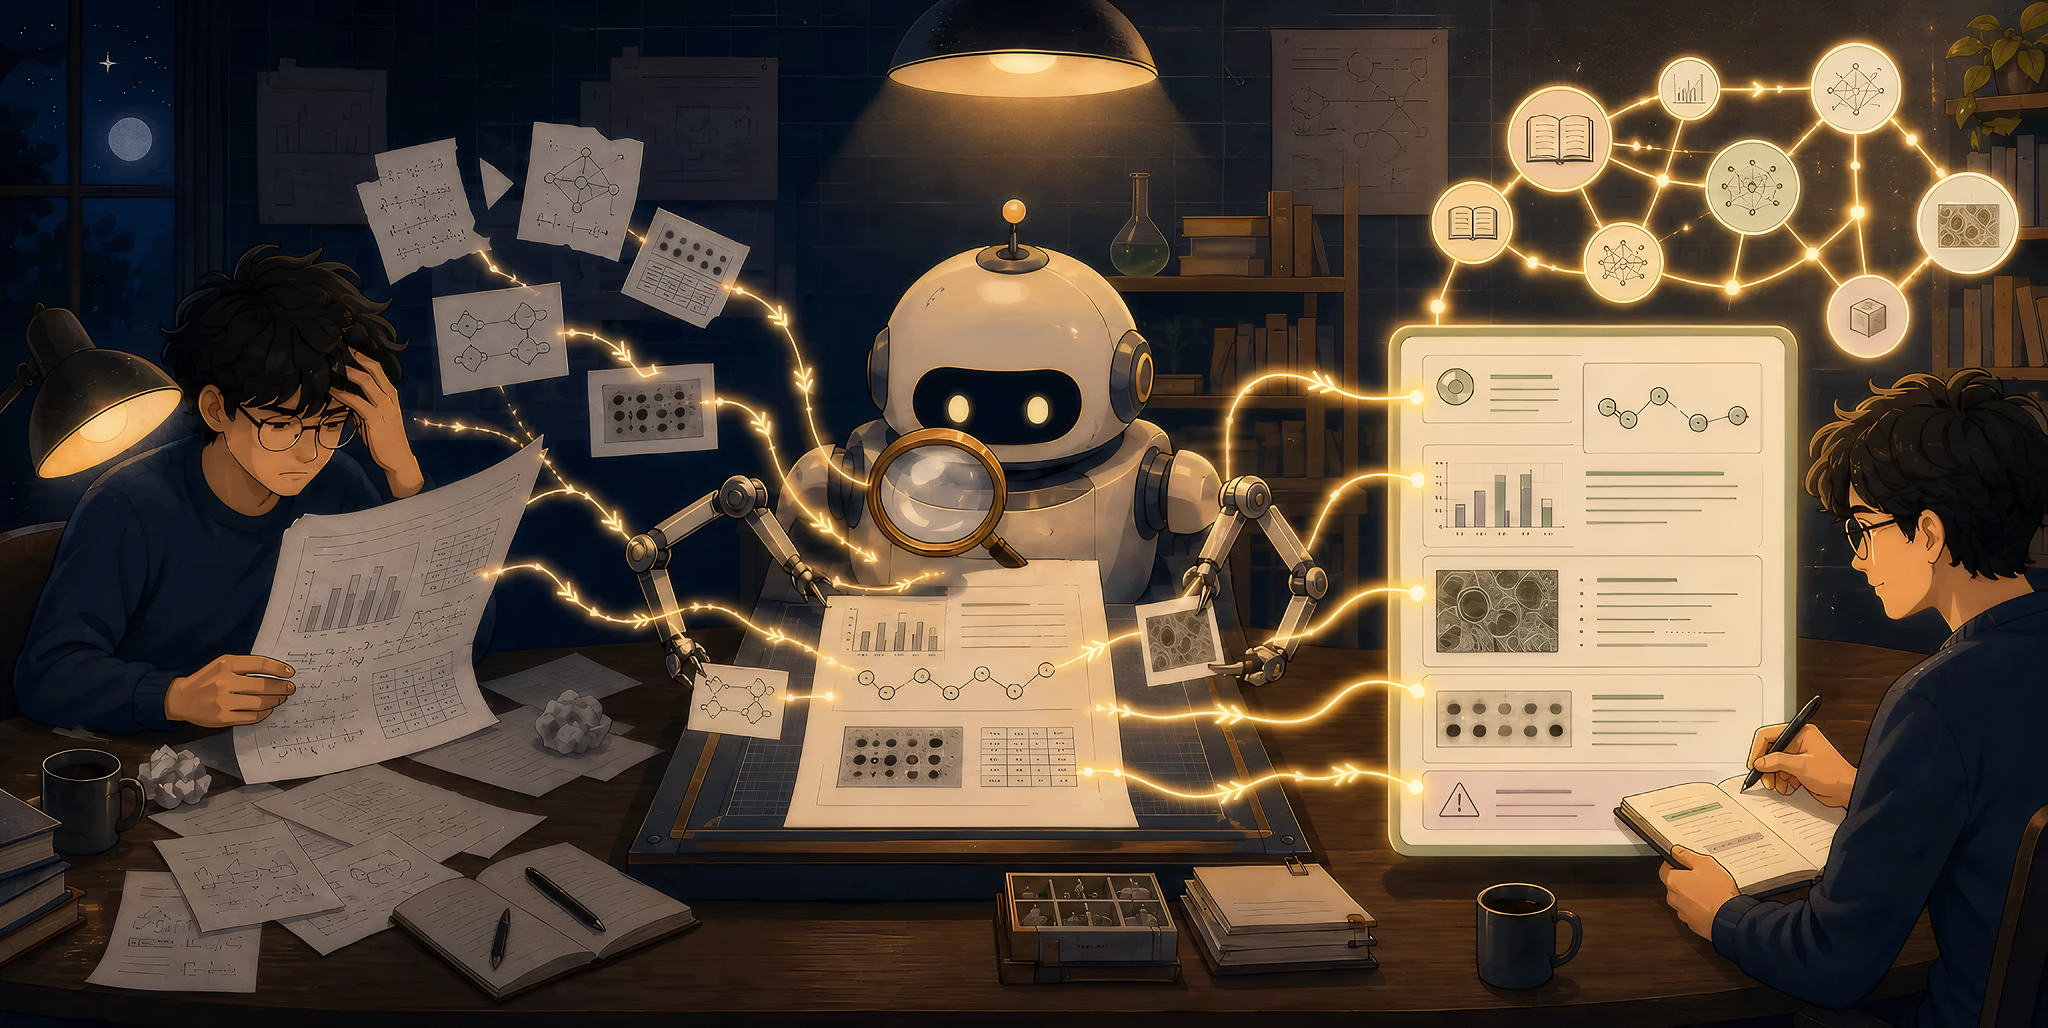
Read one paper deeply. Add one durable page to your academic wiki.
You sit down to study an important paper. The hard part is not reading it—it is turning what you understood into a note you can still use later. The time usually disappears into work like this:
- switching between the PDF, Zotero, web pages, and your note app
- manually organizing metadata, the abstract, figures, and the method backbone
- understanding part of the paper, then spending even longer turning that understanding into a coherent note
- ending up with something that looks complete but is not a note you actually want to revisit
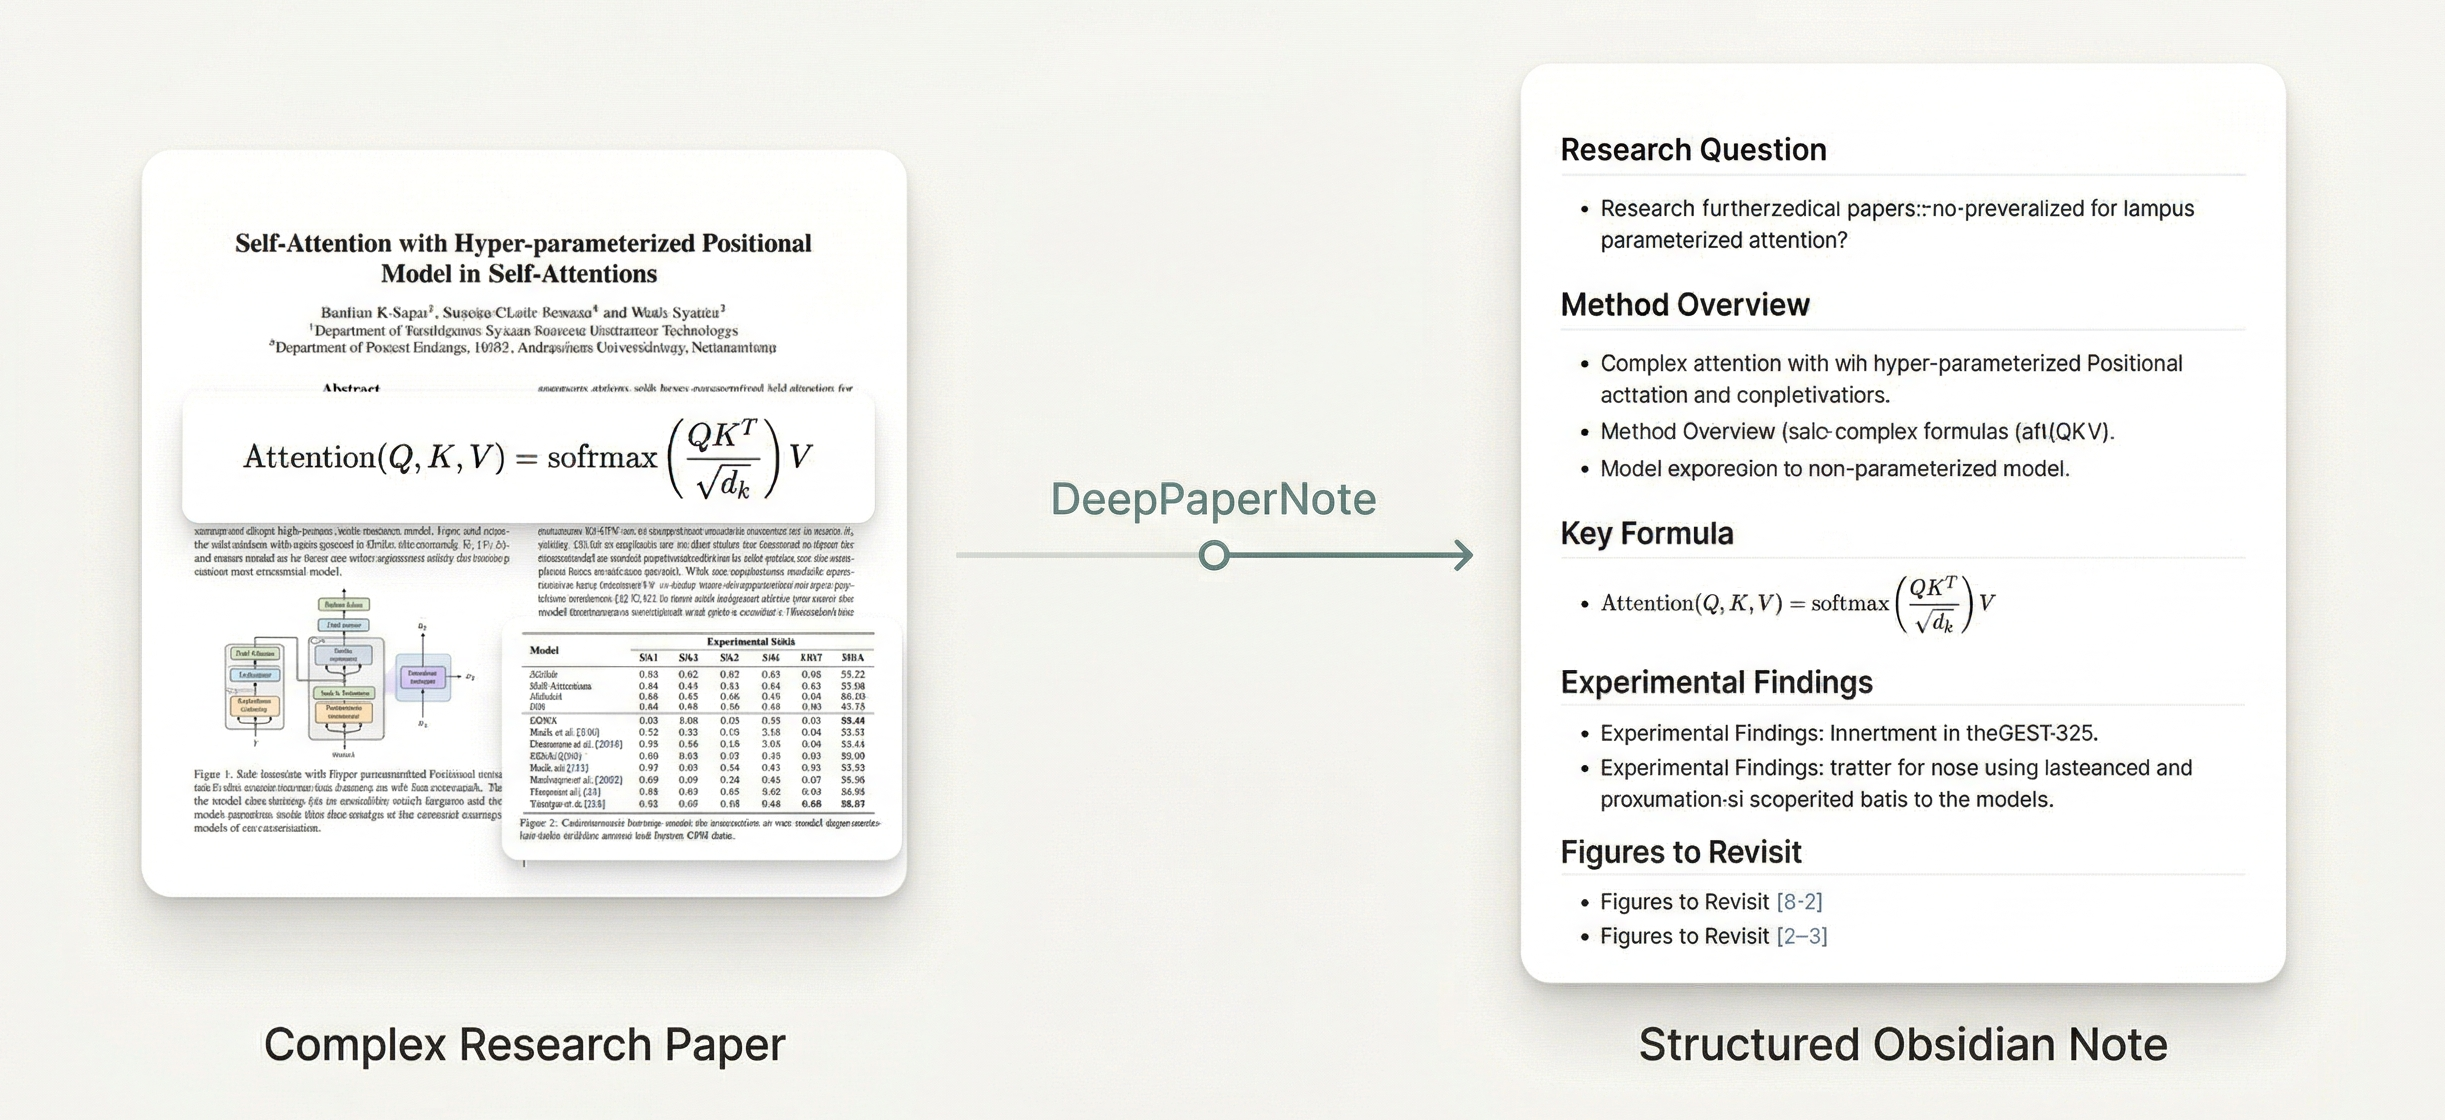
DeepPaperNote takes over that repetitive, mechanical, and surprisingly expensive layer of paper reading. It gathers the material, builds the structure, places figures in context, and shapes the final note so you can keep your attention on the paper's real ideas.
In other words, you can think of DeepPaperNote as the single-paper ingestion layer for an LLM-maintained academic wiki: it reads one paper deeply and turns its research question, methods, evidence, results, and figures into a durable page that people can read and agents can reuse. Obsidian is where those pages live, connect, and grow; DeepPaperNote is how a paper reliably enters the wiki.
DeepPaperNote is an agent skill for reading one paper at a time. The same core skill runs in Claude Code and Codex, and it focuses on the questions that distinguish a deep-reading note from an abstract rewrite:
- What problem is the paper actually solving?
- How does the method, system, or analytical mechanism really work?
- Are the key formulas, experimental conclusions, and figure context preserved?
- Will the result become a useful long-term Obsidian note rather than a disposable summary?
[!tip]
If you already use Obsidian or Zotero, DeepPaperNote automates the most time-consuming and error-prone parts of evidence gathering, organization, and note production.
📰 News
- [v2.3.0] 🌐 Added complete English note support across note structure, figure callouts, validation, and Formal Save. Release notes
- [2026-07-16] 🧩 Added
paper-glossary, an optional companion skill for building reusable Obsidian terminology notes.
- [2026-07-16] 🔌 DeepPaperNote is now distributed as a plugin for multiple agents, with support for selecting multiple skills from the repository. PR #12
News lists only the three most recent user-facing milestones. See the changelog and GitHub Releases for the full history.
🚀 Quick Start
1. Install the plugin
npx skills add 917Dhj/DeepPaperNote
The installer lets you choose which skills to install and which agents should receive them. For most users, start with deeppapernote; add paper-glossary only if you want reusable terminology notes.
2. Install the core PDF dependency
python3 -m pip install PyMuPDF
If you use uv, install PyMuPDF into the same Python environment that DeepPaperNote will use:
uv pip install PyMuPDF
DeepPaperNote requires Python 3.10 or newer. PyMuPDF powers the core PDF extraction path.
3. Hand a paper to your agent
A title, DOI, URL, arXiv ID, or local PDF all work. Zotero items are also supported when a compatible integration is available.
Generate a deep-reading note for this paper: <title, DOI, URL, arXiv ID, or local PDF>
Turn this paper into an Obsidian note: <paper>
🎯 Why DeepPaperNote?
| You may be dealing with... | DeepPaperNote helps by... |
|---|
| 📄 You finished the paper, but your notes are still a pile of fragments | Rebuilding the research question, method chain, central experiments, and limitations into one note you can actually read again |
| 🧠 You do not want another polished-looking AI summary | Preserving the formulas, numbers, figure context, and evidence boundaries that make the paper worth understanding |
| 🗂️ You keep reading papers, but they never become your academic wiki | Turning each paper into a searchable, linkable, reusable Obsidian knowledge page so your academic wiki grows one paper at a time |
| 📚 The paper is already in Zotero, and you do not want to match or download it again | Preferring local records and attachments when available, reducing repeated work and paper mismatches |
🧩 Skills
DeepPaperNote remains the main product. The repository also includes an optional companion skill that works from DeepPaperNote's saved paper artifacts without taking over or rerunning the paper-reading workflow.
| Skill | Role | When to use it |
|---|
deeppapernote | Core product · recommended | Read one paper deeply and produce a structured, evidence-based Obsidian note with figures, results, and limitations |
paper-glossary | Optional companion | Select terms from existing paper artifacts, create reusable Obsidian glossary notes, and optionally link them back to the paper note |
You do not need to install every skill. Choose the ones that match your workflow during installation.
✅ Quality Promise
- The result should be a deep-reading note for one paper, not an abstract rewrite.
- Important methods, experimental results, figures, and limitations should be explained rather than merely listed.
- If the available source is not strong enough for a real deep read, the workflow should stop and ask for better material instead of pretending the note is complete.
The canonical execution contract lives in skills/deeppapernote/SKILL.md.
🗂️ First-Run Preferences
The first time you hand a paper to your Agent, DeepPaperNote helps you choose:
- the default note language: English or Simplified Chinese
- the default save target: the current workspace or your Obsidian Vault
Once confirmed, these preferences are saved on your device and reused for future papers. You can still request a different language or save target for any individual run without changing your defaults.
DeepPaperNote never silently overwrites an existing note or switches save destinations when a save is blocked.
For advanced environment-variable and CLI configuration, see User Configuration.
🔧 Optional Enhancements
None of these are required for ordinary digital PDFs.
| Enhancement | What it helps with |
|---|
| Zotero integration | Reuses local paper records and PDF attachments before searching online |
| Semantic Scholar API | Improves metadata lookup for papers that are difficult to resolve |
| OCR tooling | Recovers page text from scanned or low-quality PDFs |
Zotero Local API
The built-in, read-only Zotero Local API integration supports three resolution modes:
auto (default): prefer a unique local item and retain web fallbackoff: skip Zotero lookuprequired: stop unless Zotero uniquely resolves the reference
An ambiguous local match always fails closed instead of selecting an arbitrary item. Compatible agent-runtime or MCP integrations remain optional alternatives.
When one of these capabilities is needed, ask your agent to inspect the current environment and guide the setup for that machine.
🧭 Inspirations
DeepPaperNote was influenced by projects that take paper reading, evidence extraction, and note generation seriously, especially:
🤝 Contributing
Pull requests should target develop, not main. Changes that may affect final note quality should be evaluated with evals/regression-workflow.md and evals/note-quality-rubric.md.
Star History

Thanks for reading, using, and supporting DeepPaperNote. May your paper-reading days be a little clearer, calmer, and more rewarding.
MIT License © 917Dhj